Tinker✓

@tinkerapi

I tink, therefore I am Post-training API by @thinkymachines

1 Takip edilen15.6K Takipçi184 Gönderiler
  1. Tinker✓@tinkerapi
    Inkling is our first open model from @thinkymachines and is now available on Tinker! Check out these quotes from Tinker customers on their experience with Inkling: @_Mantic_AI: "Not only does Inkling outperform Kimi K2.6 on our forecasting evals, it does so with half the output tokens." @trajectorylabs: "We’ve been impressed by how sharp and efficient the model is. Its reasoning is concise, its tool calling is consistently strong, and it holds up well on complex, long-horizon agentic tasks. It feels like a meaningful unlock for what teams can build with open-source models designed for customization." @lightningrodai: "We came away impressed by the model’s underlying reasoning ability. It’s thoughtful, original, and refreshingly unsycophantic.”
    Thinking Machines @thinkymachines
    Today, we are introducing Inkling. Inkling reasons efficiently across text, image, and audio modalities. We are making the full weights available. Available today for fine-tuning on Tinker. Play with it in the Inkling Playground. 🧵
    9148718.9K
  2. Thinking Machines✓@thinkymachines
    Today, we are introducing Inkling. Inkling reasons efficiently across text, image, and audio modalities. We are making the full weights available. Available today for fine-tuning on Tinker. Play with it in the Inkling Playground. 🧵
    5592K14.8K8.4M
  3. Tinker✓@tinkerapi
    Samaya trained Nemotron 3.5 Lightning to beat Fable 5.1 on its finance research benchmark at 9% of the cost. The model was trained on Tinker together with the harness it works in: first by imitating 8 teachers, then RL on its own mistakes.
    Samaya AI @samaya_AI
    Introducing Samaya Sterling: our first post-trained model for state-of-the-art financial research. On FrontierFinance, Sterling outperforms Claude Fable 5.1 (58.9% vs. 55.9%) at 11× lower cost. Using a model with just 3B active parameters, Sterling demonstrates what's possible when specialized training meets a purpose-built financial research harness. Read the full research ↓
    291096.1K
  4. Samaya AI✓@samaya_AI
    Introducing Samaya Sterling: our first post-trained model for state-of-the-art financial research. On FrontierFinance, Sterling outperforms Claude Fable 5.1 (58.9% vs. 55.9%) at 11× lower cost. Using a model with just 3B active parameters, Sterling demonstrates what's possible when specialized training meets a purpose-built financial research harness. Read the full research ↓
    İndir
    25447.7K
  5. Tinker✓@tinkerapi
    Off-policy RL is difficult; runs can suddenly collapse because of async RL staleness or numerical mismatch. StableReinforce is a new method on Tinker that keeps your RL runs stable, even when learning drifts from sampling.
    1058805126K
  6. Tinker✓@tinkerapi
    Agents are good at navigating filesystems. With RL, they learn to build new ones in anticipation of other agents' queries, boosting subsequent RAG accuracy from 44% to 77%. A step towards agents training to work together, supported by the Tinker grants program!
    Anikait Singh @Anikait_Singh_
    LLMs deployed in specialized domains, from enterprise codebases to law firms, dig through a mountain of unstructured context! Our new paper, Librarian Agents, asks: can an agent adapt by curating its own long-context workspace, anticipating queries before they arrive? 🧵⬇️
    3817410K
  7. Anikait Singh✓@Anikait_Singh_
    LLMs deployed in specialized domains, from enterprise codebases to law firms, dig through a mountain of unstructured context! Our new paper, Librarian Agents, asks: can an agent adapt by curating its own long-context workspace, anticipating queries before they arrive? 🧵⬇️
    İndir
    73217644.4K
  8. Tinker✓@tinkerapi
    now live on Tinker!
    DeepSeek @deepseek_ai
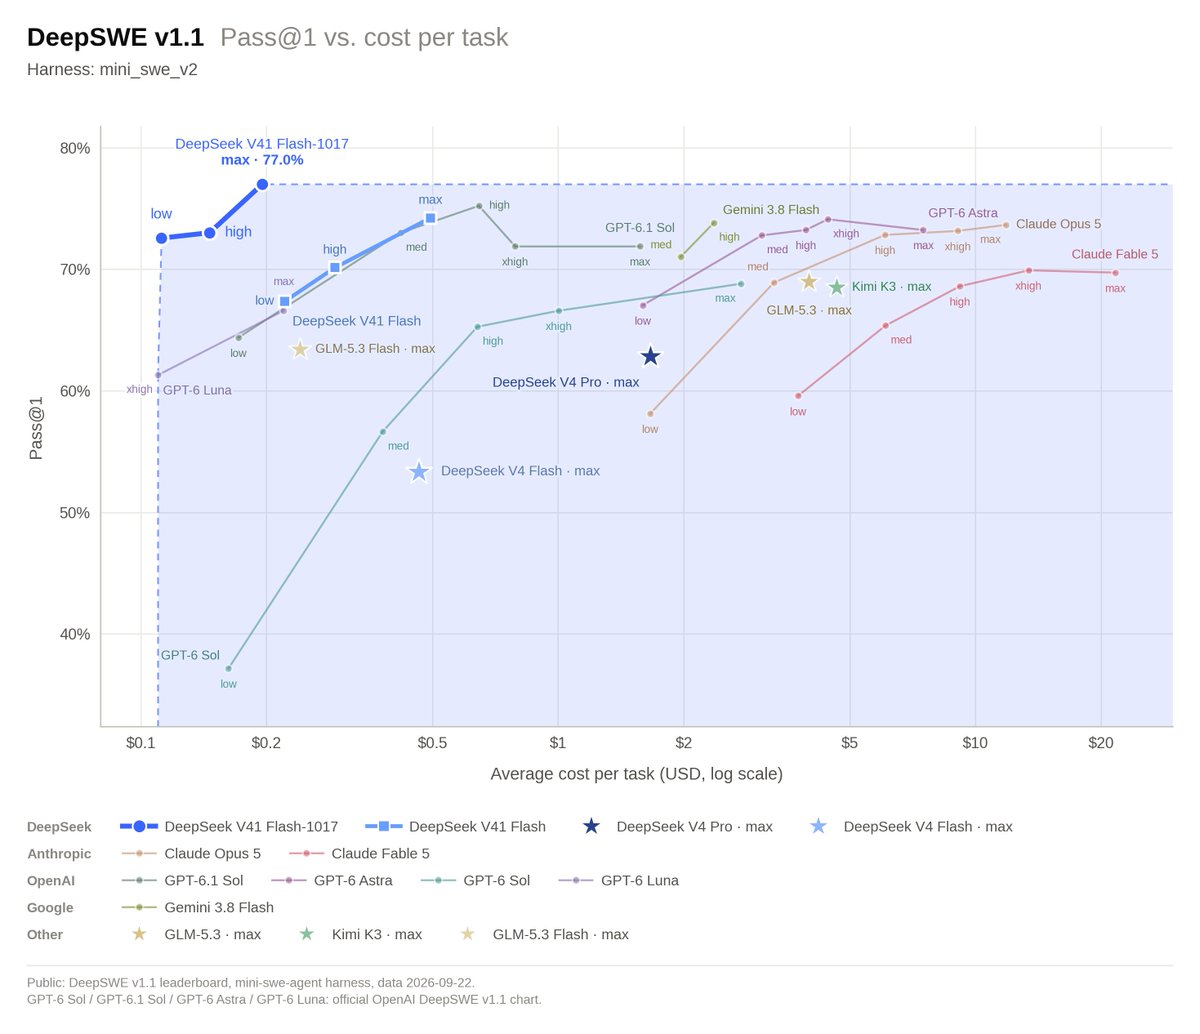
    🚀 DeepSeek-V4.1-Flash-1017 is here! Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API. 🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model. 1/4
    11366.8K
  9. DeepSeek✓@deepseek_ai
    🚀 DeepSeek-V4.1-Flash-1017 is here! Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API. 🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model. 1/4
    İndir
    1.6K4.1K37.2K8.1M
  10. Tinker✓@tinkerapi
    We're hiring a Tinkerer who's excited to read post-training research, build it in Tinker, and share the results with everyone Tinker runs on open science, and we want you to make it a home for the researcher community
    112454937.4K
  11. Tinker✓@tinkerapi
    Tinker
    RT @thinkymachines: Tinker lets customers turn their expertise into cutting-edge models that they own. One year after launch, we look back at what we’ve shipped and what our users are building.
    030043
  12. Tinker✓@tinkerapi
    Nemotron 3.5 Super VL from @nvidia is live on Tinker today. With 12B active parameters, efficient architecture, and native text, images, and video inputs 3.5 Super VL should be a strong base for training long running always-on multimodal agents.
    NVIDIA AI @NVIDIAAI
    Meet NVIDIA Nemotron 3.5 Super VL Our new open model combines reasoning and tool use with text, image, document, and video understanding for long-running AI agents. 120B total parameters with 12B active 🧵
    23523.2K
  13. NVIDIA AI✓@NVIDIAAI
    Meet NVIDIA Nemotron 3.5 Super VL Our new open model combines reasoning and tool use with text, image, document, and video understanding for long-running AI agents. 120B total parameters with 12B active 🧵
    İndir
    2905534.5K604K
  14. Tinker✓@tinkerapi
    Dimuon is a new optimizer we built for LoRA fine-tuning. In our SFT tests, it often reaches lower loss in fewer steps than AdamW. We're still experimenting with Dimuon; you can Tinker with it today and share your feedback! See our optimizers guide at
    1858594120K
  15. Tinker✓@tinkerapi
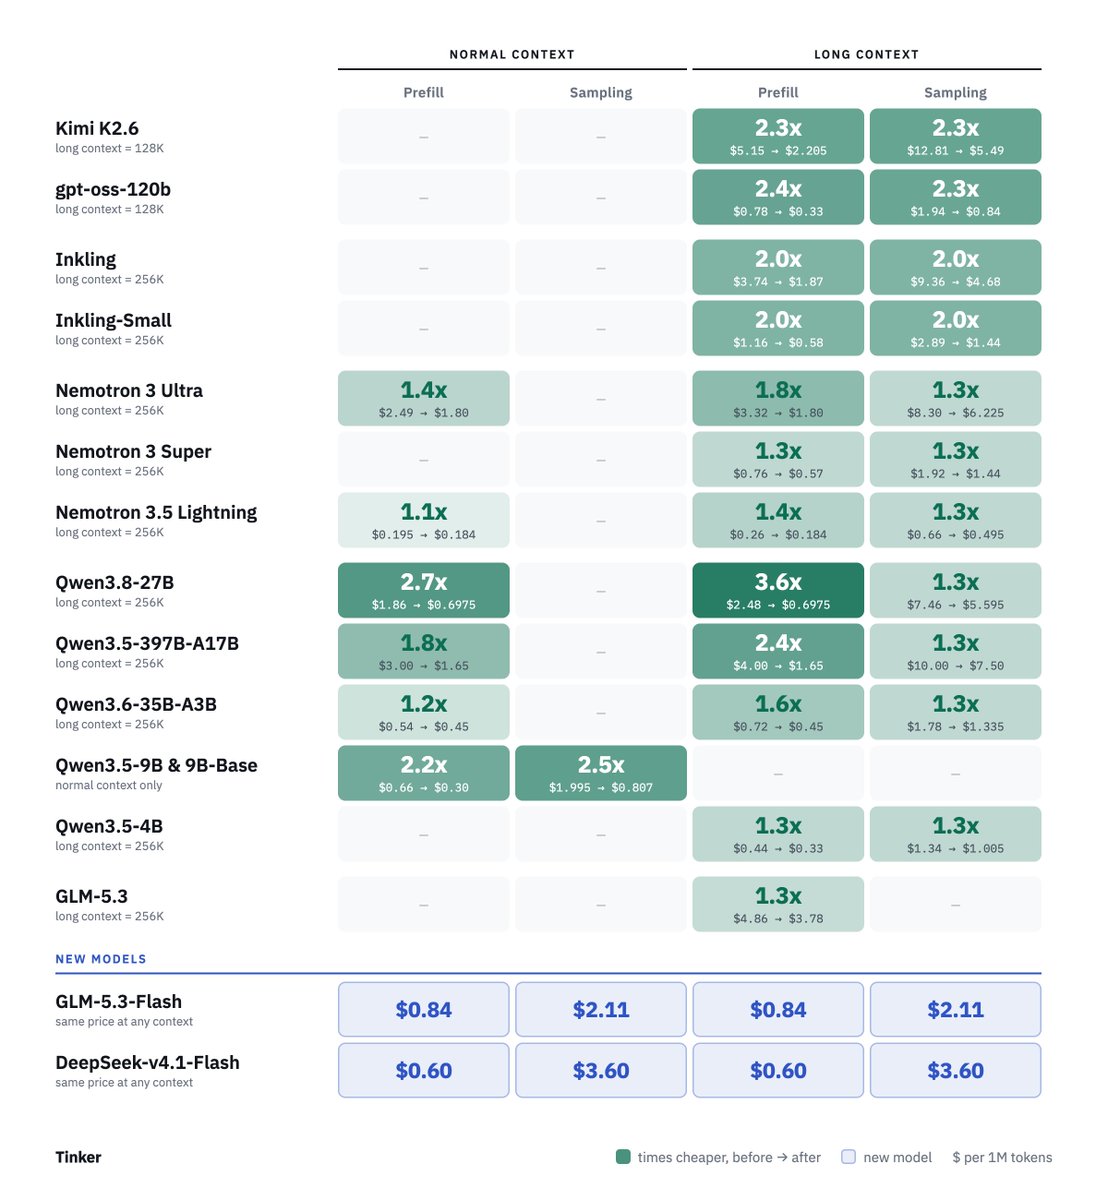
    Tinkerers have been busy scaling up long-context RL! We’ve made significant improvements to Tinker’s efficiency to support those, and are passing these on with price cuts up to 70%. GLM-5.3-Flash and DeepSeek-v4.1-Flash are also live for cost-efficient long-context work.
    İndir
    233940278.9K
  16. Tinker✓@tinkerapi
    Gönderiler @tinkerapi
    GLM-5.3-Flash and DeepSeek-v4.1-Flash join the Tinker lineup today. Both models natively take image inputs and utilize efficient attention architecture. GLM-5.3-Flash is 4-5 times cheaper on Tinker than GLM-5.3! Also live: long-context options for Qwen3.5-4B and Qwen3.6-35B-A3B.
    10202.4K
  17. Tinker✓@tinkerapi
    Gönderiler @tinkerapi
    To keep throughput high, we are retiring 3 models on 10/23. We suggest replacing these with newer and more efficient variants from the same family: • Qwen3.6-27B → Qwen3.8-27B • Nemotron-3-Nano-30B-A3B → Nemotron 3.5 Lightning • DeepSeek-v3.1 → DeepSeek-v4.1-Flash
    00111.8K
  18. Tinker✓@tinkerapi
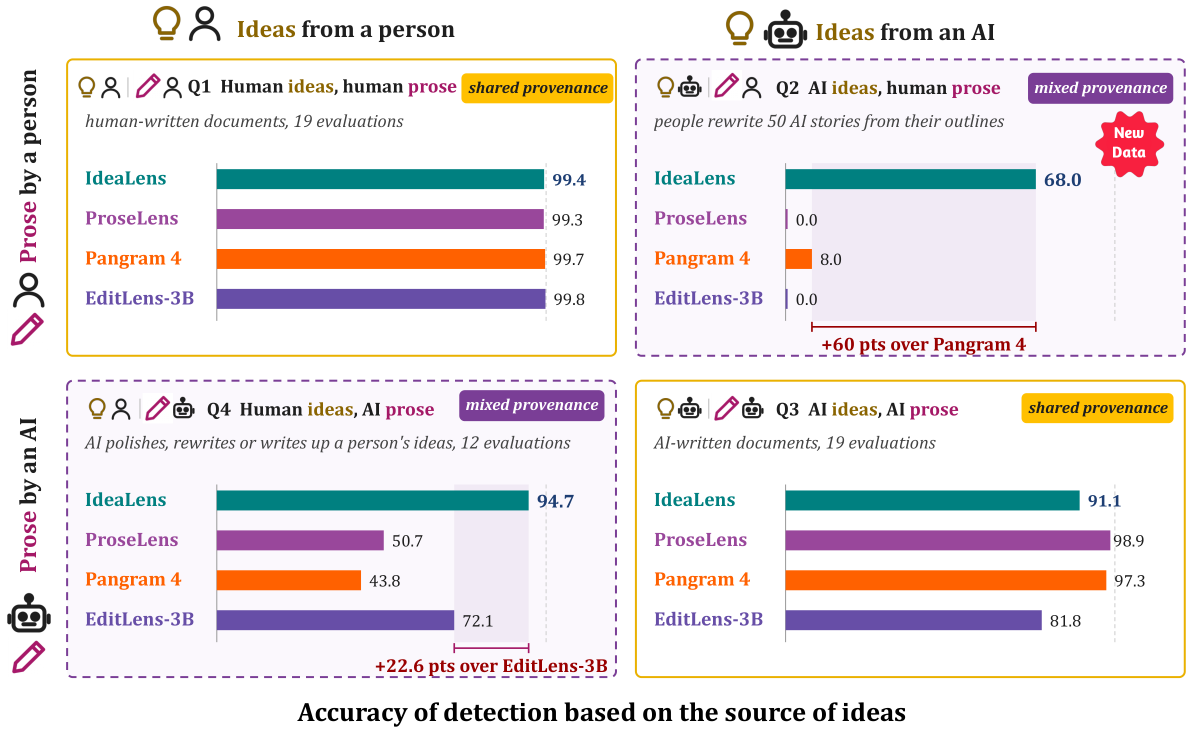
    By changing the prose but keeping the arguments and labels, IdeaLens detects where a person or AI came up with the idea, not just who wrote them down. Trained on Tinker, and the code+data+model are open sourced as well!
    rishanth rajendhran @rishanthrajendh
    Traditional AI detectors are accurate when ideas and prose come from the same source. However, on mixed provenance benchmarks where they differ, they follow the prose and not the ideas in the writing. IdeaLens correctly detects who came up with the ideas and not who wrote the prose on these mixed benchmarks, with an average idea detection accuracy of 81.3% vs ProseLens's 25.4% and Pangram 4's 25.9%. This suggests that ideas are a strong differentiator of human and AI writing.
    17533.8K
  19. rishanth rajendhran✓@rishanthrajendh
    Gönderiler @rishanthrajendh
    Traditional AI detectors are accurate when ideas and prose come from the same source. However, on mixed provenance benchmarks where they differ, they follow the prose and not the ideas in the writing. IdeaLens correctly detects who came up with the ideas and not who wrote the prose on these mixed benchmarks, with an average idea detection accuracy of 81.3% vs ProseLens's 25.4% and Pangram 4's 25.9%. This suggests that ideas are a strong differentiator of human and AI writing.
    İndir
    10156.6K
  20. Tinker✓@tinkerapi
    Tinker
    RT @moo_hax: I trained a model to memorize all the trace data, so I don't have to /s. Needs few more lines, but workers batch my traces into pipeline.
    020144
  21. Tinker✓@tinkerapi
    Fulcrum's training approach is brilliant: the base model already knows how to write, so both SFT and RL are tailored to the precise distinction between the default LLM voice and authors' voices. Smart customization can be both cheap and effective.
    Fulcrum @fulcrum_inc
    Say hello to Echo, the best writing model at style imitation. Echo beats frontier models at writing tasks ranging from fiction to technical explanations, despite costing less than $5K to train.
    92141925.8K
  22. Fulcrum✓@fulcrum_inc
    Say hello to Echo, the best writing model at style imitation. Echo beats frontier models at writing tasks ranging from fiction to technical explanations, despite costing less than $5K to train.
    İndir
    641402.3K4.8M
  23. Tinker✓@tinkerapi
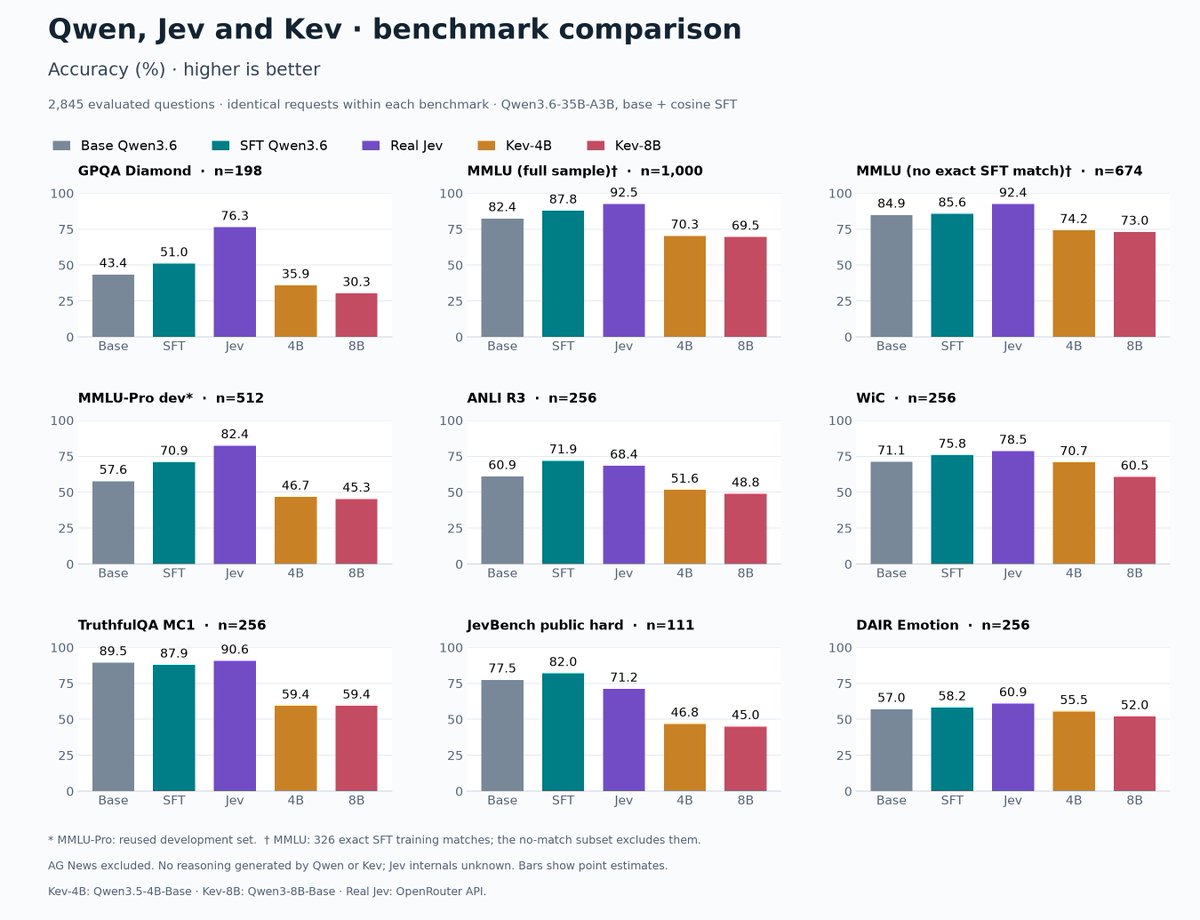
    LLM next-token prediction is already a probabilistic classifier, so an open LLM can serve a Jev-like interface: discrete options in, fast probabilities out. Our own @ekzhang1 made it better at the job with a $5, 10-minute run on Tinker.
    Eric Zhang @ekzhang1
    Did some SFT on Qwen3.6-35B-A3B this evening, just to get it to respond better to Jev-y prompts via Cost: $5, easy 10 min training run on Tinker. +8% on GPQA diamond and +12% on MMLU-Pro. Also evaled @jaredpalmer's Kev here for comparison
    161638874K
  24. Eric Zhang✓@ekzhang1
    Did some SFT on Qwen3.6-35B-A3B this evening, just to get it to respond better to Jev-y prompts via Cost: $5, easy 10 min training run on Tinker. +8% on GPQA diamond and +12% on MMLU-Pro. Also evaled @jaredpalmer's Kev here for comparison
    İndir
    162532959.4K
  25. Tinker✓@tinkerapi
    Gönderiler @tinkerapi
    @ekzhang1 ... and now you can too. Our new cookbook recipe let's you train your own decision model, targeting either a single answer or a calibrated probability distribution. It matches our reasoning RL recipe on forecasting, while requiring no reasoning at all!
    001471
  26. Tinker✓@tinkerapi
    Training a search agent is great for RL because every lever impact model behavior in legible ways. Jasper's guide shows how small updates to the reward function teach a model to avoid sloppy tool calls, prune unnecessary docs, and balance persistence with token efficiency.
    Jasper Lu @lu__jasper
    Sharing my first of hopefully many research blog posts! This one is the kind of educational blog post I wish I'd had when I started with RL for LLMs. I tried to make it as open as possible. Every rollout is browsable, the code is open source, and I walk through my entire thought process, from learning rate sweeps to reward shaping.
    1815919.3K
  27. Jasper Lu✓@lu__jasper
    Sharing my first of hopefully many research blog posts! This one is the kind of educational blog post I wish I'd had when I started with RL for LLMs. I tried to make it as open as possible. Every rollout is browsable, the code is open source, and I walk through my entire thought process, from learning rate sweeps to reward shaping.
    17100854118K
  28. Tinker✓@tinkerapi
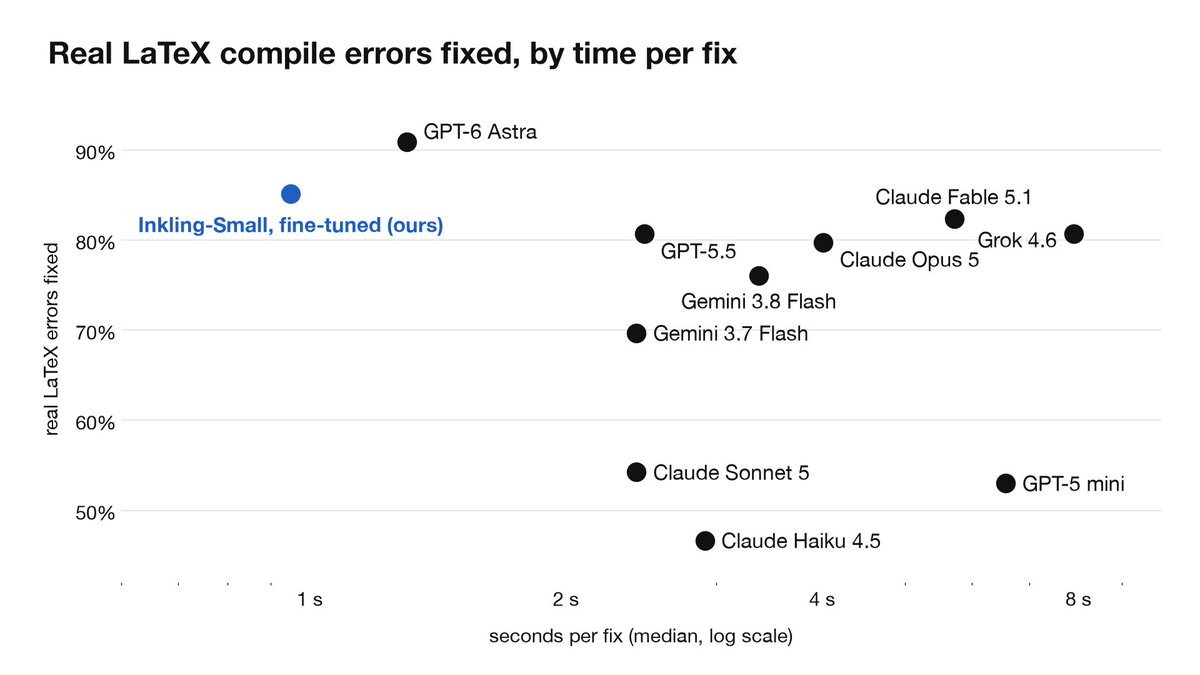
    Sundial put the effort in getting RLVR right: training on verified fixes instead of artificial errors, smart rewards that disincentivize hacking, and deterministic scoring. The result — a trained Inkling-Small that fixes 83.7% of LaTeX errors in under 1 second and $.0013.
    turboblitz @turboblitzzz
    We fine-tuned @thinkymachines' Inkling-Small to fix LaTeX compile errors inside the editor, in under a second. On real errors it matches Claude Fable 5.1, six times faster and at about 1/40 of the cost. When we interviewed mathematicians, one of the most common annoyances we heard about in their day to day work is battling with LaTeX compilation errors. The most obvious solution is to ask a chatbot to fix errors. That works decently well, except switching to a different window breaks the writing flow, and copy-pasting the snippet often loses relevant context, especially when multiple files are involved. So we scraped 272,000 questions from TeX.StackExchange and kept the 3,978 whose snippet still fails today, whose accepted answer compiles, and whose difference replays exactly as a patch. The largest dataset previously released had 88. We tried tweaking the reward function in many ways. The first one was only a compilation check, which led the model to remove content until the document built. In the end, what worked best was rewarding compilation and a close match with the solution's PDF, and penalizing removed content. We're rolling out the model inside the @sundialmd editor this week. When a compile fails, the fix is applied as a suggestion in under a second and the PDF rebuilt. Write-up: Thanks @tinkerapi and @thinkymachines for the support.
    37554.3K
  29. turboblitz✓@turboblitzzz
    We fine-tuned @thinkymachines' Inkling-Small to fix LaTeX compile errors inside the editor, in under a second. On real errors it matches Claude Fable 5.1, six times faster and at about 1/40 of the cost. When we interviewed mathematicians, one of the most common annoyances we heard about in their day to day work is battling with LaTeX compilation errors. The most obvious solution is to ask a chatbot to fix errors. That works decently well, except switching to a different window breaks the writing flow, and copy-pasting the snippet often loses relevant context, especially when multiple files are involved. So we scraped 272,000 questions from TeX.StackExchange and kept the 3,978 whose snippet still fails today, whose accepted answer compiles, and whose difference replays exactly as a patch. The largest dataset previously released had 88. We tried tweaking the reward function in many ways. The first one was only a compilation check, which led the model to remove content until the document built. In the end, what worked best was rewarding compilation and a close match with the solution's PDF, and penalizing removed content. We're rolling out the model inside the @sundialmd editor this week. When a compile fails, the fix is applied as a suggestion in under a second and the PDF rebuilt. Write-up: Thanks @tinkerapi and @thinkymachines for the support.
    İndir
    131012611.8K
  30. Tinker✓@tinkerapi
    Gönderiler @tinkerapi
    We love seeing models trained to help professionals work better and spend less time debugging LaTeX, than AI that tries to replace their work wholesale.
    1191K