
Join our creator tools hackathon and win 5K+ in cash prizes!
Hack the Feed, Fri Nov 6, 1–6pm at @Amplitude_HQ.
Build with GMI inference credits, @oriane_xyz’s video intelligence API, and @lovable_dev
Register here:
2418678

@gmi_cloud
one cloud for compute, inference, and agents Question: https://t.co/dOcscX4hmx Japan: @gmicloudJapan

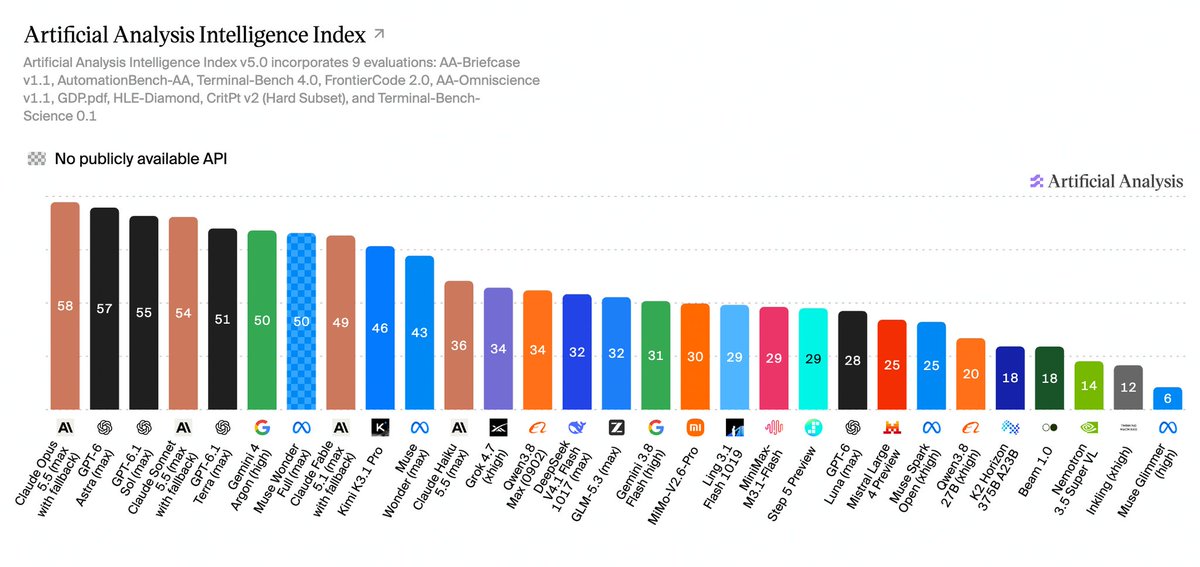
Artificial Analysis @ArtificialAnlysAnnouncing Artificial Analysis Intelligence Index v5, featuring 2 new benchmarks and 3 upgrades. For the first time, the majority of the Index is built on private datasets The Artificial Analysis Intelligence Index is our composite measure of model capabilities across tasks reflecting real-world usage today. v5 is our biggest upgrade since v4 launched in January. With v5, 60% of the Index is now based on evaluations with private test sets or held-out answers. Alongside Intelligence Index v5, we’re launching the Artificial Analysis Progress Index v1, which tracks model capability over time on one continuous scale. New to the Intelligence Index: ➤ FrontierCode 2.0: Cognition's newly-launched private benchmark of real-world coding tasks, graded on whether a repository maintainer would merge the agent's change ➤ Terminal-Bench-Science: 70 agentic scientific research tasks, run in a terminal environment Upgraded: ➤ HLE-Diamond (replacing Humanity's Last Exam): a refined 1,000-question version of Humanity's Last Exam, split evenly between reasoning and knowledge questions ➤ AA-Omniscience v1.1: An updated dataset with saturated and public set questions removed, new questions added, and ambiguous or erroneous questions revised ➤ CritPt v2: a private, 40-question hard subset of CritPt v2, revised by the CritPt authors and run with a code-execution tool Staying in the Index: AA-Briefcase, AutomationBench-AA, GDP.pdf and Terminal-Bench 4.0 Removed from the Index: GDPval-AA v2.1, SciCode, and AA-LCR v1.1 Key results: ➤ Claude Opus 5.5 (max) leads at 58, ahead of GPT-6 Astra (max, 57) and GPT-6.1 Sol (max, 55): Anthropic and OpenAI hold the top five models. Gemini 4 Argon (high) is next at 50 ➤ The open weights gap widens from 3 points to 12: Kimi K3.1 Pro (weights not yet released) is the top open weights model at 46. Among released weights, DeepSeek V4.1 Flash 1017 (max) and GLM-5.3 (max) lead at 32 - 26 points behind the leader and below Claude Haiku 5.5 (max, 36) ➤ Cost per task varies by more than 13x among the leading models: of the 10 highest-scoring models shown, GPT-6.1 Terra (max) is the cheapest at $0.96 per Intelligence Index task and Claude Fable 5.1 (max) the most expensive at $13.04


GMI Cloud @gmi_cloudFinal day of @zkasuran x GMI: gmi 1.0.0 is out. One line installs it: curl -fsSL | sh Chat, images, video, all 93 GMI API operations, sandboxes and an MCP server for agents. Apache-2.0.
GMI Cloud @gmi_cloudDay 4 of @zkasuran x GMI: AgentBox sandboxes from the terminal. gmi sandbox run starts a GMI sandbox, runs your command inside it and cleans up. Exec passes the exit code through. Files go in and out. Recorded live. No waits are shortened.

MiniMax (official) @MiniMax_AIMiniMax M3.1 Flash weights are now public. 428B parameters total, 23B activated per token. Agentic performance: A generational leap in agentic tasks, coding, and cybersecurity — 76.2 on BankerToolBench, 73.7% on DeepSWE v1.1, 61.7 on OSWorld V2, 29.6 on Agents' Last Exam, and 82.2 on CyberGym. Efficient by design: MiniMax Sparse Attention and DSpark speculative decoding improve inference efficiency. Hugging Face: ModelScope: API: M Plan: MCode for desktop:


GMI Cloud @gmi_cloud

Utopai Studios @UtopaiStudiosMeet the all-new PAI & Utopai X, highest-ranked model from a U.S.-based company on Artificial Analysis’ Text-to-Video Leaderboard with Audio. Utopai X works inside PAI, our production intelligence engine, where workflow and creative decisions connect across pro-level productions.


GMI Cloud @gmi_cloudDay 3 of @zkasuran x GMI: every GMI API operation as a command. 93 operations from GMI's four published specs, generated rather than hand written. gmi api list shows them, --dry-run previews a request and gmi api check probes the safe reads. Recorded live. One long wait is shortened.


