MiniMax (official)

@MiniMax_AI

Code: @MiniMaxAgent MiniMax Design: @Hailuo_AI API: https://t.co/fHRdSV73Hr M Plan: https://t.co/XfJWSyauda

1K Gefolgt129K Follower2.1K Beiträge
  1. MiniMax (official)@MiniMax_AI
    MiniMax M3.1 Flash: Space Performance + Bunny Speed 🚀🐰 Yes, Space Bunny - which has topped global leaderboards with 200T+ tokens - was an earlier version of M3.1 Flash. 💰Redefining the performance economics of agentic AI. M3.1 Flash achieves frontier-level intelligence across key tasks such as Cowork (Automation-Bench: 62%; ALE: 30%), Coding (DeepSWE: 74%) and Visual Reasoning (BabyVision: 91%), at 1/3 the cost of M3 and 3x the speed. API pricing (flat rate): $0.15 / $0.60 per 1M input/output tokens, with cache reads at $0.015 / 1M tokens. Model weights will arrive on Oct 23. API: M Plan: MiniMax Code for desktop:
    Herunterladen
    4726787.5K1.7M
  2. MiniMax (official)@MiniMax_AI
    💬 Live tomorrow with Fireworks AI: MiniMax M3.1 Flash. Join @VictorSuOrtiz from MiniMax and @sophiamyang from @FireworksAI_HQ with your agent ideas, integration questions, or that one thing you’ve been meaning to ask. Oct 28 · 10 AM PT 👉 RSVP:
    Herunterladen
    Fireworks @FireworksAI_HQ
    How good is MiniMax M3.1 Flash? @VictorSuOrtiz (@MiniMax_AI) and Fireworks' @sophiamyang go live Oct 28 at 10 AM PT to break down what's new, what it's built for, and how to use it on Fireworks today. Set a reminder:
    52344K
  3. Fireworks✓@FireworksAI_HQ
    How good is MiniMax M3.1 Flash? @VictorSuOrtiz (@MiniMax_AI) and Fireworks' @sophiamyang go live Oct 28 at 10 AM PT to break down what's new, what it's built for, and how to use it on Fireworks today. Set a reminder:
    21115.2K
  4. MiniMax (official)@MiniMax_AI
    MiniMax × @Pickford_AI bring Whispers to the Sydney Opera House during #NeurIPS2026. Cinema that rewrites and reanimates itself in response to its audience. December 7 · Private screening
    Pickford @Pickford_AI
    The show that re-writes and re-animates itself based on the audience is coming to the Sydney Opera House. Pickford × MiniMax. December 7. During #NeurIPS2026. @MiniMax_AI @Pickford_AI @ColeClifford @NeurIPSConf #InteractiveStorytelling #SydneyOperaHouse #minimax #Aifilmmaking
    60376.2K
  5. MiniMax (official)@MiniMax_AI
    Beiträge @MiniMax_AI
    Request an invitation →
    0002.1K
  6. MiniMax (official)@MiniMax_AI
    MiniMax (official)
    RT @EvoLinkAi: 🚀MiniMax M3.1 Flash is now available on EvoLink 💻Great for software engineering, interactive creation and research 📺Check what @MiniMax_AI made to promote M3.1 Flash it self👇
    0201.2K
  7. MiniMax (official)@MiniMax_AI
    MiniMax (official)
    RT @togethercompute: minimax m3.1 flash is now available for post-training on together ai run sft or rl with your own data, rewards + environments, while keeping the training loop in your own python code take m3.1 flash and shape it for the agentic workload you need
    0901.1K
  8. MiniMax (official)@MiniMax_AI
    MiniMax M3.1 Flash meets the @UnslothAI community. 🐙🦥✨ Unsloth’s Dynamic GGUFs bring our 428B MoE model to a 143.9GB 2-bit footprint, with 91.5% top-1 token agreement in their evaluation across seven domains. That means a lower memory barrier to self-hosting, deployment through Unsloth Desktop and llama.cpp, and an OpenAI-compatible API for existing apps and agents. With 78K+ GitHub stars and over 500M model downloads on Hugging Face, Unsloth gives M3.1 Flash a path into an established community of developers running, evaluating and building with open models. Open weights. Local control. More ways to build.
    Herunterladen
    Unsloth AI @UnslothAI
    MiniMax-M3.1-Flash can now run locally! We made 2-bit GGUF retain 91.5% top 1 accuracy while being 45% smaller. Run on 150GB RAM. MiniMax-M3.1-Flash is the strongest open model for its size & among the best overall. GGUF: Guide:
    261628920.1K
  9. Unsloth AI✓@UnslothAI
    MiniMax-M3.1-Flash can now run locally! We made 2-bit GGUF retain 91.5% top 1 accuracy while being 45% smaller. Run on 150GB RAM. MiniMax-M3.1-Flash is the strongest open model for its size & among the best overall. GGUF: Guide:
    Herunterladen
    MiniMax (official) @MiniMax_AI
    MiniMax M3.1 Flash: Space Performance + Bunny Speed 🚀🐰 Yes, Space Bunny - which has topped global leaderboards with 200T+ tokens - was an earlier version of M3.1 Flash. 💰Redefining the performance economics of agentic AI. M3.1 Flash achieves frontier-level intelligence across key tasks such as Cowork (Automation-Bench: 62%; ALE: 30%), Coding (DeepSWE: 74%) and Visual Reasoning (BabyVision: 91%), at 1/3 the cost of M3 and 3x the speed. API pricing (flat rate): $0.15 / $0.60 per 1M input/output tokens, with cache reads at $0.015 / 1M tokens. Model weights will arrive on Oct 23. API: M Plan: MiniMax Code for desktop:
    735960654K
  10. MiniMax (official)@MiniMax_AI
    Thank you 0G and the community for your support of M3.1 Flash! Hope to see more exciting projects from the community!
    0G Labs @0G_labs
    Heads up, M3.1 Flash gang . Provider-side support for the free window changed, so free access ends early: Today, 16:00 UTC (not Oct 24). But after that, it stays live on 0G Private Computer for 2 weeks at $0.09 in / $0.54 out per 1M tokens. Thanks for the unhinged usage 🫡
    10617016K
  11. 0G Labs✓@0G_labs
    Heads up, M3.1 Flash gang . Provider-side support for the free window changed, so free access ends early: Today, 16:00 UTC (not Oct 24). But after that, it stays live on 0G Private Computer for 2 weeks at $0.09 in / $0.54 out per 1M tokens. Thanks for the unhinged usage 🫡
    864723.2K
  12. MiniMax (official)@MiniMax_AI
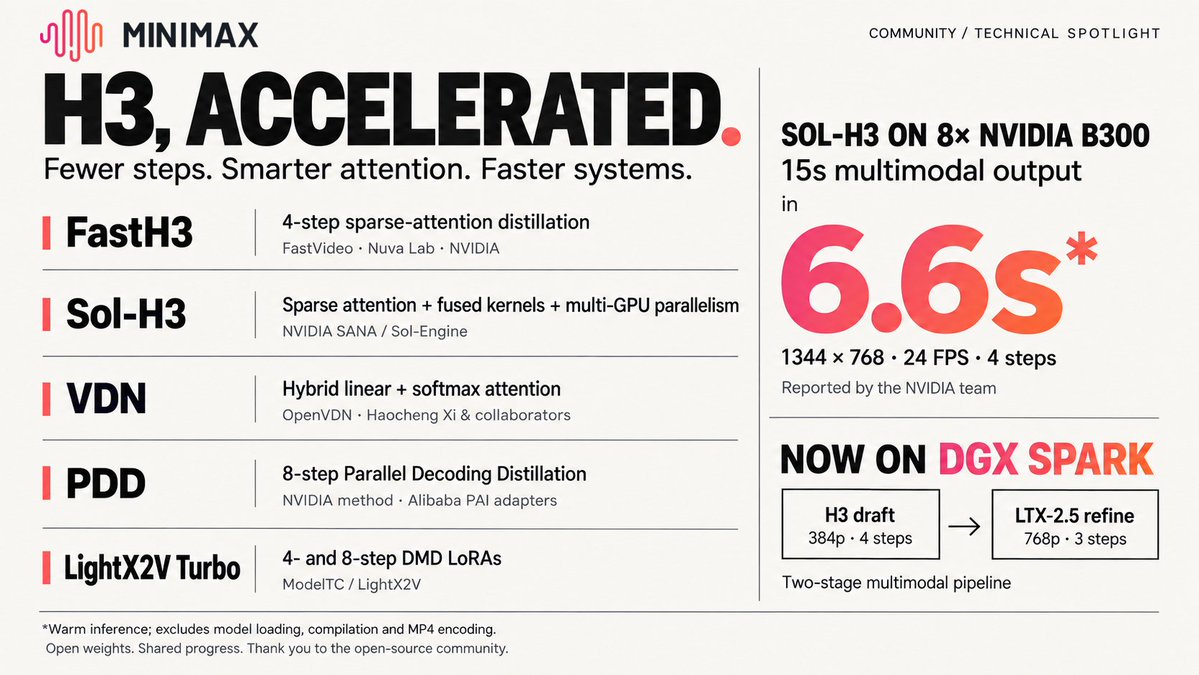
    More reference control. Fewer denoising steps. More places to run H3. The latest community contributions span 8-step reference-conditioned video + audio, 4-step distillation, sparse attention, and reference-token compression - alongside serving and workflow integrations across GPU servers, TPUs, and Apple Silicon. What matters is what this enables: more affordable experimentation, finer creative control, and more choices about where and how video generation runs. Open models become more useful when the community can improve the methods, adapt the runtime, and build workflows around them. Credit to @haoailab @yisun0618 @lanfeng491270 @guocheng_qian @Alissonerdx @ddalcu @tazmannner @HaochengXiUCB @huggingface @Jhuaplin, and the PTD, DMAD, SparkH3, TorchTPU and FlashML teams - including Zhengming Yu and zechengtang on GitHub. 11 additions to the H3 ecosystem index. Thank you to everyone building, testing, and sharing.
    Herunterladen
    MiniMax (official) @MiniMax_AI
    Open weights. Shared progress. MiniMax H3 is moving fast. We built H3 for video generation with native stereo audio and multimodal reference control. The open-source community is making that capability faster, more accessible, and easier to build on. Recent highlights: • FastH3 — FastVideo, Nuva Lab and NVIDIA: 4-step distillation, now running on DGX Spark and Apple Silicon. • Sol-H3 — NVIDIA’s SANA team: 15 seconds of 768p video + audio in 6.6 seconds on 8×B300, in the team’s warm-inference benchmark.* • VDN — Haocheng Xi and the OpenVDN team: rethinking attention for faster H3 inference, with weights, training and inference code released. • PDD — NVIDIA’s distillation method, brought to H3 by Alibaba PAI as 8-step Acc-LoRAs, now supported in ComfyUI. • LightX2V — 4- and 8-step Turbo LoRAs, with workflows for text, image and reference-conditioned video + audio. Behind every release are people training, optimizing, quantizing, testing and sharing. Special thanks to: @haoailab @nuvalab @NVIDIAAI @xieenze_jr @HaochengXiUCB @ArashVahdat @julberner @LightX2V @ComfyUI And to the individual contributors pushing the work forward: @haozhangml @cxlcl1 @lawrence_cjs @yitongli165665 @haopengl33 @songhan_mit @shanasaimoe Thank you for building with H3 and helping make it faster, more accessible, and more useful for the community. Powerful models go further when we build together. Keep pushing H3. Excited to see what comes next. 🚀 Explore the ecosystem:
    544359649.4K
  13. MiniMax (official)@MiniMax_AI
    Open weights. Shared progress. MiniMax H3 is moving fast. We built H3 for video generation with native stereo audio and multimodal reference control. The open-source community is making that capability faster, more accessible, and easier to build on. Recent highlights: • FastH3 — FastVideo, Nuva Lab and NVIDIA: 4-step distillation, now running on DGX Spark and Apple Silicon. • Sol-H3 — NVIDIA’s SANA team: 15 seconds of 768p video + audio in 6.6 seconds on 8×B300, in the team’s warm-inference benchmark.* • VDN — Haocheng Xi and the OpenVDN team: rethinking attention for faster H3 inference, with weights, training and inference code released. • PDD — NVIDIA’s distillation method, brought to H3 by Alibaba PAI as 8-step Acc-LoRAs, now supported in ComfyUI. • LightX2V — 4- and 8-step Turbo LoRAs, with workflows for text, image and reference-conditioned video + audio. Behind every release are people training, optimizing, quantizing, testing and sharing. Special thanks to: @haoailab @nuvalab @NVIDIAAI @xieenze_jr @HaochengXiUCB @ArashVahdat @julberner @LightX2V @ComfyUI And to the individual contributors pushing the work forward: @haozhangml @cxlcl1 @lawrence_cjs @yitongli165665 @haopengl33 @songhan_mit @shanasaimoe Thank you for building with H3 and helping make it faster, more accessible, and more useful for the community. Powerful models go further when we build together. Keep pushing H3. Excited to see what comes next. 🚀 Explore the ecosystem:
    Herunterladen
    8696938112K
  14. MiniMax (official)@MiniMax_AI
    MiniMax M3.1 Flash is now on @tenstorrent Cloud -bringing frontier AI to Tensix silicon, Ethernet scale-out, and an open-source stack from the team led by Jim Keller. Open weights. Diverse architectures. An open, heterogeneous AI future.🫡
    Tenstorrent @tenstorrent
    Today @MiniMax_AI released the open weights for MiniMax M3.1 Flash – available now on Tenstorrent Cloud. Explore in the playground or connect to your agent harness. Start building →
    352344169.9K
  15. Tenstorrent@tenstorrent
    Today @MiniMax_AI released the open weights for MiniMax M3.1 Flash – available now on Tenstorrent Cloud. Explore in the playground or connect to your agent harness. Start building →
    Herunterladen
    272816119.4K
  16. MiniMax (official)@MiniMax_AI
    Beiträge @MiniMax_AI
    Thanks Inferact Day 0 support!
    Inferact @inferact
    Today, we are announcing a strategic partnership with @MiniMax_AI to advance frontier production inference for open-source models. The Inferact Platform has served MiniMax M3.1 Flash in production since the day it launched. Requests through the MiniMax platform are routed to our stack alongside MiniMax’s own capacity, after we met MiniMax’s vendor verification requirements for accuracy and reliability. The Inferact Platform serves this agentic workload with guaranteed SLAs and auto-tunes the endpoint against live traffic, while MiniMax keeps control of how its model is served. Inferact also leads day-0 @vllm_project support for each MiniMax release, so the model serves at production quality the day the weights ship. The engineering from both efforts is upstreamed to vLLM. Thanks to the MiniMax team for the partnership. Read the full announcement:
    135010.9K
  17. MiniMax (official)@MiniMax_AI
    Thanks @FireworksAI_HQ for bringing M3.1 Flash to serverless on day 0! Looking sharp with the rebrand! 🎆 Try M3.1 Flash in serverless preview for your next multi-step agent workflow 🐰
    Fireworks @FireworksAI_HQ
    We have another release you don’t want to miss. @MiniMax_AI M3.1 Flash is now live on Fireworks, day 0 with the open-weights release. Built for agents that run long, multi-step work: → Cowork automation: 62.8 on AutomationBench-AA → Coding: 73.7% on DeepSWE v1.1 → Visual reasoning: 91 on BabyVision → $0.15 input / $0.60 output / $0.015 cached per 1M tokens, half the price of M3 We've heard your feedback that you want more models on serverless. So we're launching more models in preview mode, starting today with M3.1 Flash, available for two weeks. We'll be watching demand, and if the community likes it, we'll keep it around. Try it now →
    9638566.2K
  18. Inferact✓@inferact
    Today, we are announcing a strategic partnership with @MiniMax_AI to advance frontier production inference for open-source models. The Inferact Platform has served MiniMax M3.1 Flash in production since the day it launched. Requests through the MiniMax platform are routed to our stack alongside MiniMax’s own capacity, after we met MiniMax’s vendor verification requirements for accuracy and reliability. The Inferact Platform serves this agentic workload with guaranteed SLAs and auto-tunes the endpoint against live traffic, while MiniMax keeps control of how its model is served. Inferact also leads day-0 @vllm_project support for each MiniMax release, so the model serves at production quality the day the weights ship. The engineering from both efforts is upstreamed to vLLM. Thanks to the MiniMax team for the partnership. Read the full announcement:
    5149029.5K
  19. Fireworks✓@FireworksAI_HQ
    We have another release you don’t want to miss. @MiniMax_AI M3.1 Flash is now live on Fireworks, day 0 with the open-weights release. Built for agents that run long, multi-step work: → Cowork automation: 62.8 on AutomationBench-AA → Coding: 73.7% on DeepSWE v1.1 → Visual reasoning: 91 on BabyVision → $0.15 input / $0.60 output / $0.015 cached per 1M tokens, half the price of M3 We've heard your feedback that you want more models on serverless. So we're launching more models in preview mode, starting today with M3.1 Flash, available for two weeks. We'll be watching demand, and if the community likes it, we'll keep it around. Try it now →
    Herunterladen
    101011418.1K
  20. MiniMax (official)@MiniMax_AI
    MiniMax (official)
    RT @0G_labs: The meter's off. MiniMax M3.1 Flash is free on 0G Private Computer until Oct 24, 13:00 UTC. No balance needed, just an API key. Let your agent run with @MiniMax_AI
    0G Labs @0G_labs
    Save your longest agent run for Wednesday. MiniMax M3.1 Flash goes free on 0G Private Computer for 3 days, from Oct 21, 13:00 UTC. No balance needed, just an API key. Point your Hermes Agent at it.
    01401.1K
  21. MiniMax (official)@MiniMax_AI
    MiniMax (official)
    RT @SandbaseAI: Build with MiniMax M3.1 Flash for FREE. ⚡ You build. We cover the credits. 🌆 Remix any city, any way you imagine. 🏆 Compete for the $3,000 grand prize. Powered by @MiniMax_AI × SandBase Lab. Pick a city. Build your version. Make it yours.
    010801.3K
  22. 0G Labs✓@0G_labs
    Save your longest agent run for Wednesday. MiniMax M3.1 Flash goes free on 0G Private Computer for 3 days, from Oct 21, 13:00 UTC. No balance needed, just an API key. Point your Hermes Agent at it.
    Herunterladen
    8136819.2K
  23. MiniMax (official)@MiniMax_AI
    MiniMax (official)
    RT @Modular: MiniMax M3.1 Flash (aka Space Bunny) from @MiniMax_AI is live on Modular Cloud, day zero. M3.1 Flash is best in cowork automation among open models, with SOTA-level coding and engineering performance. It can ship a fix in a real codebase, then update Jira and Slack afterwards. We worked with the MiniMax team ahead of launch, so M3.1 Flash is already serving production traffic on Modular Cloud. Evaluating it for your stack? Try it now:
    0501.2K
  24. MiniMax (official)@MiniMax_AI
    MiniMax (official)
    RT @hellominds_: Congratulations to @MiniMax_AI on launching M3.1 Flash! 🎉 We're proud to be a launch partner from day one. Faster, lighter, and built for volume. Whether you’re building, learning something new or just getting through the day, your Mind is a digital companion that grows with you and helps you unlock what you never thought was possible. Try it out at
    MiniMax (official) @MiniMax_AI
    MiniMax M3.1 Flash: Space Performance + Bunny Speed 🚀🐰 Yes, Space Bunny - which has topped global leaderboards with 200T+ tokens - was an earlier version of M3.1 Flash. 💰Redefining the performance economics of agentic AI. M3.1 Flash achieves frontier-level intelligence across key tasks such as Cowork (Automation-Bench: 62%; ALE: 30%), Coding (DeepSWE: 74%) and Visual Reasoning (BabyVision: 91%), at 1/3 the cost of M3 and 3x the speed. API pricing (flat rate): $0.15 / $0.60 per 1M input/output tokens, with cache reads at $0.015 / 1M tokens. Model weights will arrive on Oct 23. API: M Plan: MiniMax Code for desktop:
    0501.3K
  25. MiniMax (official)@MiniMax_AI
    Thanks to @lightseekorg for Day-0 support with TokenSpeed!
    LightSeek Foundation @lightseekorg
    Day-0 support for @MiniMax_AI M3.1 Flash is live in TokenSpeed. DSpark speculative decoding and MXFP8 + NVFP4 mixed precision on Blackwell. TokenSpeed is featured in the official deployment guide. 📖 👉
    11218920.9K
  26. MiniMax (official)@MiniMax_AI
    Great to have Inferact as an API launch partner for M3.1 Flash! Thanks for bringing your vLLM expertise to the collaboration. Excited to keep building the serving infrastructure for complex agent workloads together.
    Inferact @inferact
    Inferact is an API launch partner for MiniMax M3.1 Flash! 🎉 We're working with @MiniMax_AI on production inference for its latest model, built for multi-step automation, real-codebase engineering and visual reasoning. M3.1 Flash scored 29.6 on Agents’ Last Exam (ALE), alongside 72.5% on AutomationBench-AA and 73.67% on DeepSWE—capabilities that matter when agents need to plan work, use tools and carry tasks through. Our contribution is the serving stack: bringing our vLLM engineering and the Inferact Platform to the collaboration. Thanks to the MiniMax team for the partnership. Explore the model and API integration:
    11446967.4K
  27. LightSeek Foundation✓@lightseekorg
    Day-0 support for @MiniMax_AI M3.1 Flash is live in TokenSpeed. DSpark speculative decoding and MXFP8 + NVFP4 mixed precision on Blackwell. TokenSpeed is featured in the official deployment guide. 📖 👉
    Herunterladen
    1322510.2K
  28. Inferact✓@inferact
    Inferact is an API launch partner for MiniMax M3.1 Flash! 🎉 We're working with @MiniMax_AI on production inference for its latest model, built for multi-step automation, real-codebase engineering and visual reasoning. M3.1 Flash scored 29.6 on Agents’ Last Exam (ALE), alongside 72.5% on AutomationBench-AA and 73.67% on DeepSWE—capabilities that matter when agents need to plan work, use tools and carry tasks through. Our contribution is the serving stack: bringing our vLLM engineering and the Inferact Platform to the collaboration. Thanks to the MiniMax team for the partnership. Explore the model and API integration:
    MiniMax (official) @MiniMax_AI
    MiniMax M3.1 Flash: Space Performance + Bunny Speed 🚀🐰 Yes, Space Bunny - which has topped global leaderboards with 200T+ tokens - was an earlier version of M3.1 Flash. 💰Redefining the performance economics of agentic AI. M3.1 Flash achieves frontier-level intelligence across key tasks such as Cowork (Automation-Bench: 62%; ALE: 30%), Coding (DeepSWE: 74%) and Visual Reasoning (BabyVision: 91%), at 1/3 the cost of M3 and 3x the speed. API pricing (flat rate): $0.15 / $0.60 per 1M input/output tokens, with cache reads at $0.015 / 1M tokens. Model weights will arrive on Oct 23. API: M Plan: MiniMax Code for desktop:
    3135315.3K
  29. MiniMax (official)@MiniMax_AI
    M3.1 Flash weights are now open 🔓 Thanks to @togethercompute for being a day-0 launch partner and bringing M3.1 Flash to production on the AI Native Cloud. Open weights, no GPUs to manage. Great building together! 🐰
    Together AI @togethercompute
    minimax m3.1 flash is now live on together ai we’re excited to be a day-0 launch partner for the model, aka space bunny m3.1 flash is built for agentic tasks, coding, computer use + cybersecurity, with a 1m context window and vision support try it now
    251451565.4K
  30. MiniMax (official)@MiniMax_AI
    Thank you for bringing H3 to TPUs! Excited to see more open-source work on efficient video inference and what it could enable: faster creative iteration, new interactive experiences, and more ways for developers to build with H3.
    SGLang @sgl_project
    Today we launch SGLang-TorchTPU, built with @Google TPU team and Meta @PyTorch team. We’re excited to see it powering production inference at Meta! SGLang-TorchTPU is a TPU plugin for SGLang that brings: - Top open models on TPU: Muse Spark Open, GLM-5.3 Flash, Kimi K3, Ling 3.1 Flash, MiniMax H3 - SGLang’s production features for large agentic workloads - Custom MegaKernel: Muse Spark Open hits 770 tok/s decode at bs=1 on InferenceX 8K/1K SGLang-TorchTPU is available now:
    9442662.9K
  31. Together AI@togethercompute
    minimax m3.1 flash is now live on together ai we’re excited to be a day-0 launch partner for the model, aka space bunny m3.1 flash is built for agentic tasks, coding, computer use + cybersecurity, with a 1m context window and vision support try it now
    Herunterladen
    1273716.5K
  32. SGLang✓@sgl_project
    Today we launch SGLang-TorchTPU, built with @Google TPU team and Meta @PyTorch team. We’re excited to see it powering production inference at Meta! SGLang-TorchTPU is a TPU plugin for SGLang that brings: - Top open models on TPU: Muse Spark Open, GLM-5.3 Flash, Kimi K3, Ling 3.1 Flash, MiniMax H3 - SGLang’s production features for large agentic workloads - Custom MegaKernel: Muse Spark Open hits 770 tok/s decode at bs=1 on InferenceX 8K/1K SGLang-TorchTPU is available now:
    Herunterladen
    82215754.1K
  33. MiniMax (official)@MiniMax_AI
    From inference to RL, ready from day one. 🐰 Thanks to the teams behind SGLang, and Miles @sgl_project alongside @NVIDIAAI and @AMD, for supporting MiniMax M3.1 Flash. Great building together!
    SGLang @sgl_project
    Space Bunny is here! 🐰 MiniMax M3.1 Flash hits >1K tok/s, bs1 decode with SGLang, production-ready from Day 0. This integration is a joint effort by @MiniMax_AI, @NVIDIAAI, @AMD, and @radixark, and you can also run RL with Miles! -Broad hardware support: NVIDIA Blackwell and Hopper (GB300/B300/B200/H200), plus AMD Instinct MI350X and MI355X. -Agentic serving at scale: ~100K total tok/s per GPU on the AgentX coding-agent trace with 96 concurrent sessions. -Speculative decoding: Supports MiniMax's DSpark draft and a DFlash2 draft trained by @radixark; supports HiCache and multimodal input. -Ultra-low-latency inference: MegaKernels deliver 2.15× faster single-request decode.
    5634159.1K
  34. MiniMax (official)@MiniMax_AI
    Beiträge @MiniMax_AI
    Tutorial + code for you to cook with. ⬇️
    10112.7K
  35. SGLang✓@sgl_project
    Space Bunny is here! 🐰 MiniMax M3.1 Flash hits >1K tok/s, bs1 decode with SGLang, production-ready from Day 0. This integration is a joint effort by @MiniMax_AI, @NVIDIAAI, @AMD, and @radixark, and you can also run RL with Miles! -Broad hardware support: NVIDIA Blackwell and Hopper (GB300/B300/B200/H200), plus AMD Instinct MI350X and MI355X. -Agentic serving at scale: ~100K total tok/s per GPU on the AgentX coding-agent trace with 96 concurrent sessions. -Speculative decoding: Supports MiniMax's DSpark draft and a DFlash2 draft trained by @radixark; supports HiCache and multimodal input. -Ultra-low-latency inference: MegaKernels deliver 2.15× faster single-request decode.
    Herunterladen
    MiniMax (official) @MiniMax_AI
    MiniMax M3.1 Flash weights are now public. 428B parameters total, 23B activated per token. Agentic performance: A generational leap in agentic tasks, coding, and cybersecurity — 76.2 on BankerToolBench, 73.7% on DeepSWE v1.1, 61.7 on OSWorld V2, 29.6 on Agents' Last Exam, and 82.2 on CyberGym. Efficient by design: MiniMax Sparse Attention and DSpark speculative decoding improve inference efficiency. Hugging Face: ModelScope: API: M Plan: MCode for desktop:
    14168722.7K
  36. MiniMax (official)@MiniMax_AI
    MiniMax M3.1 Flash + SGLang Omni: building toward a more interactive generation of voice agents. The shift ahead is from “ask, wait, listen” to conversations people can interrupt, correct, and redirect as a task unfolds. MiniMax M3.1 Flash brings intelligence and fast, concise responses. SGLang Omni adds streaming, conversation state, and interruption handling so users can redirect conversations in real time. Together, they give developers a foundation to explore proactive tutors, support agents, and hands-free copilots - pairing Flash’s capabilities with infrastructure for continuous interaction. Thanks to the SGLang Omni team for exploring this direction with M3.1 Flash! ✨
    Herunterladen
    Guitar Cat + LLM 「Will @ SGLang Summit in SF」 @GenAI_is_real
    We just tried @MiniMax_AI's M3.1 Flash in our SGLang Omni cascaded voice interaction system, and the experience was genuinely impressive! 🐰🚀 Our original pipeline was Qwen3-ASR → Qwen3 LLM → Qwen3-TTS. We replaced the locally hosted LLM with the MiniMax M3.1 Flash API while keeping the rest of the pipeline unchanged, and recorded a demo to see how it performs in real conversations. The results were excellent. M3.1 Flash responded incredibly fast, understood our questions well, and consistently delivered sharp, concise, and direct answers. The conversation felt remarkably smooth and natural. One thing I increasingly appreciate about voice agents is that intelligence alone isn't enough. Unlike text, users can't easily skim an audio response. A model that understands what you need and gets straight to the point can make a huge difference to the overall interaction experience. This is also what makes the modular architecture of SGLang Omni so exciting to me. We can swap individual components, connect local speech models with frontier LLM APIs, and immediately explore how different models change the end-to-end interaction experience. Huge congrats to the MiniMax team! Really impressive work, and we're excited to explore more together. 🔥
    221855969.9K
  37. MiniMax (official)@MiniMax_AI
    MiniMax M3.1 Flash weights are now public. 428B parameters total, 23B activated per token. Agentic performance: A generational leap in agentic tasks, coding, and cybersecurity — 76.2 on BankerToolBench, 73.7% on DeepSWE v1.1, 61.7 on OSWorld V2, 29.6 on Agents' Last Exam, and 82.2 on CyberGym. Efficient by design: MiniMax Sparse Attention and DSpark speculative decoding improve inference efficiency. Hugging Face: ModelScope: API: M Plan: MCode for desktop:
    1742653.9K416K
  38. Guitar Cat + LLM 「Will @ SGLang Summit in SF」✓@GenAI_is_real
    We just tried @MiniMax_AI's M3.1 Flash in our SGLang Omni cascaded voice interaction system, and the experience was genuinely impressive! 🐰🚀 Our original pipeline was Qwen3-ASR → Qwen3 LLM → Qwen3-TTS. We replaced the locally hosted LLM with the MiniMax M3.1 Flash API while keeping the rest of the pipeline unchanged, and recorded a demo to see how it performs in real conversations. The results were excellent. M3.1 Flash responded incredibly fast, understood our questions well, and consistently delivered sharp, concise, and direct answers. The conversation felt remarkably smooth and natural. One thing I increasingly appreciate about voice agents is that intelligence alone isn't enough. Unlike text, users can't easily skim an audio response. A model that understands what you need and gets straight to the point can make a huge difference to the overall interaction experience. This is also what makes the modular architecture of SGLang Omni so exciting to me. We can swap individual components, connect local speech models with frontier LLM APIs, and immediately explore how different models change the end-to-end interaction experience. Huge congrats to the MiniMax team! Really impressive work, and we're excited to explore more together. 🔥
    Herunterladen
    MiniMax (official) @MiniMax_AI
    MiniMax M3.1 Flash: Space Performance + Bunny Speed 🚀🐰 Yes, Space Bunny - which has topped global leaderboards with 200T+ tokens - was an earlier version of M3.1 Flash. 💰Redefining the performance economics of agentic AI. M3.1 Flash achieves frontier-level intelligence across key tasks such as Cowork (Automation-Bench: 62%; ALE: 30%), Coding (DeepSWE: 74%) and Visual Reasoning (BabyVision: 91%), at 1/3 the cost of M3 and 3x the speed. API pricing (flat rate): $0.15 / $0.60 per 1M input/output tokens, with cache reads at $0.015 / 1M tokens. Model weights will arrive on Oct 23. API: M Plan: MiniMax Code for desktop:
    542513.1K
  39. MiniMax (official)@MiniMax_AI
    Beiträge @MiniMax_AI
    Thanks SGLang day 0 support.
    SGLang @sgl_project
    Space Bunny is here! 🐰 MiniMax M3.1 Flash hits >1K tok/s, bs1 decode with SGLang, production-ready from Day 0. This integration is a joint effort by @MiniMax_AI, @NVIDIAAI, @AMD, and @radixark, and you can also run RL with Miles! -Broad hardware support: NVIDIA Blackwell and Hopper (GB300/B300/B200/H200), plus AMD Instinct MI350X and MI355X. -Agentic serving at scale: ~100K total tok/s per GPU on the AgentX coding-agent trace with 96 concurrent sessions. -Speculative decoding: Supports MiniMax's DSpark draft and a DFlash2 draft trained by @radixark; supports HiCache and multimodal input. -Ultra-low-latency inference: MegaKernels deliver 2.15× faster single-request decode.
    20388.5K
  40. MiniMax (official)@MiniMax_AI
    Thanks to the NVIDIA NeMo team for day-0 fine-tuning support for MiniMax-M3.1-Flash! 🐰 What magic will this 🐰 bring in the post train scenario?
    Huiying Li @huiying_lii
    You’ve probably already used it: Space Bunny pushed 200T+ tokens before anyone knew it was MiniMax-M3.1-Flash. Now it’s open weights 🔥 Thank you @MiniMax_AI for open sourcing it! Day-0 fine-tuning in NVIDIA NeMo-AutoModel ✅ FSDP2, expert, pipeline, and context parallelism, ✅scaling up to 128 GPUs, and the NVFP4 checkpoint loads directly.
    4737762.5K
  41. Huiying Li✓@huiying_lii
    You’ve probably already used it: Space Bunny pushed 200T+ tokens before anyone knew it was MiniMax-M3.1-Flash. Now it’s open weights 🔥 Thank you @MiniMax_AI for open sourcing it! Day-0 fine-tuning in NVIDIA NeMo-AutoModel ✅ FSDP2, expert, pipeline, and context parallelism, ✅scaling up to 128 GPUs, and the NVFP4 checkpoint loads directly.
    131912.7K