#ApacheSpark#SparkSQL 3.2.0 is coming up with a new REBALANCE hint for Adaptive Query Execution to rebalance skewed tables automatically!
👉
👉
(Wonder if @waitingforcode has already covered this? 🤔)
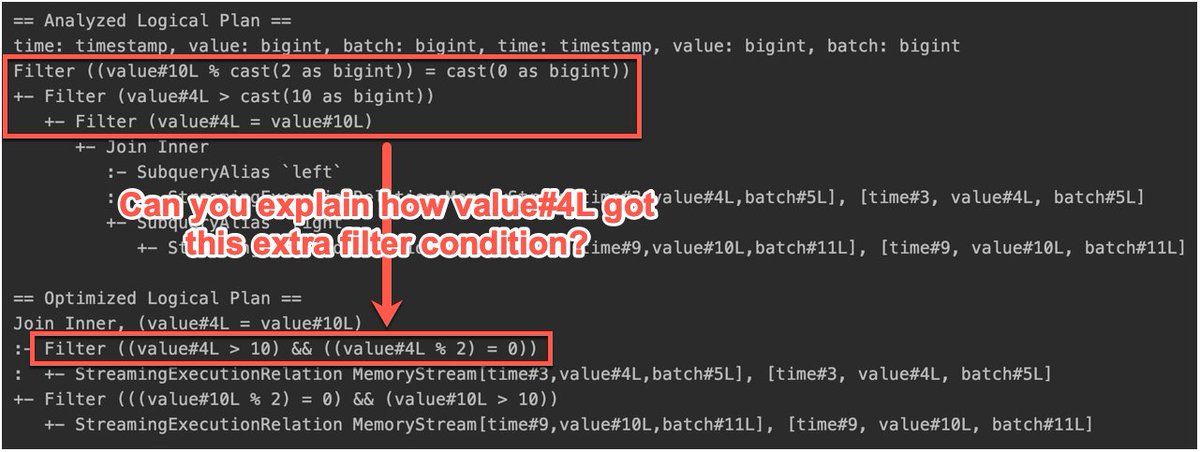
Found this filter logical optimization in #ApacheSpark#SparkSQL quite interesting 🤔
Quiz:
1️⃣(easy) Can you explain how the value attribute got this extra filter condition?
2️⃣(hard) What's the name of the optimization?
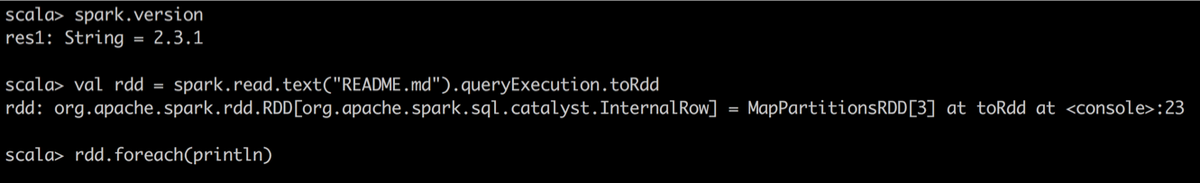
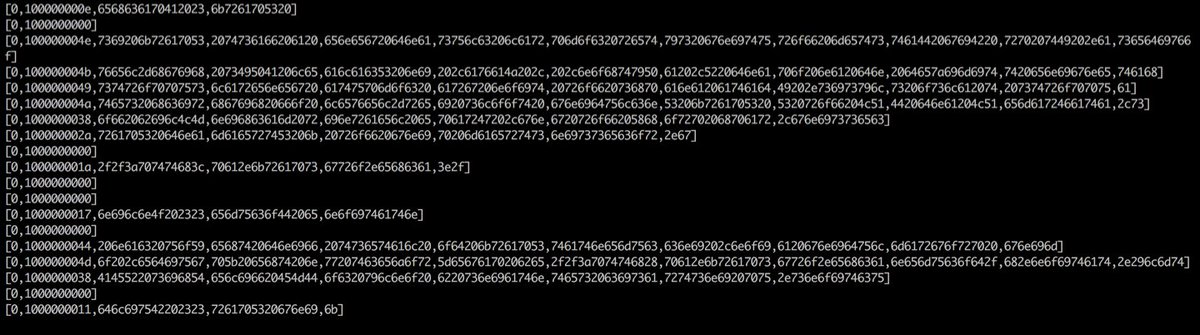
😳Can you » guess « what you get in stdout when you execute the following code? Just guess before you execute it in spark-shell. Do you know what the lines are? Took me a while to understand and was very surprised (!) #ApacheSpark#SparkSQL
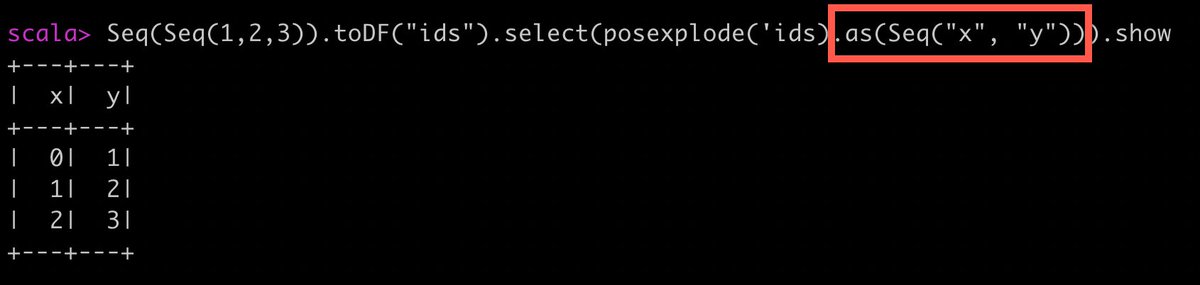
You can use multi-id aliases in #SparkSQL 👍
👉
Exactly the reason why I **love** exploring the sources of #ApacheSpark (and reading docs of various SQL engines, e.g. Snowflake) ❤️
👉
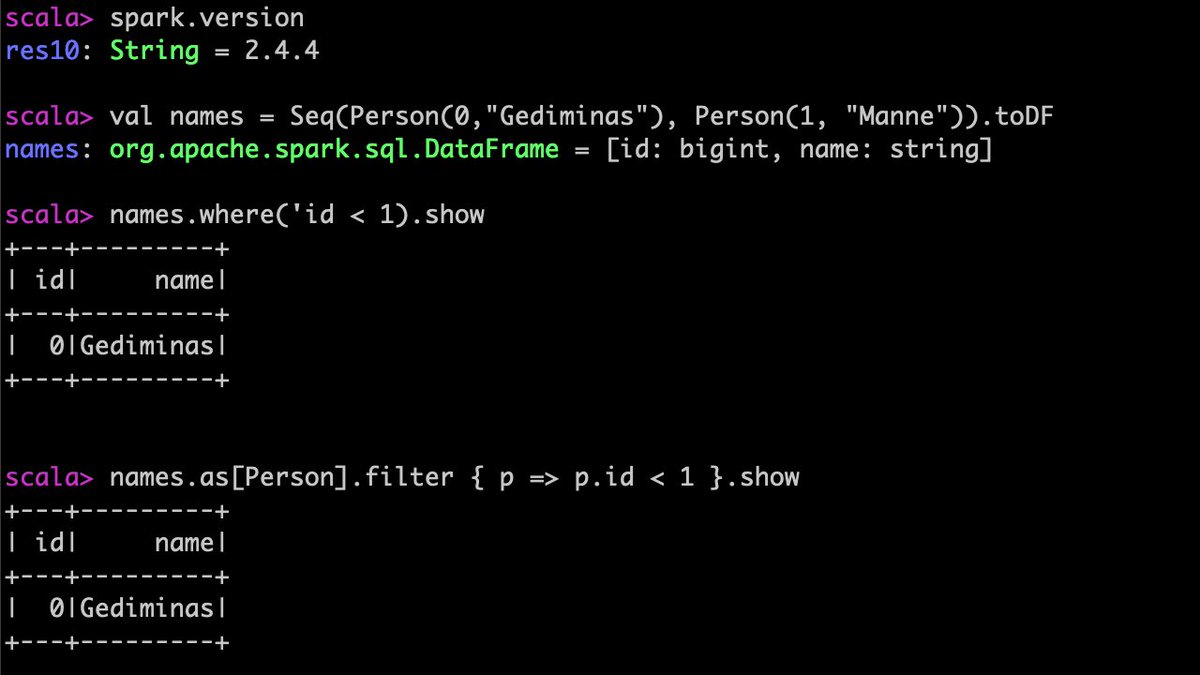
#help Can anyone explain this behaviour in #ApacheSpark#SparkSQL 2.4.4? 🙏
Same datasets, same query but different execution plans? I can understand why the type-safe version is slower, but 2 jobs?! 🤔
Kept hearing about data partitioning as a way to make many reads from a #DeltaLake table faster *somehow* but...that's what I "discovered" today...without WHERE clause (that #SparkSQL can push down) the whole table is scanned anyway (with or without partitions).
I’m sold to the idea of recording videos about #ApacheSpark#SparkSQL that’d be no longer than 5-10 minutes (such short videos have always worked best for me). Anything in particular you’d like to watch first?
Added brand new problems to solve and sharpen your skills in #ApacheSpark#SparkSQL
👉
Going to give some a try tomorrow during an online workshop I'm hosting this week. Quite a few are really challenging. Beware! 💪
I thought I knew window functions by heart and, more importantly, the difference between RANGE and ROWS BETWEENs.
But I don't! 😬
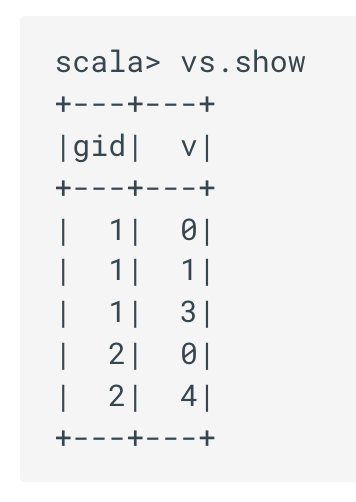
Struggling to write a query to find gaps between time series data?! How to catch these 4 groups?! It's RANGE, isn't it?!
#ApacheSpark#SparkSQL
Has anyone been considering Catalyst Expressions to write UDFs in #SparkSQL?
This code-generated execution mode seems very promising but I feel I'm lacking experience with this part of Spark. Anyone?
#ApacheSpark
Happy to announce that...I finally understood the role of CacheManager and InMemoryRelation logical operator in #ApacheSpark#SparkSQL 🎉
👉
You should hear me laughing at myself when after all the years with Spark I understood what I've been teaching 🤣
Some time ago, I was analyzing the query plan generated by my #ApacheSpark app and found a mysterious partial operations. I decided then to investigate 🕵️♀️ and today's post starts a series about aggregations in #SparkSQL