Post con #SparkSQL

#SparkSQL

Post pubblici su X che usano #SparkSQL.

Hashtag correlati

  1. Jacek Laskowski@jaceklaskowski
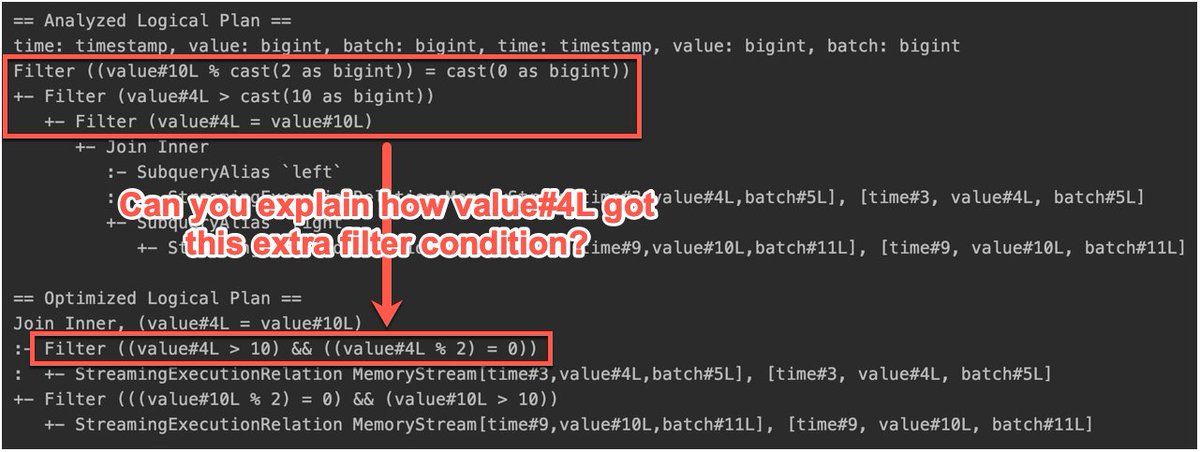
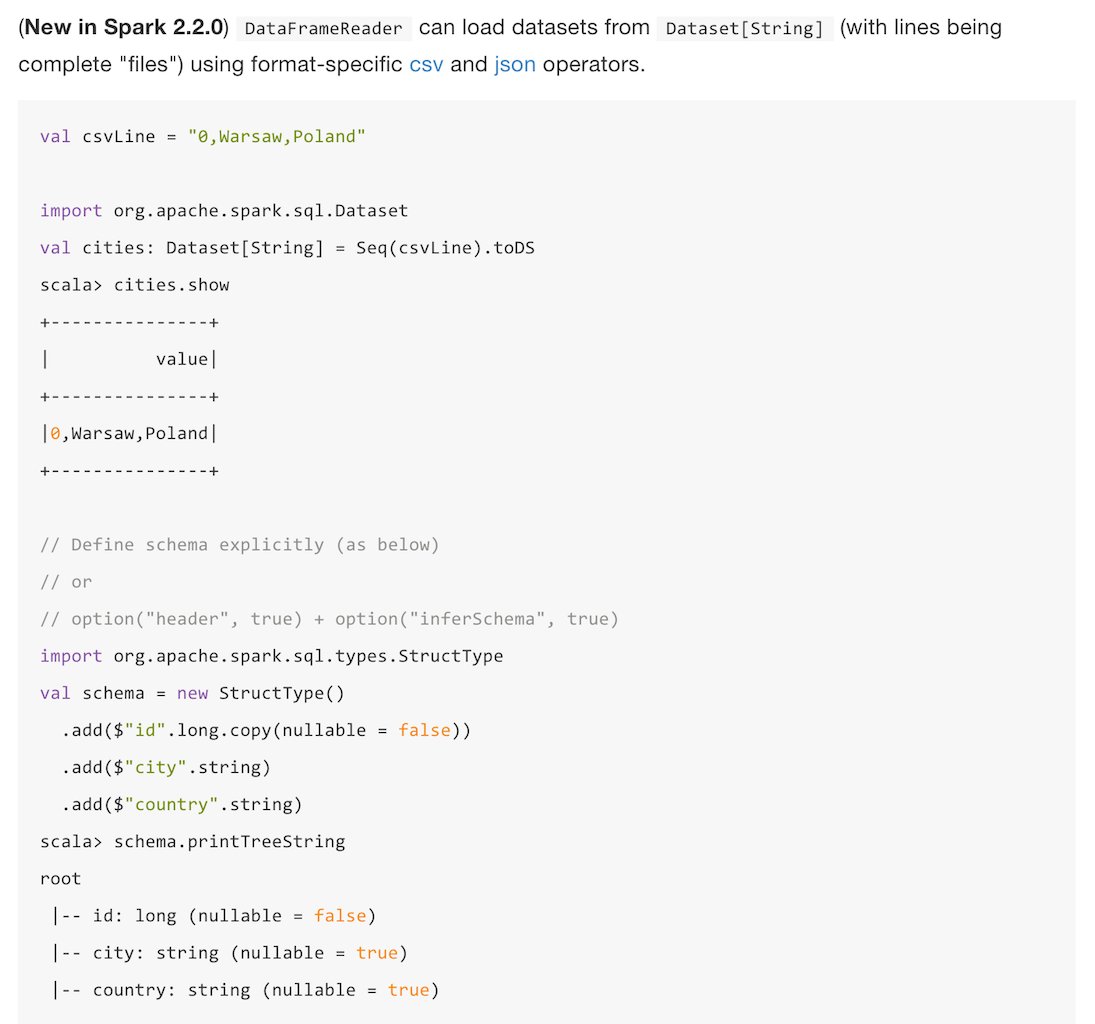
    Found this filter logical optimization in #ApacheSpark #SparkSQL quite interesting 🤔 Quiz: 1️⃣(easy) Can you explain how the value attribute got this extra filter condition? 2️⃣(hard) What's the name of the optimization?
    Scarica
    2220
  2. Jacek Laskowski@jaceklaskowski
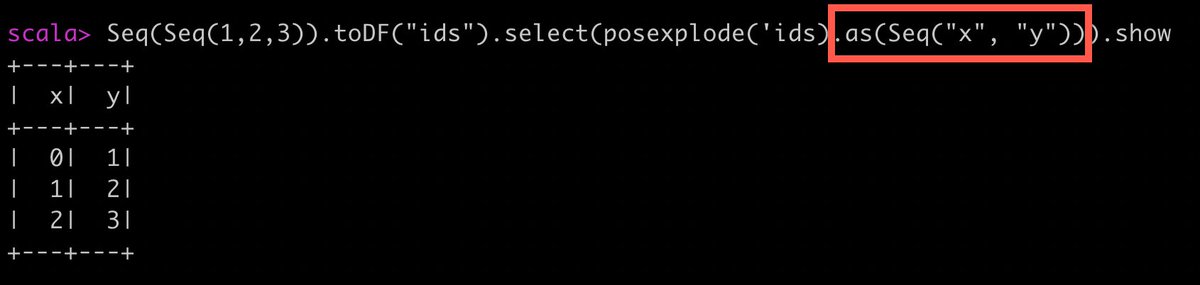
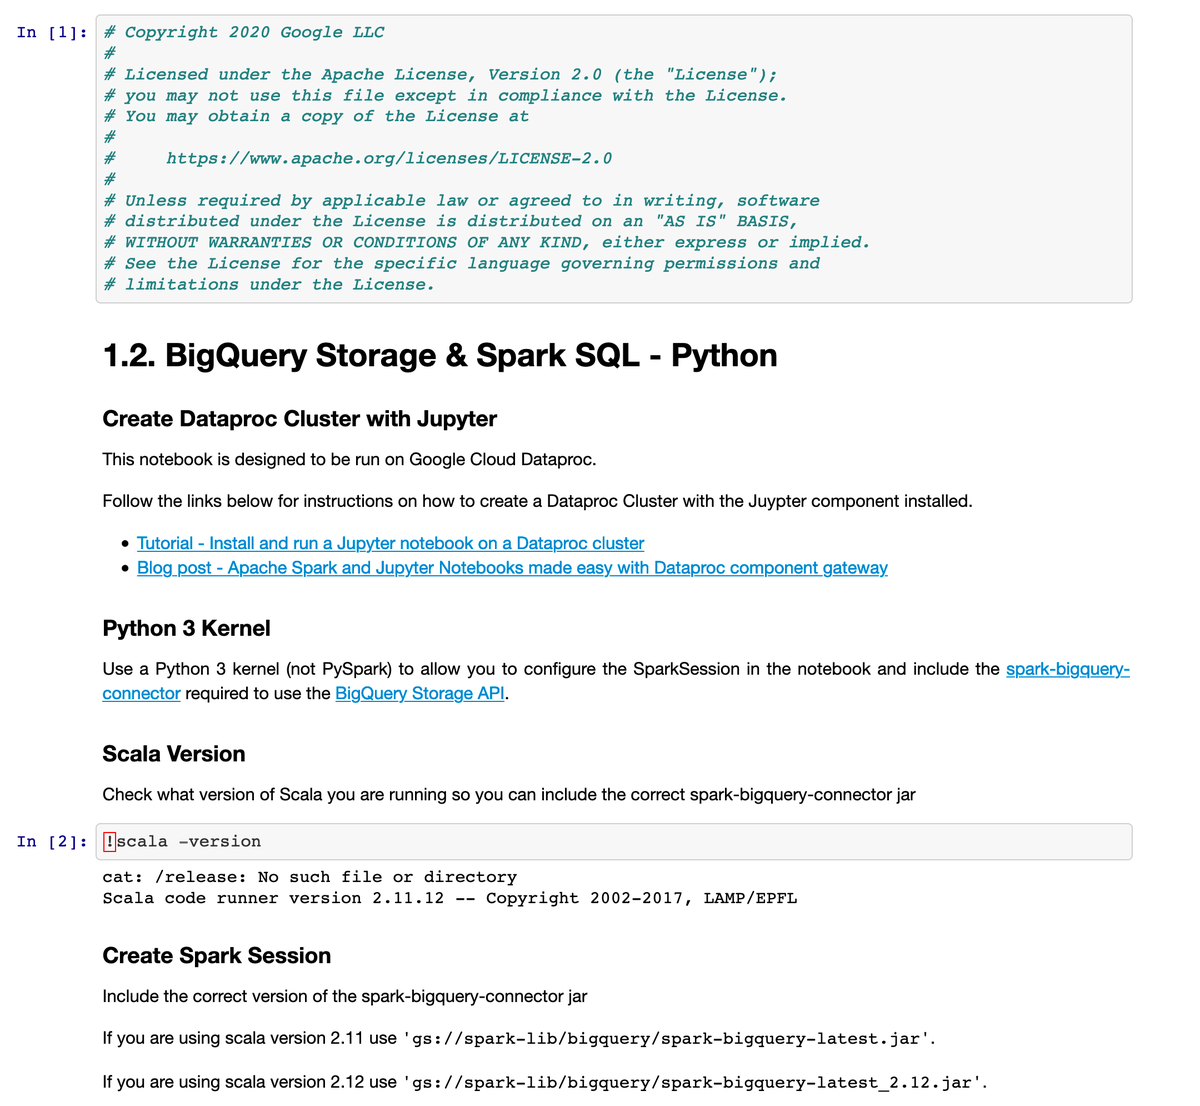
    You can use multi-id aliases in #SparkSQL 👍 👉 Exactly the reason why I **love** exploring the sources of #ApacheSpark (and reading docs of various SQL engines, e.g. Snowflake) ❤️ 👉
    Scarica
    1217
  3. Matei Zaharia✓@matei_zaharia
    @matei_zaharia
    #ApacheSpark today is very different from the research version released in 2010. First of all, the most widely used programming language for Spark is now Python. On @Databricks, we see that 68% of commands in notebooks are in Python, which is 6x more than Scala.
    Scarica
    1927
  4. Matei Zaharia✓@matei_zaharia
    @matei_zaharia
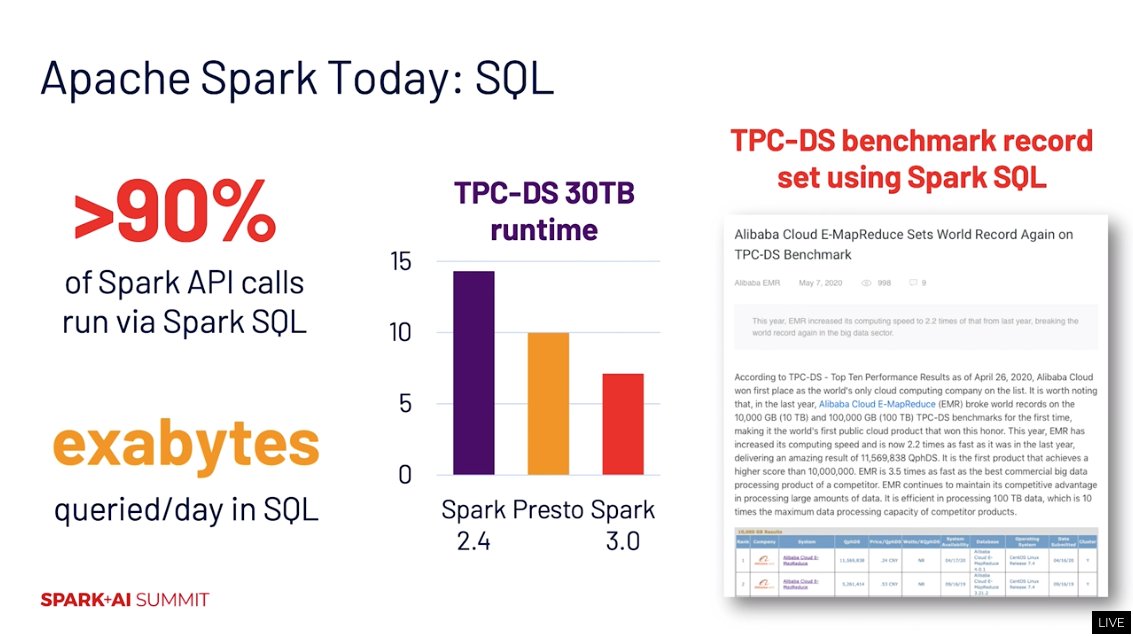
    Also, most computations on Spark today run through the #SparkSQL engine, added in 2014. Even in Python and Scala, 90% of API calls go through the DataFrame API that runs on Spark SQL. Thus the community has invested a lot in Spark SQL recently, with Spark 3.0 giving a 2x speedup.
    Scarica
    1817
  5. Jacek Laskowski@jaceklaskowski
    I’m sold to the idea of recording videos about #ApacheSpark #SparkSQL that’d be no longer than 5-10 minutes (such short videos have always worked best for me). Anything in particular you’d like to watch first?
    12024
  6. Bartosz Konieczny@waitingforcode
    Adaptive Query Execution in #SparkSQL is a set of features that can optimize the query execution at runtime. Today it's time to discover the first of them called shuffle partitions coalesce. If you want to learn more about it 👉
    0719
  7. Jacek Laskowski@jaceklaskowski
    What a day! It’s only now when I can consider myself able to explain conversions between #SparkSQL abstractions (LogicalPlan, QueryExecution and Dataset/DataFrame). The talk at @SparkAISummit in London is going to be very in-depth! #ApacheSpark
    1314
  8. Bartosz Konieczny@waitingforcode
    Some time ago, I was analyzing the query plan generated by my #ApacheSpark app and found a mysterious partial operations. I decided then to investigate 🕵️‍♀️ and today's post starts a series about aggregations in #SparkSQL
    2617
  9. Bartosz Konieczny@waitingforcode
    In March I wrote about partition-based sort in #ApacheSpark #SparkSQL. This feature is used in partitionBy method I described in my today's post
    1218
  10. Mostra altri post