#Calgorithm içeren gönderiler

#Calgorithm

X'te #Calgorithm kullanan herkese açık gönderiler.

İlgili etiketler

  1. Mustafa.✓@oprydai
    this is what happens when you stop designing mechanical parts based on how they should look and start designing them based on how forces actually flow through them. the original component weighs 2.06 kg. after topology optimization, the mass drops to 0.766 kg, roughly a 63% reduction. the interesting part isn’t just the weight reduction. it’s the geometry that emerges. instead of a solid block of material, you get an interconnected network of branches and ribs that preserve the important load paths while removing material that contributes relatively little to the structure. topology optimization works by turning structural design into a mathematical problem. you define the loads, mounting points, material properties, available design space and performance constraints. then an optimization algorithm, often coupled with finite element analysis, iteratively redistributes material to improve the objective, such as minimizing compliance under a volume constraint. what emerges often looks surprisingly biological. bones, tree branches and trabecular structures follow similar principles of distributing material where mechanical demands are greatest. the similarity isn’t accidental, although biological structures evolve under many more constraints than mechanical optimization models. this is where computational engineering and additive manufacturing become incredibly powerful together. traditional manufacturing often forces engineers to simplify geometry because complicated internal structures are difficult or expensive to produce. additive manufacturing makes many of those geometries practical. lightweight aerospace brackets, robotic arms, suspension components, structural joints and mechanical linkages can all benefit from this approach. but optimization is only the beginning. the resulting part still needs validation for stress, fatigue, buckling and manufacturability. the deeper idea is that engineering is moving from drawing geometry to defining constraints and letting mathematics discover efficient structures within them.
    İndir
    697573839.7K
  2. Nathan Lambert✓@natolambert
    Was reading the score-centering RL paper to add some notes on it the my book, and they have a great table in the appendix on the different importance sampling based train-inference mismatch methods in RL. These have been the biggest focus of RL algorithm research since the GRPO takeoff, imo.
    İndir
    323344423.9K
  3. Yacine Mahdid✓@yacinelearning
    is there any part of the deep learning algorithm stack that isn’t riddled with bugs
    Ziming Liu @ZimingLiu11
    There is a "bug" in commonly used activation functions (ReLU/SiLU/GeLU etc.) ---- The mean of post-activations is not zero. This bug, however small it seems, leads to pathologies of training dynamics, including loss spikes & representation overshooting. By removing the bug, we get improved performance in LLMs and ViTs. The science of AI can never be under-estimated.
    18426717.2K
  4. Ziming Liu✓@ZimingLiu11
    There is a "bug" in commonly used activation functions (ReLU/SiLU/GeLU etc.) ---- The mean of post-activations is not zero. This bug, however small it seems, leads to pathologies of training dynamics, including loss spikes & representation overshooting. By removing the bug, we get improved performance in LLMs and ViTs. The science of AI can never be under-estimated.
    İndir
    3068784106K
  5. Tim Haldorsson✓@TimHaldorsson
    Engagement up? New algo good Engagement down? New algo bad this is how commentary works, while X is just trying to improve the user experience for us all.
    211441.4K
  6. FlameseN アナリスト ₿✓@TraderFlameseN
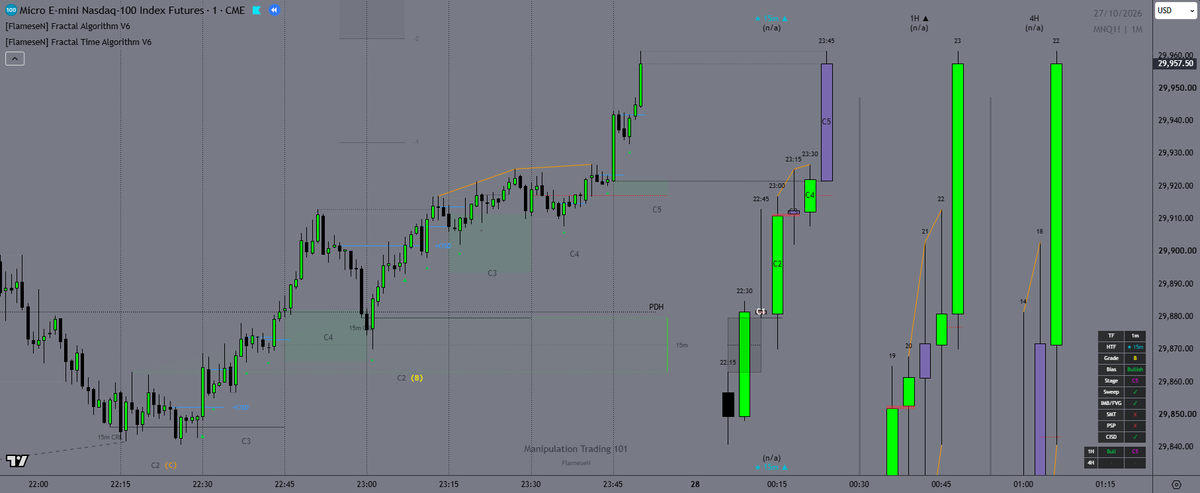
    The Algorithm caught the bottom, the continuation & sent everyone alerts straight to their phone! It'll grade each setup [A+ → D] & send you Graded Alerts for C2 pending/confirmed, CISD's & Continuation OB's. Like & comment "Automatic" & I'll dm you the link!
    İndir
    608784.9K
  7. Michael R. Bock✓@michaelrbock
    i know it seems too simple to be true, but this algorithm is the "secret" behind every RL env/data company at the moment in other words, this is the algorithm for RSI
    İndir
    33601.4K170K
  8. Mohammad Hajiaghayi (IG@mhajiaghayi,YT:hajiaghayi)@MTHajiaghayi
    Our THEO system has formalized László Babai’s landmark quasipolynomial-time Graph Isomorphism algorithm in Lean 4—uncovering 90+ corrections and proving an explicit exp(O(log^5 n)) running-time bound, down to a RAM model.
    61813614.1K
  9. elvis✓@omarsar0
    Highly recommended paper from CMU and others on how foundation models get trained. It fundamentally asks whether pretraining, midtraining, SFT, and RL really need to be separate stages. They show that this separation isn't fundamental. All of these stages can run under a single likelihood-based algorithm, which they call unified training. The key step treats suitable RL objectives as maximum-likelihood fitting to model-generated targets. RL generations and static data then share one loss and one trainer. This changes the design problem. You now choose which data to train on, in what proportions and when. Staged training becomes one special case. They first trained a 124M model from scratch on reasoning puzzles. The best unified runs beat staged training on the RL tasks. They also beat it on larger puzzles the model never saw. Those runs reused the midtraining corpus up to 4 times. Staged training lost accuracy when midtraining ran past its best budget. Under a fixed compute budget, unified training had the best accuracy at the smallest and largest budgets. Staged training led at intermediate budgets. The real-world test used a 0.76B model on math RL, with 0% to 5% midtraining data mixed in. Math accuracy stayed similar while retention improved. Coding accuracy dropped as the mix grew. Continual learning gave the clearest result. After math training, all unified models beat staged training on final coding accuracy, despite starting lower. The 5% mix did best. The experiments are small-scale. The authors have not found a mixture or schedule that works best across the board. Chat with Paper:
    İndir
    372215516.9K
  10. Timothy Gowers @wtgowers@wtgowers
    Occasionally Twitter's algorithm throws up something good for me. This was an example.
    Mike Lawler @mikeandallie
    Fun little puzzle from @octonion I was reminded of today
    24933352.5K
  11. Mathematica✓@mathemetica
    Why does a simple line sometimes take longer to learn than a whole forest of trees? Different algorithms scale differently with data. Linear models solve a system whose cost grows with features cubed, while trees and forests often grow more gently with samples. k-NN skips training entirely, then pays later at prediction time. Neural nets trade both for capacity. Choosing the right complexity keeps models usable on real data instead of theoretical ones. The fastest algorithm on paper is useless if it cannot finish before the world changes. Which complexity trade-off have you hit hardest in practice?
    İndir
    3432886.3K
  12. Roko ⏸️🆁✓@RokoMijic
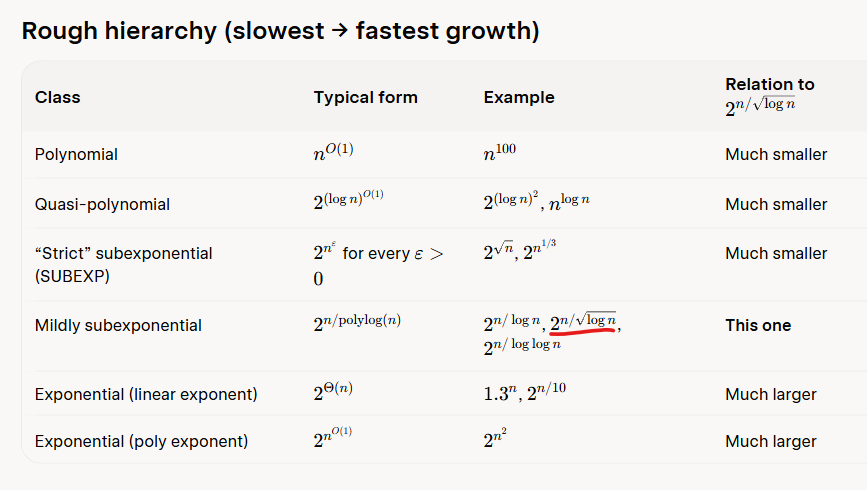
    The refutation of the Exponential Time Hypothesis is somewhat deflationary when you look into the details. The Exponential Time Hypothesis says that a certain problem (3-satisfiability) cannot be solved in less than 2^n time. They gave an algorithm that solves it in 2^(n/√log(n)) time. It feels like mathematical superintelligence is pushing the edges of human mathematics and only changing the landscape slightly.
    İndir
    Ryan Williams @rrwilliams.bsky.social @rrwilliams
    An internal model at OpenAI has produced a claimed refutation of ETH! Russell Impagliazzo, Mohan Paturi, and I have been asked to help organize an open and independent examination of this claim. 1/4
    432846368.2K
  13. Ryan Williams @rrwilliams.bsky.social@rrwilliams
    An internal model at OpenAI has produced a claimed refutation of ETH! Russell Impagliazzo, Mohan Paturi, and I have been asked to help organize an open and independent examination of this claim. 1/4
    3007587.4K3.7M
  14. Locked On Wolfpack✓@LO_Wolfpack
    THURSDAY (10/29) Locked On Wolfpack: 🔎 Would You Consider… Dan Mullen? How about Billy Napier? 🐻 Are you ready for the #Calgorithm? 🏀 Does NC State have the Top 3PT Shooting Team in the ACC? 📺: 🎧: 📸: Raymond Carlin III-Imagn Images, JMU Football
    İndir
    100121.4K
  15. Carlos That Notices Things✓@QuetzalPhoenix
    Reminder that the algorithm is in a real hair trigger. If all you like is content that makes you angry, that is all you will get. You need to program your account, use the like as a way to program, dont depend on your "for you" page. Again, a hair trigger algo!
    404253432.1K
  16. Boiler.games✓@boilergame
    Dear algorithm, Please let me cook 💵 Coming 🔜
    İndir
    2612443347.7K
  17. levent✓@__alpoge__
    “The core algorithm was found on October 16 by an internal Claude research model with 14M output tokens and no human input. Anthropic researchers worked with Claude to improve the presentation, resulting in this paper.”
    1181372.5K649K
  18. signüll✓@signulll
    it's pretty clear that frontier science is now approaching a historic inversion where humans will increasingly stop being the primary discoverers & will mostly become the ones defining objectives, maybe some constraints, & meaning if even that. if what is announced is this incredible, imagine the work here that ai labs are not disclosing that would have massive implications esp economically. e.g. has any ai lab discovered an efficient algorithm for factoring? that would mean the end of modern security & crypto.
    25734223.6K
  19. Quant Science✓@quantscience_
    RenTec uses Hidden Markov Models in trading. The technique generated 60% returns per year over 30 years. One of the co-founders of RenTec's name is in the algorithm! Here's how it works:
    İndir
    61513316.6K
  20. FlameseN アナリスト ₿✓@TraderFlameseN
    I'm so proud of what I built. Nothing ever needing drawn on the chart is a life hack. It took me a year to perfect the logic of this Algorithm & now you can sit back & get Graded Alerts {A+ → D} straight to your phone. Never missing A+ setups again can change everything!
    İndir
    187577.2K
  21. Daha fazla gönderi göster