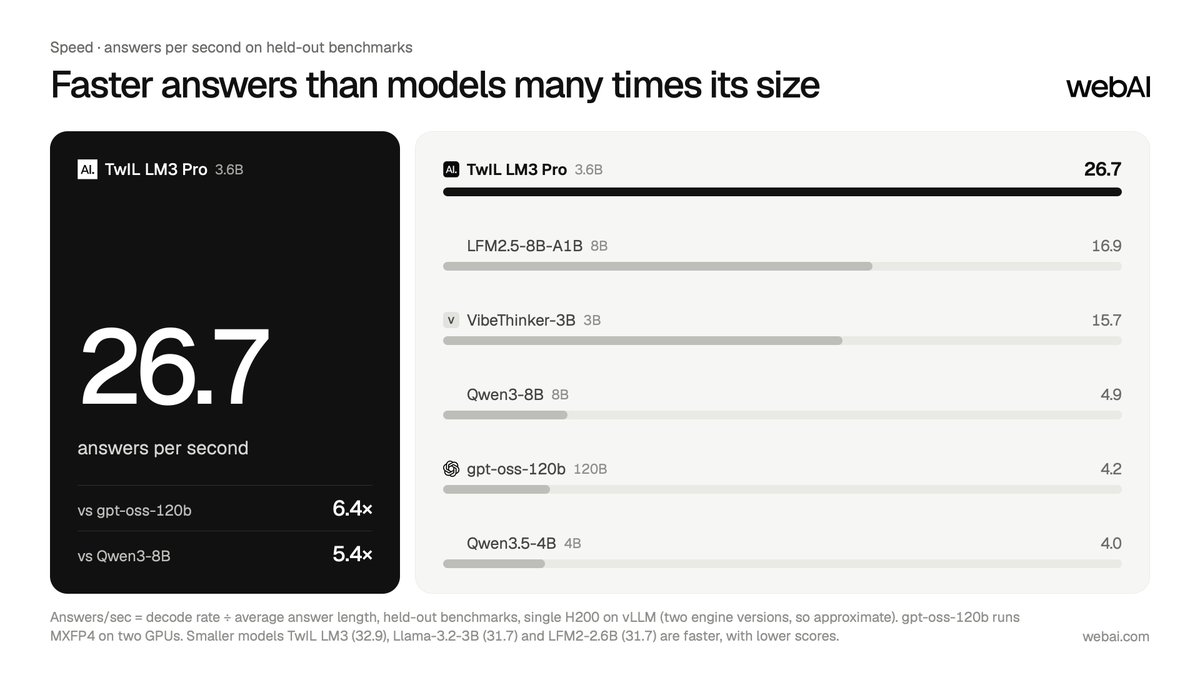

The cost of completing a task matters more than the raw intelligence of the model running it.
That’s the thesis behind TwIL-8B, our new 8.8B reasoning model. Open weights. Runs on hardware you already own.
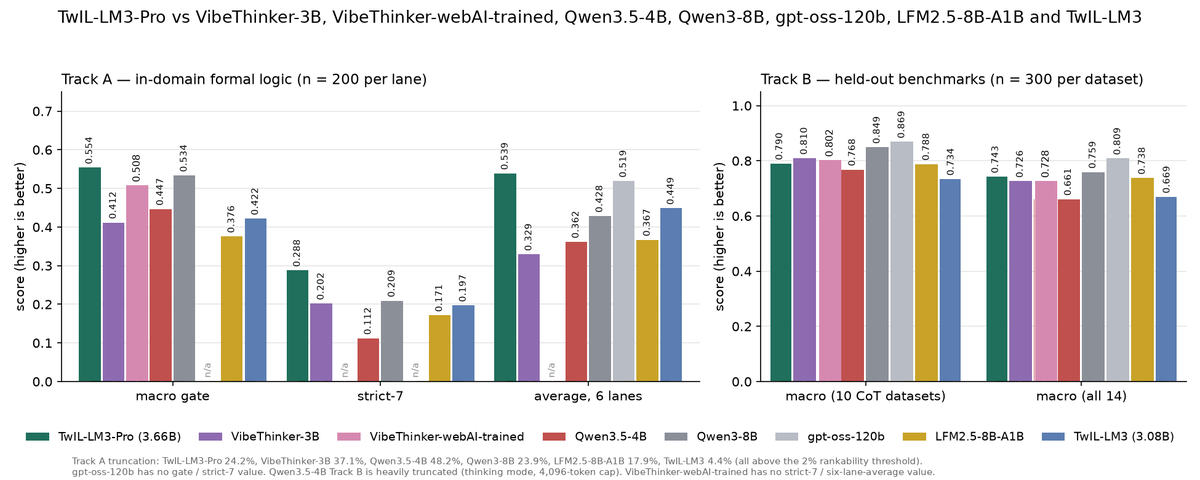
Against Qwen3.5-9B, it opens a 16-point lead on LiveCodeBench (81.6 vs 65.6) and tops MATH-500 (98.2 vs 96.6). Against Gemma 4 31B, 4x the size, it still wins on MATH-500 (98.2 vs 87.9) and AIME 2025 (88.3 vs 87.1).
Tiny by frontier standards. Does the reasoning work anyway.
Download the model on @huggingface:
915867.1K