webAI✓

@thewebAI

Sovereign AI for enterprises. Build AI you own on infrastructure you control. Private, specialized models that run where your data lives.

32 Seguiti6.4K Follower534 Post
  1. webAI✓@thewebAI
    The cost of completing a task matters more than the raw intelligence of the model running it. That’s the thesis behind TwIL-8B, our new 8.8B reasoning model. Open weights. Runs on hardware you already own. Against Qwen3.5-9B, it opens a 16-point lead on LiveCodeBench (81.6 vs 65.6) and tops MATH-500 (98.2 vs 96.6). Against Gemma 4 31B, 4x the size, it still wins on MATH-500 (98.2 vs 87.9) and AIME 2025 (88.3 vs 87.1). Tiny by frontier standards. Does the reasoning work anyway. Download the model on @huggingface:
    Scarica
    915867.1K
  2. webAI✓@thewebAI
    webAI
    RT @Davidstout: Just days after we released TwIL-8B, the Hugging Face research team is already pushing its capabilities further. Today, @huggingface published new research exploring how reinforcement learning and lightweight LoRA adapters can turn reasoning models into capable AI agents. They included @thewebAI TwIL-8B alongside models from Liquid AI. The early results are encouraging. Despite never being explicitly trained for agentic tool use, TwIL-8B is already outperforming the smaller LFM3-1.7B across all three agent harnesses in preliminary baseline evaluations. Now they're exploring how much further those capabilities can improve through specialized reinforcement learning. One base model. Many specialized capabilities. This is a direction we strongly believe in at webAI. Intelligence should be adaptable, efficient, and increasingly capable without requiring ever-larger models. But what excites me most is the collaboration happening across the open research community. We built TwIL to push the boundaries of what smaller models can accomplish. Seeing the Hugging Face team build on that work almost immediately is exactly why open research matters. Huge appreciation to the Hugging Face team for including our work and advancing this research. The future of AI will be built by more than a handful of labs. And we're excited to help build it. Research: Live training:
    07031
  3. webAI✓@thewebAI
    webAI
    RT @HuggingModels: Meet TwIL-8B, an 8B parameter model built on Granite 4.2. It's designed for reasoning, math, and code, and it's already getting love with 3.5k+ downloads. If you're into open models that punch above their weight, this one's worth a look.
    02042
  4. webAI✓@thewebAI
    webAI
    RT @yb2698: Harness adapters training is now live! We are training LoRA adapters on LFM2.5 / LFM3 from @liquidai and the recent Twil-9B model from @thewebAI using RL to make them more efficient and accurate on agentic tasks! You can follow the training going live here:
    035034
  5. webAI✓@thewebAI
    webAI
    RT @thewebAI: Local ai wins.
    David Stout @Davidstout
    Local ai wins.
    0501.5K
  6. David Stout✓@Davidstout
    Local ai wins.
    46373.1K
  7. webAI✓@thewebAI
    webAI
    RT @Davidstout: @thewebAI app is officially live for everyone. Expert AI running on your laptop. The more powerful your device, the more it can do. Download the app:
    021038
  8. webAI✓@thewebAI
    webAI
    RT @Davidstout: Today, we're announcing webAI Meridian-1 CivOE. A 12B AI model that statistically matched Gemini 4 Argon and outperformed Claude Opus 5.5 in evaluation. But the most important breakthrough isn't the benchmark. It's how we achieved it. Instead of endlessly scaling model size, we've built intelligence that adapts to the work through specialized experts. Our results: Meridian-1 CivOE: 85.5 Gemini 4: 84.7 Claude Opus 5.5: 82.7 GPT-5.6: 71.0 The same 12B foundation went from 59.8 to 85.5 through specialization. A 25.7-point improvement without making the foundation model larger. We believe this represents a fundamental shift in how intelligence will evolve. Just as software became personal, customizable, and accessible on everyday computers, intelligence is heading in the same direction. Intelligence that adapts to your knowledge, your work, and your devices. We're beginning the rollout of Meridian-1 CivOE with strategic partners over the next few weeks, before expanding access to all webAI users. The future of intelligence isn't just bigger. It's yours. Read More:
    051039
  9. webAI✓@thewebAI
    webAI
    RT @Davidstout: Thank you all for the incredible support. TwiL-8B hit #24 of 433,863 text generation models on Hugging Face in its first 7 hours. We have more to share, and it’s worth waiting for. Tomorrow morning we’re releasing one more model, our best yet, and opening general access to webAI. See you in the morning.
    06038
  10. webAI✓@thewebAI
    webAI
    RT @Davidstout: Release 2 of 4 today: webAI Air. 73% smaller. Nearly 99% of measured benchmark performance retained. Air is our method for compressing AI models so more capable intelligence can run on everyday devices. Our first release applies Air to Google’s Gemma 4 26B A4B. Compared with the original model: * 73% smaller model file: 50.5 GB → 13.47 GB. * 98.7% of the average benchmark score retained: 78.3 versus 79.3 across six benchmarks. * 2.1× the generation speed: 60.6 versus 28.7 tokens per second in our DGX Spark tests. Compared with Google’s own 4-bit version, Air is also 6.7% smaller, with 61% lower divergence from the original model’s predictions in our evaluation. Useful intelligence is becoming smaller, faster, and easier to put to work. That changes the economics of AI and puts more of it on hardware people already own. Make cloud AI optional. Two more releases coming today.
    Tyler Mauer @TylerMauer4
    @thewebAI's Intelligence Lab is open sourcing Gemma 26b 4a Air 2.6× closer to full precision Significantly more faithful to the original model than Google's official 4-bit release (KL divergence: 0.068 vs. 0.176). Nearly 4× smaller Just 13.5 GB vs. 50.5 GB, with the full 128K context fitting in 16 GB of memory. Almost no loss in intelligence Scores 78.3 vs. 79.3 across 6 benchmarks, retaining 99.4% of original performance on knowledge, math, and coding. Matches the original on real-world tasks Nearly identical wIL scores (Track A: 0.502 vs. 0.508; Track B: 0.812 vs. 0.812). HF:
    07032
  11. webAI✓@thewebAI
    webAI
    RT @TylerMauer4: @thewebAI's Intelligence Lab is open sourcing Gemma 26b 4a Air 2.6× closer to full precision Significantly more faithful to the original model than Google's official 4-bit release (KL divergence: 0.068 vs. 0.176). Nearly 4× smaller Just 13.5 GB vs. 50.5 GB, with the full 128K context fitting in 16 GB of memory. Almost no loss in intelligence Scores 78.3 vs. 79.3 across 6 benchmarks, retaining 99.4% of original performance on knowledge, math, and coding. Matches the original on real-world tasks Nearly identical wIL scores (Track A: 0.502 vs. 0.508; Track B: 0.812 vs. 0.812). HF:
    07048
  12. webAI✓@thewebAI
    webAI
    RT @Davidstout: Modest intelligence is arriving faster than most people realize. Today, we're open-sourcing TwIL-8B. Just 8.8 billion parameters, yet approaching frontier-model scores on several difficult benchmarks: • 93% of frontier performance on coding • 92% on instruction following • 90% on contest mathematics All from a model small enough to run on your own hardware. But the benchmarks aren't the most important part of this announcement. For years, the AI industry has focused on building the most capable model, regardless of the cost required to run it. I believe that equation is changing. The next era of AI will be defined by the cost of completing work. Not simply the intelligence of the model, but how efficiently that intelligence can accomplish the task. If a model with 8 billion parameters can reliably complete the same work as one with hundreds of billions, why pay for the larger model? As smaller models become more capable, intelligence becomes something we can distribute, specialize, and run across the hardware we already own. That's the future we're building at @thewebAI TwIL-8B is available today. Open weights. And this is just the first of several announcements we're making today. HF Link:
    0287043
  13. webAI✓@thewebAI
    webAI
    RT @Davidstout: its almost like ai in the cloud does not work ... ai will move toward user owned hardware. @thewebAI has major announcements this week.
    Hedgeye @Hedgeye
    Anthropic posted a third-quarter net loss of $23.3 billion, versus a $12.1 billion loss a year earlier.
    01040
  14. Hedgeye✓@Hedgeye
    Anthropic posted a third-quarter net loss of $23.3 billion, versus a $12.1 billion loss a year earlier.
    265559049.8K
  15. webAI✓@thewebAI
    webAI
    RT @Davidstout: Your car sits parked most of the day. That doesn’t mean a taxi company should own it. The same applies to AI. Ownership buys autonomy, availability, and control. Calling that “inefficient” is convenient when your business depends on selling access.
    morgan — @morqon
    sam: local inference is a terrible allocation of scarce resources “a lot of people want local inference, and somehow they assume that the problem is solved now because we have open-source models, we're going to be able to run them on our computers, and so we're not going to need all the stuff in the data centre but from a global allocation perspective, actually it's quite terrible to have everybody, like, have a bunch of the world's limited supply of DRAM sitting in their own computer and being used five percent of the time you want maximum utilisation in the cloud if you're trying to deal with this very supply-constrained environment somehow many people's intuition is the opposite of that”
    05054
  16. morgan —✓@morqon
    sam: local inference is a terrible allocation of scarce resources “a lot of people want local inference, and somehow they assume that the problem is solved now because we have open-source models, we're going to be able to run them on our computers, and so we're not going to need all the stuff in the data centre but from a global allocation perspective, actually it's quite terrible to have everybody, like, have a bunch of the world's limited supply of DRAM sitting in their own computer and being used five percent of the time you want maximum utilisation in the cloud if you're trying to deal with this very supply-constrained environment somehow many people's intuition is the opposite of that”
    Scarica
    1.6K2033.3K4.4M
  17. webAI✓@thewebAI
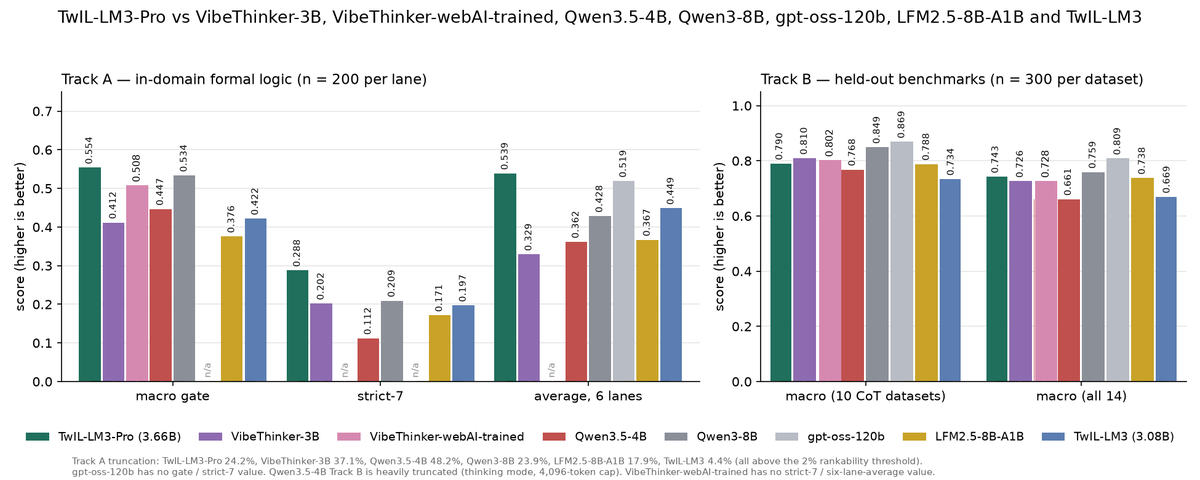
    Base-conversion arithmetic breaks most small reasoning models. There’s no base-10 shortcut, so every carry has to be worked through directly in the target base. Most small models skip the carry logic, or convert back to base-10 at the end and hope. TwIL-LM3-Pro doesn’t. It walks each step in the target base and holds state across the derivation. The same pattern shows up across our full formal logic suite. TwIL-LM3-Pro leads every model we tested on in-domain formal logic, including Qwen3-8B at 2x the parameters, gpt-oss-120b at 33x the parameters, and both VibeThinker variants. A 3.66B model built for formal reasoning, beating models 33x its size at it. And even on held-out general reasoning benchmarks we didn’t build for, it stays competitive with those same larger models. Pattern matching gets you fluent answers. Formal reasoning gets you right ones. Open weights, runs locally. Download the model on @huggingface:
    Scarica
    webAI @thewebAI
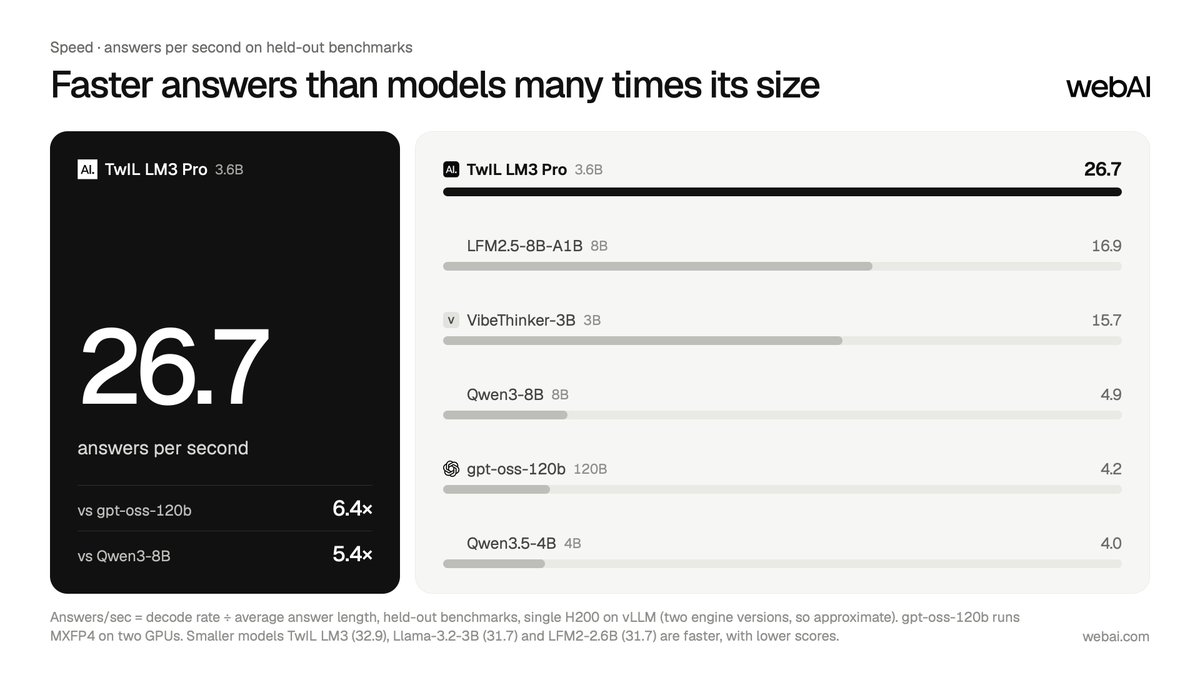
    LLMs are getting more rambly. We built TwIL-LM3-Pro to go the other way. Less than half the tokens of VibeThinker-3B and Qwen3-8B. 1.7x and 5.4x faster answers on general reasoning benchmarks. Full benchmarks:
    21132.1K
  18. webAI✓@thewebAI
    LLMs are getting more rambly. We built TwIL-LM3-Pro to go the other way. Less than half the tokens of VibeThinker-3B and Qwen3-8B. 1.7x and 5.4x faster answers on general reasoning benchmarks. Full benchmarks:
    Scarica
    43276.6K
  19. webAI✓@thewebAI
    AI shouldn’t think for you. It should help you think for yourself. The things that make your work different, the things that make it worth paying attention to, aren’t on the internet. They live in you. That’s what webAI is built on:
    Scarica
    13191.7K
  20. webAI✓@thewebAI
    Most of the AI conversation is about scale. Bigger models, more parameters, longer context windows. The assumption being that bigger is smarter. We’ve been building toward the opposite. TwIL-LM3-Pro is a 3.6B reasoning model that handles formal problems models 7 to 10x its size struggle with, and it runs on a laptop. Small isn’t a compromise. For the problems we care about, it’s the point. A model that fits in RAM, answers in seconds, and can be understood end to end gets us closer to what AI should actually be: specialized, local, and yours. Download the model on @huggingface:
    Scarica
    webAI @thewebAI
    LLMs are getting more rambly. We built TwIL-LM3-Pro to go the other way. Less than half the tokens of VibeThinker-3B and Qwen3-8B. 1.7x and 5.4x faster answers on general reasoning benchmarks. Full benchmarks:
    44181.4K
  21. webAI✓@thewebAI
    How does a 3B parameter model compete with frontier models? In our latest video, our Intelligence Lab team walks through how they built the TwIL reasoning models. The thesis behind formal reasoning, the moment that reshaped their data pipeline, and where the lab is headed next. Watch the full video:
    Scarica
    12141.2K
  22. webAI✓@thewebAI
    webAI
    RT @DevinWhiteAI: We’ve been playing around with the new TwIL-LM3-Pro model and in this maze problem it solved it so fast and even beat Qwen3.8-27B! Seeing this model perform this good at only ~4B is crazy, definitely should check it out if you haven’t already!
    webAI @thewebAI
    We ran TwIL on a CPU with 15 GiB of RAM. No GPU. It generated tokens 98x faster than Qwen3.8-27B on the same hardware. The test: - Intel Xeon CPU, 4 threads - 15 GiB RAM - No GPU Results: - TwIL-LM3-Pro (2.24 GB weights): 10.47 tokens per second - Qwen3.5-9B (5.67 GB weights): 4.36 tokens per second - Qwen3.8-27B (16.45 GB weights): 0.107 tokens per second TwIL and Qwen 9B both run at the RAM's memory limit of about 24 GB/s. Qwen 9B is 2.4x slower only because its weights are 2.5x larger. Qwen 27B's 16.45 GB of weights don't fit in the 15 GiB of RAM. Parts have to be re-read from disk for every token. Size alone would make it 7.3x slower. The disk reads add another 13x. Total: 98x slower than TwIL. With enough RAM, the gap would shrink to about 7x. But most people don't have unlimited RAM, and most people don't have a top-tier GPU. The model you can actually fit matters more than the one you can't. Download TwIL-LM3-Pro on @huggingface:
    02060
  23. webAI✓@thewebAI
    We ran TwIL on a CPU with 15 GiB of RAM. No GPU. It generated tokens 98x faster than Qwen3.8-27B on the same hardware. The test: - Intel Xeon CPU, 4 threads - 15 GiB RAM - No GPU Results: - TwIL-LM3-Pro (2.24 GB weights): 10.47 tokens per second - Qwen3.5-9B (5.67 GB weights): 4.36 tokens per second - Qwen3.8-27B (16.45 GB weights): 0.107 tokens per second TwIL and Qwen 9B both run at the RAM's memory limit of about 24 GB/s. Qwen 9B is 2.4x slower only because its weights are 2.5x larger. Qwen 27B's 16.45 GB of weights don't fit in the 15 GiB of RAM. Parts have to be re-read from disk for every token. Size alone would make it 7.3x slower. The disk reads add another 13x. Total: 98x slower than TwIL. With enough RAM, the gap would shrink to about 7x. But most people don't have unlimited RAM, and most people don't have a top-tier GPU. The model you can actually fit matters more than the one you can't. Download TwIL-LM3-Pro on @huggingface:
    Scarica
    webAI @thewebAI
    LLMs are getting more rambly. We built TwIL-LM3-Pro to go the other way. Less than half the tokens of VibeThinker-3B and Qwen3-8B. 1.7x and 5.4x faster answers on general reasoning benchmarks. Full benchmarks:
    33274.6K