AssemblyAI✓

@AssemblyAI

Access powerful AI models to transcribe and understand speech via a simple API. Try our no-code playground for free 👉 https://t.co/YPCK9mqDG6

415 A seguir46K Seguidores2.9K Publicações
  1. AssemblyAI✓@AssemblyAI
    AssemblyAI
    RT @MTSlive: AssemblyAI CEO @YouveGotFox reveals how just 10 seconds of audio is enough to clone someone's voice with AI: "We have over 4,000 voices available on our API, and we also support instant voice cloning. With as little as 10 seconds of someone’s voice, you can instantly clone it. Obviously, if you have the consent to do that." "The voice for your AI, in a lot of ways, that is the user experience. I might want my voice to sound funny and sarcastic because that fits my brand." "If you’re calling into a business, you want it to sound local. If you’re in a town in the UK, you want it to have the same regional accent as where you’re living." @AssemblyAI
    AssemblyAI @AssemblyAI
    Introducing AssemblyAI-TTS-1, our first text-to-speech model. Natural speech for voice agents, streaming in 90 ms, at $15 per million characters. On accuracy, naturalness, and cost together, it’s the best TTS model you can run at scale.
    070192
  2. AssemblyAI✓@AssemblyAI
    Introducing AssemblyAI-TTS-1, our first text-to-speech model. Natural speech for voice agents, streaming in 90 ms, at $15 per million characters. On accuracy, naturalness, and cost together, it’s the best TTS model you can run at scale.
    Baixar
    222223659.2K
  3. AssemblyAI✓@AssemblyAI
    We are live on OpenRouter as well!!
    OpenRouter @OpenRouter
    AssemblyAI-TTS-1 is now live on OpenRouter! @AssemblyAI's first text-to-speech model, built for voice agents. Ranked in the best quadrant for speed and accuracy, and highest naturalness for models at $15/1M characters or less, per @cekuraAi's benchmark. 4,000+ voices, served from US or EU.
    006916
  4. OpenRouter✓@OpenRouter
    AssemblyAI-TTS-1 is now live on OpenRouter! @AssemblyAI's first text-to-speech model, built for voice agents. Ranked in the best quadrant for speed and accuracy, and highest naturalness for models at $15/1M characters or less, per @cekuraAi's benchmark. 4,000+ voices, served from US or EU.
    AssemblyAI @AssemblyAI
    Introducing AssemblyAI-TTS-1, our first text-to-speech model. Natural speech for voice agents, streaming in 90 ms, at $15 per million characters. On accuracy, naturalness, and cost together, it’s the best TTS model you can run at scale.
    55387.9K
  5. AssemblyAI✓@AssemblyAI
    AssemblyAI
    RT @YouveGotFox: Hopping on @MTSlive with with @sophiadew at 1:30PM PT to talk about @AssemblyAI's TTS-1 model we shipped today!
    MTS @MTSlive
    UK ROGUE AGENT RESPONSE | QWEN NEURONS | TOUCHSCREEN MACBOOK
    030222
  6. MTS@MTSlive
    UK ROGUE AGENT RESPONSE | QWEN NEURONS | TOUCHSCREEN MACBOOK
    433519K
  7. AssemblyAI✓@AssemblyAI
    Tips our team found for accurate voice clones: - WAV, not MP3 - 15 to 25 seconds of reference audio - Scripted or unscripted: try both - Pick the mic that fits your use case Voice cloning docs:
    Baixar
    015938
  8. AssemblyAI✓@AssemblyAI
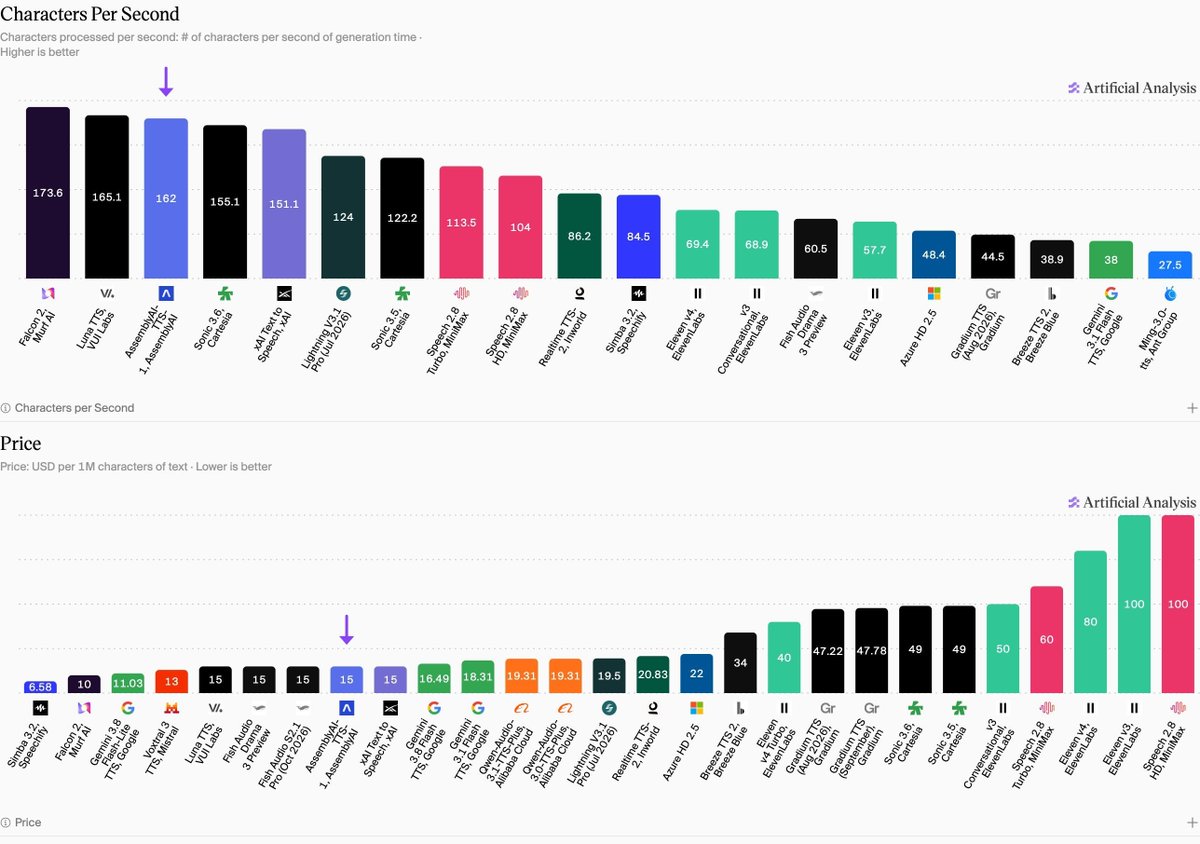
    Artificial Analysis evaluated AssemblyAI-TTS-1 in its arenas: • 162 characters/sec, faster than Sonic 3.6 • Top 10 in Controlled Voice, same 8 cloned voices across models • Top 12 in Provider Voice • Of the 11 models ranked above it, 9 cost more than $15/1M characters Thanks @ArtificialAnlys
    Baixar
    Artificial Analysis @ArtificialAnlys
    AssemblyAI has launched its first Text to Speech model! AssemblyAI-TTS-1 enters the top 12 in our Provider Voice Arena and the top 10 in Controlled Voice @AssemblyAI has launched its first Text to Speech model, AssemblyAI-TTS-1! We evaluated its performance across both Speech Arenas and our Pronunciation Robustness benchmark. Key takeaways: ➤ Text to Speech, Provider Voice: AssemblyAI-TTS-1 scores an Elo of 1,227 across 1,626 arena appearances, ranking #12, just behind Breeze TTS 2 at 1,228 and ahead of Mistral's Voxtral 3 TTS at 1,221 and Inworld's Realtime TTS-2 Flash at 1,218. It ranks #12 in both English (US) and English (UK). ➤ Text to Speech, Controlled Voice: AssemblyAI-TTS-1 scores 1,110 across 1,674 appearances, ranking #10 with the same 8 cloned voices, behind Cartesia's Sonic 3.5 at 1,118 and ahead of Speechify's Simba 3.2 at 1,086. It ranks #6 in Knowledge Sharing. ➤ Pronunciation Robustness: AssemblyAI-TTS-1 scores 81.7% across 2,115 rated clips, ranking #16, behind HeyGen Voice at 83.2% and ahead of Inworld Realtime TTS-2 at 80.7%. It ranks #6 in Preserving Exact Sequences at 81.5%. ➤ Speed: AssemblyAI-TTS-1 generates 162 characters per second, faster than Cartesia's Sonic 3.6 at 148.6 and Mistral's Voxtral 3 TTS at 112.3. ➤ Pricing: AssemblyAI-TTS-1 is priced at $15/1M characters. Of the eleven models ranked above it on Provider Voice, only two cost less: Gemini 3.8 Flash-Lite TTS at $11/1M and Simba 3.2 at $6.6/1M. Eleven v4 is $80/1M and Sonic 3.6 $49/1M. See more details and listen to samples below ⬇️
    1211993
  9. AssemblyAI✓@AssemblyAI
    AssemblyAI
    RT @ArtificialAnlys: AssemblyAI has launched its first Text to Speech model! AssemblyAI-TTS-1 enters the top 12 in our Provider Voice Arena and the top 10 in Controlled Voice @AssemblyAI has launched its first Text to Speech model, AssemblyAI-TTS-1! We evaluated its performance across both Speech Arenas and our Pronunciation Robustness benchmark. Key takeaways: ➤ Text to Speech, Provider Voice: AssemblyAI-TTS-1 scores an Elo of 1,227 across 1,626 arena appearances, ranking #12, just behind Breeze TTS 2 at 1,228 and ahead of Mistral's Voxtral 3 TTS at 1,221 and Inworld's Realtime TTS-2 Flash at 1,218. It ranks #12 in both English (US) and English (UK). ➤ Text to Speech, Controlled Voice: AssemblyAI-TTS-1 scores 1,110 across 1,674 appearances, ranking #10 with the same 8 cloned voices, behind Cartesia's Sonic 3.5 at 1,118 and ahead of Speechify's Simba 3.2 at 1,086. It ranks #6 in Knowledge Sharing. ➤ Pronunciation Robustness: AssemblyAI-TTS-1 scores 81.7% across 2,115 rated clips, ranking #16, behind HeyGen Voice at 83.2% and ahead of Inworld Realtime TTS-2 at 80.7%. It ranks #6 in Preserving Exact Sequences at 81.5%. ➤ Speed: AssemblyAI-TTS-1 generates 162 characters per second, faster than Cartesia's Sonic 3.6 at 148.6 and Mistral's Voxtral 3 TTS at 112.3. ➤ Pricing: AssemblyAI-TTS-1 is priced at $15/1M characters. Of the eleven models ranked above it on Provider Voice, only two cost less: Gemini 3.8 Flash-Lite TTS at $11/1M and Simba 3.2 at $6.6/1M. Eleven v4 is $80/1M and Sonic 3.6 $49/1M. See more details and listen to samples below ⬇️
    080177
  10. AssemblyAI✓@AssemblyAI
    Independent results from Cekura's text-to-speech benchmark, 27 models tested: • #1 on phone numbers and codes (91.7%) • Best quadrant for speed and accuracy • 4.50 naturalness, highest of any model at $15/1M characters or less • Every medical term read correctly AssemblyAI-TTS-1. Thanks @cekuraAi for running it.
    Baixar
    017709
  11. AssemblyAI✓@AssemblyAI
    What would you do if you could clone yourself? Watch to the end. Then try AssemblyAI text-to-speech, live today:
    Baixar
    119774
  12. AssemblyAI✓@AssemblyAI
    City councils decide on real estate development and rezoning in meetings almost nobody watches. Today @myhamletinc & @subes01 launched 10,000+ profiles, available for residents and journalists, powered by AssemblyAI Universal-3.5 Pro and speaker diarization. Read the full story:
    Baixar
    024865
  13. AssemblyAI✓@AssemblyAI
    Publicações @AssemblyAI
    Live today: - Leading accuracy on independent benchmarks - 90 ms time to first audio - Trained on millions of hours of audio - Instant voice cloning - 4,000+ voices, with new ones added daily Every voice, language, and region included at $15 per 1M characters Available today. Watch a kid use it to order a pizza.
    102626
  14. AssemblyAI✓@AssemblyAI
    Want an AI voice agent that joins your Zoom, Meet or Teams call and answers questions out loud? @recallai just published the full build. AssemblyAI's Voice Agent API listens, thinks and speaks. Output Media puts it in the meeting.
    4181.2K
  15. AssemblyAI✓@AssemblyAI
    Publicações @AssemblyAI
    Read the announcement:
    001543
  16. AssemblyAI✓@AssemblyAI
    Publicações @AssemblyAI
    What's inside: - One WebSocket for Speech-to-Text, LLM and voice - Short-lived tokens, so your API key stays out of the browser - Far-field Voice Focus for laptop and room mics - Tool calls, up to leaving the meeting Code: Docs:
    000302
  17. AssemblyAI✓@AssemblyAI
    Build your own captions app.. with our realtime Speech-to-Text API in 32 languages!
    Baixar
    21111.5K
  18. AssemblyAI✓@AssemblyAI
    Gemini 4 Argon is live on LLM Gateway. On Voice Standard Bench it posted the top dictation score of 50+ models (99.5) and returned faster than Gemini 3.8 Flash at every transcript length. Model string: gemini-4-argon Full results:
    Baixar
    13912.4K
  19. AssemblyAI✓@AssemblyAI
    We had so much fun at SF Tech Week that we're doing it again 👀 On October 6 we parked an ice cream truck in downtown San Francisco and handed out free scoops to the Voice AI community. Hundreds of you grabbed a scoop and chatted with us about the future of Voice AI. So the truck is coming back. 🍦 Thursday, October 29 🕛 12:00 to 5:00 PM PT 🌉 Downtown SF (RSVP to get the address, one location this time) Free ice cream. Bring your friends. RSVP:
    Baixar
    13111.8K
  20. AssemblyAI✓@AssemblyAI
    We are open sourcing Voice Standard Bench: 50+ LLMs evaluated over voice transcripts that matter! In our Results GPT-6 Luna became go to for the value amd cost, while Qwen had the lowest latency Try yourself on LLM Gateway the best for your use case!
    Baixar
    22222K
  21. AssemblyAI✓@AssemblyAI
    GrottoAI now coaches leasing agents mid-tour, on their phone, with our Sync Speech-to-Text API. With AssemblyAI, GrottoAI can capture coaching insights from accurate transcripts.
    028954
  22. AssemblyAI✓@AssemblyAI
    AssemblyAI
    RT @iHarnoorSingh: message for those who think latency matters more than voice models accuracy! "The difference between the almost right word and the right word is really a large matter—'tis the difference between the lightning bug and the lightning. ~Mark Twain
    010233
  23. AssemblyAI✓@AssemblyAI
    Calling all Android users: Blurt is coming to Android! No subscriptions. No trackers. Just dictation that works, powered by AssemblyAI. Get your FREE API key now and be ready to dictate your texts the day it lands:
    Baixar
    01101K
  24. AssemblyAI✓@AssemblyAI
    Universal-3.6 Pro is now on @OpenRouter, served through our Sync API. One request in, one finished transcript back. No job to poll, no webhook, no WebSocket. Already running your LLM calls through OpenRouter? Your Speech-to-Text can go on the same key.
    OpenRouter @OpenRouter
    Universal-3.6 Pro from @AssemblyAI is now live on OpenRouter Speech-to-text through AssemblyAI's Sync API. Compared with Universal-3.5 Pro: - 30% fewer errors on short conversational utterances - 12% fewer errors on average across supported languages - Better recognition and formatting of phone numbers, addresses, emails, and codes - 14 new languages: Korean, Catalan, Galician, Russian, Romanian, Estonian, Persian, Afrikaans, Marathi, Cantonese, Zulu, Urdu, Xhosa, and Norwegian Nynorsk Try it now at only $0.30/hr
    2151K
  25. AssemblyAI✓@AssemblyAI
    LLM Gateway now has 50+ models. Today we're releasing Voice Standard Bench, which scores all of them on real Speech-to-Text output across four voice tasks, on transcripts from 30 seconds to an hour. Quality, speed and cost are reported side by side.
    2281.2K
  26. AssemblyAI✓@AssemblyAI
    Overwhelmed the available deployment options for your latest Voice AI app? Good news: you can use AssemblyAI's cutting edge models ANYWHERE. @martschweiger explains in his video:
    Baixar
    21731.6K
  27. OpenRouter✓@OpenRouter
    Universal-3.6 Pro from @AssemblyAI is now live on OpenRouter Speech-to-text through AssemblyAI's Sync API. Compared with Universal-3.5 Pro: - 30% fewer errors on short conversational utterances - 12% fewer errors on average across supported languages - Better recognition and formatting of phone numbers, addresses, emails, and codes - 14 new languages: Korean, Catalan, Galician, Russian, Romanian, Estonian, Persian, Afrikaans, Marathi, Cantonese, Zulu, Urdu, Xhosa, and Norwegian Nynorsk Try it now at only $0.30/hr
    55589.1K
  28. AssemblyAI✓@AssemblyAI
    AssemblyAI
    RT @iHarnoorSingh: models great at coding aren't always great at voice. we are open sourcing Voice Standard Bench: 50+ LLMs evaluated over voice transcripts that matter! what model you would use? you can compare and try it yourself with LLMGateway on AssemblyAI
    020262
  29. AssemblyAI✓@AssemblyAI
    Publicações @AssemblyAI
    Speed matters for voice agents, and open models are the fastest in the run on short transcripts: on 30-second and 2-minute inputs the fastest answer in under a second (median). Every failure counts against the quality score too: wrong format, refusal, timeout, error.
    100218
  30. AssemblyAI✓@AssemblyAI
    Our Voice AI is moving into a haunted house.🎃👻 Join us for a haunted house happy hour and wander among life-size animatronics wired-up with AssemblyAI-powered voice agents. Chat with them, collect candy along the way, and enjoy drinks, bites, and great company with fellow Voice AI builders. Costumes are encouraged. Screams are optional. Oct 29, 5–8 PM PT
    Baixar
    31721.6K
  31. AssemblyAI✓@AssemblyAI
    LLM Gateway now has 50+ models. Voice Standard Bench ranks every one on real Speech-to-Text output, with quality, speed and cost side by side. Up to 15 minutes of audio, a model within two quality points of the leader costs 50 to 85× less.
    001956
  32. AssemblyAI✓@AssemblyAI
    Publicações @AssemblyAI
    All 50+ models in the run are available through LLM Gateway with your existing AssemblyAI API key, and the benchmark is open source, so you can run it on your own transcripts. How we test, and where to start:
    000159
  33. AssemblyAI✓@AssemblyAI
    Thursday, October 22nd at 11am PT: a live first listen of our upcoming Text-to-Speech model with Tom Shapland, Head of New Products. AssemblyAI-TTS-1 is our new Text-to-Speech model for voice agents. It’s built for conversation, with the natural pacing and self-corrections real callers expect. Register:
    Baixar
    41101.1K