Modular✓

@Modular

Building AI’s unified compute layer. We are hiring → https://t.co/cPTAes09WV 🚀

2 A seguir24.4K Seguidores1.4K Publicações
  1. Modular✓@Modular
    AI shouldn’t be locked to one hardware vendor or chip. To democratize AI compute, we’ve made MAX source available with Modular 26.7. 🧵
    510108344K
  2. Modular✓@Modular
    The full MAX source is out. It’s been less than a week, and we’re already amazed by what the community has built.
    Cristiano R. Amon @cristianoamon
    Modular has made the full MAX source available, including the compiler, runtime and hardware backends. Developers can write once, run across accelerators and build commercial products on MAX without licensing fees or royalties. A big step toward making heterogeneous computing more accessible across CPUs, GPUs and accelerators.
    04583.3K
  3. Cristiano R. Amon✓@cristianoamon
    Modular has made the full MAX source available, including the compiler, runtime and hardware backends. Developers can write once, run across accelerators and build commercial products on MAX without licensing fees or royalties. A big step toward making heterogeneous computing more accessible across CPUs, GPUs and accelerators.
    5201269.4K
  4. Modular✓@Modular
    Thanks for the feedback! Glad you're enjoying our inference handbook 🔥 Let us know what else you'd like us to include and check out MAX: now source-available!
    Sahil @sahil0x01
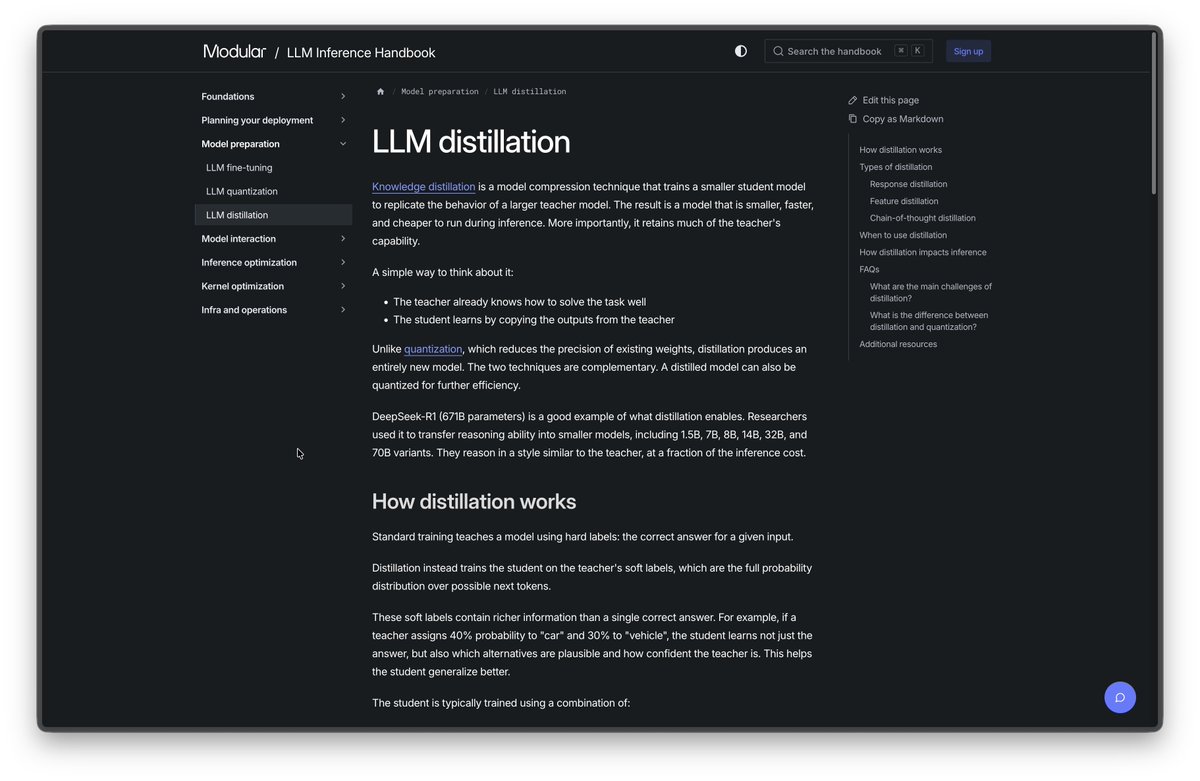
    I've almost finished 50% of this handbook, its really really good, easy to understand, covers a ton of stuff and I'm loving it. I can surely finish this by the end of this week
    00161.3K
  5. Sahil✓@sahil0x01
    I've almost finished 50% of this handbook, its really really good, easy to understand, covers a ton of stuff and I'm loving it. I can surely finish this by the end of this week
    Baixar
    Sahil @sahil0x01
    From today, I'm starting my inference engineering journey by reading this handbook from @Modular . I have little to no idea about my roadmap but I'll just start learning and see how it'll go. I read "Inference Engineering" book by @philipkiely in the past so I have some knowledge
    02181.8K
  6. Modular✓@Modular
    Our vision is to unlock heterogeneous compute and unify the industry around a single software stack. @clattner_llvm brought that vision to @Qualcomm’s Snapdragon Summit this year: one AI stack from kernel to cloud to edge, spanning Snapdragon to Dragonfly on one scalable architecture. The full recording of Chris’s talk is now on our YouTube channel:
    010602.9K
  7. Modular✓@Modular
    Modular
    RT @sahil0x01: Just finished reading the LLM Inference Handbook by @Modular. Excellent, beginner-friendly resource, even if you're unfamiliar with transformer architecture. Next up: @wafer_ai's GPU Performance Engineering resources.
    Sahil @sahil0x01
    From today, I'm starting my inference engineering journey by reading this handbook from @Modular . I have little to no idea about my roadmap but I'll just start learning and see how it'll go. I read "Inference Engineering" book by @philipkiely in the past so I have some knowledge
    0170201
  8. Sahil✓@sahil0x01
    From today, I'm starting my inference engineering journey by reading this handbook from @Modular . I have little to no idea about my roadmap but I'll just start learning and see how it'll go. I read "Inference Engineering" book by @philipkiely in the past so I have some knowledge
    Baixar
    11327.8K
  9. Modular✓@Modular
    Yesterday’s Modular community meeting is now on YouTube. Brian shares EmberJSON, his Modular Community Grant project: a reusable serialization framework for Mojo, inspired by Rust’s serde, plus a fast SIMDJSON-style JSON parser built on compile-time reflection and annotations. Watch the recording:
    12162.2K
  10. Modular✓@Modular
    In Santa Clara today for the LLVM Developers’ Meeting? Head to the Mojo Internals Deep Dive and Roadmap, a full-day workshop with the Mojo team, running from 8:30 AM to 5 PM PT: Not in Santa Clara? Join us virtually for today’s community meeting at 10 AM PT, where Brian walks through EmberJson, his pure Mojo JSON library supported by the Modular Community Grant Program:
    Baixar
    34221.4K
  11. Modular✓@Modular
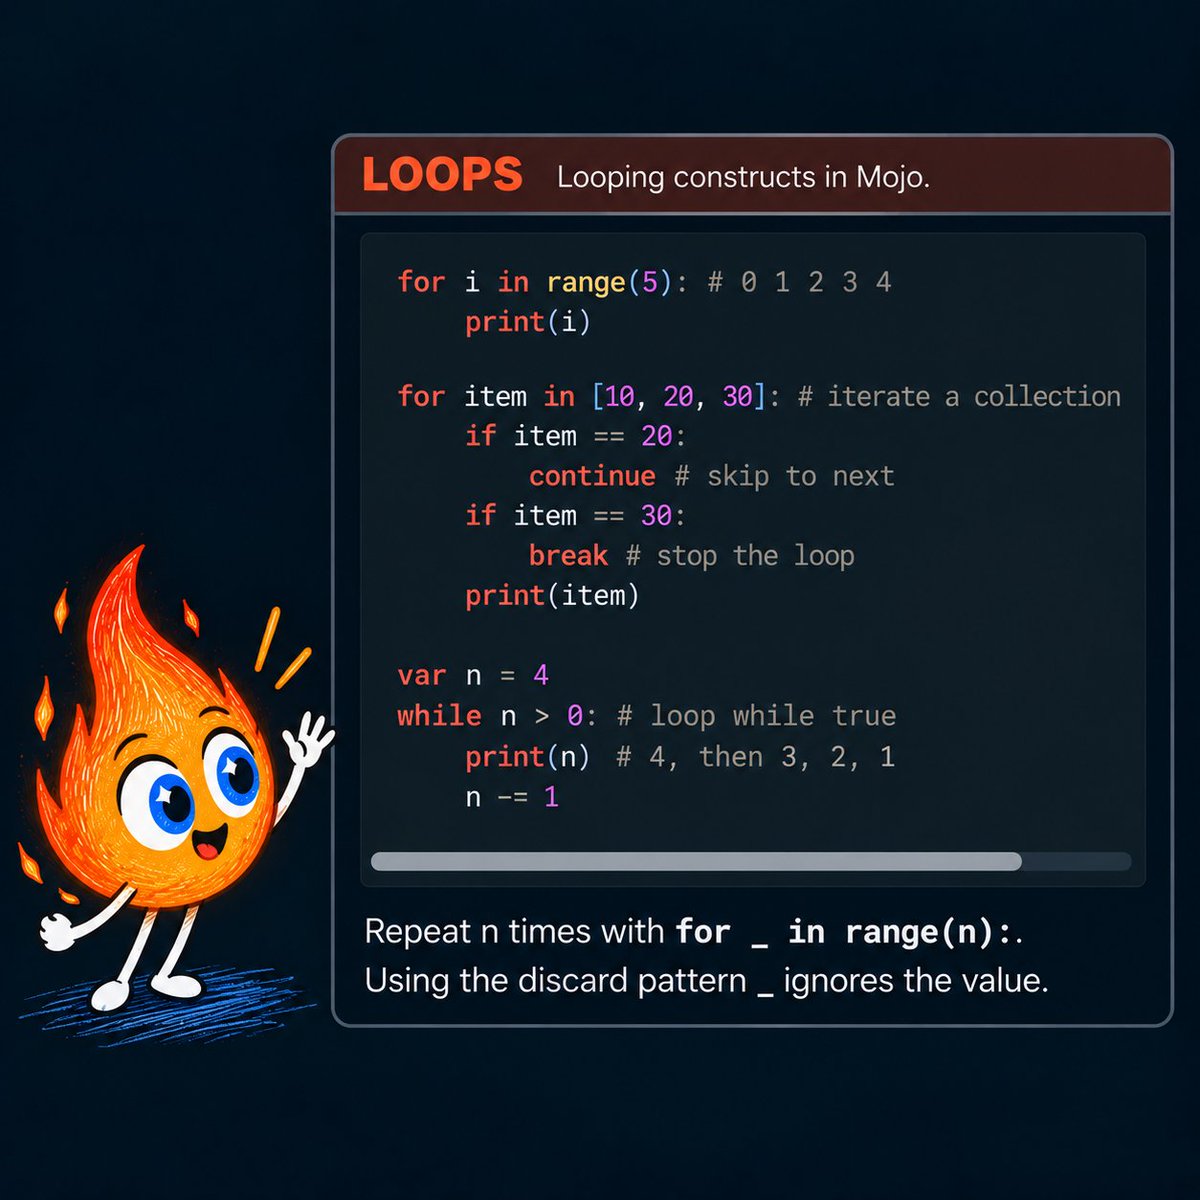
    If you write Python loops, you can already write Mojo loops. The syntax is the same: for, while, break, continue. To repeat something n times, use for _ in range(n): Comprehensions work, too, i.e. [x * x for x in range(5)] The biggest difference is speed. Mojo compiles your loop to native machine code, while Python interprets one step at a time. We counted the primes below 2 million with the same trial-division loop in both languages (no sieve): Python took 2.8 seconds, Mojo took 57 ms. More quick references in the Mojo cheat sheets:
    Baixar
    881094.1K
  12. Modular✓@Modular
    Modular
    RT @clattner_llvm: I'm happy to share that Mojo and MAX are now fully open - for development, extension, and commercial use! This includes the full Mojo programming language, but also the MAX graph compiler, MLRT runtime internals, and hardware abstraction logic. Get your agents going!👇
    01910151
  13. Modular✓@Modular
    MiniMax M3.1 Flash (aka Space Bunny) from @MiniMax_AI is live on Modular Cloud, day zero. M3.1 Flash is best in cowork automation among open models, with SOTA-level coding and engineering performance. It can ship a fix in a real codebase, then update Jira and Slack afterwards. We worked with the MiniMax team ahead of launch, so M3.1 Flash is already serving production traffic on Modular Cloud. Evaluating it for your stack? Try it now:
    Baixar
    135485.6K
  14. Modular✓@Modular
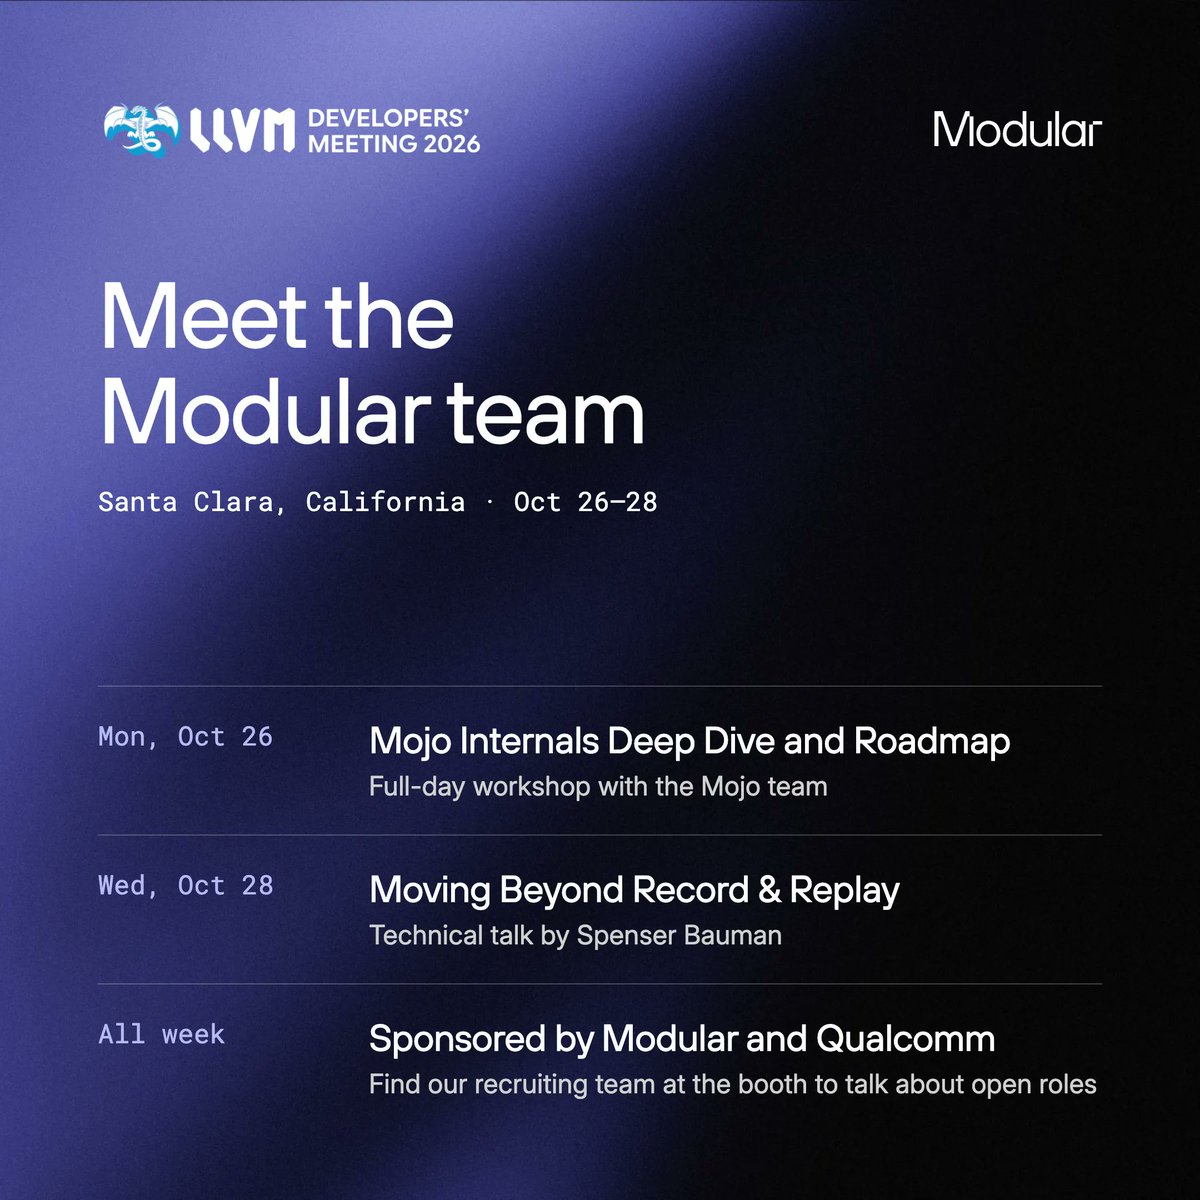
    The Modular team is heading to the 2026 @llvmorg LLVM Developers’ Meeting in Santa Clara on Oct 26–28. On Monday, the Mojo team is running a full-day workshop on Mojo internals and the roadmap. Bring your hardest questions about how the language works under the hood. On Wednesday, Spenser Bauman explains how MAX emits device graph construction code with its MLIR/LLVM graph compiler instead of relying on vendor record and replay support, which lets it support a broader range of accelerators. We’re sponsoring alongside Qualcomm all week. Our recruiting team will be at the booth if you'd like to explore open roles.
    Baixar
    14223.6K
  15. Modular✓@Modular
    Publicações @Modular
    Also in 26.7: eager mode for faster custom op development, decision model support, and Mojo 1.2 with pattern matching, the next step in Mojo’s growth into a systems programming language:
    113585
  16. Modular✓@Modular
    Software ships every week. Silicon often gets locked in years ahead of time. At ModCon 2026, @clattner_llvm asked hardware leadership from d-Matrix, Qualcomm and AWS how they plan years ahead while models change constantly, and what software challenges they keep running into. Full panel recording:
    24286.7K
  17. Modular✓@Modular
    Publicações @Modular
    Have questions on the new license? Join Chris Lattner @clattner_llvm and Tim Davis @iamtimdavis for a live Q&A on the new license, Nov 10th at 10 AM PT:
    002529
  18. Modular✓@Modular
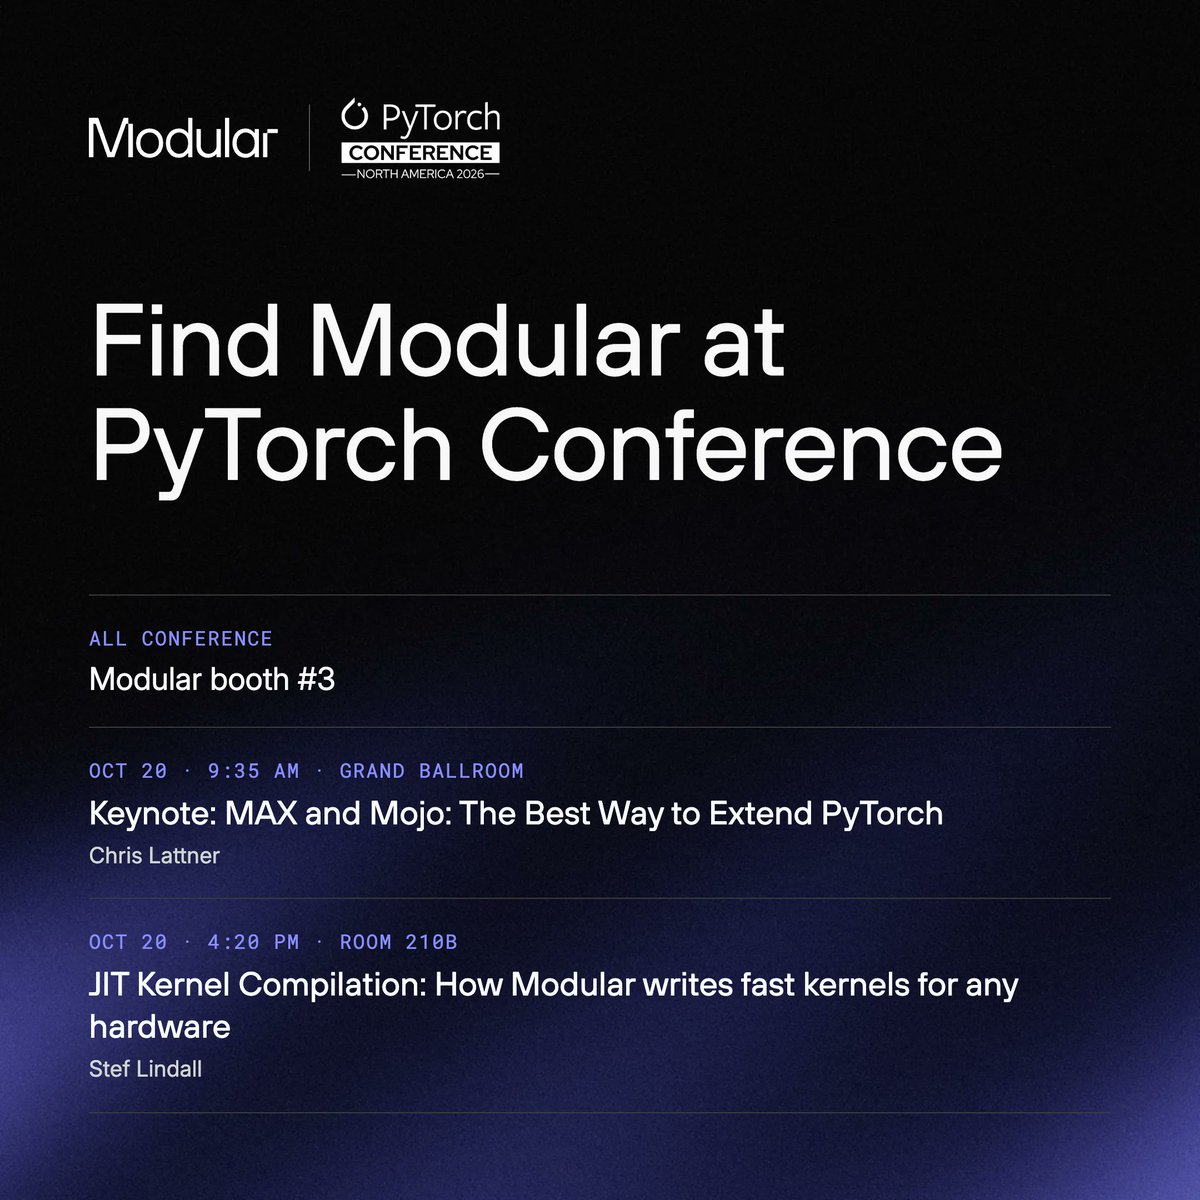
    Chris Lattner keynotes #PyTorchCon on Tuesday: “MAX and Mojo: The Best Way to Extend PyTorch.” @clattner_llvm will cover how we’re helping developers run their models across a wider range of hardware. He’ll also share an early look at how the broader ecosystem can build on MAX with us. After his keynote, swing by the Modular booth (#3) for demos and swag.
    Baixar
    11261.5K
  19. Modular✓@Modular
    It’s day 2 of @PyTorch Conference! Today is your last chance to stop by the Modular booth (#3). If you missed @clattner_llvm's talk, come find us and we’ll walk you through our stack and answer your questions. We’d love to hear about what you’re building and give you a Modular shirt.
    Baixar
    00101.6K
  20. Modular✓@Modular
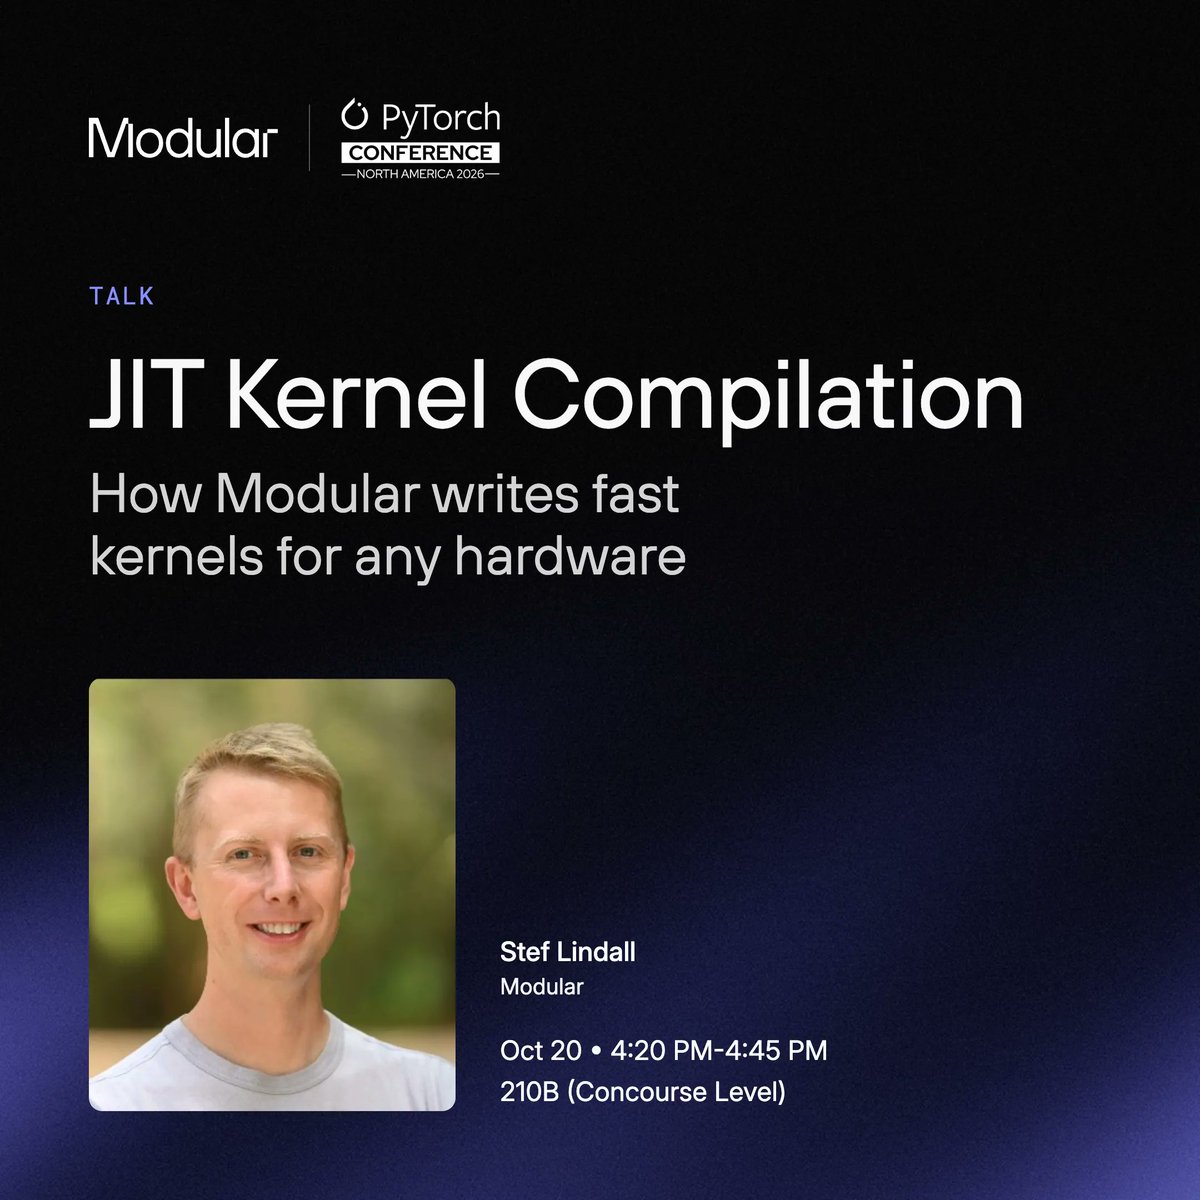
    #PyTorchCon starts next Tuesday! On day one, Stef Lindall, Principal Engineer at Modular, will cover how MAX lets you write fast kernels for any chip and compile them just in time. Oct 20, 4:20 PM, Room 210B. Find the Modular team at booth #3 on both days for live demos and swag.
    Baixar
    01191.7K
  21. Modular✓@Modular
    #PyTorchCon kicks off today, and we’re excited to spend the next two days with the PyTorch community. In a few hours, @clattner_llvm delivers a keynote: “MAX and Mojo: The Best Way to Extend PyTorch” (9:35 AM, Grand Ballroom). This afternoon, Stef Lindall goes deep on how we compile fast kernels for whatever hardware you’re running (4:20 PM, Room 210B). Throughout the conference, you can find us at booth #3 to talk accelerators, compilers, and open roles. Stop by today to grab a MAX and Mojo T-shirt while supplies last.
    Baixar
    12131.4K
  22. Modular✓@Modular
    Find us at #PyTorchCon next week! Booth 3 (Modular) and Booth D6 (@Qualcomm_Dev).
    Qualcomm Developer @Qualcomm_Dev
    Headed to #PyTorchCon? We too! 🙋 Visit us at booth D6 and don’t miss these events: 🔷 Keynote: MAX and Mojo: The Best Way to Extend @PyTorch — 10/20 @ 9:35 AM PT 🔷 Demo: Scaling AI Across Devices: ExecuTorch — 10/20 @ 1 PM PT
    11131.5K
  23. Modular✓@Modular
    A language becomes an ecosystem when its community starts building the libraries everyone else relies on. That’s happening with Mojo and MAX, and we want to support more of it. Meet the first Modular Community Grant cohort: six community-built Mojo and MAX libraries, funded by Modular, covering reinforcement learning, GPU physics, and developer tools.
    23252.2K
  24. Modular✓@Modular
    We're excited to be an official inference partner powering @MiniMax_AI M3.1 Flash, AKA Space Bunny 🐰
    MiniMax (official) @MiniMax_AI
    Welcome back. Space Bunny. 🚀 MiniMax-M3.1-Flash is coming.
    11342.9K
  25. Qualcomm Developer✓@Qualcomm_Dev
    Headed to #PyTorchCon? We too! 🙋 Visit us at booth D6 and don’t miss these events: 🔷 Keynote: MAX and Mojo: The Best Way to Extend @PyTorch — 10/20 @ 9:35 AM PT 🔷 Demo: Scaling AI Across Devices: ExecuTorch — 10/20 @ 1 PM PT
    Baixar
    11111.8K
  26. Modular✓@Modular
    Modular
    RT @Qualcomm_Dev: AI software that scales across hardware. That's the conversation we're bringing to #PyTorchCon - stop by to meet @Qualcomm and @Modular experts.
    PyTorch @PyTorch
    New chips are shipping faster than ever before, but the ecosystem is being held back by having to rewrite and then re-debug the same code over & over again. @clattner_llvm CEO and Co-founder at @Modular and EVP of Advanced AI Software & Platforms at @Qualcomm, will deliver a keynote at PyTorch Conference North America about an open software platform for heterogeneous compute powered by Mojo and MAX. PyTorch has always been the place where the best models come together, and now there's a way to get those models onto all kinds of hardware. If you're interested in Al and compute, join us at the PyTorch Conference in San Jose, CA. Register now: #PyTorchCon
    030212
  27. MiniMax (official)@MiniMax_AI
    Welcome back. Space Bunny. 🚀 MiniMax-M3.1-Flash is coming.
    Baixar
    2855256.7K885K
  28. Modular✓@Modular
    AI teams face two problems at once: compute is hard to get, and the hardware they can get is splintering across a growing wave of chips and accelerators. Every chip ends up needing its own software stack. In his AI Engineer World’s Fair 2026 talk, Modular's Chief Scientist Abdul Dakkak explains why we rebuilt the inference stack from scratch and how it runs fast across all of that hardware:
    23182.9K
  29. PyTorch✓@PyTorch
    New chips are shipping faster than ever before, but the ecosystem is being held back by having to rewrite and then re-debug the same code over & over again. @clattner_llvm CEO and Co-founder at @Modular and EVP of Advanced AI Software & Platforms at @Qualcomm, will deliver a keynote at PyTorch Conference North America about an open software platform for heterogeneous compute powered by Mojo and MAX. PyTorch has always been the place where the best models come together, and now there's a way to get those models onto all kinds of hardware. If you're interested in Al and compute, join us at the PyTorch Conference in San Jose, CA. Register now: #PyTorchCon
    Baixar
    8910421.7K