Posts with #PyTorchCon

#PyTorchCon

Public posts on X that use #PyTorchCon.

Related hashtags

  1. PyTorch✓@PyTorch
    #PyTorchCon North America starts TOMORROW! 🎉 Join us in San Jose for two days of open source AI ideas, code, connections, and serious PyTorch power. Can’t make it in person? Sign up to watch the keynote livestream: Still time to register:
    Download
    12185.8K
  2. PyTorch✓@PyTorch
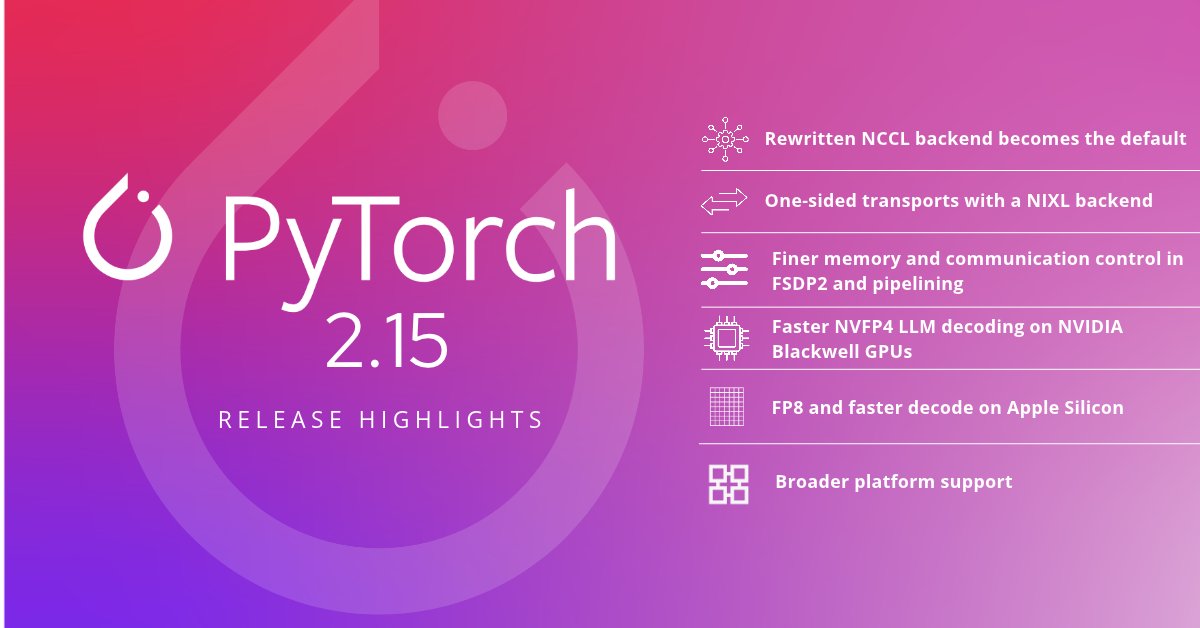
    PyTorch 2.15 is here, with 3,117 commits from 583 contributors and updates across distributed training, NVGEMM, Apple Silicon, and accelerator platform support. The release makes the rewritten NCCL backend the default and adds one-sided transports with a NIXL backend. FSDP2 and pipelining gain finer memory and communication control. It also brings faster 4-bit (NVFP4) LLM decoding on NVIDIA Blackwell GPUs, FP8 and faster decode on Apple Silicon, and broader platform support. On Thursday, November 5, at 11 AM PST, join Tristan Rice (@rice_fry), Natalia Gimelshein, Huy Do, and Jane Xu (@janeyx99) (@Meta) for a live PyTorch 2.15 Q&A, moderated by Chris Gottbrath (Gottbrath Tech). The speakers will share an overview of the release and answer community questions about PyTorch and the new capabilities in this release. 🔗 Read the release blog and register for the live Q&A:
    Download
    122116917.9K
  3. PyTorch✓@PyTorch
    Thanks for joining us at PyTorch Conference @alanzhuly and @Qualcomm!
    Alan Zhu @alanzhuly
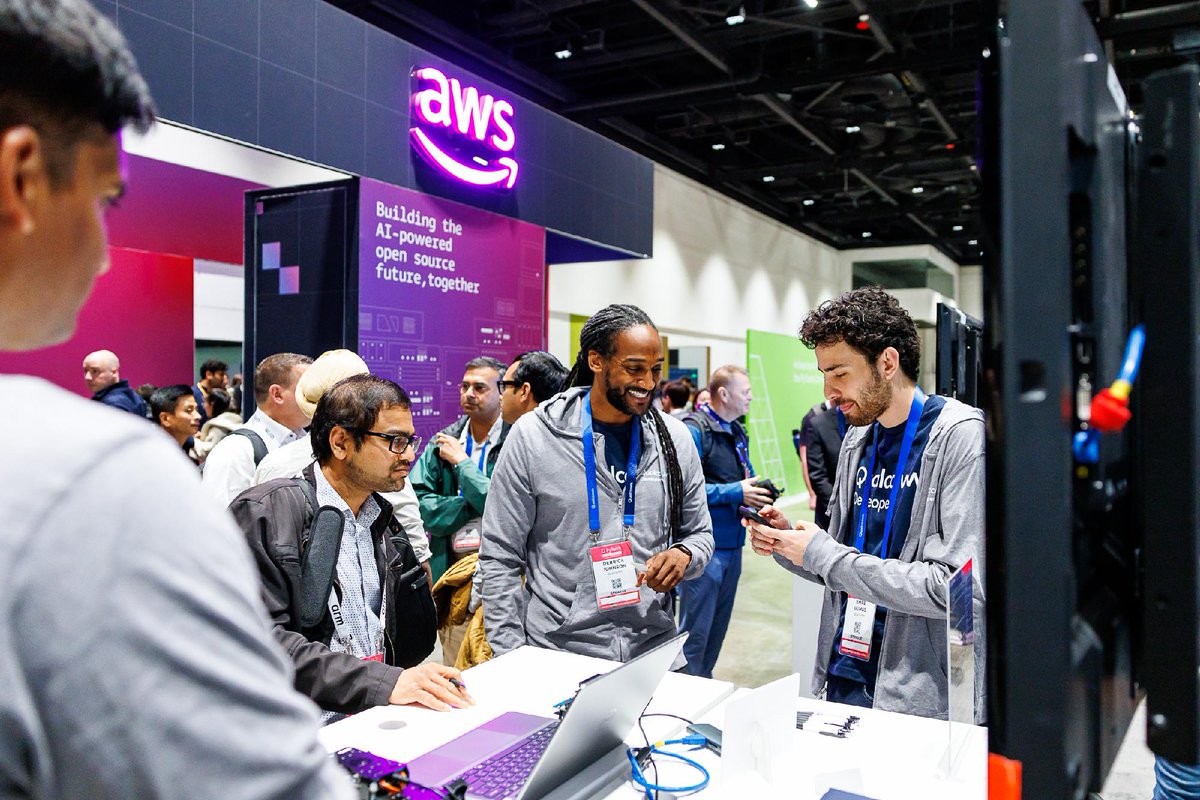
    We brought two things to @PyTorch Conference. At the @Qualcomm booth, we demoed GenieX, the open-source Gen AI runtime my team builds, running @liquidai's LFM-VL on @Innodisk_Corp's Dragonwing IQ9. It watched a live camera feed and described what it saw, all on the device. Multimodal is the workload moving on-device in production. Small VLMs are good enough now for most of what a camera needs to understand, and you don't pay per frame or wait on the network. We also ran a hands-on workshop with @awscloud : fine-tune on SageMaker, then run the model locally with GenieX. Most questions were some version of "how do I get my own model running on my own hardware?" That's sovereign AI at developer scale, and it's exactly what GenieX is for.
    333310.7K
  4. Alan Zhu✓@alanzhuly
    We brought two things to @PyTorch Conference. At the @Qualcomm booth, we demoed GenieX, the open-source Gen AI runtime my team builds, running @liquidai's LFM-VL on @Innodisk_Corp's Dragonwing IQ9. It watched a live camera feed and described what it saw, all on the device. Multimodal is the workload moving on-device in production. Small VLMs are good enough now for most of what a camera needs to understand, and you don't pay per frame or wait on the network. We also ran a hands-on workshop with @awscloud : fine-tune on SageMaker, then run the model locally with GenieX. Most questions were some version of "how do I get my own model running on my own hardware?" That's sovereign AI at developer scale, and it's exactly what GenieX is for.
    Download
    501710.4K
  5. Amazon Science✓@AmazonScience
    Announcing TorchNeuron: @PyTorch code now runs natively on AWS Trainium chips with a single configuration change. No rewrite needed. Open sourcing at #PyTorchCon on Oct 20:
    Download
    463848.1K
  6. PyTorch✓@PyTorch
    🎉 THANK YOU to our #PyTorchCon Europe diamond sponsors. Join us in Paris on 7-8 April for two exciting days of technical talks, workshops, & keynotes from the brightest minds in #AI. Register: Schedule:
    Download
    13174.7K
  7. PyTorch✓@PyTorch
    Validate your real-world PyTorch skills with the PyTorch Certified Associate (PTCA) program. Designed for early-stage practitioners, PTCA helps you demonstrate foundational ability across model design, training, and deployment while building credibility across the open source AI ecosystem. Learn more and enroll here:
    Download
    11308.9K
  8. TensorTonic✓@TensorTonic
    ML engineer interview in 2016: - Explain linear regression - What's overfitting - Train a model in sklearn - Get the offer ML engineer interview in 2026:
    821981160K
  9. TensorTonic✓@TensorTonic
    @TensorTonic
    Implement attention from scratch. Write backprop without PyTorch. Code softmax that doesn’t overflow. Explain KV cache. Implement LayerNorm. Debug a tensor shape mismatch live. Build a mini transformer in 45 mins. Every one of these is a problem you can practice on TensorTonic
    51533522.5K
  10. PyTorch✓@PyTorch
    🔥It begins! The Measuring Intelligence Summit kicks off Oct 21 at #PyTorchCon 2025. 🎙️Fireside Chat: @polynoamial (OpenAI) + @joespeez (Meta) 💡Panel: “Are We Measuring Intelligence or Just Benchmarks?” Join the conversation redefining AI evaluation →
    11247.8K
  11. PyTorch✓@PyTorch
    🧸 Parents: Sign up for complimentary child care at #PyTorchCon (Oct 22-23 in SF)! RSVP by Sept 19 - no late signups allowed. Enjoy the event carefree 👉
    Download
    42158.1K
  12. PyTorch✓@PyTorch
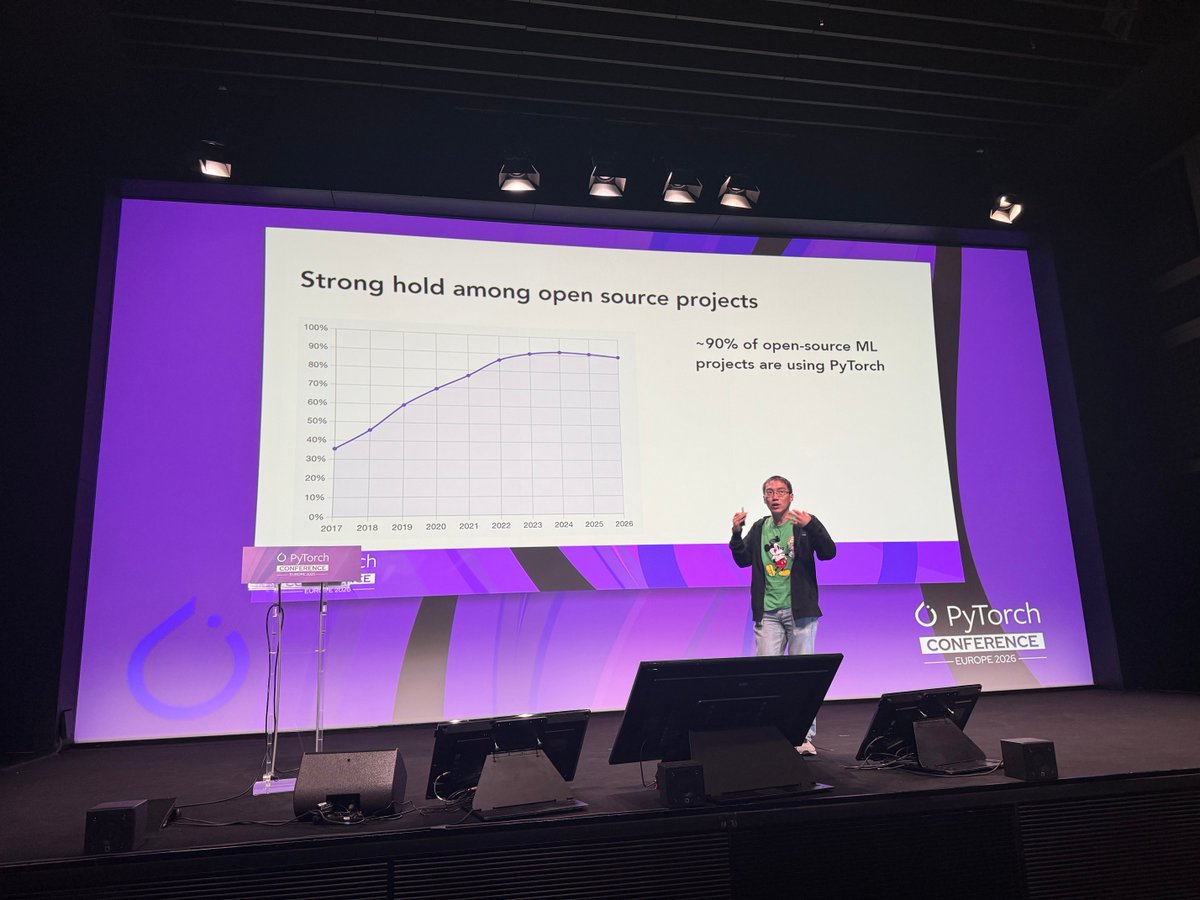
    90% of open source ML projects are using PyTorch explains @ezyang of @Meta who takes the stage at #PyTorchCon Europe to share the latest PyTorch updates and what's ahead for the framework from torch.compile to dynamic shapes & beyond
    Download
    13335.7K
  13. ayush✓@aayxx5h
    𝐂𝐚𝐧 𝐘𝐨𝐮 𝐑𝐮𝐧 π𝟎.𝟓 𝐎𝐧 𝐀 𝟏𝟔 𝐆𝐁 𝐆𝐏𝐔? Running advanced robotics models often comes with a hardware problem. The model might be ready, the code might work, but the GPU simply doesn't have enough memory to run everything. PrismaX decided to tackle that problem with its latest π0.5 optimization. And the result is quite interesting. ━━━━━━━━━━━━━━━━━━ 𝐅𝐫𝐨𝐦 𝟐𝟐 𝐆𝐁 𝐓𝐨 𝟏𝟏.𝟐 𝐆𝐁 The previous π0.5 rollout stack required approximately 22 GB of peak VRAM during model loading. That made running it on widely available 16 GB GPUs difficult. The PrismaX team investigated its memory usage and discovered two unnecessary sources of VRAM consumption: ➜ Hugging Face initialized a large random FP32 model backbone before loading and quantizing the actual model. ➜ PyTorch models were being kept in VRAM at the same time as their compiled TensorRT engines. After fixing these two issues, peak VRAM usage dropped to just 11.2 GB. That's almost a 49% reduction. ━━━━━━━━━━━━━━━━━━ 𝐖𝐡𝐚𝐭 𝐃𝐨𝐞𝐬 𝐓𝐡𝐢𝐬 𝐌𝐞𝐚𝐧? Lower VRAM requirements make advanced robotics inference accessible to more hardware configurations. The optimized stack can now fit within 16 GB GPUs, including: ➜ NVIDIA RTX 5080 ➜ NVIDIA RTX 5070 Ti This is particularly relevant as high-end mobile GPUs become harder to find and more expensive. Instead of depending on expensive 24 GB hardware, developers now have more accessible options to explore. ━━━━━━━━━━━━━━━━━━ 𝐃𝐨𝐞𝐬 𝐋𝐨𝐰𝐞𝐫 𝐕𝐑𝐀𝐌 𝐌𝐞𝐚𝐧 𝐋𝐨𝐰𝐞𝐫 𝐏𝐞𝐫𝐟𝐨𝐫𝐦𝐚𝐧𝐜𝐞? Not necessarily. PrismaX estimates that the mobile RTX 5080 configuration could run at around 100 ms per step, although this configuration hasn't been benchmarked yet. The team also expects desktop RTX 5070 Ti and 5080 configurations to perform faster than the 5090 Mobile because of their higher power limits. The important part is that reducing memory requirements doesn't automatically mean sacrificing the entire inference experience. ━━━━━━━━━━━━━━━━━━ 𝐖𝐡𝐲 𝐓𝐡𝐢𝐬 𝐌𝐚𝐭𝐭𝐞𝐫𝐬 𝐅𝐨𝐫 𝐏𝐡𝐲𝐬𝐢𝐜𝐚𝐥 𝐀𝐈 Building powerful robotics models is only one part of the challenge. Developers also need practical ways to run those models on real hardware. Reducing memory consumption can lower hardware requirements, expand access for builders, and make experimentation easier. Sometimes, better performance isn't about adding more powerful hardware. It's about making better use of the hardware already available. That's exactly what this π0.5 optimization demonstrates. ━━━━━━━━━━━━━━━━━━ 𝐑𝐞𝐚𝐝 𝐌𝐨𝐫𝐞 ➣ Full article: ➣ GitHub: ➣ Linktree: ➣ Discord: ➣ X: @PrismaXai
    Download
    40559
  14. PyTorch✓@PyTorch
    🚀 Unlock frontier-level AI training performance with DeepSpeed! Join Masahiro Tanaka of DeepSpeed at PyTorch Day Japan 2026 as he presents “DeepSpeed at the Frontier: Community-Driven Optimizations for State-of-the-Art Training Performance,” exploring the latest innovations advancing the performance and scalability of distributed AI training. Register by November 11 and save ¥3,000.
    Download
    33328.7K
  15. PyTorch✓@PyTorch
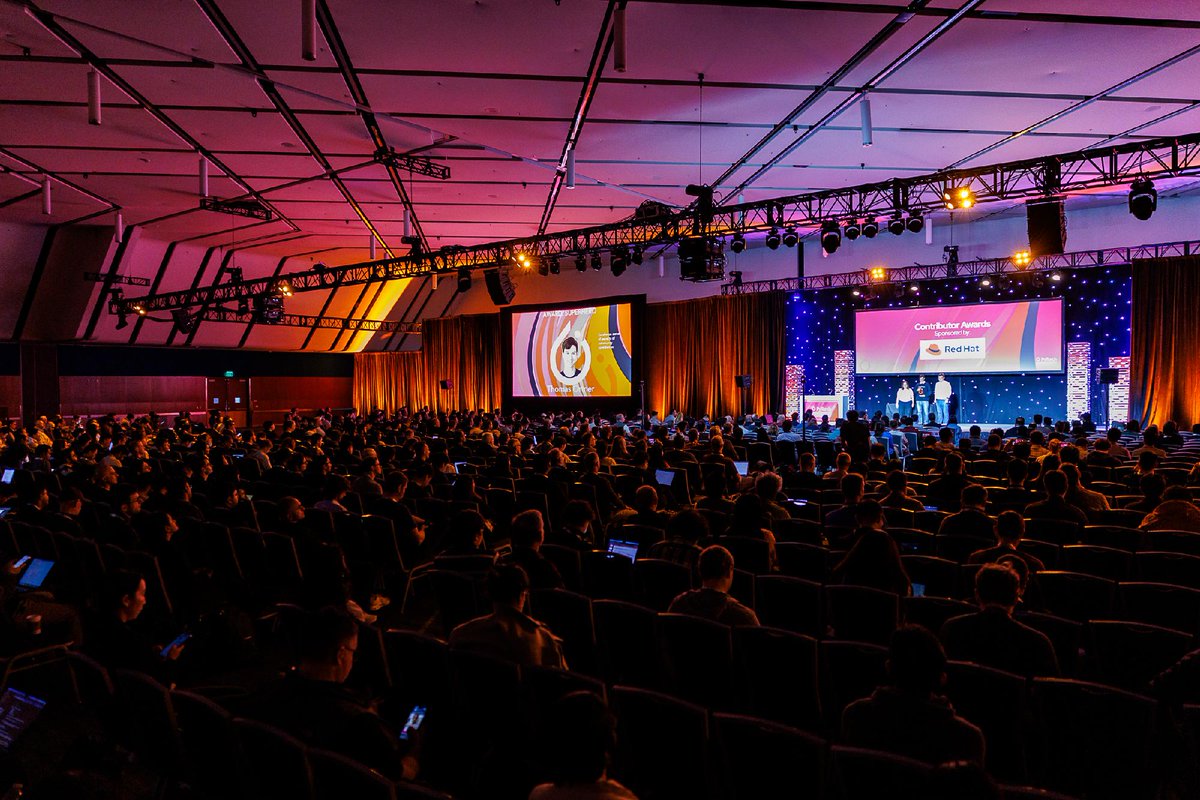
    #PyTorchCon North America 2026 brought 3,500+ attendees to San Jose to accelerate open intelligence. The PyTorch Foundation welcomed nine new members, including @Nebius, @Nscale, and @Shopify as Platinum members, deepening its role as the intelligence layer for open source AI development. “Open systems learn faster when more people, projects, and organizations are working together, creating compounding gains,” said @sparkycollier, Executive Director of the PyTorch Foundation. “Open source ecosystems let breakthroughs travel between organizations instead of staying locked inside one company.” @Google and @Meta introduced TorchTPU for native PyTorch execution on Google TPUs. @awscloud announced TorchNeuron for AWS Trainium. TorchTitan expanded model support, improved training performance, and introduced reinforcement learning through TitanRL. The program featured more than 100 sessions and 144 poster sessions, alongside Day 0 training and workshops. In the Community Expo, attendees connected with sponsors, exhibitors, and core maintainers through booth conversations, demonstrations, and Meet the Developers. The 2026 PyTorch Contributor Awards recognized innovation, collaboration, and impact across PyTorch, @vllm_project, @DeepSpeedAI, Ray, Helion, and Safetensors. Explore the announcements, keynotes, technical updates, contributor recognition, and community highlights in our recap. Thank you to the contributors, maintainers, speakers, trainers, program chairs and committee, sponsors, and attendees who made #PyTorchCon possible. Read the recap: Stay tuned for session slides and recordings, and save the date: PyTorch Conference returns to San Jose, October 6–7, 2027!
    Download
    56287.8K
  16. Red Hat@RedHat
    Scale distributed inference and control AI serving costs with confidence. llm-d 1.0 brings multi-tenant quality of service, zero-downtime rolling updates, and prefix-cache-aware routing to your production workloads. Explore the release: #PyTorchCon
    Download
    57356.8K
  17. PyTorch✓@PyTorch
    The PyTorch Foundation OSPO & Academic Outreach Working Group is inviting academic open source projects to submit for a Day 0 workshop at #PyTorchCon North America 2026. Projects using PyTorch, @DeepSpeedAI, Helion, @raydistributed, Safetensors, or @vllm_project can submit for consideration. Eight selected projects will present five-minute lightning talks, followed by a hands-on workshop and mentor office hours. Depending on the project, workshop conversations may cover open source readiness, governance, reproducibility, community, security and maintenance, and ecosystem positioning. The call is open to students, researchers, faculty, research engineers, university labs, academic OSPOs, research institutions, and maintainers of research-originated open source projects. The submission deadline is September 30, 2026, at midnight PT. Register for PyTorch Conference North America: 🔗 Read more and submit:
    Download
    222414.3K
  18. PyTorch✓@PyTorch
    Keynote sessions are underway! Executive Director Matt White opens #PyTorchCon with a look back at the PyTorch Foundation’s remarkable year of growth. As an umbrella foundation, PyTorch Foundation connects developers, researchers, and industry pioneers to accelerate collaboration, spark innovation, and build the future of open source AI. Now on stage, Meta's @_seemethere! #PyTorchLive 🔗 Find the full schedule here: #PyTorchCon #PyTorch #OpenSourceAI
    Download
    22155.5K
  19. Show more posts