- NVIDIA AIRT @maithra_raghu: Introducing Samaya Sterling, our new model post-trained for challenging financial research that outperforms the frontier! Sterling started off as a two person research effort to see if we could increase efficiency in agentic orchestration. To our surprise we were able to post-train a much smaller model (Nemotron 3.5 Lightning, a 30B mixture-of-experts model with 3B active parameters) to greater accuracy (58.9% vs 55.9% on FrontierFinance) and 11x lower cost ($0.61 vs $6.89) than Claude Fable 5.1, the best performing frontier model. We did this via a four-stage training process, two stages of SFT where the model first learns to research with our financial tools and how to construct a good agentic research strategy. The second two stages are RL, with an offline GRPO stage where the model further hones its research strategy from eight teachers that provide diverse approaches, and an online GRPO stage where the model can make end to end attempts and learn from its mistakes. We see substantial gains from the co-adaptation of the model and harness through post-training, both through the model learning to effectively use the high-quality financial tools, and better compaction approaches that let even a small model execute on longer and deeper research. We are exploring multiple follow-up directions, from multi-agent research swarms using this small model, to training firm-specific models to encode unique judgement, to training a larger model, where early results show even greater gains from the training process. The full research is linked below!05701.6K
- Congrats @MistralAI team on the next gen Le Chonk! 🙌 1T-parameter MoE multimodal model trained from scratch on 3,800 NVIDIA Grace Blackwell GPUs. Our day 0 support: NVFP4 on @huggingface → Scale distributed inference using performance-optimized Dynamo →Mistral AI @MistralAIToday, we release the weights of a new and improved Le Chonk, advancing the open frontier for agentic coding and cybersecurity. 💻 Built to build: Le Chonk ranks #1 on @cognition’s FrontierCode among open models, and sets a new benchmark for Pareto efficiency on @artificialanalysis. 🛡 Built to defend: State-of-the-art in cyberdefense, put through the paces by the world's leading cyber vendors, including @CrowdStrike, @cloudflare, @rubrik, @zscaler, and others. Built for sovereignty: Make it yours. Download the weights on @huggingface , customize it with Mistral Forge, and deploy it wherever you need it. Read more from our team and customers 👇:323848420.9K
 Today, we release the weights of a new and improved Le Chonk, advancing the open frontier for agentic coding and cybersecurity. 💻 Built to build: Le Chonk ranks #1 on @cognition’s FrontierCode among open models, and sets a new benchmark for Pareto efficiency on @artificialanalysis. 🛡 Built to defend: State-of-the-art in cyberdefense, put through the paces by the world's leading cyber vendors, including @CrowdStrike, @cloudflare, @rubrik, @zscaler, and others. Built for sovereignty: Make it yours. Download the weights on @huggingface , customize it with Mistral Forge, and deploy it wherever you need it. Read more from our team and customers 👇:
 3116214.9K444K
- Beiträge @NVIDIAAISGLang @sgl_projectSGLang has Day-0 support for Mistral Large 4 (Le Chonk), and is the first to serve it on NVIDIA Vera Rubin! Le Chonk is Mistral's largest model to date: a natively multimodal 1T MoE that unifies instruct, reasoning, coding, and agentic workflows. SOTA among open weights for security work, with strong document understanding and a 1M context window. Vera Rubin, NVFP4, and DSpark speculative decoding all supported on Day 0.11102.4K
 SGLang has Day-0 support for Mistral Large 4 (Le Chonk), and is the first to serve it on NVIDIA Vera Rubin! Le Chonk is Mistral's largest model to date: a natively multimodal 1T MoE that unifies instruct, reasoning, coding, and agentic workflows. SOTA among open weights for security work, with strong document understanding and a 1M context window. Vera Rubin, NVFP4, and DSpark speculative decoding all supported on Day 0.
 Mistral AI @MistralAIToday, we release the weights of a new and improved Le Chonk, advancing the open frontier for agentic coding and cybersecurity. 💻 Built to build: Le Chonk ranks #1 on @cognition’s FrontierCode among open models, and sets a new benchmark for Pareto efficiency on @artificialanalysis. 🛡 Built to defend: State-of-the-art in cyberdefense, put through the paces by the world's leading cyber vendors, including @CrowdStrike, @cloudflare, @rubrik, @zscaler, and others. Built for sovereignty: Make it yours. Download the weights on @huggingface , customize it with Mistral Forge, and deploy it wherever you need it. Read more from our team and customers 👇:912825.1K
- Available now: NVIDIA Nemotron 3.5 Bolt E4B 4GB ⚡️ Our newest small open model is built for local assistants, interactive characters and robots that can carry on a conversation and use tools to get things done. Watch Reachy Mini chat and move, with Bolt handling conversation and NVIDIA Cosmos handling vision. Both models run locally on Jetson Orin Nano 8GB. Learn more:1482602.1K289K
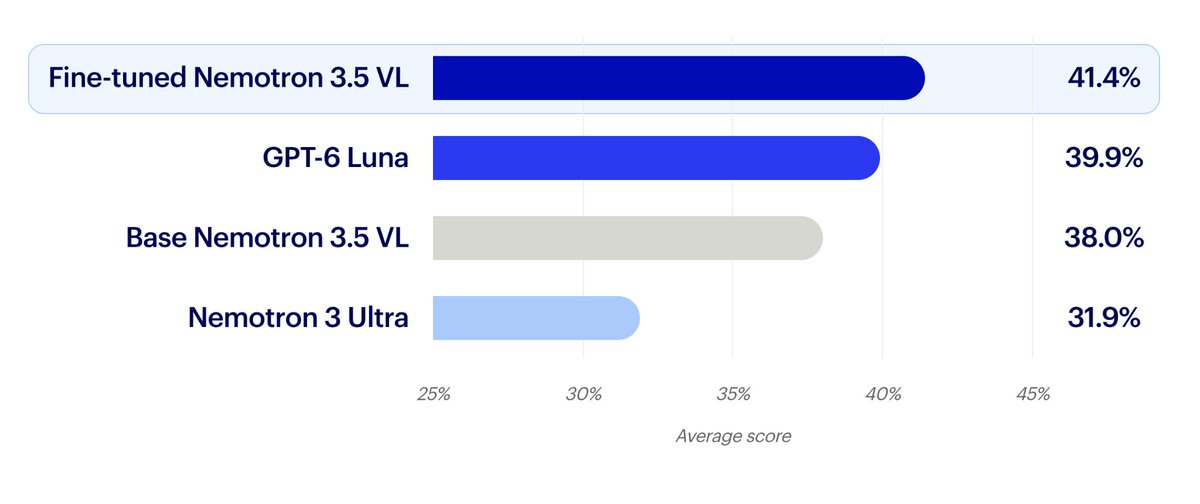
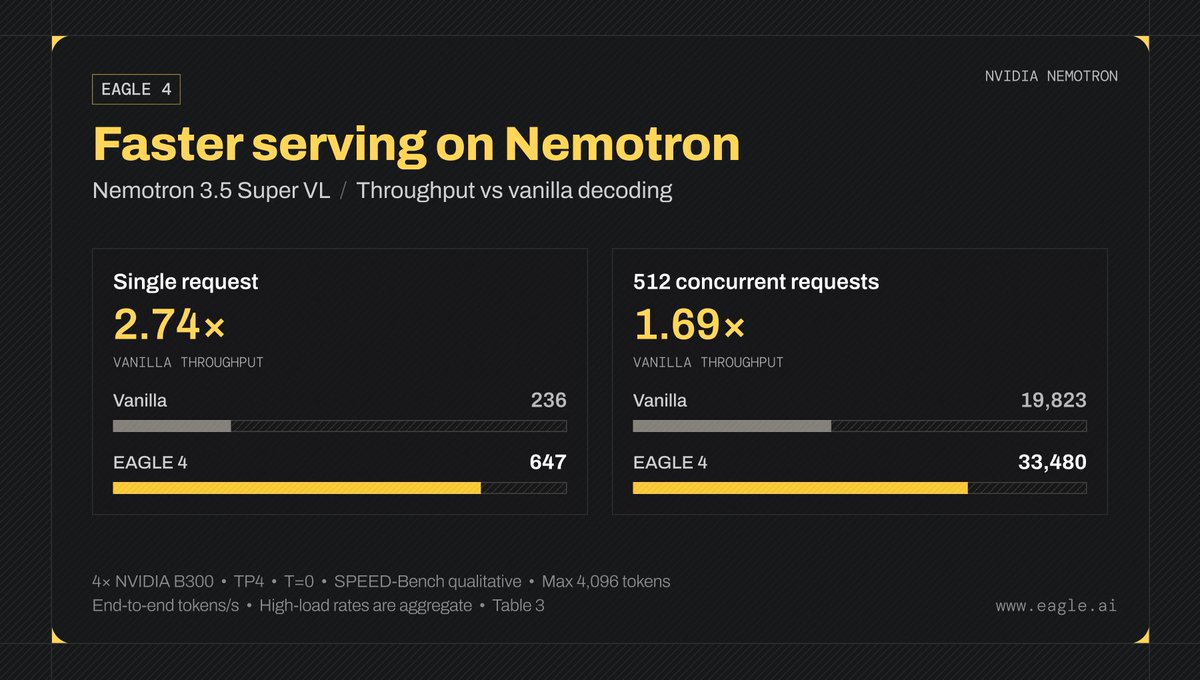
- Big shoutout to all of our partners for making Nemotron 3.5 Super VL their own through post-training 🙌 Here’s what they’ve built 🧵357567464.9K
- Beiträge @NVIDIAAIAs always, NVIDIA Nemotron 3.5 Bolt E4B 4GB is open and customizable. This includes weights, data and recipes. Available now on @huggingface →361068.7K
- Beiträge @NVIDIAAIBenchling @benchlingWe teamed up with @NVIDIAAI to post-train Nemotron 3.5 Super VL on scientific protocol data. It outperformed comparable closed models in troubleshooting and optimizing lab experiments, at a remarkably low cost, representing a promising path for R&D teams to build specialized intelligence they can customize and improve over time with their own data.1195.3K
- Beiträge @NVIDIAAIScale Labs @ScaleAILabsNemotron 3.5 Bolt E4B 4GB from @NVIDIAAI is the 🥇small language model on MultiChallenge, scoring 56.03% and finishing 12.8 points clear of Gemma 4 E4B (43.2%). MultiChallenge tests how well models hold up across realistic multi-turn conversations, from remembering details a user mentioned earlier to following instructions set at the start of a chat. Where Bolt E4B pulls ahead says a lot about where small models are improving. 🧵22557K
 We teamed up with @NVIDIAAI to post-train Nemotron 3.5 Super VL on scientific protocol data. It outperformed comparable closed models in troubleshooting and optimizing lab experiments, at a remarkably low cost, representing a promising path for R&D teams to build specialized intelligence they can customize and improve over time with their own data.
 0166.1K
 Scale Labs@ScaleAILabsNemotron 3.5 Bolt E4B 4GB from @NVIDIAAI is the 🥇small language model on MultiChallenge, scoring 56.03% and finishing 12.8 points clear of Gemma 4 E4B (43.2%). MultiChallenge tests how well models hold up across realistic multi-turn conversations, from remembering details a user mentioned earlier to following instructions set at the start of a chat. Where Bolt E4B pulls ahead says a lot about where small models are improving. 🧵443512.4K
- NVIDIA AIRT @NVIDIAAIInfra: Congrats @MiniMax_AI on dropping MiniMax M3.1 Flash 428B, built for everyday coding and agents. 🙌 In the first-ever Day 0 support, NVIDIA Vera Rubin delivers excellent out-of-the-box performance: ✔️ High throughput of up to 200K TPS/GPU ✔️ Fast interactivity with more than 700 TPS/user Download the NVFP4 checkpoints from @huggingface: or try it instantly:MiniMax (official) @MiniMax_AIMiniMax M3.1 Flash weights are now public. 428B parameters total, 23B activated per token. Agentic performance: A generational leap in agentic tasks, coding, and cybersecurity — 76.2 on BankerToolBench, 73.7% on DeepSWE v1.1, 61.7 on OSWorld V2, 29.6 on Agents' Last Exam, and 82.2 on CyberGym. Efficient by design: MiniMax Sparse Attention and DSpark speculative decoding improve inference efficiency. Hugging Face: ModelScope: API: M Plan: MCode for desktop:02202K

 MiniMax (official)@MiniMax_AIMiniMax M3.1 Flash weights are now public. 428B parameters total, 23B activated per token. Agentic performance: A generational leap in agentic tasks, coding, and cybersecurity — 76.2 on BankerToolBench, 73.7% on DeepSWE v1.1, 61.7 on OSWorld V2, 29.6 on Agents' Last Exam, and 82.2 on CyberGym. Efficient by design: MiniMax Sparse Attention and DSpark speculative decoding improve inference efficiency. Hugging Face: ModelScope: API: M Plan: MCode for desktop:1772653.9K418K
- Meet NVIDIA Nemotron 3.5 Transcribe 🎙️ An open-weight, promptable 30B MoE model with ~4B active parameters that brings transcription in 40 languages, speaker attribution, translation, contextual prompting and audio understanding into one checkpoint. Watch it keep track of who said what when everyone’s talking at once. 1/ 🧵2996658.3K847K
- Beiträge @NVIDIAAIvLLM @vllm_projectRun it today with NeMo Speech's vLLM 0.32.0 plugin, OpenAI-compatible chat completions and MTP speculative decoding. Deployment guide:114915K
 Beiträge @vllm_projectRun it today with NeMo Speech's vLLM 0.32.0 plugin, OpenAI-compatible chat completions and MTP speculative decoding. Deployment guide:102516.4K
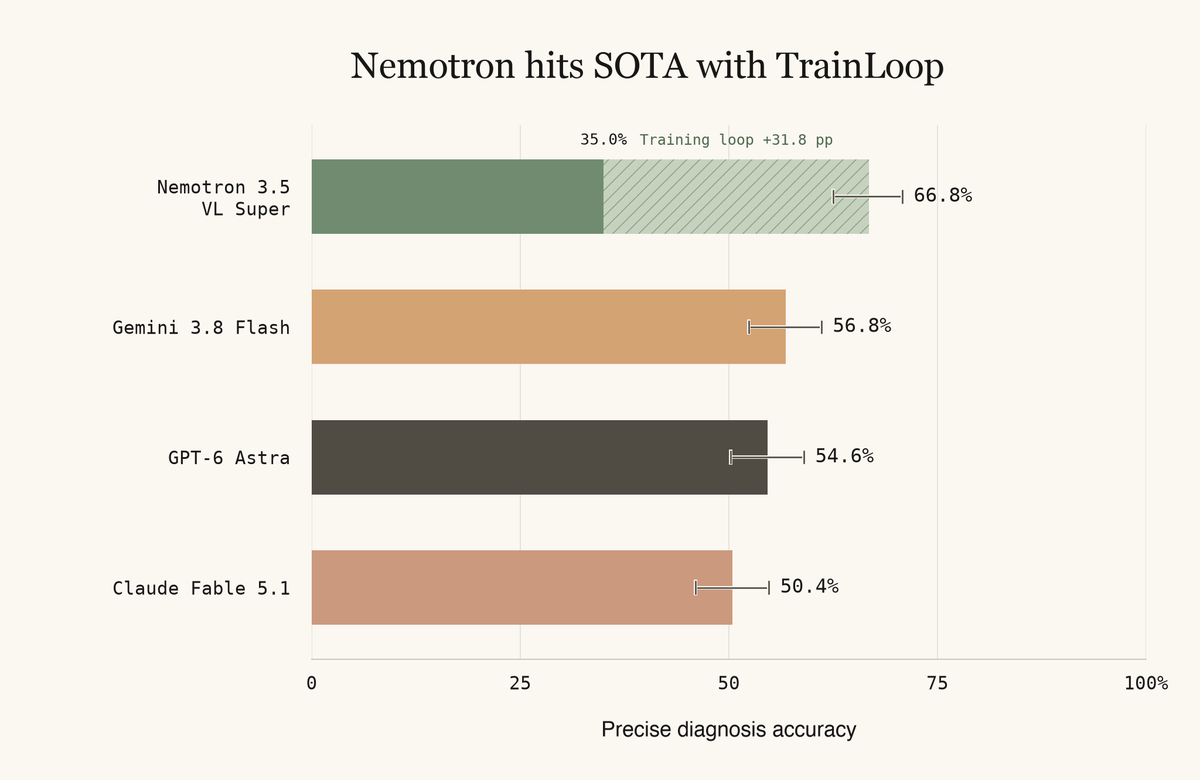
- Beiträge @NVIDIAAIJackson Stokes @jackson_stokesWe partnered with @nvidia, @nollahealth, and @nebiusai to post train Nemotron 3.5 VL Super far past the frontier on dermatology diagnosis. The model set new standards in our internal measures of trainability, and with Nolla it's powering the future of AI in medical care.13145.2K
- Beiträge @NVIDIAAISGLang @sgl_projectNemotron 3.5 Transcribe runs on SGLang-Omni from day 0 🎙️ 30B MoE, ~4B active, 40-language transcription served through /v1/audio/transcriptions endpoint, with streaming and custom prompts. Serve it today:034412.9K
 We partnered with @nvidia, @nollahealth, and @nebiusai to post train Nemotron 3.5 VL Super far past the frontier on dermatology diagnosis. The model set new standards in our internal measures of trainability, and with Nolla it's powering the future of AI in medical care.
 35487.9K
- Nemotron 3.5 Transcribe runs on SGLang-Omni from day 0 🎙️ 30B MoE, ~4B active, 40-language transcription served through /v1/audio/transcriptions endpoint, with streaming and custom prompts. Serve it today:
 NVIDIA AI @NVIDIAAIMeet NVIDIA Nemotron 3.5 Transcribe 🎙️ An open-weight, promptable 30B MoE model with ~4B active parameters that brings transcription in 40 languages, speaker attribution, translation, contextual prompting and audio understanding into one checkpoint. Watch it keep track of who said what when everyone’s talking at once. 1/ 🧵063915.4K
- Serving World Models: Latency vs Throughput with NVIDIA Cosmos 3 Super on Nebius | Cosmos Labs11117311K
- How do you assess cyclone risk beyond what a few decades of historical data can reveal? @AXA researchers are using NVIDIA Earth-2 to help fill that gap. Using FourCastNet 3, one of Earth-2’s open, global weather forecasting models, the team generated more than 1,000 simulated cyclone seasons to study possible storm activity around the globe. These simulations help researchers understand where cyclones travel, how often they occur, and how storms affect multiple regions within the same season. Those insights can inform AXA’s risk assessments and help customers target prevention efforts. Learn how AXA and other organizations are applying Earth-2 to weather forecasting, risk assessment, and environmental modeling:241515813.3K
- NVIDIA AIRT @nvidia: Europe is building its AI future, and we’re all in. From AI factories and AI agents to robotics and healthcare, Jensen took the stage at #NVIDIAGTC Berlin to show how AI is taking shape across the continent. Here's a look back at the highlights:010601.5K
- GTC Berlin After Hours: Keynote Reactions & What’s Next for Developers448512.3K
- Jensen's a black belt now. 🥋NVIDIA Newsroom @nvidianewsroomThe black leather jacket wasn't the final form. 🥋 @JensenHuang was awarded an honorary black belt by the International @Judo Federation, recognizing his leadership and the shared values of judo and innovation: perseverance, respect, and continuous improvement.252642025K
 The black leather jacket wasn't the final form. 🥋 @JensenHuang was awarded an honorary black belt by the International @Judo Federation, recognizing his leadership and the shared values of judo and innovation: perseverance, respect, and continuous improvement.
 183638348.1K
- Build AI agents that speak the language and understand the local context. Here's 5 steps to learn how to post-train NVIDIA Nemotron with synthetic data and LoRA to adapt its responses for regional terminology, policies and tone. Follow the step-by-step tech blog:213119819.8K
- "There's no question everybody will become an AI company and we're going to have a thriving AI economy here in Europe."1323032.6K116K
- From autonomous vehicles to smarter factories, companies are putting physical AI to work. We’ve added new NVIDIA Cosmos tools to help developers generate training data, train world models and test them before deployment. See how @Porsche, @MercedesBenz, @encord_team, @Siemens, @fogsphere, and @ltx_io are using Cosmos across robotics, autonomous driving and factory operations 👇242818318.5K
- NVIDIA AIRT @JensenHuang: I was the opening act for a family of ducks. Thank you, Berlin. What a GTC. Europe is building its AI ecosystem and economy, from AI factories to agents to robots. DSX POD: Vera Rubin modular factories built, cabled and tested in the factory, then delivered ready to produce intelligence. Agents: models, harnesses, sandboxes, knowledge and tools. NVIDIA Agent Toolkit brings the pieces together so companies control what their agents know, access and do. NVIDIA OpenShell enhances safety. Physical AI: new customers across AI-RAN, robotaxis and robotics. Personal AI: after four years building with Microsoft, RTX Spark brings personal agents to the Windows PC. Thank you to President @EmmanuelMacron, Prime Minister @andyburnham and Chancellor @bundeskanzler for hosting me. Great to celebrate Sferical One with Sweden’s technology leaders. And thank you to President @TokayevKZ for the warm welcome. And to our partners and NVIDIA teams: thank you for making it happen. The keynote is here:Pollen Robotics @pollenroboticsMicroducks on stage for Jensen Huang’s famous keynote! We couldn’t be prouder of our little ones. 🥹059901.7K
- NVIDIA AIRT @nvidianewsroom: NVIDIA and @Meta will expand our partnership on @Muse models to improve inference and training performance. Together, we’re exploring NVIDIA OpenShell for safe AI agent deployment and NVIDIA Sentry for monitoring agent behavior. Meta plans broader deployments of NVIDIA Vera Rubin and Vera CPUs. Read the press release:024102.2K
- Beiträge @NVIDIAAICatch up on the latest from GTC Berlin: See what's new with NVIDIA Cosmos, including work from @ADNOCGroup, @microagi, @roboflow, and @ultralytics → And the latest industrial AI announcements →22165.3K
 Microducks on stage for Jensen Huang’s famous keynote! We couldn’t be prouder of our little ones. 🥹1132582.6K601K
- NVIDIA AIRT @NVIDIAGTC: That's a wrap on the #NVIDIAGTC Berlin keynote. 💚 ICYMI, watch the replay:01402.2K
- Europe’s industrial future is taking shape at GTC Berlin. With our CUDA-X and Omniverse libraries, plus Cosmos and Nemotron open models and tools, Europe’s industrial leaders are testing designs faster, simulating robots and improving factory operations. Learn how Agile Robots, @Audi, @Dassault3DS, Schaeffler and @Siemens are putting these technologies to work:233627117.3K
- Beiträge @NVIDIAAIThe innovation extends across Europe’s industrial ecosystem. @autodesk, @AVEVAGroup, @Cadence, Falkor, @MercedesBenz and @Synopsys are also putting our technology to work, from faster design simulations to vehicle inspection and AI factory digital twins. Read their stories in the blog above. 👆02225K