
Kaggle@kaggle
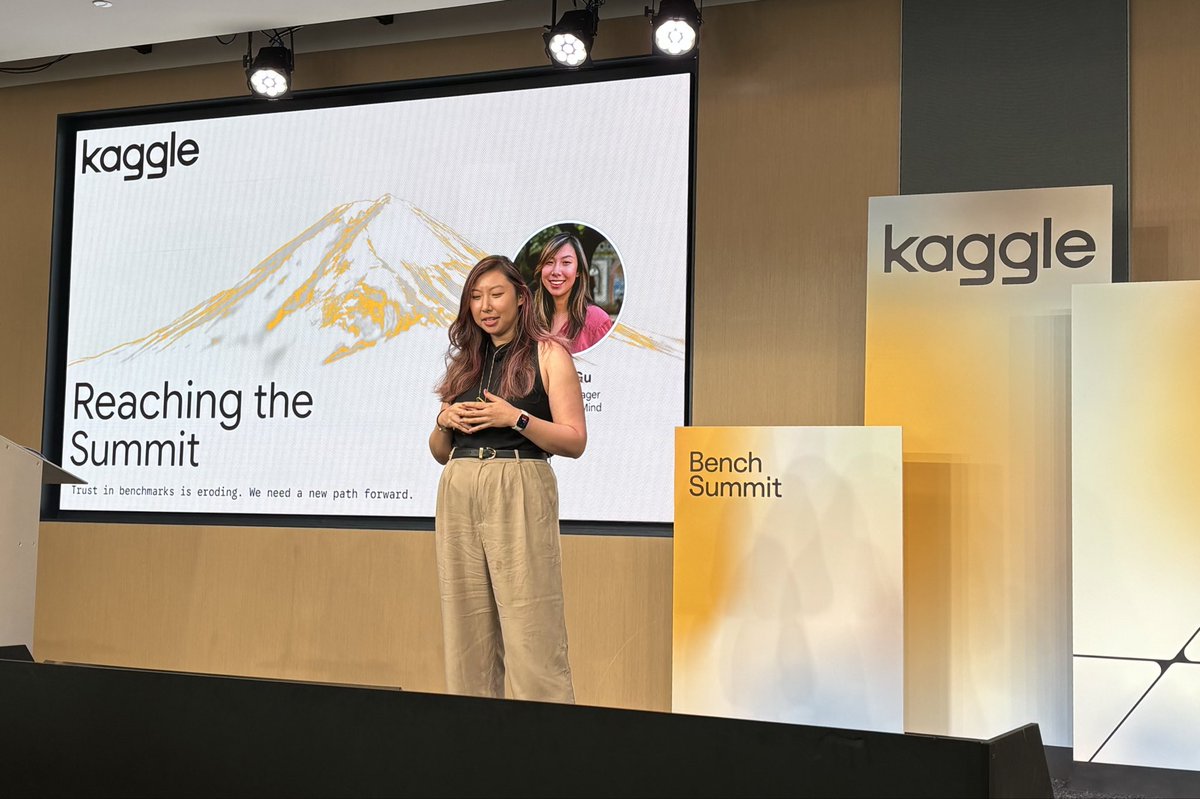
Bench Summit by Kaggle has officially kicked-off!
Trust in benchmarks is eroding. The path forward starts here.
We started strong with @janiejgu sharing key insights on the problems with benchmarks today and Kaggle’s mission to build trust in evals and help the world discover what works and doesn’t work in AI.
During the session, she shared four ways benchmarks fail today:
1. Relevance: Many public benchmarks don’t resemble what your agents do in production.
2. Saturation: Evals go stale within a release cycle.
3. Verification: Everyone has their own implementation of the same benchmarks, meaning scores vary wildly due to infrastructure, not model quality.
4. Infrastructure: Evals infra is hard to build correctly, and everyone rolls their own.
To get numbers you can actually trust, Janie highlighted four essentials:
1. Real workflows as the foundation for benchmarks
2. Continuous benchmarks from crowdsourced tasks, arenas, and production data
3. Rigorous and transparent methodology audited by the community experts
4. Eval infrastructure that everyone can use out of the box
Here’s a sneak peak of the early moments:



43212.4K