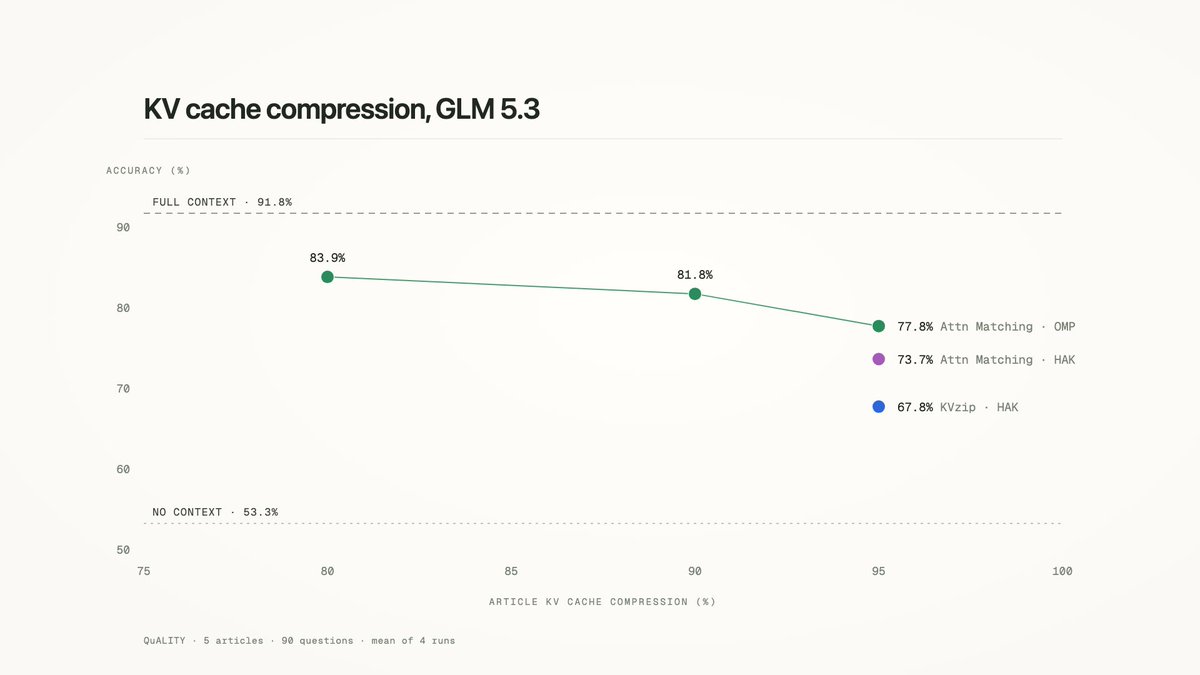
Recent KV cache compression research has focused on small models with dense attention. We scaled these techniques to GLM 5.3, a frontier sparse attention model.
We adapted KVzip and Attention Matching, reducing KV cache size by 80% while retaining over 90% of full-context accuracy on the QuALITY benchmark.
92219921.3K