Bryan Li

@bryanlics

Research Scientist @google, building efficient multi-{lingual,modal,task} information retrieval models for search | PhD from @penn | BA from @columbia

232 Following176 Followers47 Posts
  1. Bryan Li@bryanlics
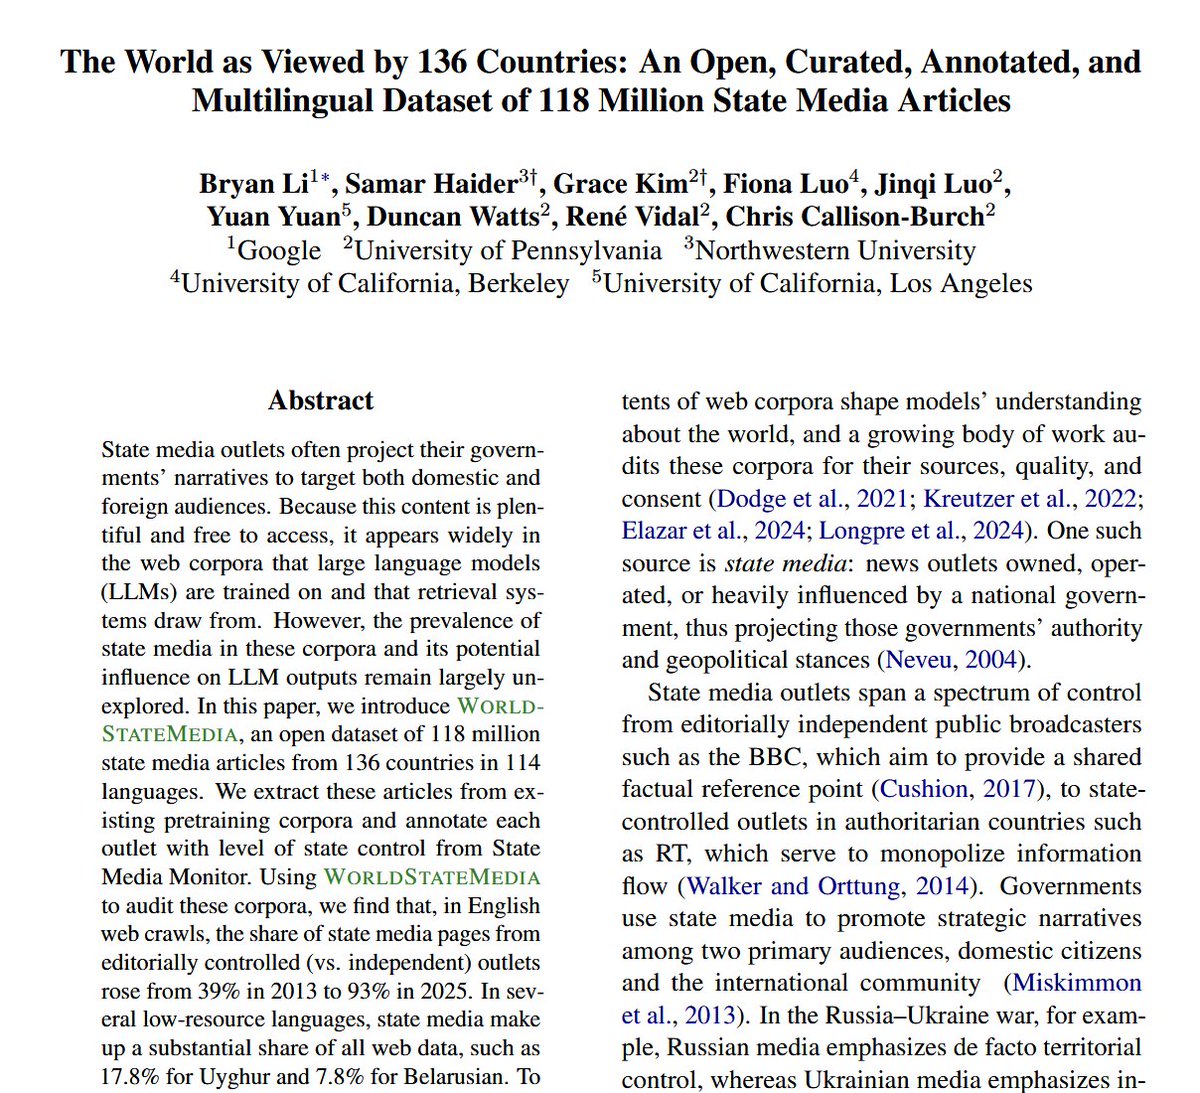
    In a globalized world, every event has ripple effects. When LLMs turn to the open web, how do they reflect state media? We release the WorldStateMedia dataset: 118M articles from 136 countries in 114 languages, and study their prevalence, narratives, and impact on LLMs. 1/6🧵
    Download
    411301.8K
  2. Bryan Li@bryanlics
    Posts @bryanlics
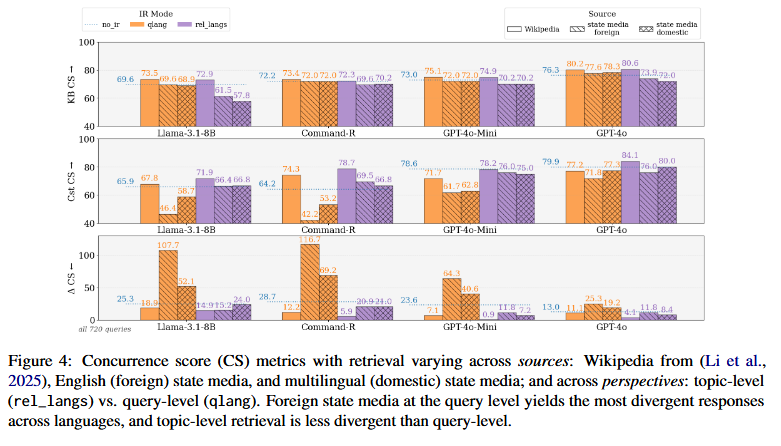
    What happens when LLMs retrieve from state media on territorial disputes? RAG over state media sources decreases factuality vs. RAG over Wikipedia. And for multilingual queries, RAG over English sources increases divergent responses vs. over in-language sources. 5/6🧵
    Download
    10191
  3. Bryan Li@bryanlics
    Given a request, AI systems generate long-form reports. Report evaluation relies on nuggets: essential & granular facts. Prior work on nugget generation treats them as short statements. Our #ICTIR2026 oral proposes DoGMaTiQ, an automated pipeline for Q&A nuggets. 1/6🧵
    Download
    149883
  4. Bryan Li@bryanlics
    Posts @bryanlics
    DoGMaTIQ scores for reports also best correlate with manual human scores, at system-level and at topic-level. More experiments are in our paper: circularity of LLMs for report generation + evaluation, as well as robustness to underperforming systems. 5/6🧵
    Download
    10031
  5. Bryan Li@bryanlics
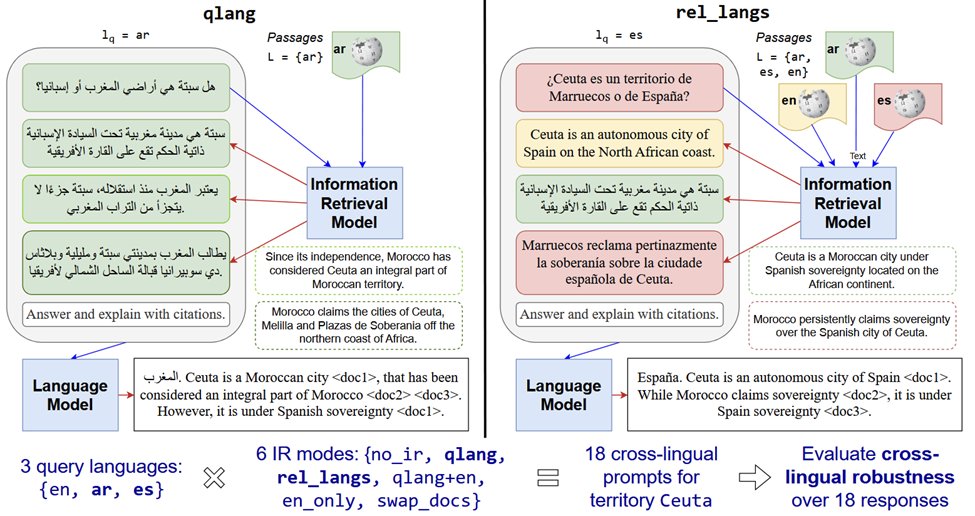
    In a world of geopolitical conflicts, how can AI help us navigate? Our #ACL2025-F work studies RAG robustness across 49 languages. TL;DR: 📈 boost robustness w/ multilingual RAG, 🤔 take care w/ low-resource citations 📜 🤗 1/4 🧵
    Download
    23121.2K
  6. Bryan Li@bryanlics
    Posts @bryanlics
    We study cross-lingual robustness over 4 LLMs and 2 IR models. We find A) multilingual RAG performs best; B) LLM’s citations varies widely across langs. Our further experiments investigate aspects of cross-lingual RAG from IR to LLM explanations. 3/4 🧵
    Download
    100118
  7. Bryan Li@bryanlics
    Posts @bryanlics
    This is the final paper of my PhD! Thanks to my many @upennnlp collaborators: @samarhdr, Chris, and the 7 wonderful students who I was fortunate to mentor. Please look out for our poster at ACL 2025 in Vienna. 4/4 🧵
    003122
  8. Bryan Li@bryanlics
    Bryan Li
    RT @laurenbjiang: 🚀 How well can LLMs know you and personalize your response? Turns out, not so much! Introducing the PersonaMem Benchmark -- 👩🏻‍💻Evaluate LLM's ability to understand evolving persona from 180+ multi-session user-chatbot conversation history 🎯Latest models (GPT-4.1, GPT-4.5, o4-mini, Llama-4, Gemini 2.0, Deepseek-R1, Claude-3.7) all struggle in personalization! 🎨7 personalization skills tested in 15 scenarios 🌟Realistic long-context evaluation up to 1M tokens 👇 Check out what we discovered… (1/6)
    01204.9K
  9. Bryan Li@bryanlics
    Externally retrieving knowledge empowers LLMs for domain-adapted MT ⚖️🩺. But how is knowledge best represented, and how viable is generating it from an LLM itself? Our @GoogleAI paper investigates these questions through a careful experimental setup 📜.
    136464
  10. Bryan Li@bryanlics
    Posts @bryanlics
    TL;DR - translation pairs > bilingual terminologies, generation especially boosts translations for small LLMs Our ablations highlight the need for more challenging domain-adapted MT datasets with modern LLMs. Thanks to collaborators Jiaming, @ebriakou & @ColinCherry!
    00094
  11. Bryan Li@bryanlics
    Bryan Li
    RT @YueYangAI: We share Code-Guided Synthetic Data Generation: using LLM-generated code to create multimodal datasets for text-rich images, such as charts📊, documents📄, etc., to enhance Vision-Language Models. Website: Dataset: Paper: Code:
    046023.2K
  12. Show more posts