SGLang✓

@sgl_project

Run LLMs fast at any scale 🔗 https://t.co/F3u6wYESL0 Join our community https://t.co/fmlOfTOEec For AI tech blogs & deep-dives 👉 @lmsysorg

57 Following12.5K Followers582 Posts
  1. SGLang✓@sgl_project
    DeepInfer set the bar. SGLang pushed it higher! 🚀 SGLang now matches DeepInfer performance on BOTH prefill and decode: • Prefill: Up to 1.04× throughput on 4× GB300 and 4× B300 • Decode: Up to 7.4% throughput on 64× GB300 We also provide an end-to-end reproduction guide and a full serving stack to run it in production.
    Download
    4077658149K
  2. SGLang✓@sgl_project
    SGLang has Day-0 support for LFM3 from @liquidai! LFM3 is a family of small models built to be specialized and run anywhere. · New tri-hybrid architecture: LFM3-1.7B beats LFM2.5-2.6B with 35% fewer parameters · One backbone for every modality: text, vision (now with video), audio, omni, and decision · Built for the edge: ~1 GB at 4-bit, 256K context for on-device agents · Fine-tunes on a single GPU Get started with SGLang 👇
    Download
    Liquid AI @liquidai
    Introducing 𝙻𝙵𝙼𝟹: our new generation of Liquid Foundation Models. With a new tri-hybrid architecture and new multimodal encoders, the LFM3 family is the ideal model suite for specialized intelligence. > 6 model instances, across text, audio, vision, and omni modalities, generative and decision models. > 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱: text, 256k context window. > 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱: vision-language model with video-input support for spatial understanding > 𝙻𝙵𝙼𝟹-𝙰𝚞𝚍𝚒𝚘-𝟸𝙱: tool calls, voice chat, reasoning in 18 languages. > 𝙻𝙵𝙼𝟹-𝙾𝚖𝚗𝚒-𝟸𝙱: an omni model combines vision, audio, and language. > 𝚍𝟷-𝟸𝙱 and 𝚍𝟷-𝙾𝚖𝚗𝚒-𝟸𝙱: decision models with typed outputs and calibrated probabilities in a single pass. Omni adds audio input. > fine-tune on 1 GPU. > a new tri-hybrid architecture > architecture optimized for 14 processor classes across GPUs, CPUs, and NPUs. > 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱 is a beast. It performs competitively with Gemma 4 12B (6x larger), and Gemini 3.5 Flash Lite, and GPT-5.6 Luna, with 1.9B parameters. > 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱 is #1 on the Pareto frontier of device intelligence 𝚙𝚒𝚙𝚎𝚝𝚝𝚎.𝚕𝚒𝚚𝚞𝚒𝚍.𝚊𝚒 Every modality for specialized intelligence. Pick the one that fits your use case, customize it, and run it on-device. 1/ 🧵
    35381.9K
  3. Liquid AI✓@liquidai
    Introducing 𝙻𝙵𝙼𝟹: our new generation of Liquid Foundation Models. With a new tri-hybrid architecture and new multimodal encoders, the LFM3 family is the ideal model suite for specialized intelligence. > 6 model instances, across text, audio, vision, and omni modalities, generative and decision models. > 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱: text, 256k context window. > 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱: vision-language model with video-input support for spatial understanding > 𝙻𝙵𝙼𝟹-𝙰𝚞𝚍𝚒𝚘-𝟸𝙱: tool calls, voice chat, reasoning in 18 languages. > 𝙻𝙵𝙼𝟹-𝙾𝚖𝚗𝚒-𝟸𝙱: an omni model combines vision, audio, and language. > 𝚍𝟷-𝟸𝙱 and 𝚍𝟷-𝙾𝚖𝚗𝚒-𝟸𝙱: decision models with typed outputs and calibrated probabilities in a single pass. Omni adds audio input. > fine-tune on 1 GPU. > a new tri-hybrid architecture > architecture optimized for 14 processor classes across GPUs, CPUs, and NPUs. > 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱 is a beast. It performs competitively with Gemma 4 12B (6x larger), and Gemini 3.5 Flash Lite, and GPT-5.6 Luna, with 1.9B parameters. > 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱 is #1 on the Pareto frontier of device intelligence 𝚙𝚒𝚙𝚎𝚝𝚝𝚎.𝚕𝚒𝚚𝚞𝚒𝚍.𝚊𝚒 Every modality for specialized intelligence. Pick the one that fits your use case, customize it, and run it on-device. 1/ 🧵
    Download
    5031.2K8.9K2.2M
  4. SGLang✓@sgl_project
    Posts @sgl_project
    @liquidai Cookbook:
    001190
  5. SGLang✓@sgl_project
    Hy-SimulMT is coming to SGLang Omni! 🚀 🎙️ Chinese ↔ English speech translation ⚡ Streaming audio in, translated text out 🛠️ BF16 inference on a single H200 Excited to bring Tencent Hunyuan’s latest speech translation model to the community! Serve with SGLang now 👇
    Download
    Tencent Hy @TencentHunyuan
    Hy-SimulMT is now open source! 🚀 Tencent HY’s real-time Chinese ↔ English Simultaneous Interpreting Model. Key features: ⚡ Low latency (~3s) 🎯 High accuracy 🎙️ Real-time voice cloning 🏆 Outperforms most open-source models and commercial APIs Download, try, and build with it! 👇: Hugging Face: ModelScope: GitHub:
    2191.5K
  6. Tencent Hy✓@TencentHunyuan
    Hy-SimulMT is now open source! 🚀 Tencent HY’s real-time Chinese ↔ English Simultaneous Interpreting Model. Key features: ⚡ Low latency (~3s) 🎯 High accuracy 🎙️ Real-time voice cloning 🏆 Outperforms most open-source models and commercial APIs Download, try, and build with it! 👇: Hugging Face: ModelScope: GitHub:
    Download
    443334227.3K
  7. SGLang✓@sgl_project
    Posts @sgl_project
    Cookbook:
    002480
  8. SGLang✓@sgl_project
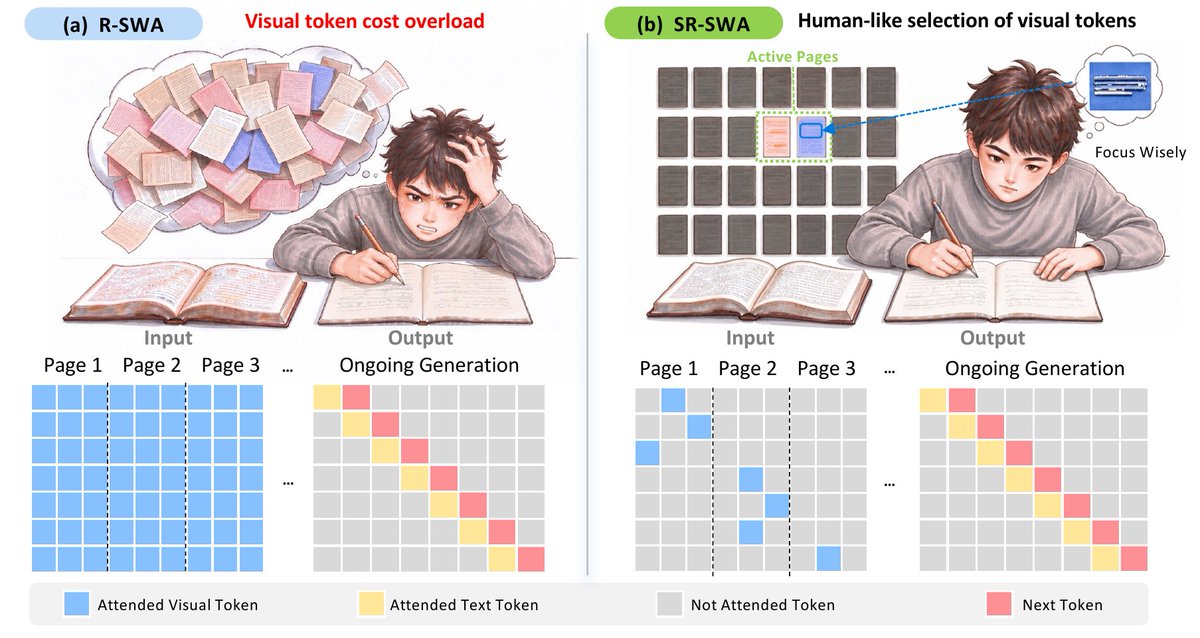
    Congrats to @Baidu_Inc on Unlimited OCR 2! An entire book parsed in a single request, with decode latency and memory staying flat across hundreds of pages 👀 Proud to be the recommended serving path. Serving instructions are in the model card: Cookbook coming
    Baidu Inc. @Baidu_Inc
    Unlimited OCR 2 is here, and it's open source. 📖 ✨ Longer documents can mean a lot more attention computation. Our new SR-SWA mechanism keeps that in check by condensing text-visual attention interactions into a fixed-size set of working references. Here's what it delivers: - Document parsing at virtually any length, within a finite context window - Nearly constant per-step decoding latency and memory footprint as documents grow longer - State-of-the-art performance on MPDocBench and MarathonDocBench, covering documents from dozens to hundreds of pages Check out the model here ↓
    33312.1K
  9. Baidu Inc.@Baidu_Inc
    Unlimited OCR 2 is here, and it's open source. 📖 ✨ Longer documents can mean a lot more attention computation. Our new SR-SWA mechanism keeps that in check by condensing text-visual attention interactions into a fixed-size set of working references. Here's what it delivers: - Document parsing at virtually any length, within a finite context window - Nearly constant per-step decoding latency and memory footprint as documents grow longer - State-of-the-art performance on MPDocBench and MarathonDocBench, covering documents from dozens to hundreds of pages Check out the model here ↓
    Download
    661161.1K164K
  10. SGLang✓@sgl_project
    SGLang
    RT @inco_ai: Inco is going to #SGLangSummit 2026 🧡 Our open-model endpoints run several times faster than most providers on @ArtificialAnlys. Our co-founder @ZhijianLiu will lead a breakout session on #DFlash and what it takes to build inference for the agentic era, at scale. 🎙️ DFlash and Beyond: How Inco Runs the Fastest Open-Model Endpoints 📍 Nov 12–13, SF 🎟️ Coming to the summit? Stop by, say hi, and let's talk about your inference stack.
    06067
  11. SGLang✓@sgl_project
    SGLang
    RT @zili_meng: Giving a talk at SGLang Summit in SF next month -- will talk about Running Trillion Parameter LLMs on Consumer Hardware using SSD! @sgl_project community
    01072
  12. SGLang✓@sgl_project
    We’ve been working to push both ends of the curve on DeepSeek V4.1 Flash 🚀 • For low latency, our MegaKernel optimizations take interactivity from 538 to 943 tok/s/user. • For high throughput, WideEP and system-wide optimizations take total throughput (cache + new input + output) from 348K to 654K tok/s per GPU. There’s still lots of room for improvement. We’ll share more updates soon.
    SemiAnalysis @SemiAnalysis_
    Congrats to the SGLang and RadixArk team for their amazing work on MegaKernel + PD, improving both high concurrency throughput and low-latency serving as well! (1/2)🧵
    1491519.2K
  13. SemiAnalysis✓@SemiAnalysis_
    Congrats to the SGLang and RadixArk team for their amazing work on MegaKernel + PD, improving both high concurrency throughput and low-latency serving as well! (1/2)🧵
    Download
    10710735.4K
  14. SGLang✓@sgl_project
    Posts @sgl_project
    We published the full reproduction guide, including exact SGLang commits, configurations, launch commands, and benchmark scripts.
    30242.4K
  15. SGLang✓@sgl_project
    Posts @sgl_project
    Huge thanks to @deepseek_ai for open-sourcing DeepInfer and setting such a high bar! Sharing engineering at this level moves the entire community forward. We've worked hard to bring these optimizations into SGLang and rigorously validate the results. We're excited to keep pushing inference performance and efficiency further, making tokens more affordable for everyone! Full technical blog:
    10332.1K
  16. SGLang✓@sgl_project
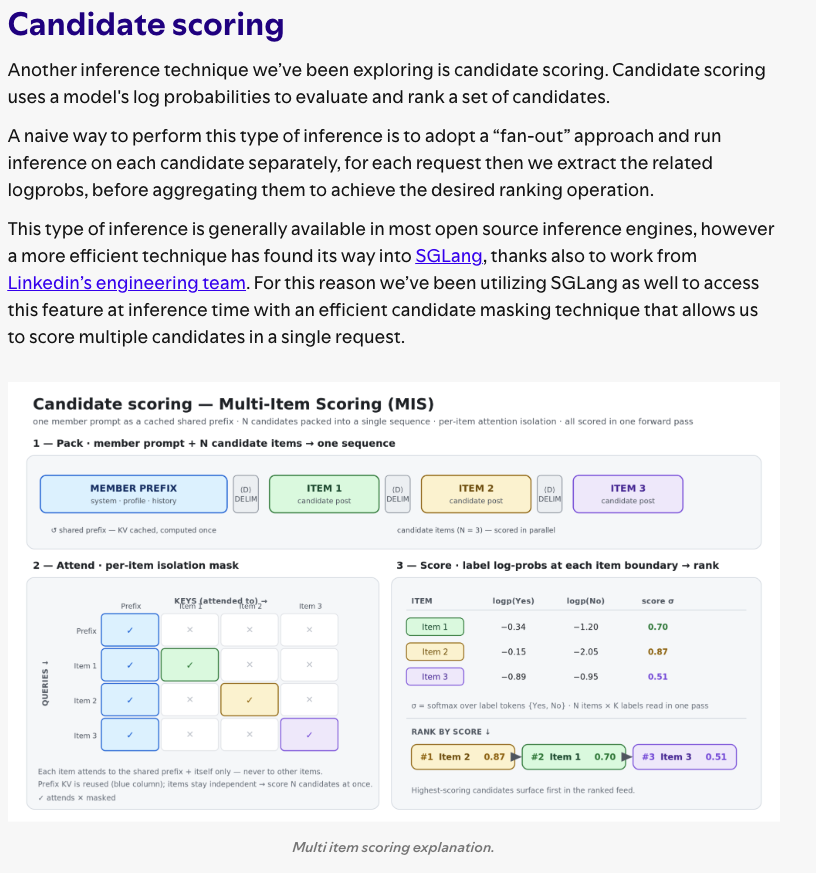
    🎧 Scoring many candidates one request at a time gets expensive fast in generative recommendation. @SpotifyEng uses SGLang to solve it. In their latest blog, @Spotify shares how they serve LLM-powered podcast recommendations. For candidate scoring, they rely on SGLang's Score API. It uses multi-item scoring with candidate masking to score many candidates in a single request. This removes the per-candidate request fan-out and cuts overhead. The feature was built with contributions from @LinkedIn, and Spotify uses it to explore LLM-based candidate ranking. Great to see SGLang in Spotify's generative recommendation work. Read the blog:
    Download
    75513K
  17. SGLang✓@sgl_project
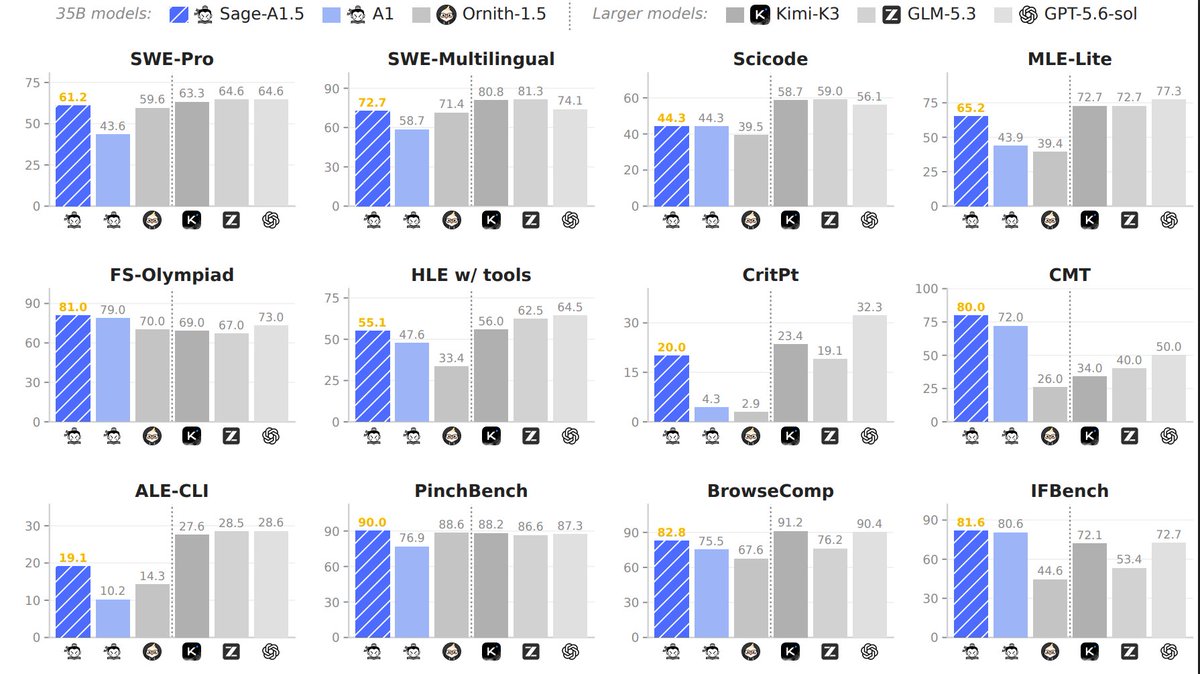
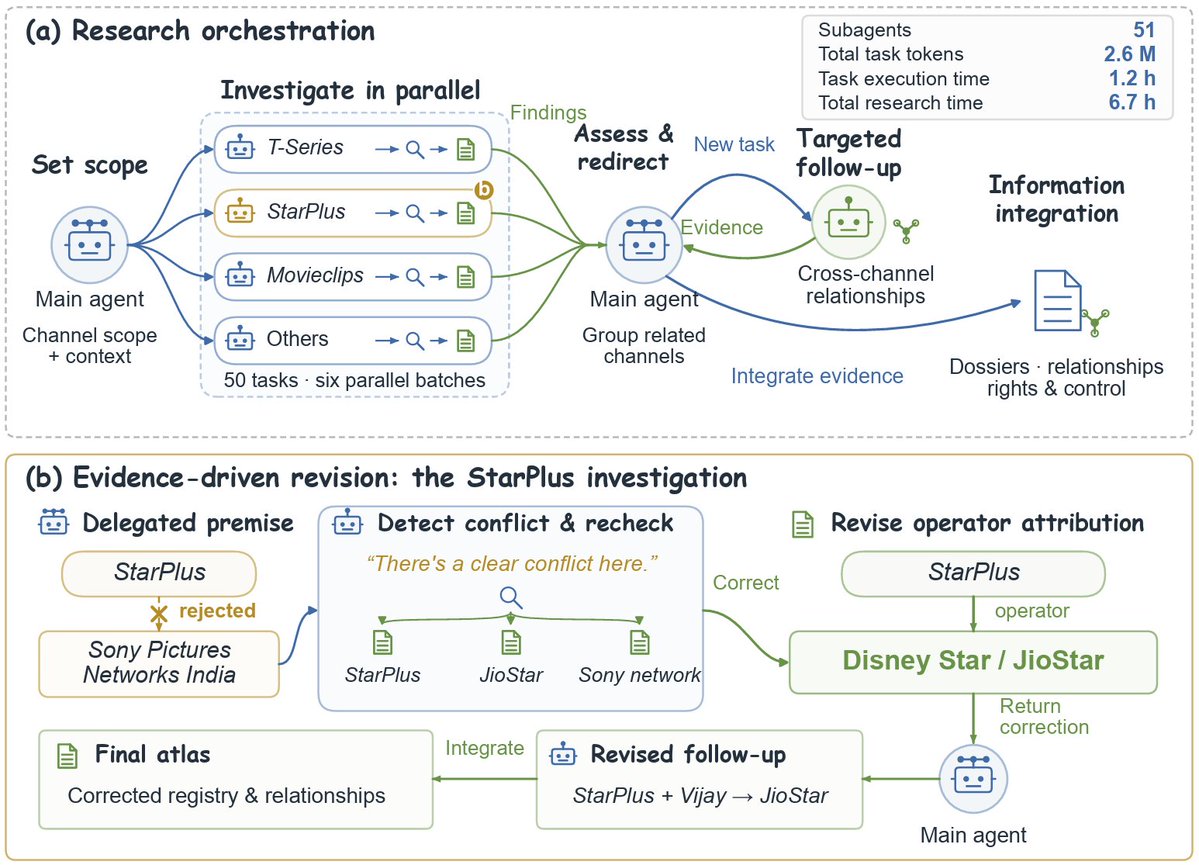
    SGLang has Day-0 support for Sage-A1.5 from @sageai_official, a 35B MoE with only 3B active, built for agentic workflows: parallel subagents, self-verification, and 61.2% on SWE-Bench Pro. Try it on SGLang today!
    SageAI @sageai_official
    🚀Sage-A1.5 by Shanghai AI Lab is here — pushing 35B agentic intelligence to the next level 🔥 🤖 35B MoE (3B active) 🧩 Agentic Orchestration & Verification — spawns parallel subagents & self-corrects on the fly 🔄 RSI Data Flywheel — evolved via real scientific discovery workflows & tens of thousands of synthesized environments 🚀 Beats frontier giants on FS-Olympiad, FS-Research, CMT & PinchBench, and hits 61.2% on SWE-Bench Pro 💻 Runs locally via vLLM(@vllm_project), SGLang(@sgl_project), llama.cpp & LM Studio (Q4_K_M ~20GB) Scale the Horizon, Compose the Capabilities 👇 🔗 Model: @huggingface @ModelScope2022 🕹️ Try it free:
    31151.5K
  18. SageAI✓@sageai_official
    🚀Sage-A1.5 by Shanghai AI Lab is here — pushing 35B agentic intelligence to the next level 🔥 🤖 35B MoE (3B active) 🧩 Agentic Orchestration & Verification — spawns parallel subagents & self-corrects on the fly 🔄 RSI Data Flywheel — evolved via real scientific discovery workflows & tens of thousands of synthesized environments 🚀 Beats frontier giants on FS-Olympiad, FS-Research, CMT & PinchBench, and hits 61.2% on SWE-Bench Pro 💻 Runs locally via vLLM(@vllm_project), SGLang(@sgl_project), llama.cpp & LM Studio (Q4_K_M ~20GB) Scale the Horizon, Compose the Capabilities 👇 🔗 Model: @huggingface @ModelScope2022 🕹️ Try it free:
    Download
    19168812.1K
  19. SGLang✓@sgl_project
    Space Bunny is here! 🐰 MiniMax M3.1 Flash hits >1K tok/s, bs1 decode with SGLang, production-ready from Day 0. This integration is a joint effort by @MiniMax_AI, @NVIDIAAI, @AMD, and @radixark, and you can also run RL with Miles! -Broad hardware support: NVIDIA Blackwell and Hopper (GB300/B300/B200/H200), plus AMD Instinct MI350X and MI355X. -Agentic serving at scale: ~100K total tok/s per GPU on the AgentX coding-agent trace with 96 concurrent sessions. -Speculative decoding: Supports MiniMax's DSpark draft and a DFlash2 draft trained by @radixark; supports HiCache and multimodal input. -Ultra-low-latency inference: MegaKernels deliver 2.15× faster single-request decode.
    Download
    14168722.9K
  20. MiniMax (official)@MiniMax_AI
    MiniMax M3.1 Flash weights are now public. 428B parameters total, 23B activated per token. Agentic performance: A generational leap in agentic tasks, coding, and cybersecurity — 76.2 on BankerToolBench, 73.7% on DeepSWE v1.1, 61.7 on OSWorld V2, 29.6 on Agents' Last Exam, and 82.2 on CyberGym. Efficient by design: MiniMax Sparse Attention and DSpark speculative decoding improve inference efficiency. Hugging Face: ModelScope: API: M Plan: MCode for desktop:
    1772653.8K419K
  21. SGLang✓@sgl_project
    Posts @sgl_project
    Cookbook:
    012542
  22. SGLang✓@sgl_project
    Posts @sgl_project
    Read full Blog:
    013680
  23. SGLang✓@sgl_project
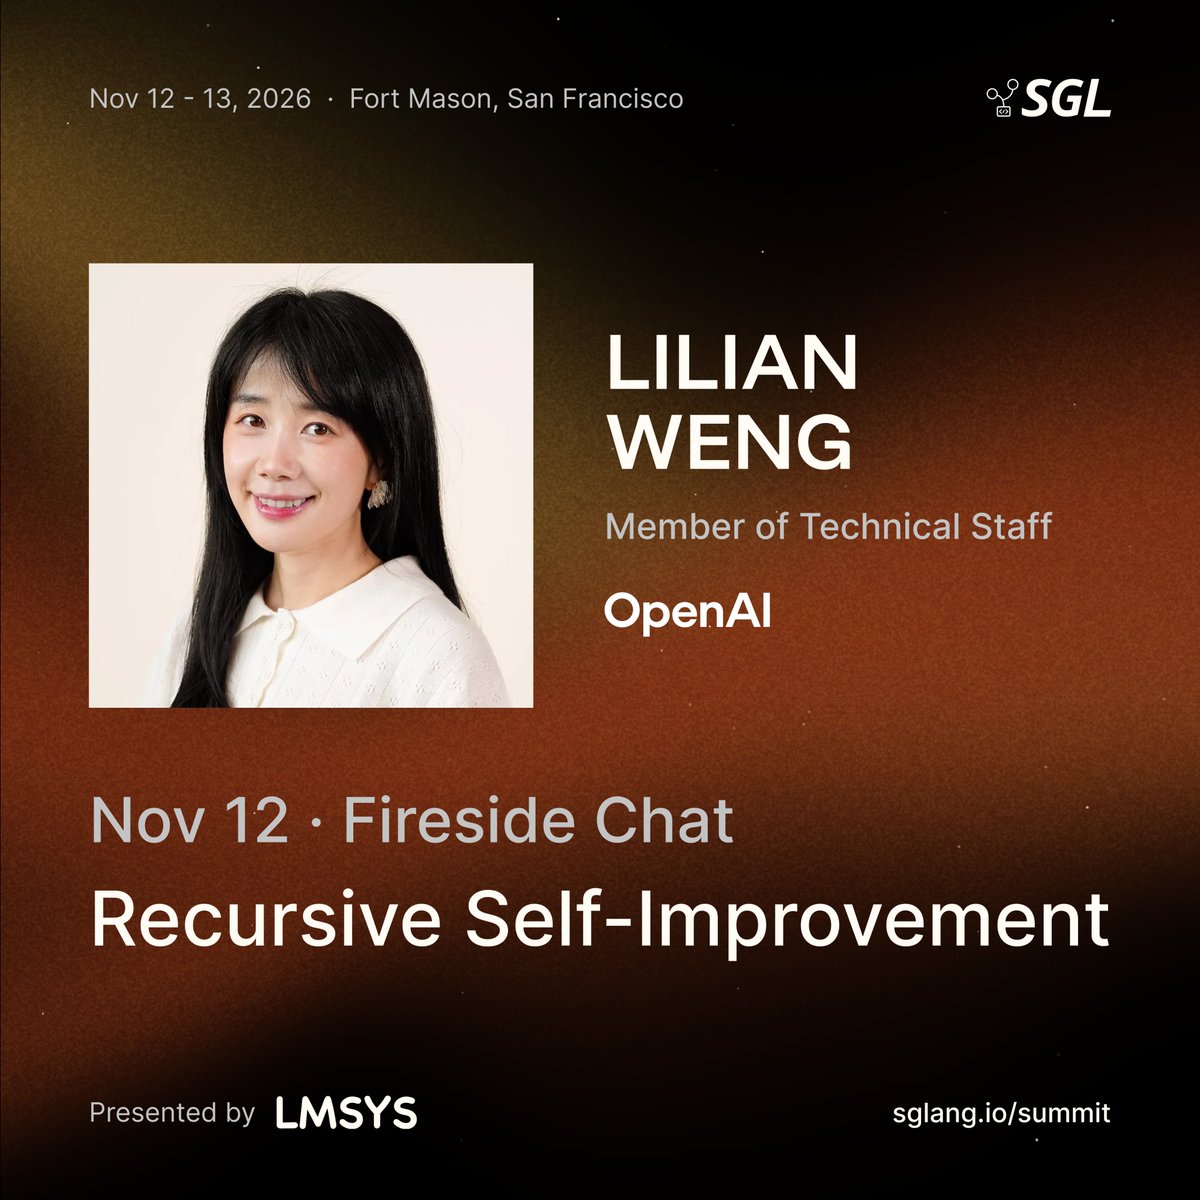
    We’re excited to welcome @lilianweng to SGLang Summit for a fireside chat on Recursive Self-Improvement! She’ll explore how AI can help build its own successors, what it takes to make that work, and where the process runs into limits. If you’ve followed her writing on Lil’Log, come hear her live on Nov 12. We can’t wait to see you there! 🗓️ Nov 12-13 📍 Fort Mason, SF 🎟️ Get your pass:
    Download
    105040757.8K
  24. SGLang✓@sgl_project
    Today, in close collaboration with @awscloud and alongside the TorchNeuron launch, we’re announcing the beta of the SGLang AWS Trainium plugin, built on TorchNeuron and running on Trainium2 and Trainium3. What’s in the beta: - Inference serving and RL rollouts - Support for Qwen3, DeepSeek, and GLM model families, with more frontier models on the way - Early preview of heterogeneous RL, with rollouts on Trainium and training via Miles (@radixark) Stay tuned for more at the SGLang Summit next month!
    Download
    984228.6K
  25. SGLang✓@sgl_project
    Posts @sgl_project
    Want to try it out? Beta sign-up is here:
    001293