Unsloth AI✓

@UnslothAI

Run and train models locally with the Unsloth Desktop app. 🦥 https://t.co/2kXqhhvdCD

483 Following102K Followers817 Posts
  1. Unsloth AI✓@UnslothAI
    Introducing Unsloth Desktop 🦥 The first desktop app to run and train models locally. • Open-source. Runs on Mac, Windows and Linux • Supports MLX, diffusion image/video, audio, GGUF • Connect Claude Code and Codex to local LLMs • 50% more accurate, self-healing tool calls + sandboxed code exec • Works for CPU + multiGPU setups - NVIDIA, AMD, Intel, Mac • Train models 2× faster with 70% less VRAM • Private web search, deep research, RAG, MCP and exports (NVFP4, GGUF) • Use Unsloth’s OpenAI-compatible API and cloud models • Securely deploy LLMs remotely and access anywhere Unsloth Desktop is now available on and GitHub. GitHub: Blog and Guide:
    Download
    2866484.9K885K
  2. Unsloth AI✓@UnslothAI
    Your local LLM can now take control of a browser and complete tasks autonomously via Unsloth! Qwen3.8-27B successfully controlled the browser to complete tasks like chess, painting, with no human intervention. GitHub: Guide:
    Download
    627276531.2K
  3. Unsloth AI✓@UnslothAI
    Unsloth AI
    RT @MiniMax_AI: MiniMax M3.1 Flash meets the @UnslothAI community. 🐙🦥✨ Unsloth’s Dynamic GGUFs bring our 428B MoE model to a 143.9GB 2-bit footprint, with 91.5% top-1 token agreement in their evaluation across seven domains. That means a lower memory barrier to self-hosting, deployment through Unsloth Desktop and llama.cpp, and an OpenAI-compatible API for existing apps and agents. With 78K+ GitHub stars and over 500M model downloads on Hugging Face, Unsloth gives M3.1 Flash a path into an established community of developers running, evaluating and building with open models. Open weights. Local control. More ways to build.
    Unsloth AI @UnslothAI
    MiniMax-M3.1-Flash can now run locally! We made 2-bit GGUF retain 91.5% top 1 accuracy while being 45% smaller. Run on 150GB RAM. MiniMax-M3.1-Flash is the strongest open model for its size & among the best overall. GGUF: Guide:
    01701.1K
  4. Unsloth AI✓@UnslothAI
    MiniMax-M3.1-Flash can now run locally! We made 2-bit GGUF retain 91.5% top 1 accuracy while being 45% smaller. Run on 150GB RAM. MiniMax-M3.1-Flash is the strongest open model for its size & among the best overall. GGUF: Guide:
    Download
    MiniMax (official) @MiniMax_AI
    MiniMax M3.1 Flash: Space Performance + Bunny Speed 🚀🐰 Yes, Space Bunny - which has topped global leaderboards with 200T+ tokens - was an earlier version of M3.1 Flash. 💰Redefining the performance economics of agentic AI. M3.1 Flash achieves frontier-level intelligence across key tasks such as Cowork (Automation-Bench: 62%; ALE: 30%), Coding (DeepSWE: 74%) and Visual Reasoning (BabyVision: 91%), at 1/3 the cost of M3 and 3x the speed. API pricing (flat rate): $0.15 / $0.60 per 1M input/output tokens, with cache reads at $0.015 / 1M tokens. Model weights will arrive on Oct 23. API: M Plan: MiniMax Code for desktop:
    756161855.7K
  5. Unsloth AI✓@UnslothAI
    Unsloth AI
    RT @NVIDIARTXSpark: Getting started with @UnslothAI on RTX Spark? Just run the .exe. @danielhanchen and @NaderLikeLadder got hands-on with NVIDIA RTX Spark to talk about running and training AI models locally, exploring reinforcement learning, and making it easier to start building with Unsloth.
    01101.2K
  6. MiniMax (official)@MiniMax_AI
    MiniMax M3.1 Flash: Space Performance + Bunny Speed 🚀🐰 Yes, Space Bunny - which has topped global leaderboards with 200T+ tokens - was an earlier version of M3.1 Flash. 💰Redefining the performance economics of agentic AI. M3.1 Flash achieves frontier-level intelligence across key tasks such as Cowork (Automation-Bench: 62%; ALE: 30%), Coding (DeepSWE: 74%) and Visual Reasoning (BabyVision: 91%), at 1/3 the cost of M3 and 3x the speed. API pricing (flat rate): $0.15 / $0.60 per 1M input/output tokens, with cache reads at $0.015 / 1M tokens. Model weights will arrive on Oct 23. API: M Plan: MiniMax Code for desktop:
    Download
    4726787.5K1.7M
  7. Unsloth AI✓@UnslothAI
    NVIDIA releases Nemotron-3.5-Bolt-E4B, a new model that runs locally on 6GB RAM. 💚 Bolt-E4B can run on edge devices like phones and delivers top-tier performance for its size. Trained on Gemma 4, it supports vision. GGUF: Guide:
    Download
    NVIDIA AI @NVIDIAAI
    Available now: NVIDIA Nemotron 3.5 Bolt E4B 4GB ⚡️ Our newest small open model is built for local assistants, interactive characters and robots that can carry on a conversation and use tools to get things done. Watch Reachy Mini chat and move, with Bolt handling conversation and NVIDIA Cosmos handling vision. Both models run locally on Jetson Orin Nano 8GB. Learn more:
    912032.3K122K
  8. NVIDIA AI✓@NVIDIAAI
    Available now: NVIDIA Nemotron 3.5 Bolt E4B 4GB ⚡️ Our newest small open model is built for local assistants, interactive characters and robots that can carry on a conversation and use tools to get things done. Watch Reachy Mini chat and move, with Bolt handling conversation and NVIDIA Cosmos handling vision. Both models run locally on Jetson Orin Nano 8GB. Learn more:
    Download
    1472602.1K287K
  9. Unsloth AI✓@UnslothAI
    Unsloth AI
    RT @reflection_ai: We plugged Beam into @opencode, asked it to look at @UnslothAI, and create a fine-tuning notebook for the latest and smallest Gemma-4 model on a Text2SQL task – an out of distribution domain for Beam. The model successfully researches the model cards, Unsloth documentation, and available READMEs, and implements the fine-tuning logic and surrounding machinery. As a result, Beam is able to successfully finetune Gemma, increasing Gemma’s accuracy on its heldout test set by 66.5%.
    01901.2K
  10. Unsloth AI✓@UnslothAI
    Run Flint locally on 24GB RAM via Unsloth Dynamic GGUFs! Flint is the strongest MoE model under 50B parameters. Recursive’s Apache-2.0 model has 39.8B parameters (2.5B active). Run at 125 t/s on Mac, 150 on RTX Spark GGUF: Guide:
    Download
    Richard Socher @RichardSocher
    Introducing Flint, @Recursive_SI’s first model: a fast local coding model built with our automated research system, the Eureka Machine. • Best-in-class fast local coding • Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark • Built from scratch in under 4 months Private, unmetered intelligence on your own machine. Open weights available now on @huggingface, run it locally on your favorite framework or try it for free on @opencode or @pidotdev.
    589389245.7K
  11. Richard Socher✓@RichardSocher
    Introducing Flint, @Recursive_SI’s first model: a fast local coding model built with our automated research system, the Eureka Machine. • Best-in-class fast local coding • Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark • Built from scratch in under 4 months Private, unmetered intelligence on your own machine. Open weights available now on @huggingface, run it locally on your favorite framework or try it for free on @opencode or @pidotdev.
    Download
    6388938.4K3.4M
  12. Unsloth AI✓@UnslothAI
    Unsloth AI
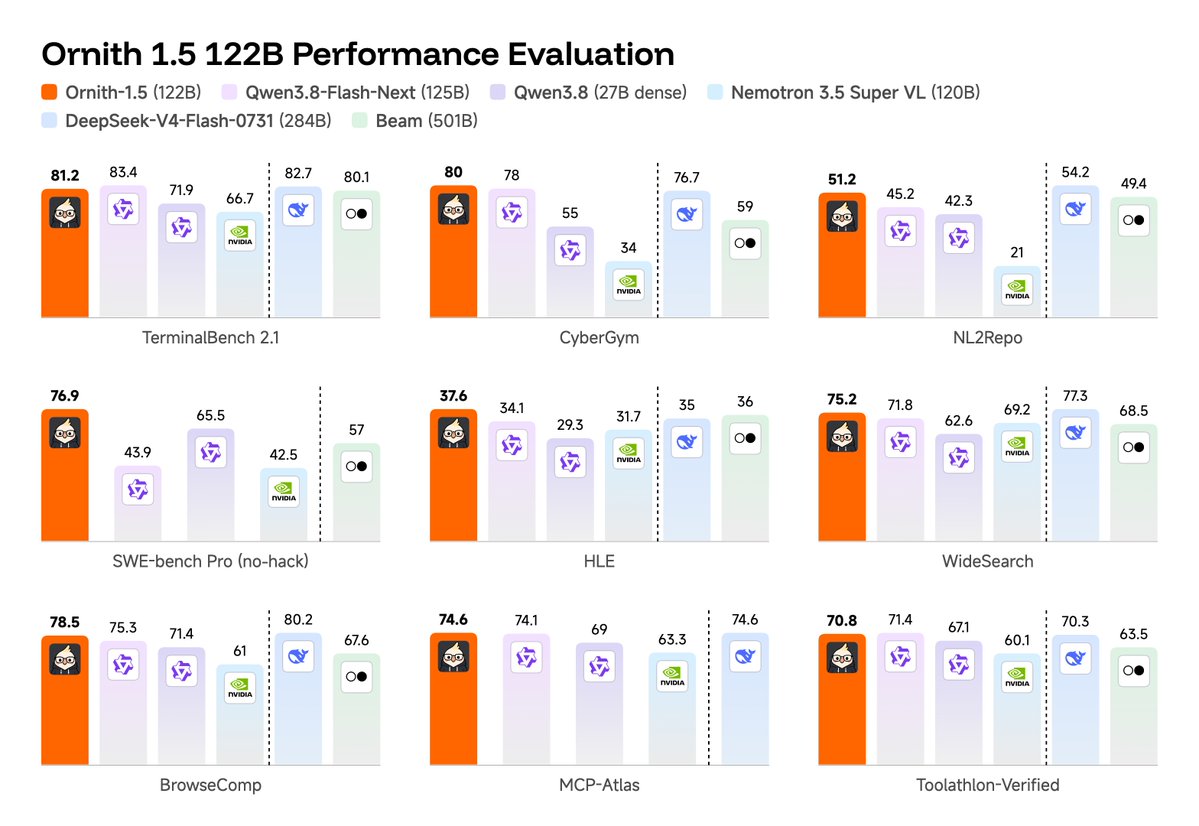
    RT @ornith_: 🥳 Ornith-1.5-122B Unsloth GGUFs are now available! 🧡 Thanks for the awesome work by @UnslothAI 🔗
    Ornith @ornith_
    Aloha!🌺 Meet Ornith-1.5-122B: No Tradeoff Between Strong and Fast Stronger. Faster. Leaner. Ornith-1.5-122B delivers frontier-level capabilities with exceptional inference efficiency. With superior instruction following, stronger task decomposition, and deeper understanding of real-world workflows, it achieves state-of-the-art performance among open-source models of comparable size, while running on a single NVIDIA DGX card!! Open weights under the MIT license. Coding ✅SWE-bench Verified: 0.845 ✅TB2.1: 0.813 ✅CyberGym: 0.800 ✅NL2Repo: 0.512 Agentic ✅HLE: 0.446 ✅BrowseComp: 0.785 ✅MCP-Atlas: 0.746 ✅Toolathlon: 0.708 🤗Hugging Face: We can’t wait to see what you build with Ornith-1.5-122B.
    01901.2K
  13. Ornith✓@ornith_
    Aloha!🌺 Meet Ornith-1.5-122B: No Tradeoff Between Strong and Fast Stronger. Faster. Leaner. Ornith-1.5-122B delivers frontier-level capabilities with exceptional inference efficiency. With superior instruction following, stronger task decomposition, and deeper understanding of real-world workflows, it achieves state-of-the-art performance among open-source models of comparable size, while running on a single NVIDIA DGX card!! Open weights under the MIT license. Coding ✅SWE-bench Verified: 0.845 ✅TB2.1: 0.813 ✅CyberGym: 0.800 ✅NL2Repo: 0.512 Agentic ✅HLE: 0.446 ✅BrowseComp: 0.785 ✅MCP-Atlas: 0.746 ✅Toolathlon: 0.708 🤗Hugging Face: We can’t wait to see what you build with Ornith-1.5-122B.
    Download
    2225212.8K1.5M
  14. Unsloth AI✓@UnslothAI
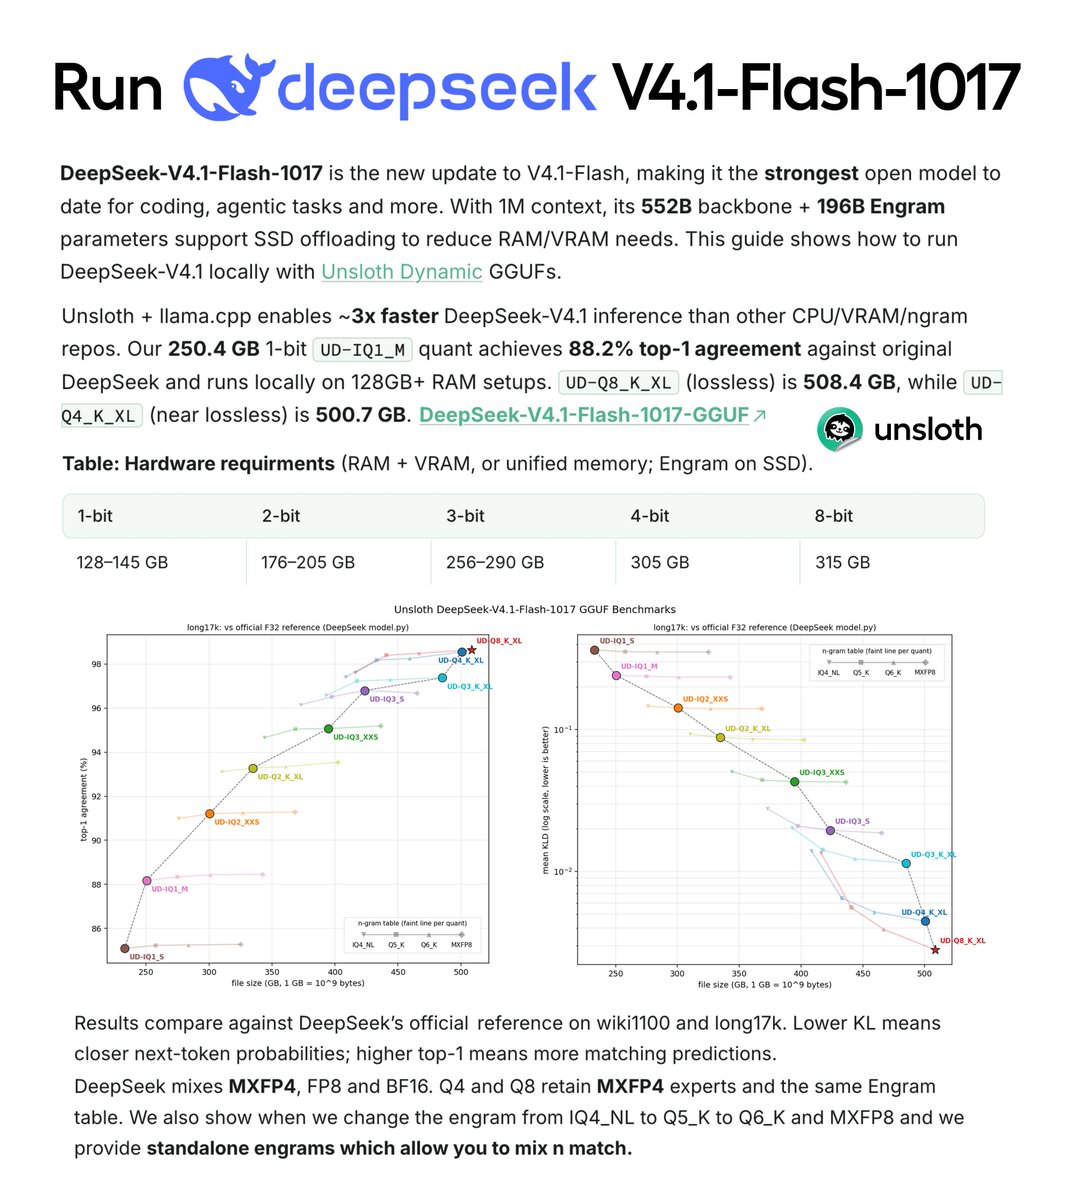
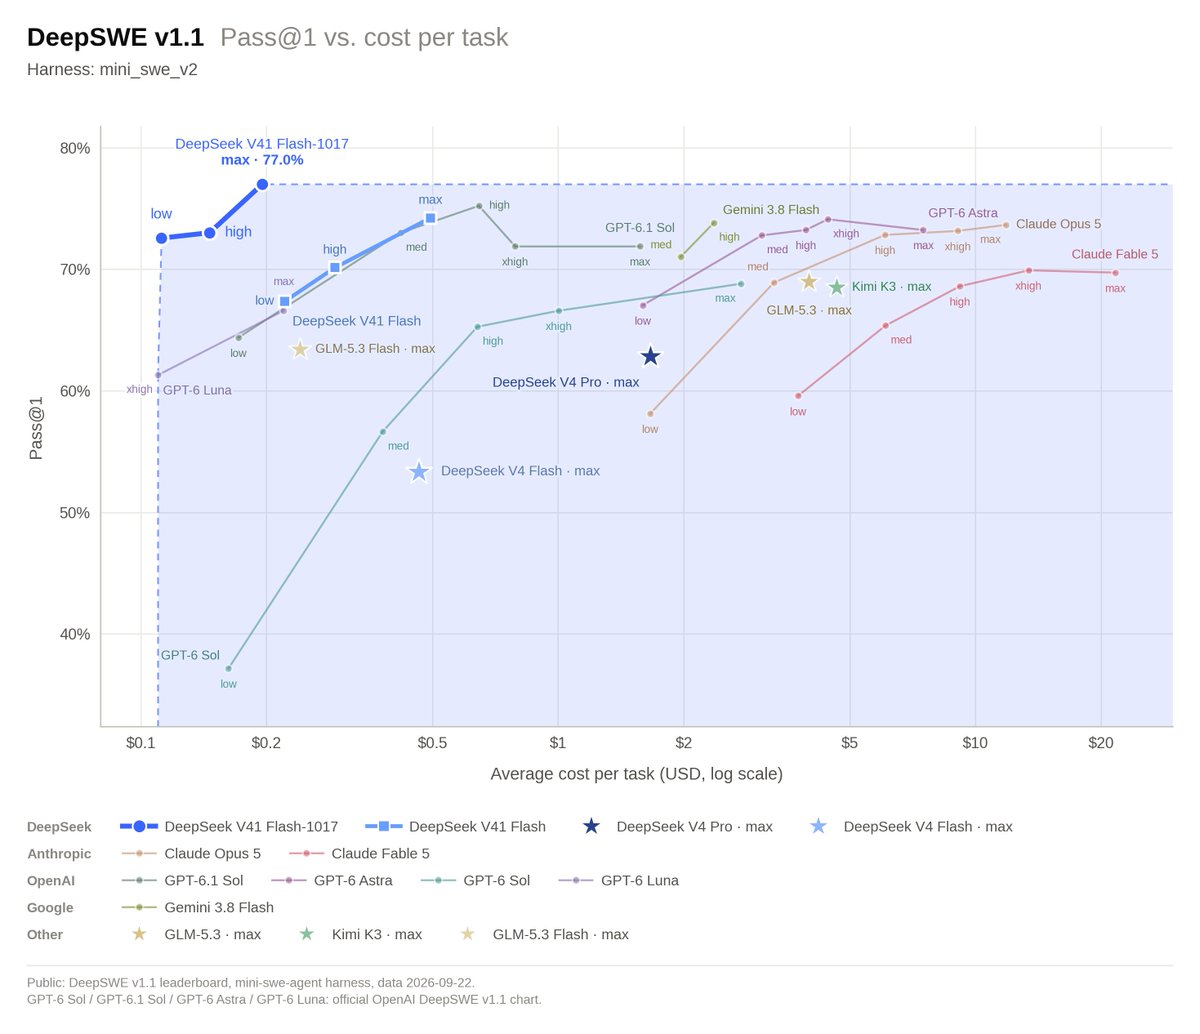
    DeepSeek V4.1-Flash-1017 can now run locally! 🐳 We made 1-bit retain ~88.2% accuracy while shrinking size from 508GB to 250GB (−52%). Run on a 128GB+ RAM device. V4.1 Flash 1017 is the strongest open model to date Guide: GGUF:
    Download
    DeepSeek @deepseek_ai
    🚀 DeepSeek-V4.1-Flash-1017 is here! Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API. 🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model. 1/4
    1252943.1K315K
  15. DeepSeek✓@deepseek_ai
    🚀 DeepSeek-V4.1-Flash-1017 is here! Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API. 🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model. 1/4
    Download
    1.6K4.1K37.2K8.1M
  16. Unsloth AI✓@UnslothAI
    You can now run and train 120B+ parameter models locally on a laptop! NVIDIA RTX Spark is here. 💚 With Unsloth and RTX Spark, train diffusion, decision, multimodal models ~2.7× faster with optimized kernels and binaries for CUDA on ARM. All local with up to 128GB unified memory
    Download
    NVIDIA RTX Spark @NVIDIARTXSpark
    NVIDIA RTX Spark is here. Build AI locally, bring your creative ideas to life, and take your favorite games along. A new beginning for @Windows PCs starts today.
    233438426.9K
  17. NVIDIA RTX Spark✓@NVIDIARTXSpark
    NVIDIA RTX Spark is here. Build AI locally, bring your creative ideas to life, and take your favorite games along. A new beginning for @Windows PCs starts today.
    Download
    49877371.1M
  18. Unsloth AI✓@UnslothAI
    Unsloth AI
    RT @helloiamleonie: how do you fine-tune a decision model on your own data? in these two notebooks, you'll learn: • how to prepare the training data • how to fine-tune our d1-3B decision model • using @UnslothAI and @huggingface TRL all within 30 minutes on a free-tier GPU. unsloth: TRL: ps: how adorable are these halloween kitties? 👻
    024201.4K
  19. Unsloth AI✓@UnslothAI
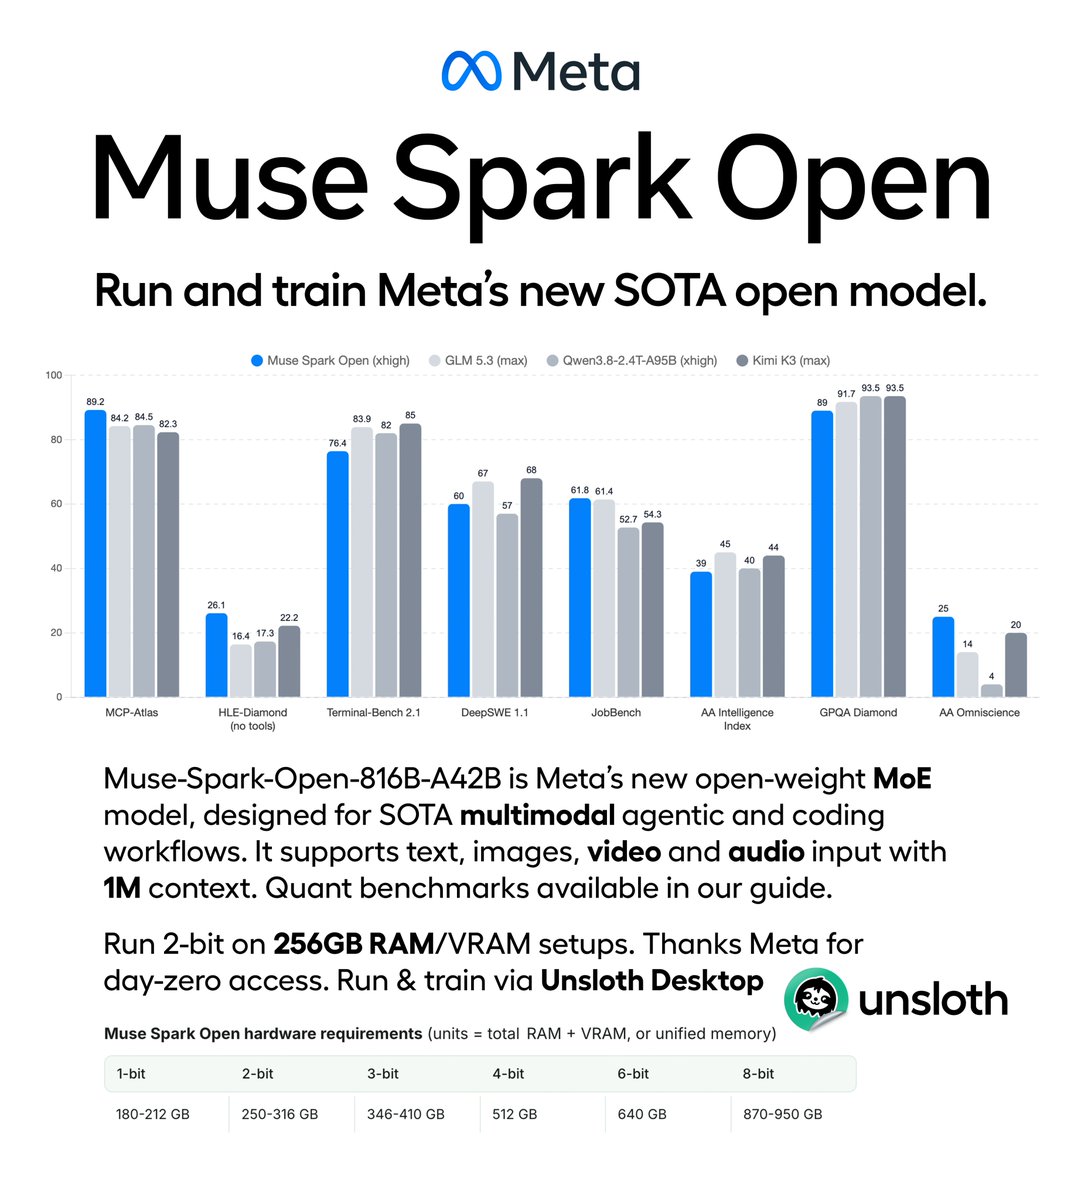
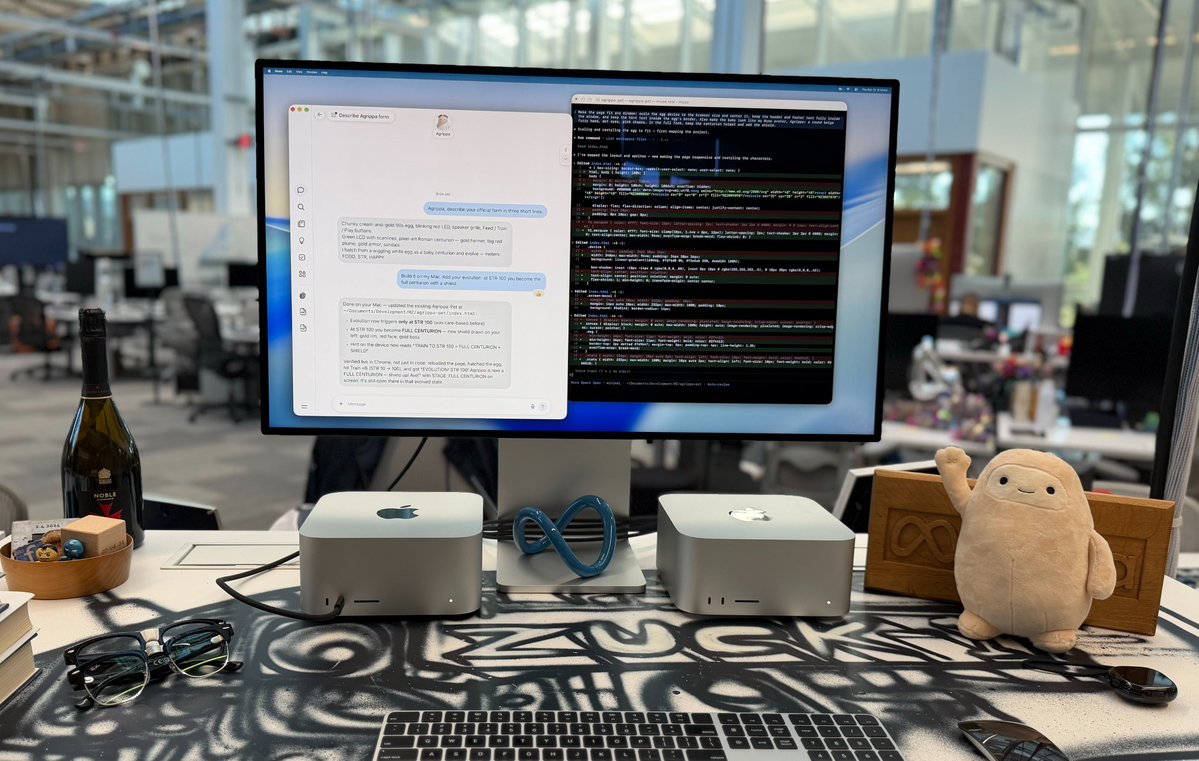
    Meta releases Muse Spark Open, a new SOTA open model. Run on a Mac Studio via Dynamic 2-bit Unsloth GGUFs. Muse-Spark-Open-816B-A42B supports text, images, video and audio input with 1M context. GGUF: Guide:
    Download
    Mark Zuckerberg @finkd
    Muse Spark Open -- weights releasing today -- runs great on new Mac Studios thanks to work with @johnternus and Apple.
    357661734.4K
  20. Mark Zuckerberg✓@finkd
    Muse Spark Open -- weights releasing today -- runs great on new Mac Studios thanks to work with @johnternus and Apple.
    Download
    1.7K1.7K32K4.9M
  21. Unsloth AI✓@UnslothAI
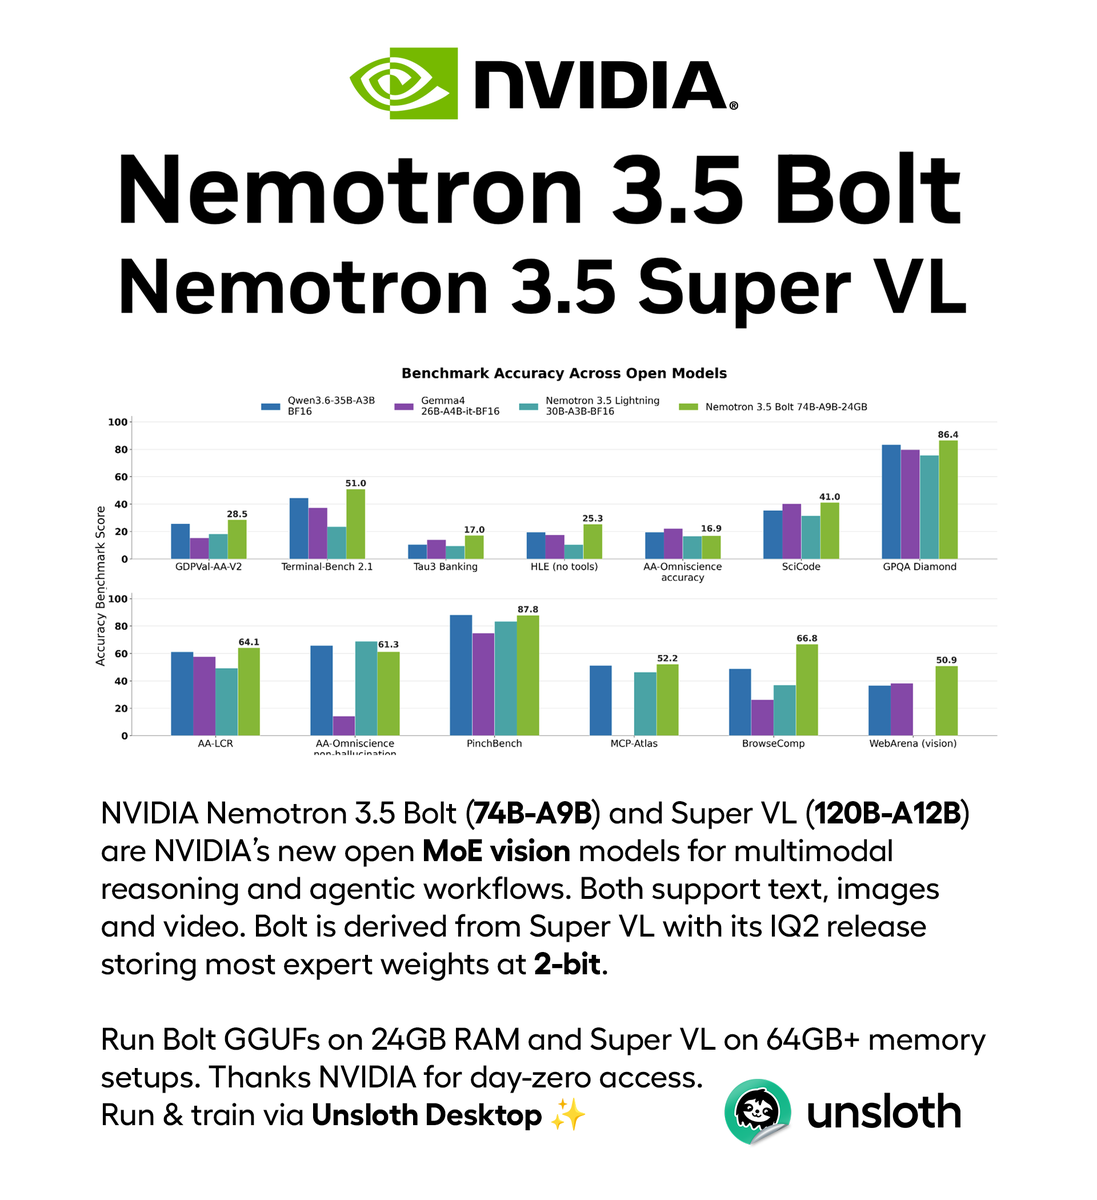
    NVIDIA releases 2 new models: Nemotron-3.5-Bolt and Nemotron-3.5-Super-VL. Nemotron-3.5-Bolt-74B-A9B runs on 24GB RAM. It delivers top-tier performance for its size. Super-VL-120B-A12B runs on 82GB RAM. Bolt GGUF: Guide: Super GGUF:
    Download
    NVIDIA AI @NVIDIAAI
    Meet NVIDIA Nemotron 3.5 Super VL Our new open model combines reasoning and tool use with text, image, document, and video understanding for long-running AI agents. 120B total parameters with 12B active 🧵
    491141K61.1K
  22. NVIDIA AI✓@NVIDIAAI
    Meet NVIDIA Nemotron 3.5 Super VL Our new open model combines reasoning and tool use with text, image, document, and video understanding for long-running AI agents. 120B total parameters with 12B active 🧵
    Download
    2905534.5K604K
  23. Unsloth AI✓@UnslothAI
    Unsloth AI
    RT @ivanfioravanti: Video: Decision model trained in ~2 mins on a single DGX Spark using Unsloth! Qwen3.5-2B as base model. Just follow instruction here:
    03401.3K
  24. Unsloth AI✓@UnslothAI
    You can now train your own Decision model with our free notebook! 💡 Qwen3.5-4B will generate decisions instead of text on just 8GB VRAM locally. Learn to data prep (state, questions, gold answers), train, serve. Notebook: Guide:
    Download
    Unsloth AI @UnslothAI
    You can now train your own Decision model like Jev locally! We increased Qwen3.5 0.8B’s aggregate accuracy from 20.7% to 74.3% across 3 decision benchmarks - on just 4GB VRAM. Turn any LLM like Qwen3.8, Gemma 4 into decision models with our open-source Unsloth repo. We fine-tuned with a Clef head using Unsloth and LoRA (r=64) for one epoch, increasing downstream accuracy from 30–37% to 78%. GitHub: Guide and Notebooks:
    1114513.8K352K
  25. Unsloth AI✓@UnslothAI
    You can now train your own Decision model like Jev locally! We increased Qwen3.5 0.8B’s aggregate accuracy from 20.7% to 74.3% across 3 decision benchmarks - on just 4GB VRAM. Turn any LLM like Qwen3.8, Gemma 4 into decision models with our open-source Unsloth repo. We fine-tuned with a Clef head using Unsloth and LoRA (r=64) for one epoch, increasing downstream accuracy from 30–37% to 78%. GitHub: Guide and Notebooks:
    Download
    1865084.2K338K
  26. Unsloth AI✓@UnslothAI
    Windows now has sandboxing! Microsoft released an open-source repo, mxc, for sandboxed code execution. We collaborated with Windows to add mxc OS level sandboxing to Unsloth which adds just <100 ms of overhead. GitHub: Guide:
    Download
    402111.6K63.9K
  27. Unsloth AI✓@UnslothAI
    Posts @UnslothAI
    With just 2.5GB VRAM, you can train your own Decision Model using small models like Laya. Training is simply done through a UI interface. Video tutorial and analysis are in our guide. GitHub repo:
    5101129.8K
  28. Unsloth AI✓@UnslothAI
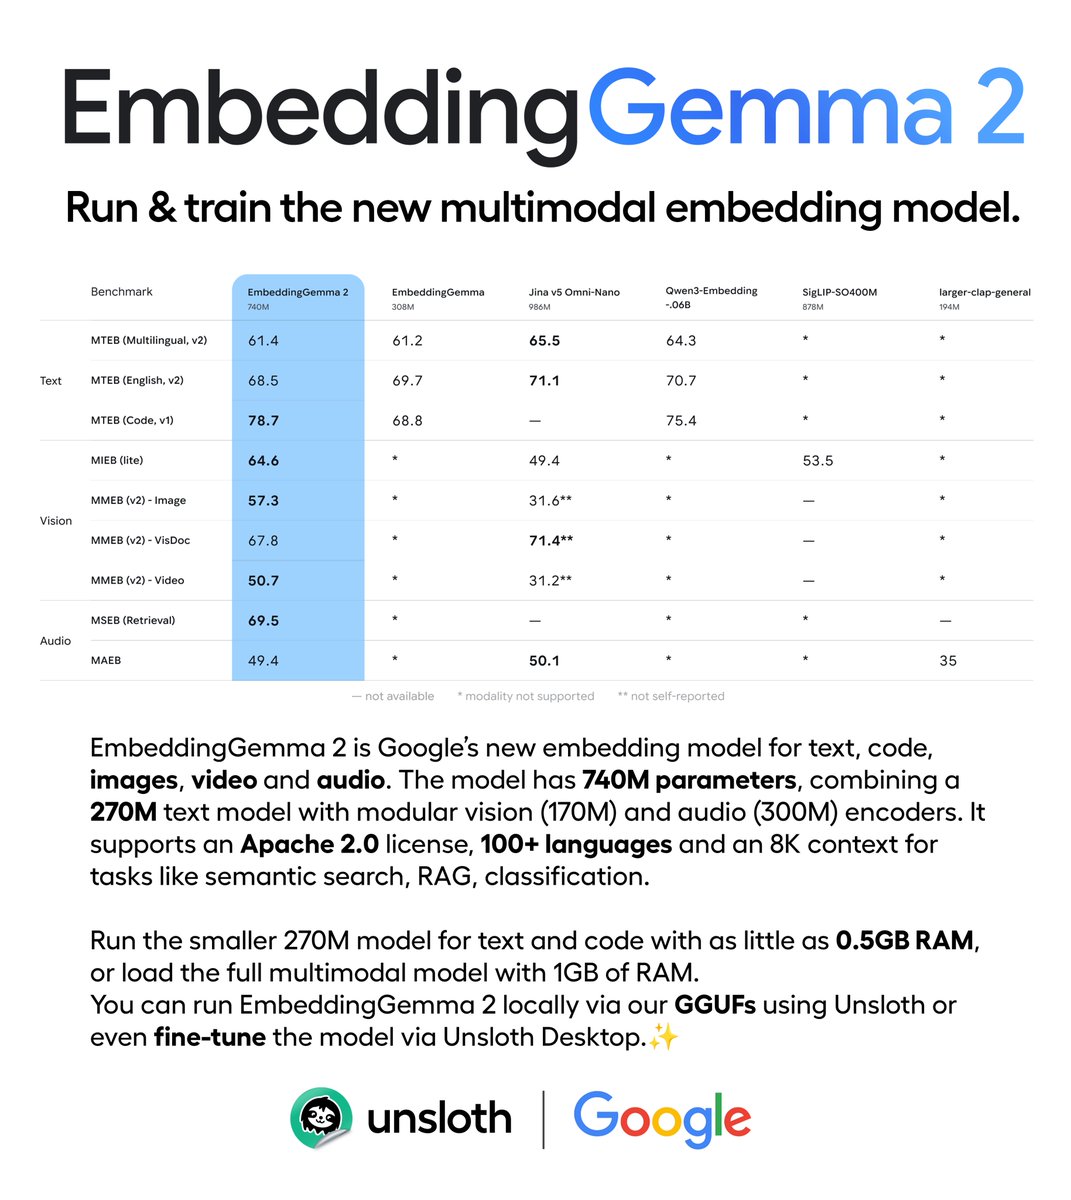
    Google releases EmbeddingGemma 2, a new open model that runs locally on 0.5GB RAM. The 740M parameter Apache 2.0 model combines a 270M text model with vision (170M) + audio (300M). Run & train the model via Unsloth. GGUF: Guide:
    Download
    Google DeepMind @GoogleDeepMind
    Meet EmbeddingGemma 2, our first natively multimodal open model for on-device embeddings. It expands beyond text to unify code, images, audio, and video in a shared space. 🧵
    794013.5K185K
  29. Google DeepMind@GoogleDeepMind
    Meet EmbeddingGemma 2, our first natively multimodal open model for on-device embeddings. It expands beyond text to unify code, images, audio, and video in a shared space. 🧵
    Download
    2925374.5K1.8M
  30. Show more posts