Fireworks✓

@FireworksAI_HQ

The frontier platform for training and inference on open-weights models at scale.

308 Following36.3K Followers1.8K Posts
  1. Fireworks✓@FireworksAI_HQ
    Today we're launching the Specialized Intelligence Index (SII): one destination for real-work benchmarks across industries, built by the teams that use them every day. Hear from Fireworks co-founder @the_bunny_chen on the importance of specialized benchmarks:
    Download
    203718563.9K
  2. Fireworks✓@FireworksAI_HQ
    Microsoft EVP @jayparikh joins us for a fireside chat at Fireworks Forge, and we have plenty of questions about building and running AI at @Microsoft's scale. For those joining at home, tune in to watch the Forge keynote live Nov 3:
    Download
    114887
  3. Fireworks✓@FireworksAI_HQ
    At Fireworks: Deploy, we’ll have three 25-minute technical sessions from each host: Fireworks, @Microsoft and @nvidia. Attendees will hear what it takes to beat a closed frontier model from companies already doing it and get mentorship all day. Register to apply with teams of 2+:
    Download
    003906
  4. Fireworks✓@FireworksAI_HQ
    The person whose GPUs your training jobs are queued on, @JensenHuang, President & CEO of @nvidia, joins us for a fireside chat at Fireworks Forge. Can't make it to Forge? Tune in to watch the keynote live here:
    Download
    03151.5K
  5. Fireworks✓@FireworksAI_HQ
    Not every task needs the most expensive model. @Tenzai_Labs's new Model Sets uses a mix of frontier and specialized open-weight models to get the job done. The team used Fireworks' serverless training API to achieve these results. Congrats to the Tenzai team on the launch.
    Tenzai @Tenzai_Labs
    NEW DROP: Match your AI model to your test, so you don't run everything on the same one and hope for the best. 🫠 The numbers speak for themselves. 71% of top-tier recall at 3% of the cost. Thrilled to partner with @FireworksAI_HQ, where open-weight models run with zero data retention, same safety guarantees as frontier. Spend on intelligence where it matters, save where it doesn’t. Details, by @anermazursky -->
    40121.9K
  6. Tenzai@Tenzai_Labs
    NEW DROP: Match your AI model to your test, so you don't run everything on the same one and hope for the best. 🫠 The numbers speak for themselves. 71% of top-tier recall at 3% of the cost. Thrilled to partner with @FireworksAI_HQ, where open-weight models run with zero data retention, same safety guarantees as frontier. Spend on intelligence where it matters, save where it doesn’t. Details, by @anermazursky -->
    Download
    14192.5K
  7. Fireworks✓@FireworksAI_HQ
    Last week you saw Deepseek vs. Claude building a Tetris game. Now, here's Deepseek vs. Astra playing @OfficialWordle.
    Sophia Yang @sophiamyang
    paying more for intelligence is overrated big shoutout to @hershyb_ for the demo!
    01424.4K
  8. Fireworks✓@FireworksAI_HQ
    LoRA can teach a 2.8T-parameter model like Kimi K3 a new skill by training under 0.2% of its weights. Why does such a tiny rank work? @juliarturc explains why, then tests it: a Qwen3.8-27B prompt router fine-tuned at r=1 vs r=16. Full video:
    12122.1K
  9. Fireworks✓@FireworksAI_HQ
    Before Fireworks, she led PyTorch at Meta. @lqiao, CEO & Co-founder of @FireworksAI_HQ, opens Forge with the keynote. Watch the keynote live Nov 3:
    Download
    14262.4K
  10. Fireworks✓@FireworksAI_HQ
    Fireworks
    RT @fal: We are excited to work together with @FireworksAI_HQ on the early-launch of EAGLE-4. Check out our technical blog to understand how EAGLE-4 works and why it matters for creative workflows:
    Eagle @EagleCorp
    EAGLE-4 is here. From EAGLE-1 to EAGLE-3, we’ve kept making inference faster. EAGLE-4 is our fastest yet. 961.6 tokens/s on @Alibaba_Qwen’s Qwen3.8-27B with TokenSpeed (BF16, 4× @NVIDIA B300, TP4, one request, T=0). Github:
    0120287
  11. Eagle@EagleCorp
    EAGLE-4 is here. From EAGLE-1 to EAGLE-3, we’ve kept making inference faster. EAGLE-4 is our fastest yet. 961.6 tokens/s on @Alibaba_Qwen’s Qwen3.8-27B with TokenSpeed (BF16, 4× @NVIDIA B300, TP4, one request, T=0). Github:
    Download
    92773611.5K5.2M
  12. Fireworks✓@FireworksAI_HQ
    Can you show that specialized open models can beat a closed frontier model? If so, you could walk away with the top prize at Fireworks: Deploy, our flagship buildathon with @Microsoft and @nvidia, Mon, Nov 2 in SF. Here's how it works: → Pick a task, build an eval → Go head to head on quality, latency or cost → Win on one axis Spots are limited, so apply now to attend here: 1 / 4 🧵
    Download
    173332.9K
  13. Fireworks✓@FireworksAI_HQ
    Specialized intelligence can outperform frontier closed models. @tryheidi’s 12-person team used Fireworks to post-train @NVIDIA Nemotron 3 Ultra. It won ~54% of clinician comparisons against the frontier model powering Heidi Evidence. Read how:
    Download
    22272.1K
  14. Fireworks✓@FireworksAI_HQ
    Posts @FireworksAI_HQ
    There are three ways to win: 1. Fine-tune a specialized model 2. Build a smarter harness 3. Route across open models Combine them if that's what it takes to win. 3 / 4 🧵
    Download
    113839
  15. Fireworks✓@FireworksAI_HQ
    How good is MiniMax M3.1 Flash? @VictorSuOrtiz (@MiniMax_AI) and Fireworks' @sophiamyang go live Oct 28 at 10 AM PT to break down what's new, what it's built for, and how to use it on Fireworks today. Set a reminder:
    1091.3K
  16. Fireworks✓@FireworksAI_HQ
    Posts @FireworksAI_HQ
    Start building Mon, Nov 2 from 10:30 AM to 4:30 PM PT with our team in San Francisco. Teams of 2+ are required and seats are limited, so apply today for your chance to show what specialized open models are capable of. 4 / 4 🧵
    Download
    011662
  17. Fireworks✓@FireworksAI_HQ
    Fireworks
    RT @sophiamyang: Train Muse Glimmer for free: Our recipe for out-betting Jev Kalshi Market
    Download
    Fireworks @FireworksAI_HQ
    We trained @Meta’s Muse Glimmer on Kalshi outcomes. One pass put it 11.2 percentage points ahead of Jev in prediction accuracy. In a backtest, it returned +7.1% to Jev’s −8.1%. Good thing the money was hypothetical. Train it for free with SFT through Nov 30. Try our recipe:
    030276
  18. Fireworks✓@FireworksAI_HQ
    Fireworks' @Prof_OZ explains how training a specialized open model is easier than you may realize. The first step involves using supervised fine-tuning (SFT) to train a behavior into the model's weights. This way, you don't have to repeat it in every prompt. → Pick one task → Pair inputs with ideal outputs → Train on Fireworks → Test on new inputs → Compare against the original Here's the full guide for you to try yourself:
    Download
    183342.4K
  19. Fireworks✓@FireworksAI_HQ
    We trained @Meta’s Muse Glimmer on Kalshi outcomes. One pass put it 11.2 percentage points ahead of Jev in prediction accuracy. In a backtest, it returned +7.1% to Jev’s −8.1%. Good thing the money was hypothetical. Train it for free with SFT through Nov 30. Try our recipe:
    Download
    588810K
  20. Fireworks✓@FireworksAI_HQ
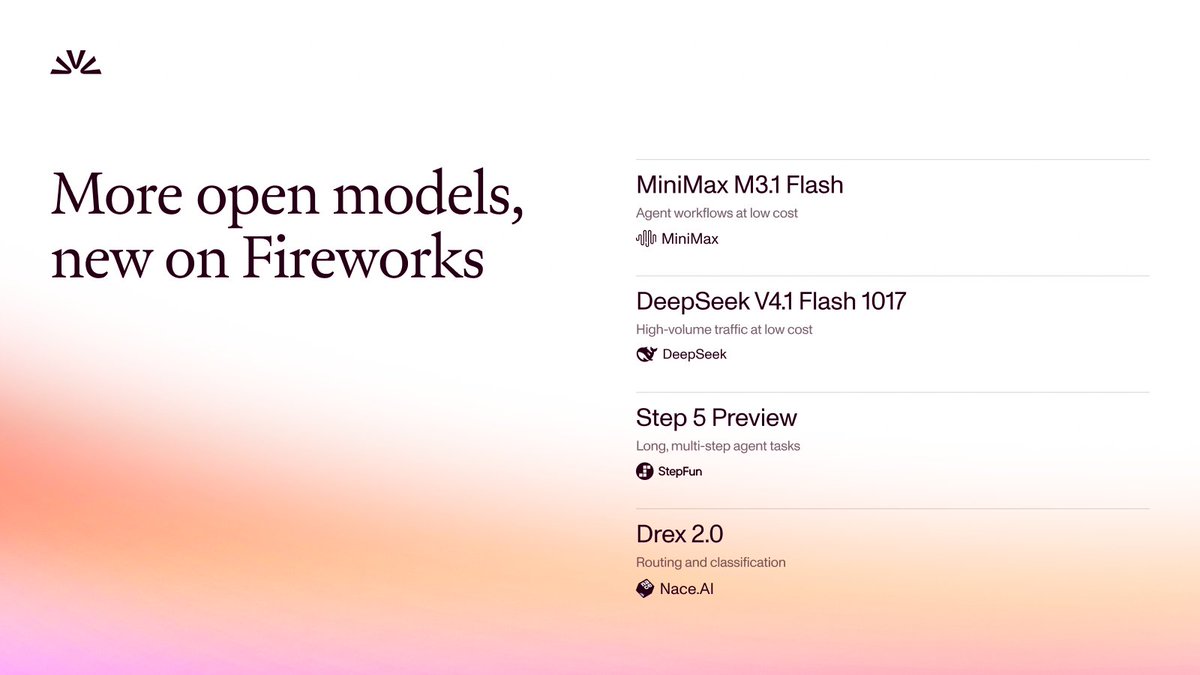
    Our team has been racing to release 7 new open models on Fireworks over the last two weeks. Each one shows how specialized intelligence is within reach for everyone. Here’s everything we released:
    Download
    64605K
  21. Fireworks✓@FireworksAI_HQ
    We have another release you don’t want to miss. @MiniMax_AI M3.1 Flash is now live on Fireworks, day 0 with the open-weights release. Built for agents that run long, multi-step work: → Cowork automation: 62.8 on AutomationBench-AA → Coding: 73.7% on DeepSWE v1.1 → Visual reasoning: 91 on BabyVision → $0.15 input / $0.60 output / $0.015 cached per 1M tokens, half the price of M3 We've heard your feedback that you want more models on serverless. So we're launching more models in preview mode, starting today with M3.1 Flash, available for two weeks. We'll be watching demand, and if the community likes it, we'll keep it around. Try it now →
    Download
    101011317K
  22. Fireworks✓@FireworksAI_HQ
    Posts @FireworksAI_HQ
    → Low-cost agents: MiniMax M3.1 Flash (@MiniMax__AI) → Low-cost volume: DeepSeek V4.1 Flash 1017, plus an Ultrafast preview for speed → Long agent tasks: Step 5 Preview (@StepFun_ai) → Routing: Drex 2.0 (@NaceAI) Want to try Ultrafast? Join the waitlist:
    Download
    208881
  23. Fireworks✓@FireworksAI_HQ
    Fireworks
    RT @ThePrimeagen: This is my dream situation. I want to be able to talk through interfaces, changes, ideas, consequences and think through things. I get so derailed asking a question and coming back in 5 minutes
    Fireworks @FireworksAI_HQ
    DeepSeek V4.1 Flash 1017 runs at 1,521+ tok/s on Fireworks Ultrafast. Fast enough to ship Tetris in 11 seconds, 7x faster than Claude Opus 5.5. Join the Ultrafast waitlist:
    0500269
  24. Fireworks✓@FireworksAI_HQ
    Posts @FireworksAI_HQ
    The standout: @AIatMeta's Muse Spark Open beat Claude Opus 5 on Rogo’s Big Finance Benchmark in our Specialized Intelligence Index, at about a fifth of the cost per task. Try them now:
    Download
    002620
  25. Fireworks✓@FireworksAI_HQ
    DeepSeek V4.1 Flash 1017 runs at 1,521+ tok/s on Fireworks Ultrafast. Fast enough to ship Tetris in 11 seconds, 7x faster than Claude Opus 5.5. Join the Ultrafast waitlist:
    Download
    1903715.6K1M
  26. Fireworks✓@FireworksAI_HQ
    Specializing @Kimi_Moonshot K3 for your own tasks takes fast iteration and stable training. Our new research explains how Fireworks optimizes training, rollouts, and weight updates together to make reinforcement learning practical at 2.8T parameters. 1/3 🧵
    Download
    48487.2K
  27. Fireworks✓@FireworksAI_HQ
    We choose @nvidia's full-stack platform because we believe Vera Rubin and OpenShell together offer the best holistic approach to agentic security. Read more:
    Download
    03262.8K
  28. Fireworks✓@FireworksAI_HQ
    Posts @FireworksAI_HQ
    A few measured results: Our MoE Mega Kernel delivers up to 2.61× faster routed-expert forward passes vs. optimized DeepEPv2. Coordinated caching reuses ~99% of prompt tokens in our long-context, multi-turn rollout benchmarks, reducing repeated prompt processing. 2/3 🧵
    1191.2K
  29. Fireworks✓@FireworksAI_HQ
    Posts @FireworksAI_HQ
    You can test your own tasks and reward functions on @Kimi_Moonshot K3 with serverless training through the Fireworks Training API: shared training and rollout capacity, no dedicated GPUs to provision. Full write-up: 3/3 🧵
    015672