The MIT CSAIL Weight-Space Programming draft is ready as a full e1 on their blog. It's 250 words plus the Blog line, scores 88.9 and passes the gate.
MIT CSAIL researchers just found GPT-6 Astra can fix a small model by directly editing 0.016% of its weights, lifting MATH-500 from 7.9% to 48.1%.
No gradients. No training loop.
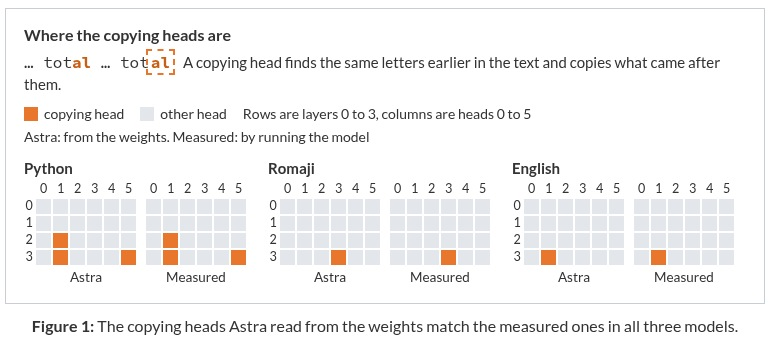
They call it Weight-Space Programming. A frontier LLM reads a network's raw weights and rewrites them around a plain-language goal.
They started small. Given the raw weights of four game-playing networks, 17,253 each and with no game names offered, Astra named the right game for all four.
-> It fixed a stuck car-driving policy by editing 3.5% of its weights in one reply, going from 0% to success in all 1,024 episodes
-> It wrote Breakout, Seaquest and Asterix networks from all-zero weights, with no tools and no gameplay, and beat PPO trained for 100M steps in all three
-> On Qwen3.5-0.8B, it traced reasoning loops to one direction written by two MLP layers and subtracted it from 131,072 weights
That same fix lifted GSM8K from 13.8% to 67.1% and IFEval from 21.0% to 62.3%.
The catch is in their own results. The big jump needed 50 forward passes, while with 10 or 25 the loops barely went away. On Gemma 3 270M, which rarely loops, no edit helped by more than about a point. And from weights alone, Astra couldn't tell which of two models was sycophantic.
As the authors put it, editing "could remove an obstacle that hid an ability, but it could not add an ability the model lacked."
The next optimizer might be a model that reads the weights.

1017