Sumedh Tech Journal@Iam_boron
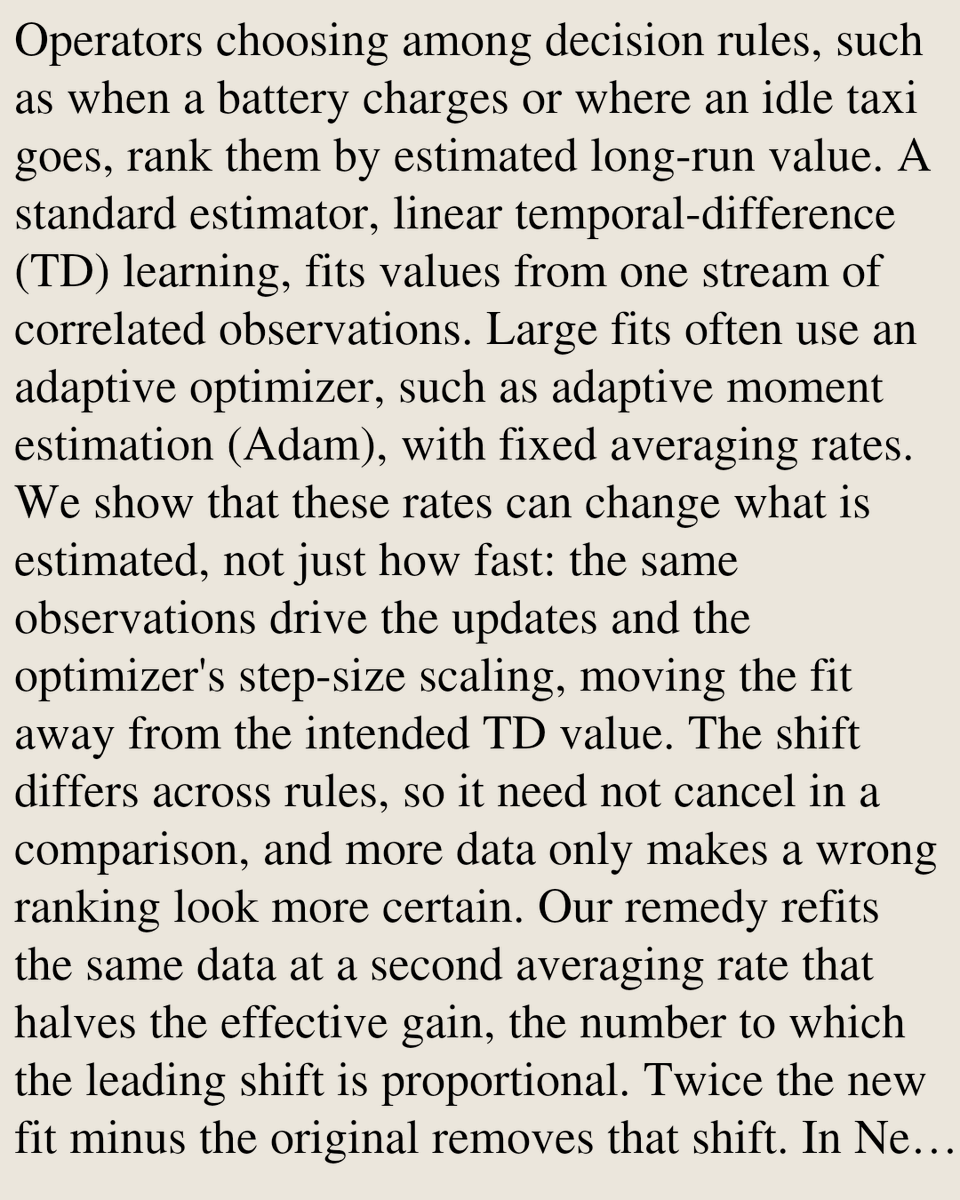
Started optimizers. Vanilla gradient descent struggles with picking the right learning rate, predefined schedules that can’t adapt to the data, one learning rate for every parameter, and saddle points where the gradient vanishes. Momentum, RMSprop and Adam each fix a piece.
0011