Jina AI
@JinaAI_
Your Search Foundation, Supercharged! (acquired by @elastic Oct. 2025)
1 Following17.9K Followers2.3K Posts
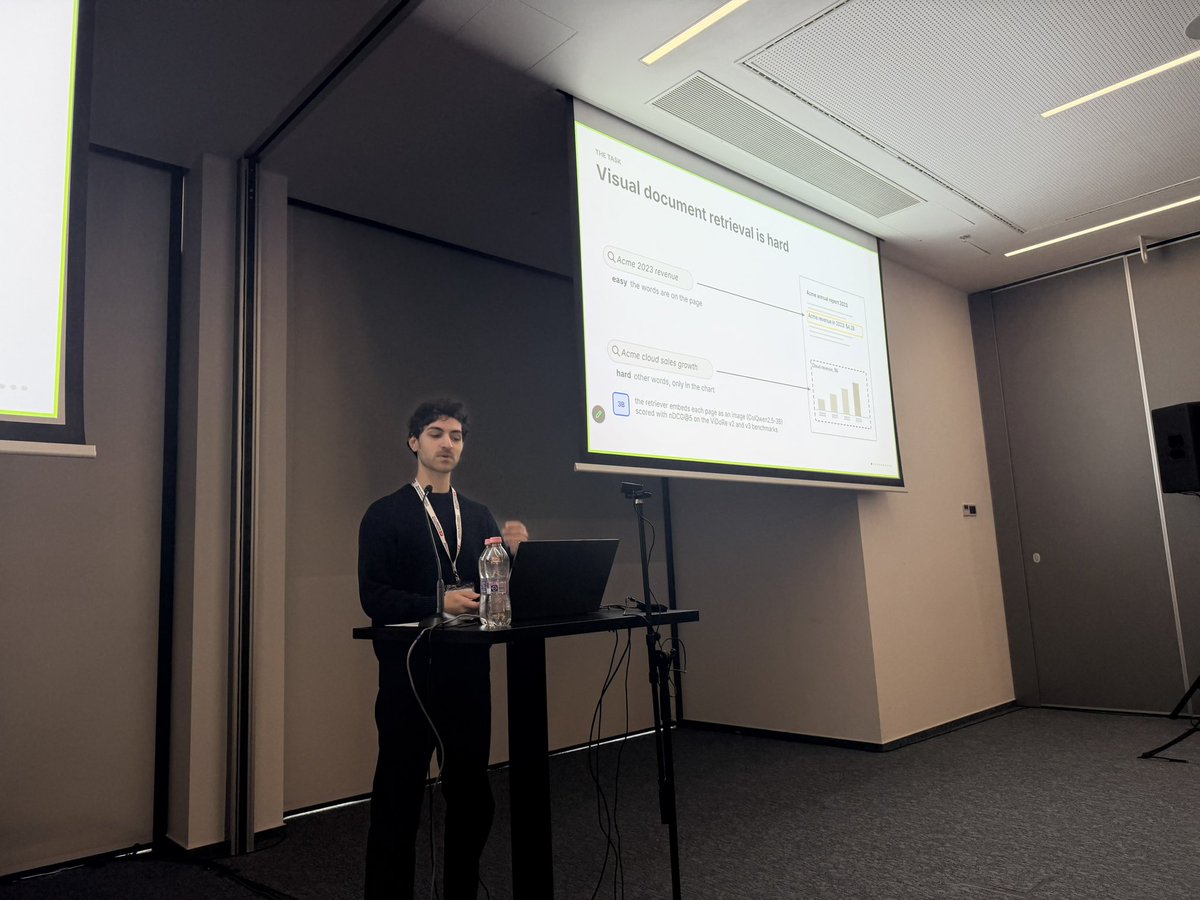
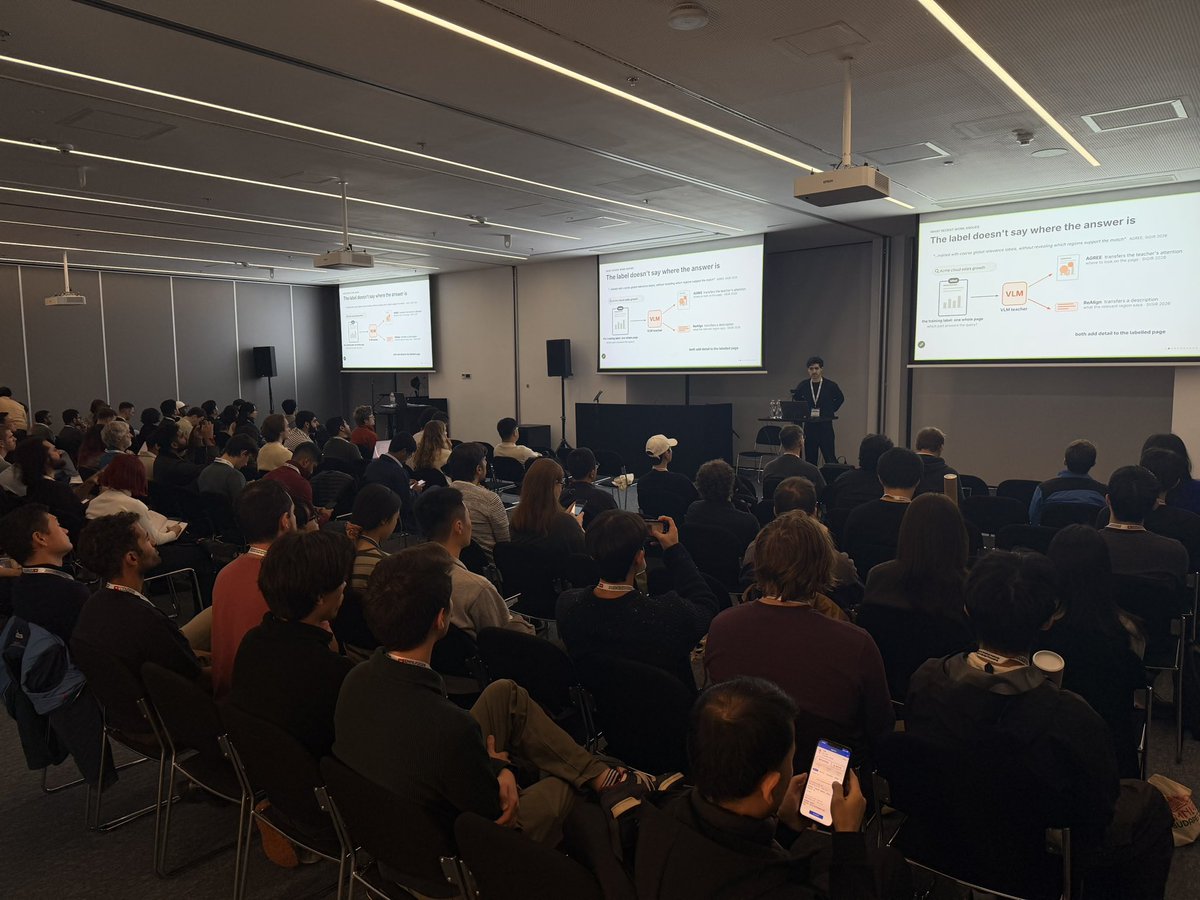
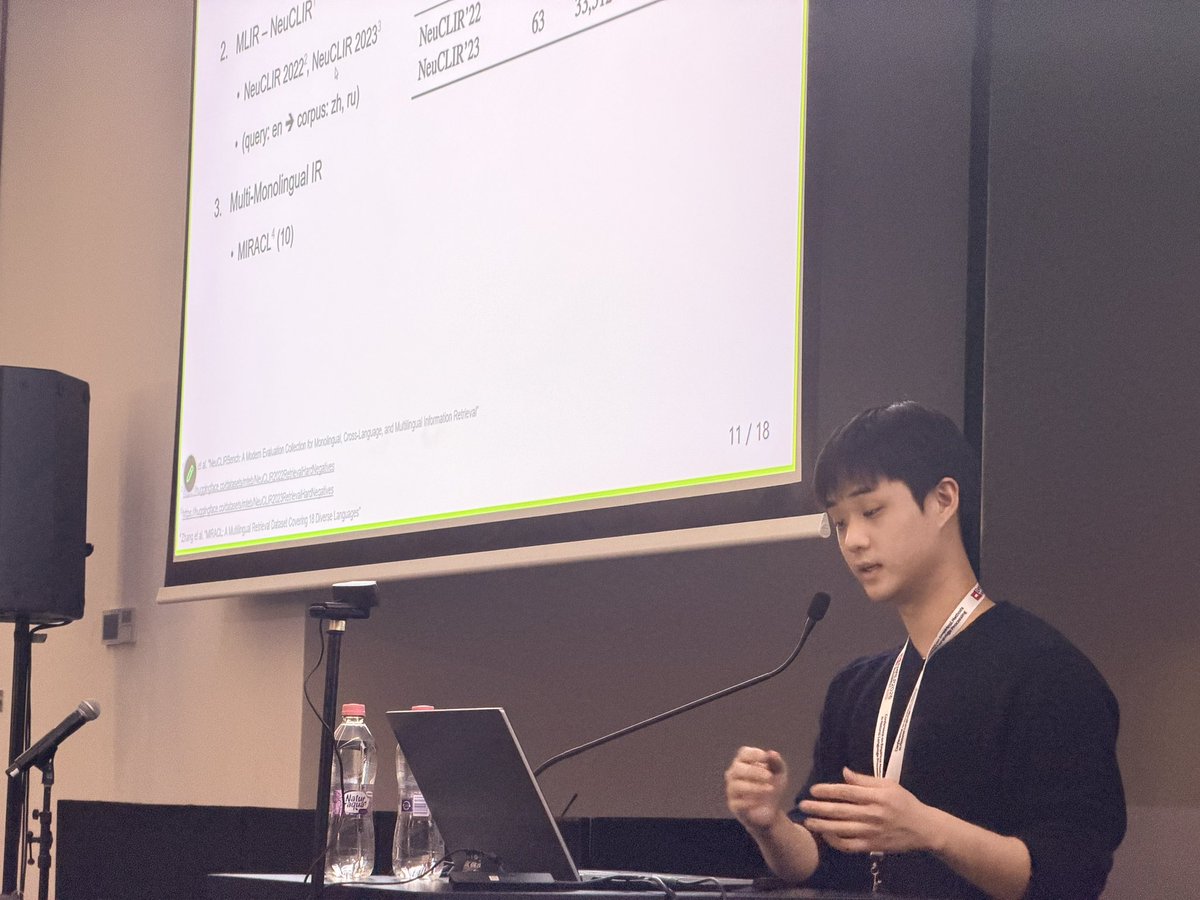
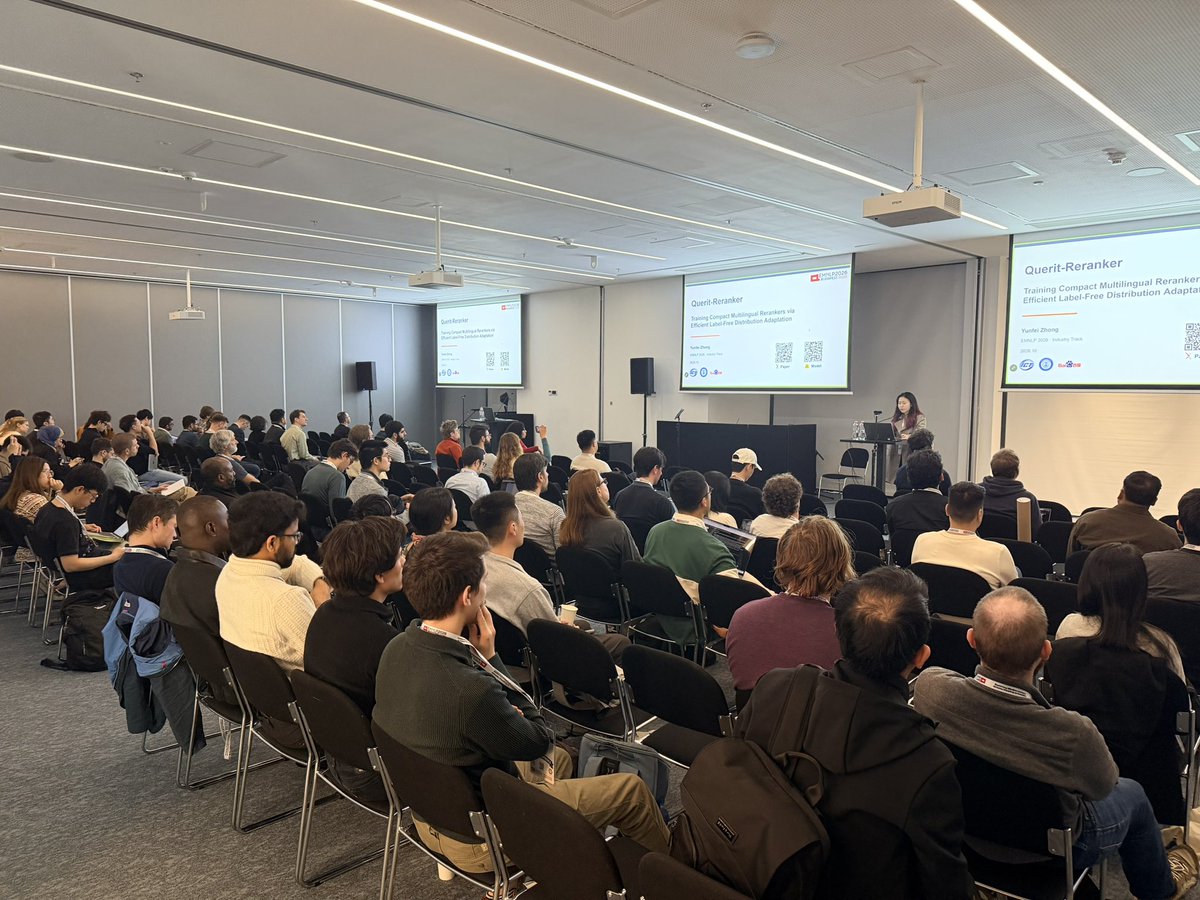
- Jina AI@JinaAI_We are hosting the 4th BoF on embeddings, rerankers & small language models for search at EMNLP2026 in Budapest. We welcome talks on Jev-like decision models this year. Submit your work here:21203.7K
- Jina AI@JinaAI_Posts @JinaAI_- Date: Sunday, October 25, 2026 - Time: 11:00 to 12:30, Budapest time (CET) - Location: Room G9-10 & G11, Gallery floor, HUNGEXPO Congress Centre, Budapest - Format: in-person, 10-minute lightning talks followed by open discussion Walk-in attendance is super welcome.001477
- Jina AI@JinaAI_Jina AIRT @hxiao: Introducing omni-macos: a semantic Finder for Apple Silicon. It was first released months ago, but now getting really good and becoming my daily productivity. Over the last few months I've kept improving fully local, on-device semantic search for my everyday agentic use. The goal: a local multimodal search engine that's easy for both humans and agents, fast, and handles CRUD in real time. After years of working on embedding and reranker models, I figured this would be easy, especially with coding agents hill-climbing tps for you. Turns out making it actually good is pretty damn hard. I've also seen other projects like zvec-grep going after the same thing, but I think most of them miss some key points about local search, especially on personal devices. They optimize for efficiency and relevance, which is fair with a SaaS mindset, but not enough for an air-gapped personal device: - Efficiency matters, but on a laptop, an indexer that hogs the machine to finish sooner is worse than one that takes a bit longer and you never notice. - Personal files are massively duplicated: v1, v2, v-final, v-final-final, plus backups, often with only tiny diffs between them. So using the file as the indexing unit is inefficient. - Some files get edited all the time, but only a small part changes each time. Reindexing the whole file is, again, a waste. - CRUD needs to be handled properly at the folder level. - You only have one GPU interface and it's non-preemptive. Embedding needs it, vector search needs it, OCR needs it. You can't lower the priority of work that's already queued, so priority can only be set at admission.030122
- Jina AI@JinaAI_Announcing jina-ocr-v1, our new visual document parser with 3.4B total parameters and 570M active parameters, with speculative decoding built in. Throw PDFs, scans, tables, charts, or invoices at it and get clean markdown back. Available on 🤗 & Jina Reader `x-respond-with` today461181.5K158K
- Jina AI@JinaAI_Posts @JinaAI_Post-trained on DeepSeek-OCR, we strengthened multilingual support across 25 languages and optimized it for low-budget GPUs such as the nvidia L4. jina-ocr-v1 scores 91.14 on OmniDocBench v1.6 and 83.4 on olmOCR-Bench, and hits the highest page throughput among all competitors.
 23487.3K
- Jina AI@JinaAI_Posts @JinaAI_Learn more about jina-ocr-v1 and use it today, and let us know what you think! - huggingface: - tech report: - blog:28615.6K
- Jina AI@JinaAI_Pareto front or ngmi. Releasing jina-reranker-v3.5: our latest 0.6B listwise reranker that takes v3's last-but-not-late interaction, makes it faster, and makes it actually good at the data enterprises search. 63.20 nDCG@10 on BEIR, beating Qwen3-Reranker-4B at ~7× fewer params.25397.8K
- Jina AI@JinaAI_jina-embeddings-v5-omni is here! Our first universal embedding model for text, images, audio, and video. Available in two sizes: small (1.57B, 1024-dim, 32K context) and nano (0.95B, 768-dim, 8K context). Both support Matryoshka truncation down to 32 dimensions. v5-omni is back-compatible: if you already use jina-embeddings-v5-text-small/nano, the existing text indexes work with v5-omni out of the box. Without reindexing the text, just index your multimodal content with v5-omni and start searching images, audio, and video.1391588137K
- Jina AI@JinaAI_Posts @JinaAI_v5-omni keeps the v5-text backbone completely frozen and adds pretrained vision and audio encoders connected through small trainable projectors: - Vision: Qwen3.5 vision encoders with 2x2 spatial merge. We freeze everything except the final projection layer (fc_vision_2), which we replace with a randomly initialized layer mapping into the text backbone's hidden dimension. - Audio: Qwen2.5-Omni encoder. A single randomly initialized fc_audio layer projects the 1280-dimensional output into the text backbone. - Video: Handled as a sequence of visual frames, optionally preceded by an extracted audio segment.
 21123.9K
- Jina AI@JinaAI_Posts @JinaAI_Today v5-omni is available on Elastic Inference Service, HuggingFace and Jina API. Learn more about v5-omni from links below. 🤗: arXiv: blog:07253.1K
- Jina AI@JinaAI_Posts @JinaAI_v5-text uses decoder-only backbones with last-token pooling instead of mean pooling. Four lightweight LoRA adapters are injected at each transformer layer, handling retrieval, text-matching, classification, and clustering independently. Users select the appropriate adapter at inference time. For retrieval, queries get a "Query:" prefix and documents get "Document:". Context length is 32K tokens, a 4x increase over v3.
 10193.4K
- Jina AI@JinaAI_Posts @JinaAI_The trend toward smaller embeddings is a shift. On-device retrieval, browser-based search, and edge deployment all demand models that fit in constrained memory budgets. Learn more about Small & Nano below: - blog post: - 🤗 weights including GGUFs and MLX: - arXiv:12162.4K
- Show more posts