ScitiX✓

@scitix

Shaping the Future with Intelligent Computing!

89 Following69 Followers251 Posts
  1. ScitiX✓@scitix
    Boson AI's flagship speech models are now live on ScitiX Model Inference. bosonai/tts for expressive, conversational text-to-speech, and bosonai/asr for accurate multilingual transcription — a complete voice loop behind one OpenAI-compatible API. Listening and speaking, on infrastructure built to be simple, fast, and secure.
    Download
    112458.9K
  2. ScitiX✓@scitix
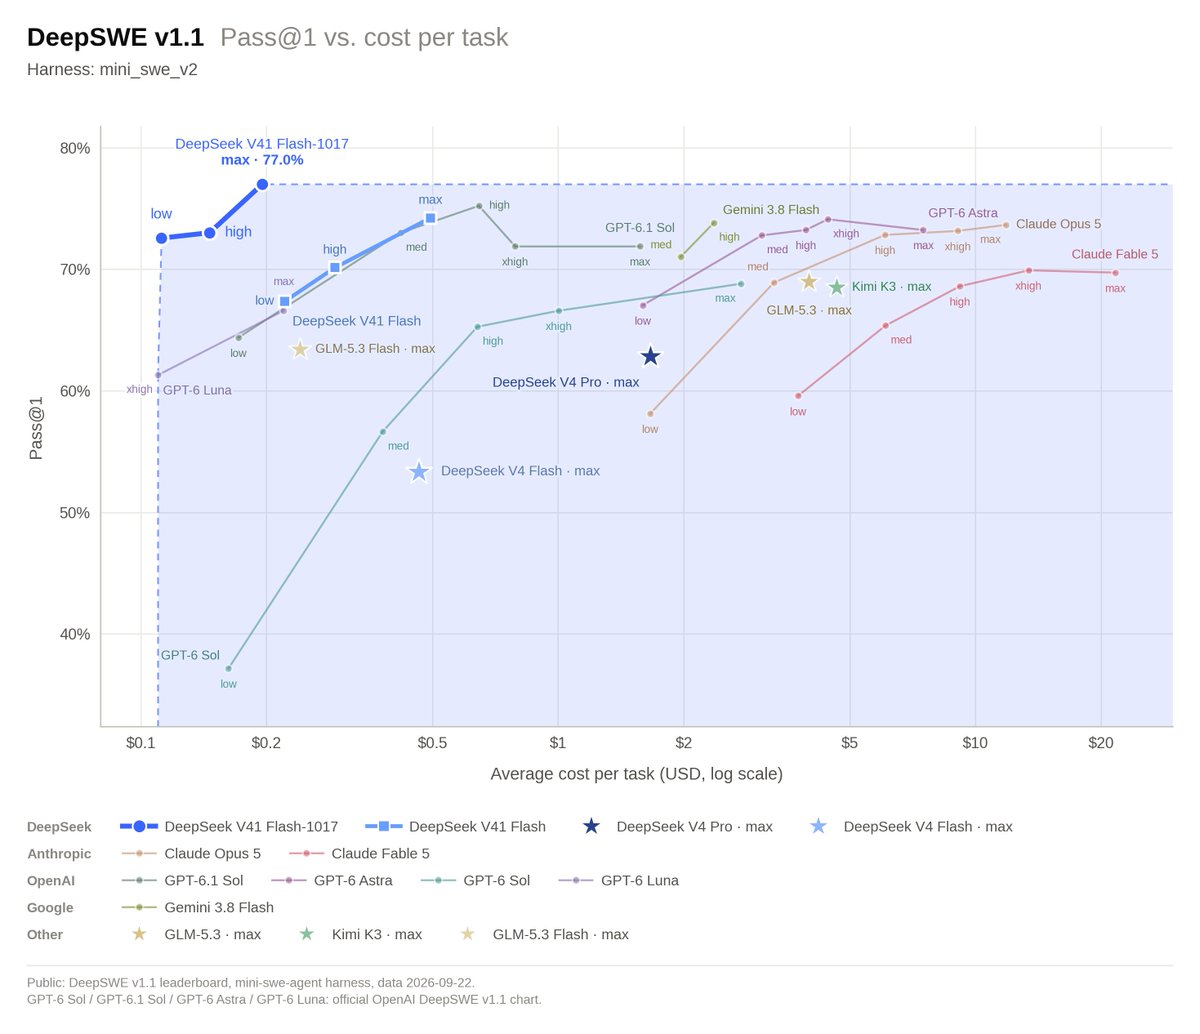
    DeepSeek-V4.1-Flash-1017 is now available on ScitiX. PD-separated serving for stable latency under concurrent load. One endpoint alongside GLM, Qwen, Kimi, MiniMax, and 20+ other models — your architecture stays the same when model requirements change. Zero data retention. 99.9% uptime. T+3 availability.
    Download
    DeepSeek @deepseek_ai
    🚀 DeepSeek-V4.1-Flash-1017 is here! Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API. 🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model. 1/4
    00279
  3. DeepSeek✓@deepseek_ai
    🚀 DeepSeek-V4.1-Flash-1017 is here! Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API. 🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model. 1/4
    Download
    1.6K4.1K37.2K8.1M
  4. ScitiX✓@scitix
    Live cluster monitoring, updated in real time. Active jobs, GPU utilization, token throughput, node-level breakdowns, job logs, inference throughput curves—all moving as your workload runs. Not a snapshot. Not a 30-second refresh. Live. Four commands from install to this dashboard. pip install scitix-cli and you're in. →
    Download
    00017
  5. ScitiX✓@scitix
    Your AI infra expert, inside Slack, Teams, and your API. Check GPU utilization. Pull price quotes. Set alerts. Trigger autoscale. Troubleshoot a failing job. Manage billing. All without leaving your workspace—natural language or code, whichever fits the moment. No tickets. No portal. Just ask. Connect your workspace:
    Download
    00016
  6. ScitiX✓@scitix
    Different tasks need different models. ScitiX Model Advisor shows you why. Complex Reasoning → GLM-5 (744B MoE, long-horizon agentic tasks) Low-Latency RAG → gpt-oss-20b (18ms TTFT, fastest open-weight option) Code, Batch, Vision, Agents & more—describe your use case, get a recommendation with reasoning attached.
    Download
    00166
  7. ScitiX✓@scitix
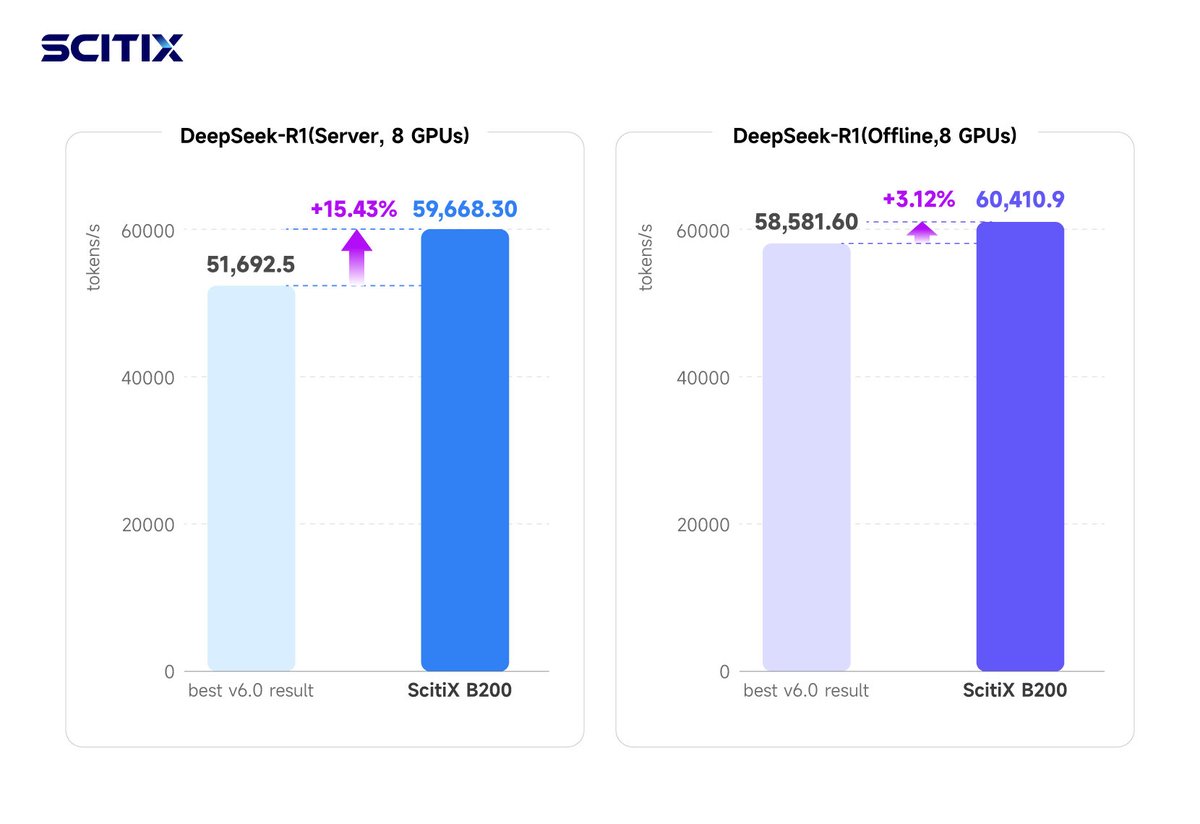
    In MLPerf Inference v6.1, ScitiX recorded 59,668 tok/s Server and 60,410 tok/s Offline for DeepSeek-R1 on 8×SZ002-SXM-180GB. Same hardware, same model—but two different optimization problems. Offline maximizes steady-state throughput with no latency constraint. Server has to protect TTFT and TPOT p99 under continuous request arrival. The scheduler parameters that maximize one can break the other. We tuned them separately. If you're running inference at this scale, that distinction matters more than the headline number.
    Download
    10175
  8. ScitiX✓@scitix
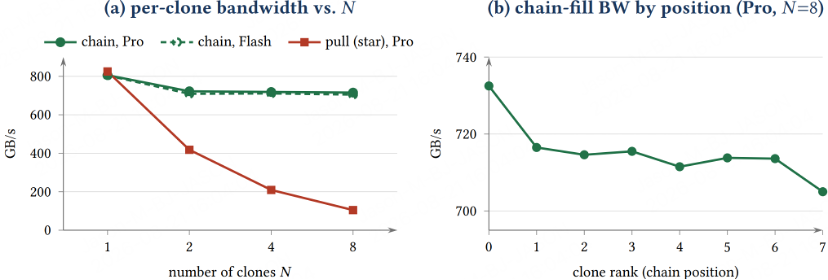
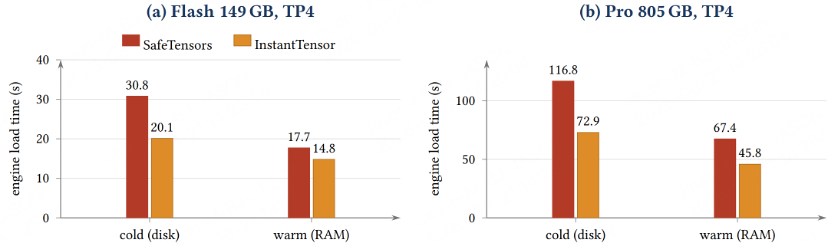
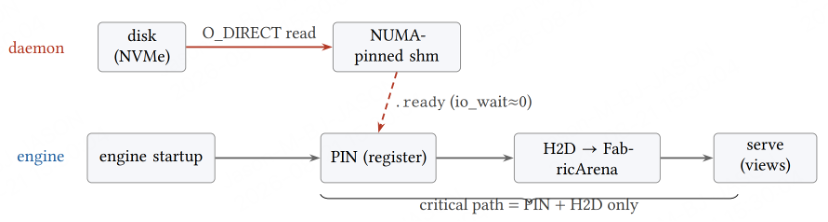
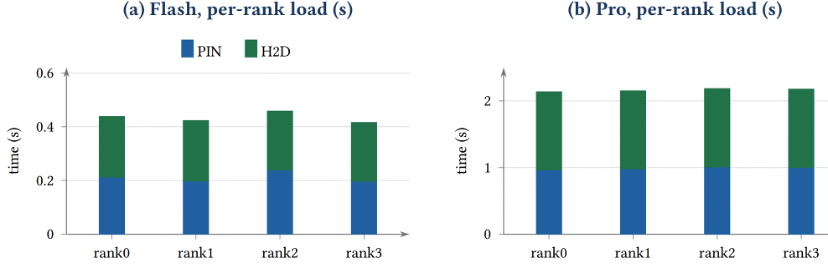
    Weight movement isn’t solved for trillion-scale models. FlashBoot turns layout, transfer, and replication into one data path—at the bandwidth ceiling. NVL72 · DeepSeek-V4-Pro · TP=4 Load: 20.1s → 0.40s (50× vs InstantTensor) 8 replicas: 87s → 0.32s (270×+ vs SGLang R-Fork)
    Download
    709750
  9. ScitiX✓@scitix
    Posts @scitix
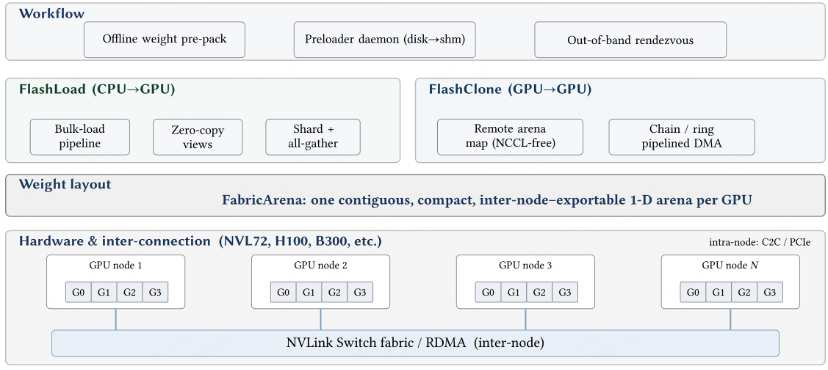
    FlashBoot co-designs layout, transfer, and replication as one data path—and drives each to hardware limits. Not NVL72-specific: covers C2C/PCIe and NVLink/RDMA, validated on GLM-5.2, DeepSeek-V4, and Kimi-K3. Trillion-parameter elasticity starts here.
    00034
  10. ScitiX✓@scitix
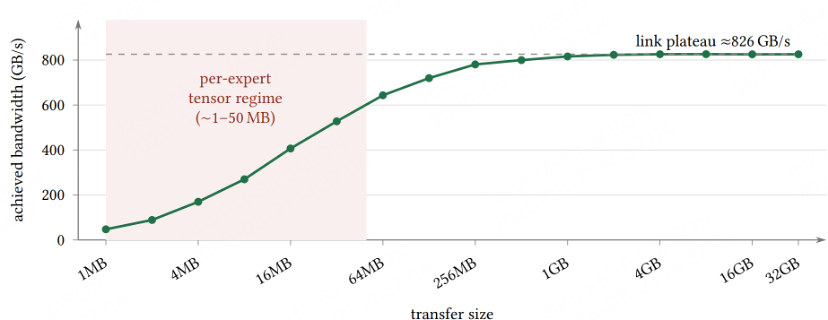
    FlashBoot: At measured C2C bandwidth, 217 GB of DeepSeek-V4-Pro weights should transfer in ~1.2s. Baseline loaders took 45–67s—using 3% of available bandwidth.
    Download
    10072
  11. ScitiX✓@scitix
    Posts @scitix
    FlashLoad pipelines host→GPU transfer with zero-copy placement, built on FabricArena's single-IO layout. On NVL72: single-node loading 20.1s → 0.40s, up to 50× faster.
    Download
    00144
  12. ScitiX✓@scitix
    LPerf Inference v6.1 results are live. @mlcommons ScitiX delivered 59,668.30 output tokens/s for DeepSeek-R1 Server (Open) on one 8× SZ002-SXM-180GB system—the record-breaking result in its category and 15.43% above the best v6.0 comparison result.
    20273
  13. ScitiX✓@scitix
    Posts @scitix
    Behind these results: a corrected evaluation path, joint tuning of speculative decoding, memory and scheduling, and full-load validation. Our goal was not a short-test peak, but sustainable serving performance within quality and latency constraints. #ModelInference #AIInfra
    00017
  14. ScitiX✓@scitix
    Posts @scitix
    This was not unconstrained peak throughput. The Server run remained within the applicable latency limits, with p99 TTFT of 1.719s and p99 TPOT of 70.43ms. The same system also reached 60,410.90 output tokens/s in DeepSeek-R1 Offline (Closed), 3.12% above v6.0.
    00147
  15. ScitiX✓@scitix
    DeepSeek-V4-Pro has 20K+ weight tensors, most 1–50 MB each. Sending them individually leaves C2C and NVLink nowhere near saturated. FabricArena lays tensors in a virtually contiguous, cross-node-addressable GPU-memory region. Tens of thousands of transfers collapse into one.
    Download
    10070
  16. ScitiX✓@scitix
    Posts @scitix
    Full write-up →
    00029
  17. ScitiX✓@scitix
    8 nodes, each 217 GB, loaded concurrently in 0.32s. That's not a typo. FlashBoot is a hardware–software co-designed weight-loading subsystem for NVLink/RDMA systems, built on SGLang.
    Download
    10032
  18. ScitiX✓@scitix
    Posts @scitix
    On NVL72 with DeepSeek-V4-Pro and DeepSeek-V4-Flash (TP=4): single-node loading up to 50× faster, 8-clone replication >270× faster. Full write-up → SGLang integration →
    00186
  19. ScitiX✓@scitix
    We made our inference stack faster — under the hood. sglang L3 read batch: 128 → 512. Mooncake load balancing added for SSD saturation. Together: 1M-context full SSD reads 30%+ faster at peak. Validated before ship: 80 GPUs, GLM5.2 PD disaggregated, 24 hours continuous — 99.4% warm KV cache hit rate, L3 success rate 100%, zero L3 timeouts. Small tuning. Meaningful at scale.
    10045
  20. ScitiX✓@scitix
    Posts @scitix
    Fast inference is one thing. Consistent fast inference is another. prefetch_threshold tuned from 256 → 64 — warm L3 hit rate up 1%+. Real-time cache hit rate monitoring now live. More on how we build →
    00034
  21. ScitiX✓@scitix
    Something we keep running into with agent inference: the tool-call idle window. Local tools (file I/O, shell) come back in milliseconds. Remote tools (search, APIs) can take 10+ seconds. And during that wait? GPU's just sitting there. KV cache too — fully loaded in HBM, doing absolutely nothing. So at @Scitix we've been playing with agent-aware KV eviction: · Kick the KV out while the tool call is still running, pull it back right before the result comes in. · Turns dead time into free memory. No latency cost to the user. · Chat serving never had to deal with this. Agents do. Still early, but there's clearly more here.
    10277
  22. ScitiX✓@scitix
    Fast models still feel slow when the infrastructure isn't right. What we obsess over at ScitiX: — 1s average TTFT — 93.9% KV-cache hit rate — 99.9% uptime — 72% average cost savings Built on ScitiX's own GPU clusters with session-aware orchestration and 3-tier failover. This is what production inference should feel like. Get Started →
    Download
    1108123
  23. Show more posts