BackboardIO
RT @RobImbeault: What happens when the workload keeps coming?
In our GLM 5.3 sustained test at 32 concurrent users:
@BackboardIO: 370 output tokens/sec
vLLM: 74.9
4.94X aggregate output throughput.
Full model. No Quant!
0301

@BackboardIO
inference. pre-training. post-training. quant.


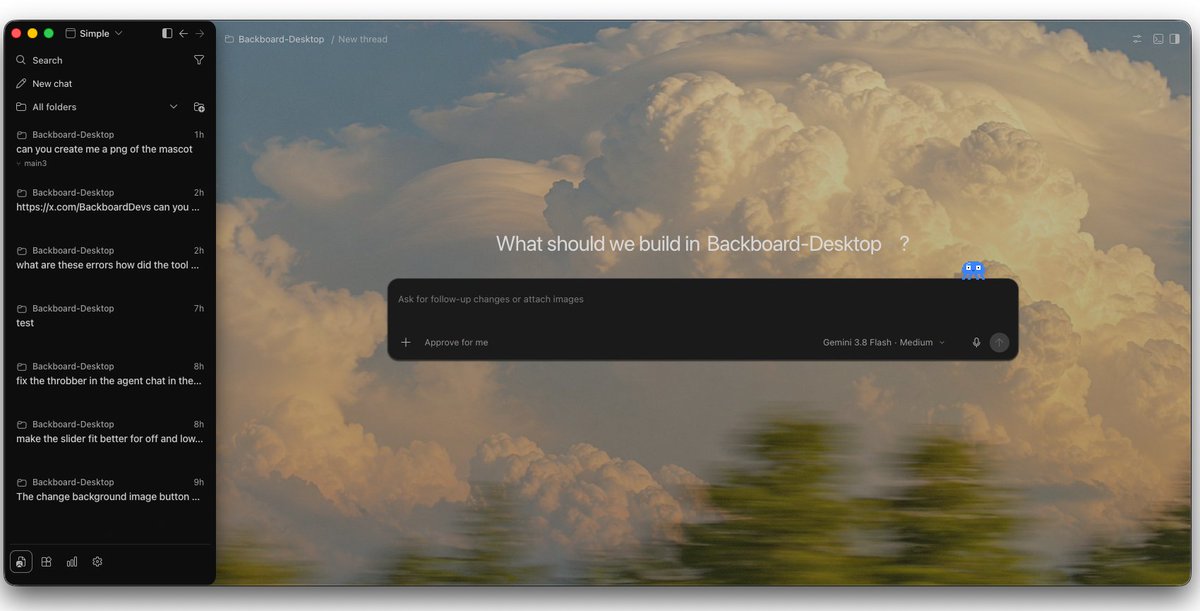
a16z @a16zastra waiting to get added to the model selector dropdown


Google @GoogleIntroducing Gemini 3.8, our best reasoning & coding model yet. By leveraging long-running agentic loops, we’re building on the momentum of 3.7 Flash from just three weeks ago to release two new 3.8 variants: Meet Gemini 3.8 Flash and Gemini 3.8 Flash Cyber 🧵