Pit Neitemeier✓

@PitNeitemeier

pre-training @Aleph__Alpha

  • Joined
369 Following314 Followers62 Posts
  1. Pit Neitemeier✓@PitNeitemeier
    We’re so back! The calls to train models in Europe again were getting louder and louder and we worked incredibly hard to make this happen. It was a pleasure to build these teams from the ground up! Now off to do some euromaxxing. Looking forward to everyone trying the model!
    Aleph Alpha @Aleph__Alpha
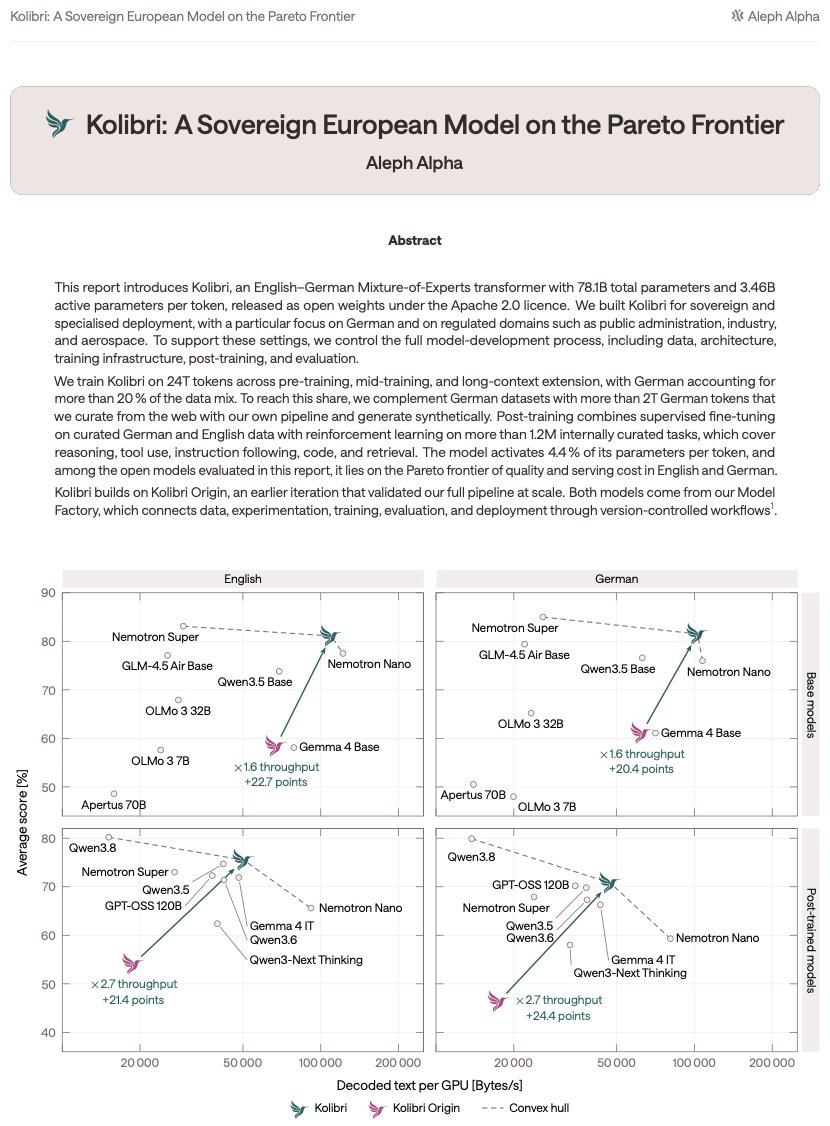
    Small bird, fast wings, Kolibri is here. 78B parameters. 3.46B active. Up to 1M tokens of context. Built in Europe. Now the weights are yours. Run it on your own hardware, under Apache 2.0.
    23828414.6K
  2. Aleph Alpha@Aleph__Alpha
    Small bird, fast wings, Kolibri is here. 78B parameters. 3.46B active. Up to 1M tokens of context. Built in Europe. Now the weights are yours. Run it on your own hardware, under Apache 2.0.
    Download
    4361K9.8K2.7M
  3. Pit Neitemeier✓@PitNeitemeier
    We worked out efficient distributed calculation of global quantiles for quantile MoE load balancing. Additionally we found a better surrogate for straight through estimation of load errors that outperforms the common GShard loss for local balance. Check it out!
    Aleph Alpha @Aleph__Alpha
    Expert load balancing is key to training Kolibri efficiently at scale. We developed two new methods: Exact Quantile Balancing (EQB) for global balance and Load-Error Injection (LEI) for local balance. @JesseLiJiaze and @PitNeitemeier explain them in a new, visual blog post.
    01182.6K
  4. Aleph Alpha@Aleph__Alpha
    Expert load balancing is key to training Kolibri efficiently at scale. We developed two new methods: Exact Quantile Balancing (EQB) for global balance and Load-Error Injection (LEI) for local balance. @JesseLiJiaze and @PitNeitemeier explain them in a new, visual blog post.
    Download
    111435.2K
  5. Pit Neitemeier✓@PitNeitemeier
    One of my favourite things to see here is how for DeepSeek at short seqlens we read the attention state more than once (dashed read line above solid total) due to cross-layer reuse. Past 16K, sparse attention takes over, so we read it less than once and the lines cross.
    Aleph Alpha @Aleph__Alpha
    The total attention state controls how many sequences fit during decode and the state read per step impacts decode speed. Sparse attention decouples the two by reading only a subset. With state reuse across layers, the read state can surpass the total.
    0113374
  6. Aleph Alpha@Aleph__Alpha
    Posts @Aleph__Alpha
    The total attention state controls how many sequences fit during decode and the state read per step impacts decode speed. Sparse attention decouples the two by reading only a subset. With state reuse across layers, the read state can surpass the total.
    Download
    114421
  7. Pit Neitemeier✓@PitNeitemeier
    How many of your active parameters go to attention, and how many to the experts? In our new blog we derive how modern architectures allocate parameters and FLOPs, and what that means for attention state and long-context FLOPs. Also: cute kolibris!
    Download
    Aleph Alpha @Aleph__Alpha
    Every architectural choice has a cost. Choose where to pay it. @alessio__serra and @PitNeitemeier derive from first principles how design choices allocate parameters, FLOPs and KV cache, compare open models, and share some of the tooling we used to design Kolibri.
    43341.8K
  8. Aleph Alpha@Aleph__Alpha
    Every architectural choice has a cost. Choose where to pay it. @alessio__serra and @PitNeitemeier derive from first principles how design choices allocate parameters, FLOPs and KV cache, compare open models, and share some of the tooling we used to design Kolibri.
    Download
    102012812.5K
  9. Pit Neitemeier✓@PitNeitemeier
    Pit Neitemeier
    RT @konarkmodi: Got Kolibri-1 to play Breakout completely on its own, no fine-tuning. The more I am playing with @Aleph__Alpha’s Kolibri the more I am getting excited about its potential. Less talk. More Breakout. 🕹️ We optimized the inference for action probabilities: around 25 ms inference per decision. Four moves. No generated text. One shared game. Open weights. New possibilities. Watch 👇 Cc @IlhanScheer @PitNeitemeier
    Konark Modi @konarkmodi
    Dear @Aleph__Alpha team - thank you for making Kolibri-1 open. We care deeply about sovereign AI, and launching it on German Unity Day makes today feel especially fitting. As a small gesture of support, we’ve hosted and made Kolibri-1 free for anyone to try for the next few days. No GPU. No setup. Just try it. Open Models move us all forward. We’re rooting for you. 🇩🇪 Tesseracted Labs GmbH. #alephalpha #openweightmodels
    0705.7K
  10. Pit Neitemeier✓@PitNeitemeier
    Pit Neitemeier
    RT @resiliem: What is not covered in the report is how we scaled model training to be efficient on 768 B200 GPUs. I explain it in detail here: A how to guide to scale up model training without wasting your GPU hours. Even if you only have 1 or 2 GPUs and cannot scale, our optimisation philosophy can still make your GPUs go brrr. I couldn't explain ALL the details of our method in the blogpost, since the big launch came after. You can connect the dots now, the 30B MoE architecture was in fact Kolibri Origin all along.
    Aleph Alpha @Aleph__Alpha
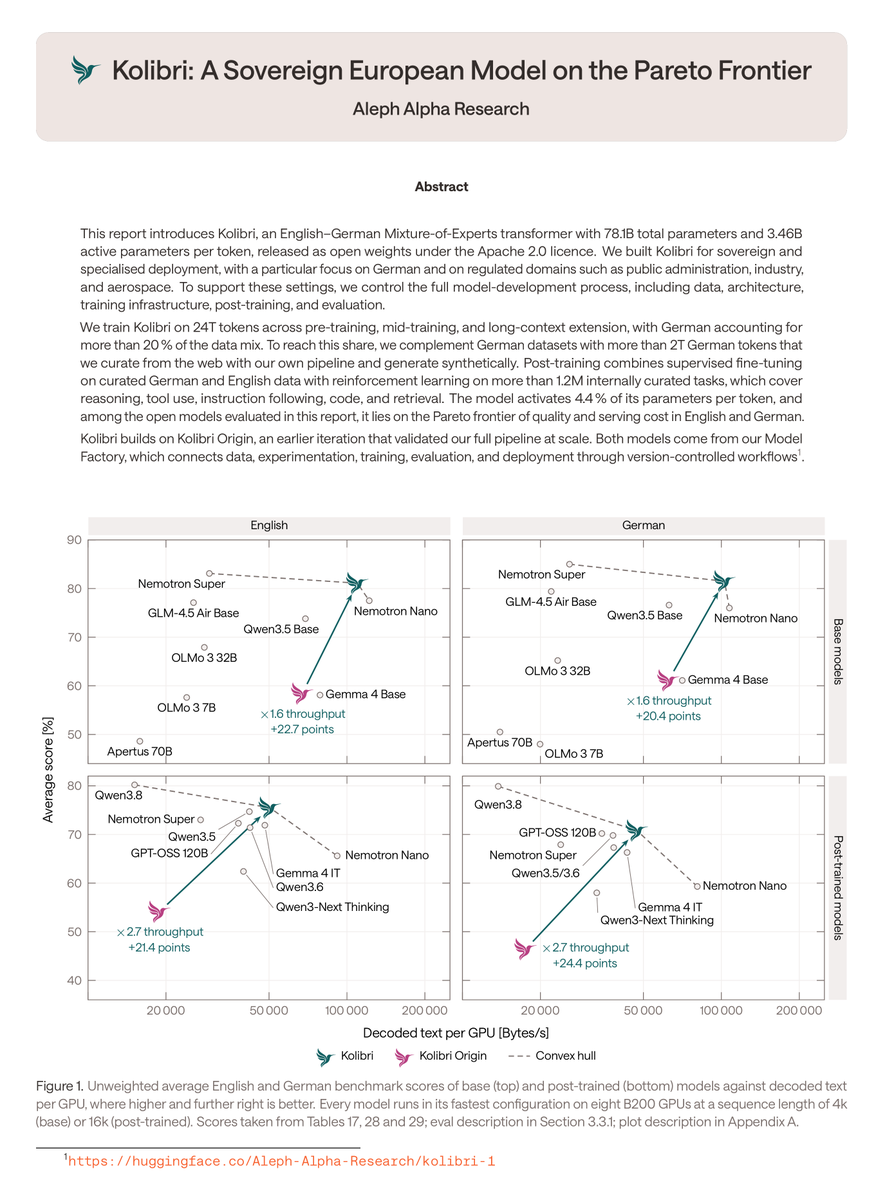
    Tech report is available:
    0770177K
  11. Aleph Alpha@Aleph__Alpha
    Posts @Aleph__Alpha
    Tech report is available:
    Download
    1839671305K
  12. Pit Neitemeier✓@PitNeitemeier
    Pit Neitemeier
    RT @alessio__serra: a look at our approach to architecture, load balancing and hyperparameter transfer for Kolibri-1. i wanted to write about it yesterday, but Pit was faster :)
    Pit Neitemeier @PitNeitemeier
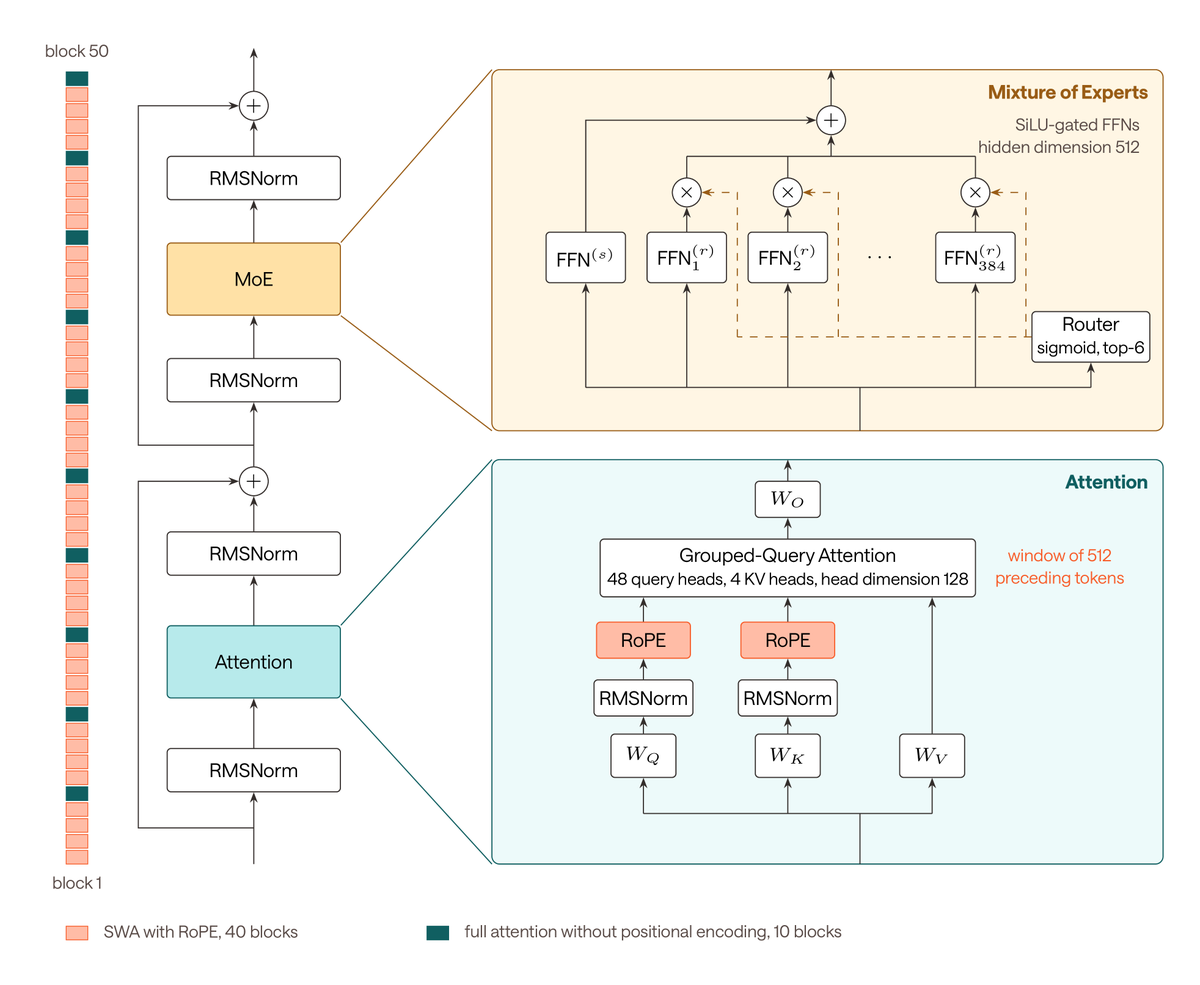
    Love the reactions to our release today! Here are some of my favorite details covering architecture, load balancing and hyperparameter transfer from developing and training Kolibri, our 78B-total, 3.5B-active MoE model:
    0103.6K
  13. Pit Neitemeier✓@PitNeitemeier
    Love the reactions to our release today! Here are some of my favorite details covering architecture, load balancing and hyperparameter transfer from developing and training Kolibri, our 78B-total, 3.5B-active MoE model:
    Download
    19494.9K
  14. Pit Neitemeier✓@PitNeitemeier
    Posts @PitNeitemeier
    To train models this sparse, load balancing needs to be dialed in. We built on the work of @Jianlin_S and team and developed Exact Quantile Balancing (EQB). Finding the exact balancing quantile naively requires keeping the tokens × experts matrix of the full global batch.
    216222
  15. Pit Neitemeier✓@PitNeitemeier
    Posts @PitNeitemeier
    @Jianlin_S We also published our work on quantile balancing on arxiv:
    00132
  16. Pit Neitemeier✓@PitNeitemeier
    Pit Neitemeier
    RT @tfburns: How do you pick the best data for a model? For Kolibri we stopped looking for one "quality" score and blended several. 🧵
    0302.2K
  17. Pit Neitemeier✓@PitNeitemeier
    Posts @PitNeitemeier
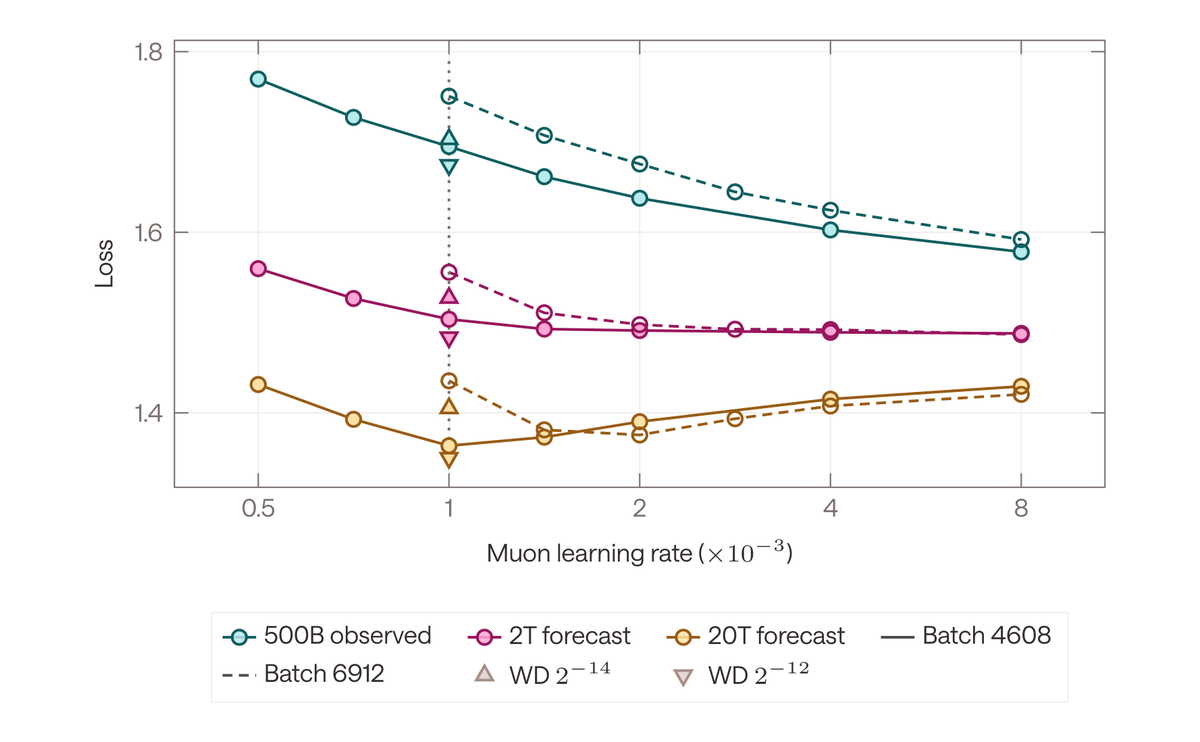
    To transfer hyperparameters from proxy runs, we use μP across width and loss extrapolation across token horizon. I haven't seen this used this way before, and it's very satisfying to watch the LR basin emerge and the optimum shift as the target horizon grows.
    Download
    114190
  18. Pit Neitemeier✓@PitNeitemeier
    Posts @PitNeitemeier
    For all the details, see our tech report. We love reports with the development story and ablations, so we included as many as we could while keeping it (slightly) shorter than Order of the Phoenix (just with more plots). Missing a detail? Call us out!
    Download
    026186
  19. Pit Neitemeier✓@PitNeitemeier
    Pit Neitemeier
    RT @teortaxesTex: Hybrid SWA, 3.46B active. Europe on the Pareto frontier indeed. At least they're keeping up with the Chinese literature, kind of (but Sberbank is on MLA + GDN already; Euros have too much GDP to stoop that low). Scale that up.
    Aleph Alpha @Aleph__Alpha
    Small bird, fast wings, Kolibri is here. 78B parameters. 3.46B active. Up to 1M tokens of context. Built in Europe. Now the weights are yours. Run it on your own hardware, under Apache 2.0.
    0806.2K
  20. Pit Neitemeier✓@PitNeitemeier
    Pit Neitemeier
    RT @Aleph__Alpha: This morning we released Kolibri. Some details on how we built it in the thread.
    033028.8K
  21. Pit Neitemeier✓@PitNeitemeier
    Amazing work by Max to get this up this fast. He was actually one of the drivers to get us back into model training before he went on to found construct labs. Excited for people to try it!
    Max Meuer @meuer_max
    Big congrats to my friends at Aleph. Glad I was still around when this team formed and got to see how much work went into building it end to end. We will offer inference for free for the next ~48 hours. Hit me up if you are interested in bringing this into production or post-training it.
    2019977
  22. Max Meuer✓@meuer_max
    Big congrats to my friends at Aleph. Glad I was still around when this team formed and got to see how much work went into building it end to end. We will offer inference for free for the next ~48 hours. Hit me up if you are interested in bringing this into production or post-training it.
    Aleph Alpha @Aleph__Alpha
    Small bird, fast wings, Kolibri is here. 78B parameters. 3.46B active. Up to 1M tokens of context. Built in Europe. Now the weights are yours. Run it on your own hardware, under Apache 2.0.
    7118692.1K
  23. Pit Neitemeier✓@PitNeitemeier
    Pit Neitemeier
    RT @konarkmodi: Dear @Aleph__Alpha team - thank you for making Kolibri-1 open. We care deeply about sovereign AI, and launching it on German Unity Day makes today feel especially fitting. As a small gesture of support, we’ve hosted and made Kolibri-1 free for anyone to try for the next few days. No GPU. No setup. Just try it. Open Models move us all forward. We’re rooting for you. 🇩🇪 Tesseracted Labs GmbH. #alephalpha #openweightmodels
    043052.8K
  24. Show more posts