Albert Gu✓

@_albertgu

assistant prof @mldcmu. chief scientist @cartesia. leading the ssm revolution.

  • Joined
78 Following25.9K Followers644 Posts
  1. Albert Gu✓@_albertgu
    I've always believed that intelligence should come from simple, general building blocks that learn their own abstractions directly from raw data; in other words, the bitter lesson. I think we're finally seeing a real step towards AI that can learn from all data. Language modeling on raw bytes is a microcosm of this ideal, and to me it's a central problem in AI: if we can't build LLMs that learn end-to-end from bytes, how will we handle the rest of the world's data that we understand even less? Last year we introduced hierarchical networks (H-Nets) as a first step. Our new version finds up to 3-5x efficiency gains in controlled scaling law experiments, and at larger scale matches an open-source model trained on 11T tokens with ~10x less data and compute. The posts below walk through what we found and why we think it works.
    Download
    2317216.7K822K
  2. Albert Gu✓@_albertgu
    Posts @_albertgu
    And of course major kudos to the talented @cartesia research team who did all this amazing research 🙏
    2213234.4K
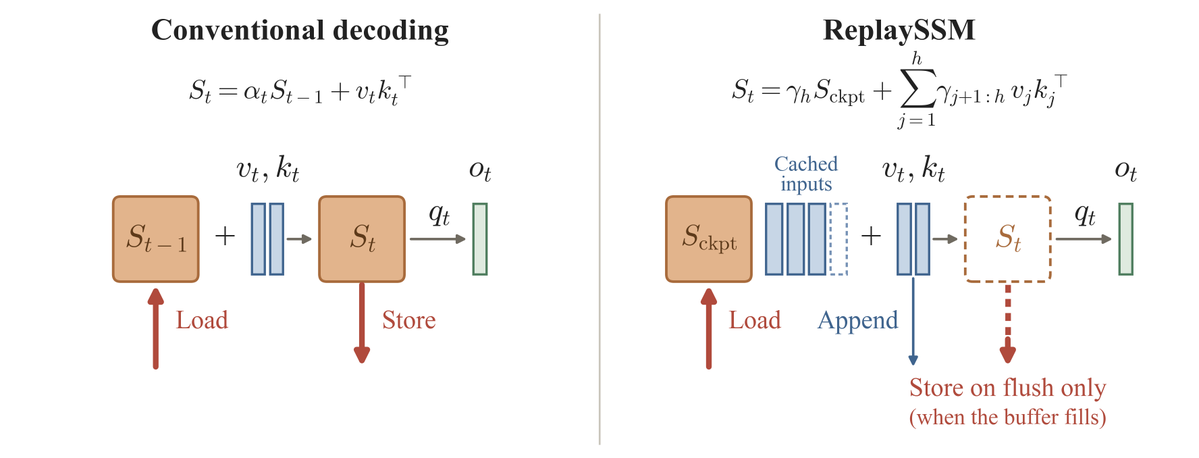
  3. Albert Gu✓@_albertgu
    Posts @_albertgu
    @cartesia Also forgot to shout out @JonathanHayase and @alisawuffles who taught me a bunch about tokenization (and pretokenization) after we released the first H-Net paper last year!
    239721.3K
  4. Albert Gu✓@_albertgu
    trying our best fam 🫡
    Timothy Luong (Chongz) @chongz
    10475.4K
  5. Albert Gu✓@_albertgu
    Albert Gu
    RT @cartesia: Cartesia Managed Agents is #1 on the @ArtificialAnlys Speech Agent Arena, outperforming 20+ speech-to-speech systems on tasks like appointment booking and ordering. We achieve frontier quality and naturalness by co-designing our speech models and harness in one vertically integrated stack.
    Artificial Analysis @ArtificialAnlys
    Cartesia Managed Agents scores an Elo of 1115 on the Artificial Analysis Speech Agent Arena, 98 points above Cartesia's earlier voice agent product, Cartesia Line, with Task Success Rate up from 77.5% to 91.7% Managed Agents is @CartesiaAI's fully managed platform for building and deploying voice agents. It is a cascaded system: Cartesia's own Ink Speech to Text and Sonic Text to Speech models run around an LLM of the developer's choice. We evaluated Cartesia Managed Agents with GPT-5.5 as the LLM and the Skylar and Daniel voices. Key takeaways: ➤ Speech Agent Arena: Cartesia Managed Agents scores an Elo of 1115 (95% CI 1086-1144, 685 samples), 98 points above Cartesia Line at 1017 (95% CI 985-1049) ➤ Agentic tasks: On tasks that need tool calls, Cartesia Managed Agents scores an Elo of 1112 ➤ Task Success Rate: 91.7% of eligible tool-calling conversations end with the correct final task-completing tool call Congrats to the @CartesiaAI team! See below for more details ⬇️
    0130104
  6. Artificial Analysis✓@ArtificialAnlys
    Cartesia Managed Agents scores an Elo of 1115 on the Artificial Analysis Speech Agent Arena, 98 points above Cartesia's earlier voice agent product, Cartesia Line, with Task Success Rate up from 77.5% to 91.7% Managed Agents is @CartesiaAI's fully managed platform for building and deploying voice agents. It is a cascaded system: Cartesia's own Ink Speech to Text and Sonic Text to Speech models run around an LLM of the developer's choice. We evaluated Cartesia Managed Agents with GPT-5.5 as the LLM and the Skylar and Daniel voices. Key takeaways: ➤ Speech Agent Arena: Cartesia Managed Agents scores an Elo of 1115 (95% CI 1086-1144, 685 samples), 98 points above Cartesia Line at 1017 (95% CI 985-1049) ➤ Agentic tasks: On tasks that need tool calls, Cartesia Managed Agents scores an Elo of 1112 ➤ Task Success Rate: 91.7% of eligible tool-calling conversations end with the correct final task-completing tool call Congrats to the @CartesiaAI team! See below for more details ⬇️
    Download
    452223242.4K
  7. Albert Gu✓@_albertgu
    to prepare for an upcoming release (👀) we dug into the pretokenizer a little more. are people aware that hand-crafted regexes are part of every frontier LLM and doing some pretty heavy lifting? some quick examples 🧵
    Download
    313444736.7K
  8. Albert Gu✓@_albertgu
    Posts @_albertgu
    GPT4o: honestly i have no idea, something about additional rules around upper/lower case
    Download
    31333.2K
  9. Albert Gu✓@_albertgu
    Posts @_albertgu
    Deepseek: 🤷🏻‍♂️🤷🏻‍♂️🤷🏻‍♂️
    Download
    01393.1K
  10. Albert Gu✓@_albertgu
    i know this is a joke but... actually tho 🧐
    will brown @willcb
    dude of course i didn’t look at the data that isn’t bitter lesson pilled
    3011011.8K
  11. will brown✓@willcb
    dude of course i didn’t look at the data that isn’t bitter lesson pilled
    112090938.2K
  12. Albert Gu✓@_albertgu
    Albert Gu
    RT @MayankMish98: Releasing FLAT: Flash Linear Attention on TPUs 🚀 Pallas training kernels for Linear Attention, Mamba-2 and GLA. On one TPU v6e, forward + backward is up to 3x faster than FLA on an H100 for GLA, and 1.5x faster for Mamba-2. 🧵
    0450119
  13. Albert Gu✓@_albertgu
    transformer inference has had dozens of tricks optimized by the entire ecosystem, there are still many ideas and optimizations waiting to be discovered for alternative architectures!
    Ze-Wei (Johnny) Liou @zwljohnny
    ReplaySSM now runs in production in GLM-5.3-Flash and Kimi-K3, and ships in TensorRT-LLM, vLLM, FlashInfer, and SGLang! It speeds up standard decoding (up to 1.47x) and speculative decoding (up to 2.1x), and now also enables a low-precision SSM state whose rounding error never propagates through the recurrence. Building on our earlier ReplaySSM work, we collaborated with @NVIDIA to pin down what the method really unlocks. Caching SSM inputs instead of the state is what ReplaySSM does. What it changes is that computing the output and updating the state can be separated during decoding. All three gains follow from that separation. Joint blog post, paper, and code with @NVIDIA and @tri_dao 👇
    71628113.3K
  14. Ze-Wei (Johnny) Liou@zwljohnny
    ReplaySSM now runs in production in GLM-5.3-Flash and Kimi-K3, and ships in TensorRT-LLM, vLLM, FlashInfer, and SGLang! It speeds up standard decoding (up to 1.47x) and speculative decoding (up to 2.1x), and now also enables a low-precision SSM state whose rounding error never propagates through the recurrence. Building on our earlier ReplaySSM work, we collaborated with @NVIDIA to pin down what the method really unlocks. Caching SSM inputs instead of the state is what ReplaySSM does. What it changes is that computing the output and updating the state can be separated during decoding. All three gains follow from that separation. Joint blog post, paper, and code with @NVIDIA and @tri_dao 👇
    Download
    197745071.5K
  15. Albert Gu✓@_albertgu
    really excited to see an application built on top of Hydra (bidirectional Mamba at small scales we had done some DNA language modeling and found evidence that Mamba is better than Transformers and convolutions; this paper from a serious bio group shows that it allows modeling at higher nucleotide resolution and improves performance on various genomic prediction tasks
    David Kelley @drklly
    This week we're releasing a preprint exploring state space models for long-sequence genomic prediction, alongside Cerberus, a set of open PyTorch models built on this work.
    81318715.2K
  16. David Kelley@drklly
    This week we're releasing a preprint exploring state space models for long-sequence genomic prediction, alongside Cerberus, a set of open PyTorch models built on this work.
    44716126.2K
  17. Albert Gu✓@_albertgu
    🤔
    Alex Veremeyenko @alex_verem
    Albert Gu aka the Mamba guy has the top ranked voice model now. How much of that is the architecture and how much is they just trained it better?
    105311.1K
  18. Alex Veremeyenko✓@alex_verem
    Albert Gu aka the Mamba guy has the top ranked voice model now. How much of that is the architecture and how much is they just trained it better?
    Karan Goel @krandiash
    Introducing Multilingual Voices We partnered with Baklavastory, our neighbor in the Mission, to show what it sounds like when a business's character and warmth stay consistent, no matter who calls or what language they speak. It's easy to translate speech, but much harder to preserve a single identity across languages. Every language has different rhythms, tones, and emphasis. When you change the language, identity tends to get lost in that shift, and your voice ends up sounding like someone else. With Multilingual Voices, pick a voice and keep one brand identity in every market you serve:
    2124618.7K
  19. Albert Gu✓@_albertgu
    chat with your model with a single identity across languages and accents!
    Karan Goel @krandiash
    Introducing Multilingual Voices We partnered with Baklavastory, our neighbor in the Mission, to show what it sounds like when a business's character and warmth stay consistent, no matter who calls or what language they speak. It's easy to translate speech, but much harder to preserve a single identity across languages. Every language has different rhythms, tones, and emphasis. When you change the language, identity tends to get lost in that shift, and your voice ends up sounding like someone else. With Multilingual Voices, pick a voice and keep one brand identity in every market you serve:
    00355.7K
  20. Karan Goel✓@krandiash
    Introducing Multilingual Voices We partnered with Baklavastory, our neighbor in the Mission, to show what it sounds like when a business's character and warmth stay consistent, no matter who calls or what language they speak. It's easy to translate speech, but much harder to preserve a single identity across languages. Every language has different rhythms, tones, and emphasis. When you change the language, identity tends to get lost in that shift, and your voice ends up sounding like someone else. With Multilingual Voices, pick a voice and keep one brand identity in every market you serve:
    Download
    1882551.4K5.4M
  21. Albert Gu✓@_albertgu
    poor ronald 😭
    Cartesia @cartesia
    We regret to inform our AI researcher Ronald that AI has replaced him. Sorry Ronald. Here's our team trying to tell his real voice from his cloned one. They were not good at it.
    004210.8K
  22. Cartesia✓@cartesia
    We regret to inform our AI researcher Ronald that AI has replaced him. Sorry Ronald. Here's our team trying to tell his real voice from his cloned one. They were not good at it.
    Download
    1437940365K
  23. Albert Gu✓@_albertgu
    misleading paper title, and even the phrasing in the tweet is still a misnomer. this is not about "post-training" but "retrofitting" (cross-architecture distillation) fwiw i've been bearish on distilling Transformers to recurrent models for a while, they're too different; architectural innovations just need to be trained from scratch
    Alexia Jolicoeur-Martineau @jm_alexia
    Simple beats complicated: We show that switching to a sliding-window attention mask with attention sinks (at no cost) beats linear attention post-training. Huge thanks to my collaborators @RheaSukthanker, @CameronPashmina, and @Emy_Aze. Paper:
    162465581K
  24. Albert Gu✓@_albertgu
    Albert Gu
    RT @voicearena_ai: Cartesia Sonic-3.6 is the #1 TTS model on the Voice Arena US English 🇺🇸 Leaderboard. It debuts at 1085 Elo, in a statistical tie with Google DeepMind's Gemini 3.1 Flash TTS, and ahead of its own Sonic-3.5, Simba 3.2 and Grok TTS. It holds the top spot as a real-time model. Sonic-3.6 is the latest TTS model from @cartesia. The model has been highly preferred among raters on @voicearena_ai. Results backed by 1,400+ blind, head-to-head listener votes across two languages 🧵
    01000123