v0.25.0: new Harbor features to mitigate reward hacking
31310921.3K

Onur Solmaz @onusozHaving 6.5k stars on @harborframework repo is crazy The group of people doing evals is still so small compared to developers as a whole But we know literally every company who uses AI will be running their own private evals at some point... "Evaluator" as a role has the potential to be as prevalent as "software developer"


Kobe @kobe0938Which model names (-m) can you use in Harbor? Now there's one answer: LiteLLM's.

Docker @DockerAgents that can edit files and run commands can also game their own evals. Harbor + Docker Sandboxes fix that: every eval task runs in an isolated microVM, with network policies for fair, reproducible runs.

Docker @DockerAgents that can edit files and run commands can also game their own evals. Harbor + Docker Sandboxes fix that: every eval task runs in an isolated microVM, with network policies for fair, reproducible runs.
Refresh @refresh_devIntroducing Blender Bench v1 (BBv1): a benchmark for frontier LLMs on 20 realistic 3D production workflows including animation, modeling, rigging, cloth & surfacing. GPT-6 Astra leads overall; Claude Opus 5.5 wins modeling & cloth simulation.

Unreal Labs @unreallabsaiFull results, harbor traces and implementation details in our blog -

Suresh @SureshRaghu07New blog: Is human taste overrated in harness engineering? An agent harness is the system around a model. It decides which tools the model can call, what evidence it sees, and what it remembers between steps. Most harnesses are still designed by human taste. Run the agent, read where it failed, change the harness, try again. That loop is increasingly being automated, with a strong model rewriting the harness itself. So we asked how far that can go. We ran Qwen on three drug design tasks from SMDD-Bench and compared a manually redesigned harness against one produced by automated harness search with Claude in the loop. No single approach won everywhere. The manual harness pulled clearly ahead when the fix was changing what the agent sees and remembers. Automated search did better once that was in place and the remaining problem was how to search the chemistry itself. The hard part was rarely implementing the fix. It was diagnosing what kind of failure we were looking at, and that is where human taste still mattered. Work with @KevinH1119568 , @aviral_kumar2 and @niloofar_mire Read more 👇

elie @eliebakouchxiaomi MiMo oss RL environments + training code

Unreal Labs @unreallabsaiIntroducing Unreal Agent: An open-source harness with state-of-the-art cost efficiency 39% cheaper than Codex+Astra on Terminal-Bench 4.0 while maintaining performance

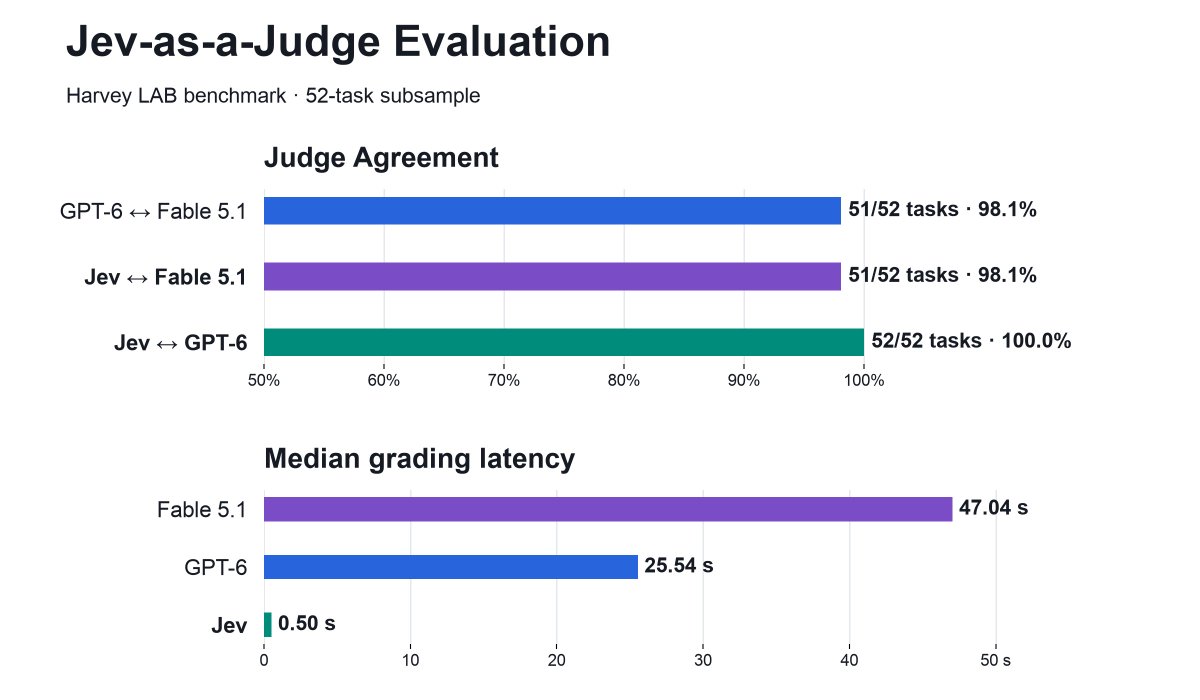
Benedikt Stroebl @benediktstroeblJev-as-a-Judge in Harbor Rewardkit is pretty amazing. It agrees with Fable and GPT and is very fast. When we test it on a real eval that uses an LLM judge, such as the @harvey LAB benchmark, Jev achieves perfect agreement but is 50x faster.