Posts with #Benchmarks

#Benchmarks

Public posts on X that use #Benchmarks.

Related hashtags

  1. Thoughtful@thoughtfullab
    Can AI forecast elections better than experts and prediction markets? We built BallotBench to find out: a live benchmark where 9 frontier AI agents compete to predict the 2026 US midterms, from today through Election Day, Nov 3. Follow along → Watch the agents do their research, revise their predictions, and make their calls all in live feeds.
    Download
    18169328.9K
  2. CNBC✓@CNBC
    BREAKING: The Federal Reserve voted Wednesday to keep benchmark interest rates on hold, opting to take a patient approach in its fight against inflation despite mounting evidence that price pressures are proving more nettlesome than policymakers had hoped.
    22196627.1K
  3. micro1✓@micro1_ai
    Today we’re announcing the micro1 Medical Index: a suite of medical benchmarks built and graded by working doctors, biostatisticians, regulatory experts, and psychiatrists. It brings all of our medical research into one place, with a combined score across models and a living leaderboard that grows as we publish new benchmarks. We’re starting with three, each built around a fundamental question: - RealmPathology Benchmark: can a model reason over a real pathology report, staying exact on what it says, within its diagnostic limits, and without escalating beyond what the evidence supports? - PharmaBench: can a model work through the regulatory and clinical documentation behind an FDA drug program with the precision a clinical development team would expect? - WellnessBench: when a young person brings a sensitive health question, can a model stay safe without shutting the conversation down, and hold that line under pushback? Together, these three benchmarks cover a meaningful range of medical work, from diagnostic reasoning to pharmaceutical research and patient safety. While they don't yet capture the full scope of the entire medical industry, they establish a strong starting point that will become more comprehensive as we expand the index. Huge shoutout to every expert who built and graded these tasks. Full reports linked in the comments below!
    Download
    3933241117K
  4. CNBC✓@CNBC
    The Federal Reserve voted Wednesday to keep benchmark interest rates on hold, opting to take a patient approach in its fight against inflation despite mounting evidence that price pressures are proving more nettlesome than policymakers had hoped. In a widely expected decision, the Federal Open Market Committee kept the overnight funds rate in a range between 3.75%-4%, where it has been since the central bank approved a quarter percentage-point increase in September. Full details:
    Download
    15295823.1K
  5. Artificial Analysis✓@ArtificialAnlys
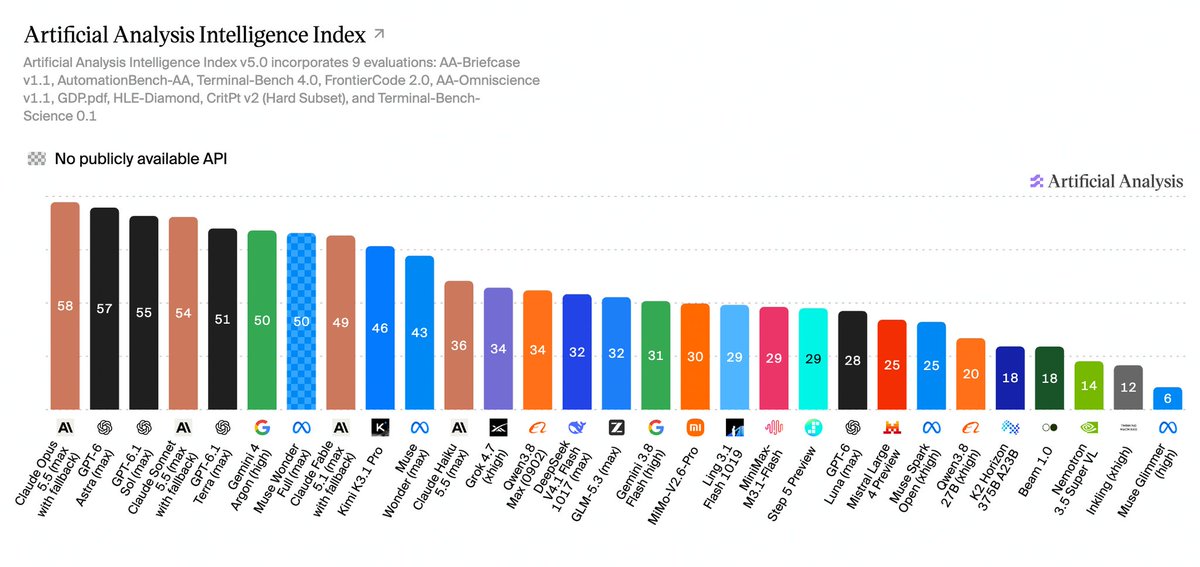
    Announcing Artificial Analysis Intelligence Index v5, featuring 2 new benchmarks and 3 upgrades. For the first time, the majority of the Index is built on private datasets The Artificial Analysis Intelligence Index is our composite measure of model capabilities across tasks reflecting real-world usage today. v5 is our biggest upgrade since v4 launched in January. With v5, 60% of the Index is now based on evaluations with private test sets or held-out answers. Alongside Intelligence Index v5, we’re launching the Artificial Analysis Progress Index v1, which tracks model capability over time on one continuous scale. New to the Intelligence Index: ➤ FrontierCode 2.0: Cognition's newly-launched private benchmark of real-world coding tasks, graded on whether a repository maintainer would merge the agent's change ➤ Terminal-Bench-Science: 70 agentic scientific research tasks, run in a terminal environment Upgraded: ➤ HLE-Diamond (replacing Humanity's Last Exam): a refined 1,000-question version of Humanity's Last Exam, split evenly between reasoning and knowledge questions ➤ AA-Omniscience v1.1: An updated dataset with saturated and public set questions removed, new questions added, and ambiguous or erroneous questions revised ➤ CritPt v2: a private, 40-question hard subset of CritPt v2, revised by the CritPt authors and run with a code-execution tool Staying in the Index: AA-Briefcase, AutomationBench-AA, GDP.pdf and Terminal-Bench 4.0 Removed from the Index: GDPval-AA v2.1, SciCode, and AA-LCR v1.1 Key results: ➤ Claude Opus 5.5 (max) leads at 58, ahead of GPT-6 Astra (max, 57) and GPT-6.1 Sol (max, 55): Anthropic and OpenAI hold the top five models. Gemini 4 Argon (high) is next at 50 ➤ The open weights gap widens from 3 points to 12: Kimi K3.1 Pro (weights not yet released) is the top open weights model at 46. Among released weights, DeepSeek V4.1 Flash 1017 (max) and GLM-5.3 (max) lead at 32 - 26 points behind the leader and below Claude Haiku 5.5 (max, 36) ➤ Cost per task varies by more than 13x among the leading models: of the 10 highest-scoring models shown, GPT-6.1 Terra (max) is the cheapest at $0.96 per Intelligence Index task and Claude Fable 5.1 (max) the most expensive at $13.04
    Download
    5534225.1K1.6M
  6. *Walter Bloomberg✓@DeItaone
    🇧🇷 BRAZIL'S BENCHMARK STOCK INDEX BOVESPA FUTURES EXTEND LOSSES AFTER LULA WINS, LAST DOWN NEARLY 20%
    4843370135K
  7. Hamel Husain✓@HamelHusain
    I've been looking into public benchmarks and am astounded by the poor quality vs. how much we rely on them as an industry. @xeophon pointed me to this excellent site which is an independent third party which scrutinizes benchmarks and "looks at the data" 💪 For example, here are some popular benchmarks we all rely on. Before trusting a benchmark its worth running them and inspecting examples the grader failed carefully, to get a sense of the quality. I'm continuing to look more into this, and will write something up eventually once I've collected more data, but I think this is an important subject.
    Download
    1337468875.1K
  8. am.will✓@LLMJunky
    This is fascinating. As it turns out, when you stop making benchmarks public, open models perform significantly worse. For me, Deepseek 4.1 Flash and GLM 5.3 have been an incredible revelation, these models are sooo good. But when these labs/people start trying to sell me the idea that we have "Fable at home" and that "China caught up" I just can't help but roll my eyes. I want there to be Opus 5.5 at home so badly, but the narrative spinning is so unhelpful. We've gotten to a point where we basically ignore almost every benchmark. Really hope this is a new leaf where we can start to put a little more stock in the results.
    Artificial Analysis @ArtificialAnlys
    Announcing Artificial Analysis Intelligence Index v5, featuring 2 new benchmarks and 3 upgrades. For the first time, the majority of the Index is built on private datasets The Artificial Analysis Intelligence Index is our composite measure of model capabilities across tasks reflecting real-world usage today. v5 is our biggest upgrade since v4 launched in January. With v5, 60% of the Index is now based on evaluations with private test sets or held-out answers. Alongside Intelligence Index v5, we’re launching the Artificial Analysis Progress Index v1, which tracks model capability over time on one continuous scale. New to the Intelligence Index: ➤ FrontierCode 2.0: Cognition's newly-launched private benchmark of real-world coding tasks, graded on whether a repository maintainer would merge the agent's change ➤ Terminal-Bench-Science: 70 agentic scientific research tasks, run in a terminal environment Upgraded: ➤ HLE-Diamond (replacing Humanity's Last Exam): a refined 1,000-question version of Humanity's Last Exam, split evenly between reasoning and knowledge questions ➤ AA-Omniscience v1.1: An updated dataset with saturated and public set questions removed, new questions added, and ambiguous or erroneous questions revised ➤ CritPt v2: a private, 40-question hard subset of CritPt v2, revised by the CritPt authors and run with a code-execution tool Staying in the Index: AA-Briefcase, AutomationBench-AA, GDP.pdf and Terminal-Bench 4.0 Removed from the Index: GDPval-AA v2.1, SciCode, and AA-LCR v1.1 Key results: ➤ Claude Opus 5.5 (max) leads at 58, ahead of GPT-6 Astra (max, 57) and GPT-6.1 Sol (max, 55): Anthropic and OpenAI hold the top five models. Gemini 4 Argon (high) is next at 50 ➤ The open weights gap widens from 3 points to 12: Kimi K3.1 Pro (weights not yet released) is the top open weights model at 46. Among released weights, DeepSeek V4.1 Flash 1017 (max) and GLM-5.3 (max) lead at 32 - 26 points behind the leader and below Claude Haiku 5.5 (max, 36) ➤ Cost per task varies by more than 13x among the leading models: of the 10 highest-scoring models shown, GPT-6.1 Terra (max) is the cheapest at $0.96 per Intelligence Index task and Claude Fable 5.1 (max) the most expensive at $13.04
    89391.2K110K
  9. Hamel Husain✓@HamelHusain
    I've seen a lot of pushback to this, with the following complaints: 1. "The benchmark owners already know about the flaws, and are working on it." 2. "Why are they spending time critiquing and not contributing to the benchmark" OR "critiquing known issues are not helpful". 3. "The flawed verdict is too binary" I find this pushback to be misguided. These benchmarks are used to move millions of dollars of token spend, and many people blindly trust how well these benchmarks generalize to their own products, and don't look any further than the headline numbers. For example, whenever a new model drops, you'll find thousands of youtube videos analyzing the pareto frontier using one of these benchmarks as the primary quality metric without questioning the benchmark. I think we would all be better served by inviting skepticism and encouraging people to develop an independent opinion of how well these benchmarks represent the tasks they care about. Concretely: - For the failing tasks within the benchmark, are they: realistic, have a proper harness, graded properly, sufficiently disambiguated user intent? - Are models and API calls configured properly (ex: inconsistent context windows, reasoning levels). - Are the models equipped with a modern harness and minimal retrieval that is sufficiently realistic? - Does the score even make sense ex: is it just a LLM judge committee that produces a score on a 0-100 scale that isn't aligned with ground truth? It's often the case you'll see many of these issues while looking at traces of a failing benchmark tasks, and it doesn't take long! Often the **very first trace you look at** has a serious issue. I also don't think there is an issue with verified vs. flawed verdict. It's good to have opinions. If you look through enough of what's behind their opinions and you find that you usually agree with their verdict, then they have earned your trust, the same way that a benchmark can lose your trust. I think this eval of benchmarks is a red pill that motivates investing in your own private evals.
    Epoch AI @EpochAIResearch
    Introducing Benchmark Reviews: our new initiative to audit AI benchmarks. We are launching with 15 benchmarks: 4 Verified, 9 Flawed, and 2 with not enough information for a review.
    82916512.1K
  10. Epoch AI✓@EpochAIResearch
    Introducing Benchmark Reviews: our new initiative to audit AI benchmarks. We are launching with 15 benchmarks: 4 Verified, 9 Flawed, and 2 with not enough information for a review.
    Download
    1161992K655K
  11. Investing.com✓@Investingcom
    *NEW ZEALAND CENTRAL BANK LEAVES BENCHMARK INTEREST RATE AT 2.75%; EST. 3.00% *NZ DOLLAR DROPS OVER 1% AS RBNZ UNEXPECTEDLY KEEPS RATE STEADY *NZ DOLLAR DROPS ALMOST 2% VS AUSSIE, MOST SINCE 2017 $NZD $AUD
    7108734.2K
  12. Yahoo Finance✓@YahooFinance
    South Korea’s benchmark stock index is up nearly 30% this year, but it’s a long way from its peak. Even as the KOSPI has pulled back, third quarter GDP grew 1.0%, more than triple the central bank’s forecast, on strong chip demand. Read more:
    Download
    16107214.2K
  13. Insilico Medicine✓@InSilicoMeds
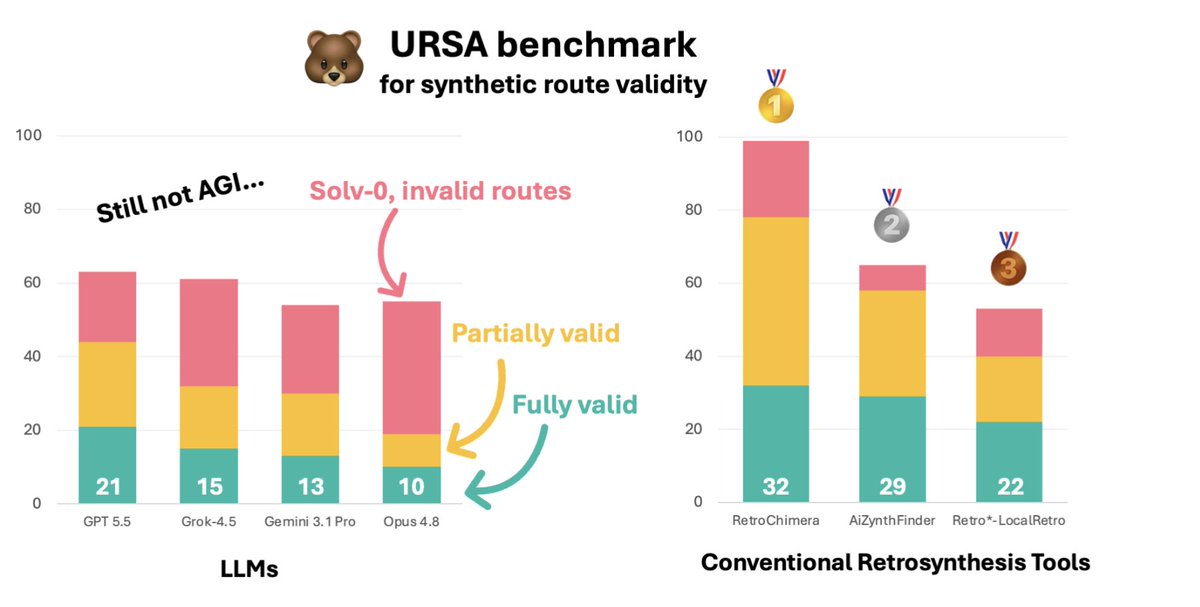
    🧪 Retrosynthesis #benchmarks are broken. For ~9 years, they’ve rewarded patent matching or “reaching” purchasable building blocks, even through chemistry no chemist would trust. The real test is simple: would a chemist take this route to the lab? That’s why we built #URSA 🧵 Continue reading 👇
    Download
    4131108.7K
  14. amrit✓@amritwt
    cognition's ceo is my benchmark for being qualified as a smart person
    Download
    721374.5K671K
  15. Bloomberg✓@business
    China’s national team may need to accelerate stock purchases after the benchmark notched a record losing streak, but state-backed buying alone may not be enough to put the market on a sustained recovery, according to Bloomberg Intelligence
    182614299.6K
  16. Eric Daugherty✓@EricLDaugh
    🚨 BREAKING UPDATE: Brazilian markets are ABSOLUTELY TUMBLING on the fraudulent reelection of leftist President Lula "Brazil's Real TUMBLING 8% against the US dollar, one of its biggest daily declines ON RECORD." - Brazil Benchmark Index: Plunged over 15% - U.S.-Traded Brazil ETF: Crashed nearly 20% in dollar terms, wiping out two months of gains in a single day - Brazilian Real: Tanked 8%+ - Interest Rate Futures: Spiked over 300 basis points as investors price in runaway socialist spending - National Treasury Bond Auctions: Cancelled for both Tuesday and Thursday after bond yields blew out THIS IS WHAT YOU GET WITH SOCIALISTS Brazil is on a DARK PATH. And all it took? ONE ORDER from Lula's hand-picked Supreme Court justice and former lawyer to extend the voting hours Madness. ANNUL!
    Download
    1672.7K8.5K153K
  17. Ionut Balosin@ionutbalosin
    🚀 Call for Contributors If you're interested in contributing to the #JVM #Performance #Benchmarks project - an initiative that gained significant traction in the #Java community through our recent #JDK17 and #JDK11 analyses - check out the repo: 🔗
    115242K
  18. chuplung✓@choopyplug1
    THIS IS INSANE Anthropic just dropped a goldmine of 20 Claude Code plugins. $29,077 worth of tools, FREE on GitHub paid marketplaces sell a skill for $19 and an agent for $39. these repos ship 970 skills and 273 agents for $0 1.8M stars combined, picked from 68,900 repos tagged claude-code most people still run Claude Code bare: no memory, no team, no taste, burning tokens on raw logs 20 GitHub projects you should open first: 1. Everything Claude Code → 71 agents, 311 skills and 97 commands in one harness. the closest thing to an agent OS 2. agent-skills → 25 production skills by Addy Osmani: spec, plan, build, verify, review, ship 3. Ruflo → runs agent swarms across Claude Code and Codex with shared memory between them 4. agents → 202 agents, 185 skills and 105 commands packed into 94 installable plugins 5. claude-mem → records what your agent did, summarizes it and feeds it back next session 6. planning-with-files → keeps the plan in markdown on disk, so it survives /clear, compaction and crashes 7. Graphify → turns code, docs and SQL schemas into a knowledge graph. parsed locally, nothing leaves your machine 8. Understand-Anything → an interactive map of your codebase with search, guided tours and diff impact analysis 9. ponytail → makes Claude code like the laziest senior dev. 53% less code and 45% fewer tokens in its own Opus 5.5 benchmark 10. rtk → a Rust CLI proxy that cuts 60-90% of the tokens from common dev command output 11. headroom → compresses logs, tool outputs and JSON before they reach the model 12. context-mode → sandboxes tool output. 315 KB in, 5.4 KB to the model 13. UI UX Pro Max → 79 styles, 192 palettes and 74 font pairings, so your UI stops looking AI-made 14. taste-skill → gives Claude art direction, real reference photos and a browser check at several screen widths 15. video-shotcraft → turns your real pages into a cinematic product video in Remotion, synced to the beat 16. Agent-Reach → lets your agent read YouTube, GitHub, Reddit and the web from one CLI, zero API fees 17. cc-switch → a desktop app to switch providers in one click and manage MCP, skills and prompts in one place 18. pm-skills → 69 product skills and 42 chained workflows, from discovery to launch 19. claude-skills → 380+ skills across engineering, marketing, finance, compliance and C-level advice 20. career-ops → scans job boards, scores every role against your CV and drafts the application. you still press Submit start with 3, not 20: one for memory, one for tokens, one for your actual job run the same task before and after. keep only what makes the result better or cheaper every plugin you add loads into context, so more isn't free save this before you spend another weekend building something that already exists and repost it for the friend who's still paying $19 a skill ↓
    Download
    chuplung @choopyplug1
    511771.4K144K
  19. chuplung✓@choopyplug1
    291186431.4M
  20. Show more posts