Posts with #FastInference

#FastInference

Public posts on X that use #FastInference.

Related hashtags

  1. Zach Mueller✓@TheZachMueller
    Happy to announce #fastinference! The bad news: fastshap and ClassConfusion are gone. The good news: they moved to a new home! In this module we have all of the above plus some speed-up and QOL integrations into @fastdotai's inference methods, see here: 1/
    Download
    51891
  2. Zach Mueller✓@TheZachMueller
    Just released the newest version of #fastinference ! Now included: Text Model support for @fastdotai's AWD-LSTM! Besides some timing increase (predict sped up by a factor of 10X, get_preds by only a little), we also have intrinsic attention on your classification predictions!
    Download
    11486
  3. Vithu Thangarasa@vithursant19
    We just released Kimi-Linear-REAP-35B-A3B-Instruct (30% pruned from 48B). Showing REAP’s robustness on Hybrid-attention MoEs, lighter footprint, more context headroom. 🤗 📄 🔗 #Cerebras #FastInference #Kimi
    008739
  4. Zach Mueller✓@TheZachMueller
    For those wanting an in-depth guide to the major performance changes, as well as how to use the ONNX support in @fastdotai with #fastinference, here is the first part of my tutorial blogs:
    11040
  5. Coenraad Loubser 🇿🇦✓@dagelf
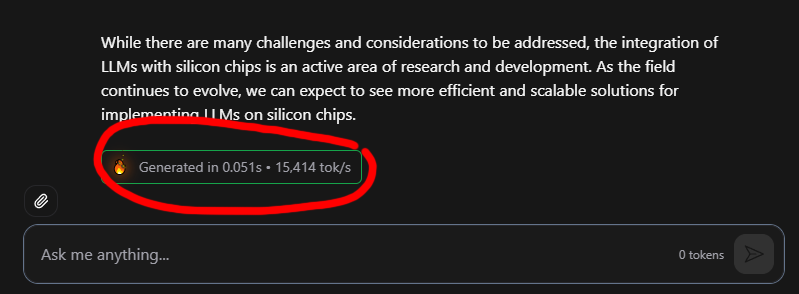
    This outputs whole responses in the time it takes other inference providers to output one token!!! #fastinference
    Wildminder @wildmindai
    17,000 tokens per second!! Read that again! LLM is hard-wired directly into silicon. no HBM, no liquid cooling, just raw specialized hardware. 10x faster and 20x cheaper than a B200. the "waiting for the LLM to think" era is dead. Code generates at the speed of human thought. Transition from brute-force GPU clusters to actual AI appliances.
    00253
  6. Wildminder@wildmindai
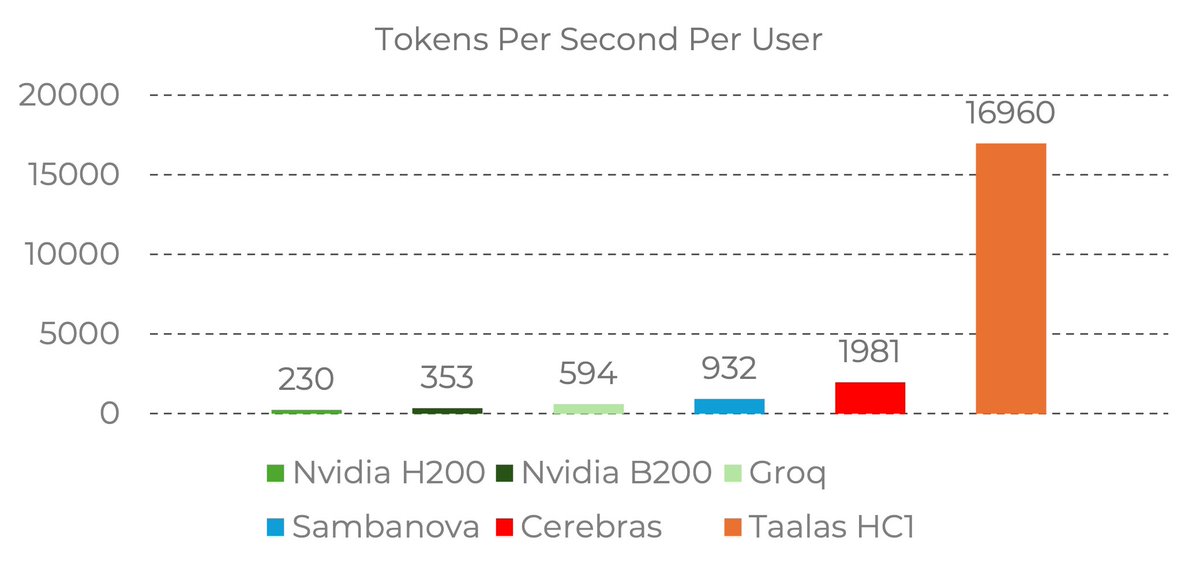
    17,000 tokens per second!! Read that again! LLM is hard-wired directly into silicon. no HBM, no liquid cooling, just raw specialized hardware. 10x faster and 20x cheaper than a B200. the "waiting for the LLM to think" era is dead. Code generates at the speed of human thought. Transition from brute-force GPU clusters to actual AI appliances.
    Download
    3769137.3K1.8M
  7. Morgan McGuire✓@morgymcg
    Zach has been doing amazing work with #fastinference for @fastdotai, the addition of intrinsic attention on your text predictions is the icing on the cake!
    Zach Mueller @TheZachMueller
    Just released the newest version of #fastinference ! Now included: Text Model support for @fastdotai's AWD-LSTM! Besides some timing increase (predict sped up by a factor of 10X, get_preds by only a little), we also have intrinsic attention on your classification predictions!
    1316
  8. Zach Mueller✓@TheZachMueller
    This question is geared towards my @fastdotai extension #fastinference. In the pytorch-version only, what would be the *minimal* augmentation you would expect available at runtime after training your model (from a vision perspective)
    303
  9. Zach Mueller✓@TheZachMueller
    Join me Sunday at 2pm CST for my walk-through of my @fastdotai extension #fastinference. I'll be talking about how to use it, how it's built, and the decisions I made along the way:
    1533
  10. Zach Mueller✓@TheZachMueller
    #fastinference on pip has now been released to reflect the recent change to fastai, finally got there.
    015
  11. Zach Mueller✓@TheZachMueller
    In a situation where you may not want all of #fastinference? Well now you can choose to install specific flavors to suit your need! Don't quite need GPU support? We go that covered! The base library only contains the @fastdotai inference speedup code, and building up from there
    Download
    1421
  12. Zach Mueller✓@TheZachMueller
    Bringing light to an older @fastdotai thread today, where a thorough experiment with tabular was done. Including: feature importance, dendrograms, embedding transfer with RF, and partial dependence
    11357
  13. Zach Mueller✓@TheZachMueller
    @TheZachMueller
    Working on getting this all to #fastinference a bit more (long term goal rn)
    004
  14. Zach Mueller✓@TheZachMueller
    Deploying with @fastdotai isn't always learn = load_learner(), learn.predict. There are numerous scenarios when you might only want some, part, or none of both the API and the library as a whole. In this thread we will be exploring your options, how they work, and what to do: 1/n
    324118
  15. Zach Mueller✓@TheZachMueller
    @TheZachMueller
    In this scenario, we need to ensure that ALL functions which were used in relation to the data are imported before loading in the learner. This can run into issues when using fastAPI and other platforms when loading in the Learner is done in a multi-process fashion 3/
    103
  16. Zach Mueller✓@TheZachMueller
    @TheZachMueller
    2. We have my #fastinference library: -> Model is run through ONNX ort and DataLoaders (which are the same blank DataLoaders from 1) get exported. Still requires that all related functions are in the namespace still 4/
    102
  17. Zach Mueller✓@TheZachMueller
    It's the end of 2020, and I suddenly feel the need to write down what I've managed to accomplish. Both from my goals I set this year, and in general. In no particular order, let's begin 1/
    1237
  18. Zach Mueller✓@TheZachMueller
    @TheZachMueller
    First off I built #fastinference, a @fastdotai extension geared towards making inference with the fastai more approachable, faster at times, and include integrations with libraries such as ONNX. 2/
    1112
  19. Zach Mueller✓@TheZachMueller
    Minor little update: If you've been using #fastinference and #shap you may have noticed it takes much longer to analyze some rows. Their new release seems to have change some bits so the last version is pinned. (May look into it more once time is available)
    007
  20. Zach Mueller✓@TheZachMueller
    Ever wondered just what parameters you used in your @fastdotai pipline? (or what fastai set) Spent the last few days making a nice and easy way to do so! (Coming soon) And yes, I will 100% be taking advantage of this for #fastinference
    Download
    3220
  21. Show more posts