Posts with #GPU

#GPU

Public posts on X that use #GPU.

Related hashtags

  1. Higgsfield AI 🧩✓@higgsfield
    Jensen Huang: “… the founders of Higgsfield are visionary in the work that they do … but these are some of the brightest people in the world.” We're grateful to Jensen and the teams at NVIDIA and TCV for believing in us. Both companies have joined Higgsfield as investors in our Series B extension. Since our August Series B: • We’ve crossed $1 billion in annualized revenue. • Enterprise contracts are up 71%, growing 100%+ month-over-month • We’ve grown from 30 million to over 40 million users globally. TCV has backed Netflix, Facebook, ByteDance and Spotify, companies that changed how people create and consume media. NVIDIA has powered every generation of Higgsfield, from L40 and A40 GPUs through Hopper and Blackwell, with Vera Rubin next to meet growing demand. Thank you to our creators and customers for building with us every day, and to everyone at Higgsfield whose work brought us here. The full Bloomberg Announcement is linked below.
    Download
    Bloomberg @business
    Higgsfield, an AI video startup founded by a former Snap executive, said it has attracted investment from Nvidia and TCV to help fund global infrastructure and hiring to capture growing demand.
    2165942.1K2.1M
  2. Bloomberg✓@business
    Higgsfield, an AI video startup founded by a former Snap executive, said it has attracted investment from Nvidia and TCV to help fund global infrastructure and hiring to capture growing demand.
    1313140147K
  3. NVIDIA Customer Care✓@nvidiacc
    NVIDIA GeForce/RTX Spark Hotfix Driver v621.12 is now available. This update resolves the following: ✅Fixed an issue where video playback may freeze or black screen on some GeForce RTX 50 Series GPUs/RTX Spark after updating to GRD 621.01. ✅Unreal Engine 5.8 may crash when Ray Lighting Mode is set to Hit Lighting ✅[RTX Spark] HDMI monitor connected to StarTech Thunderbolt 3 to HDMI 2.0 adapter may show corruption ✅[MSI N16 Flip] Intermittent flickering may be observed ⤵️Learn more: Select Download: Windows 10/11 (x64) - Windows 11 (ARM64) -
    Download
    3810579667.1K
  4. Tom's Hardware@tomshardware
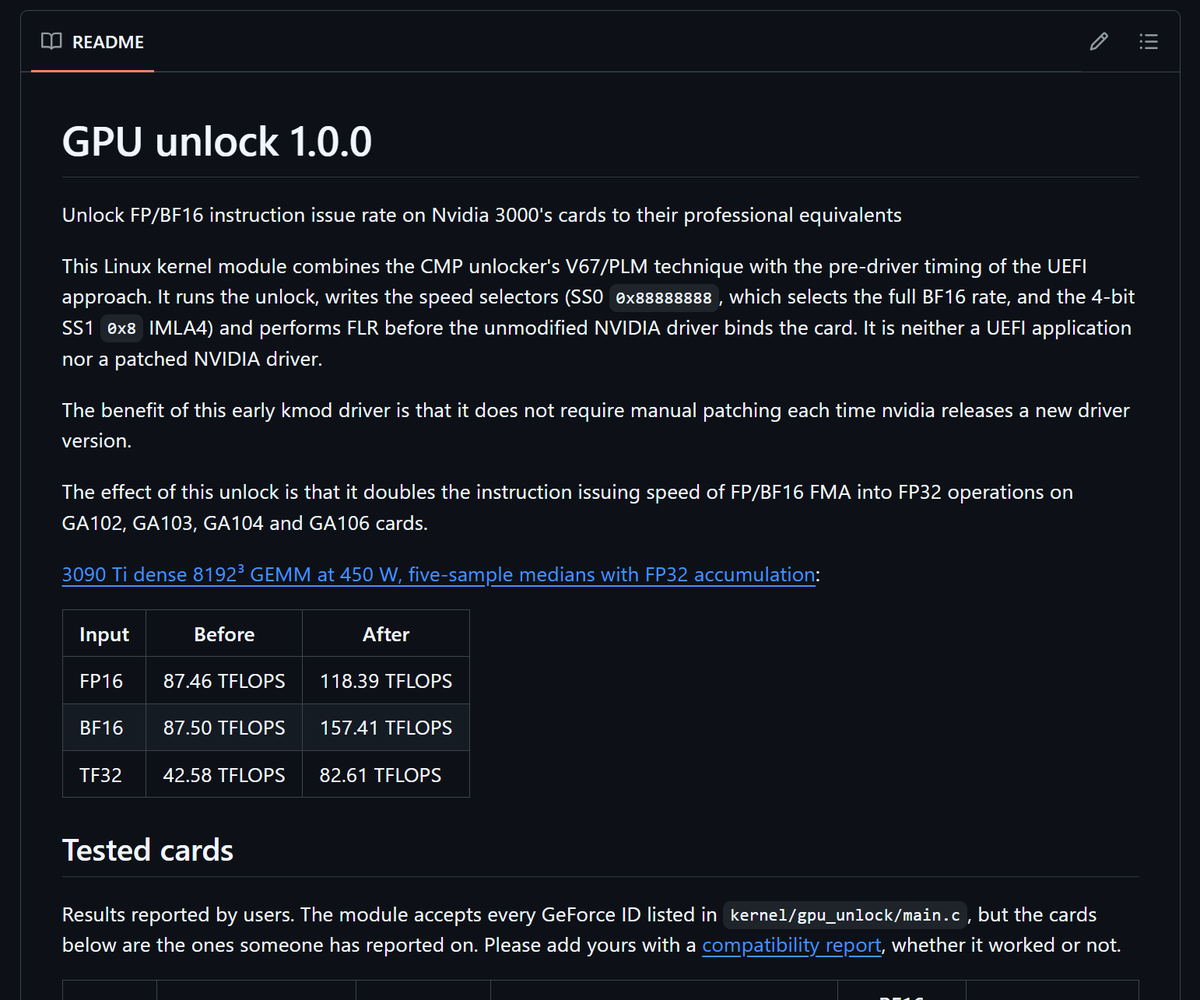
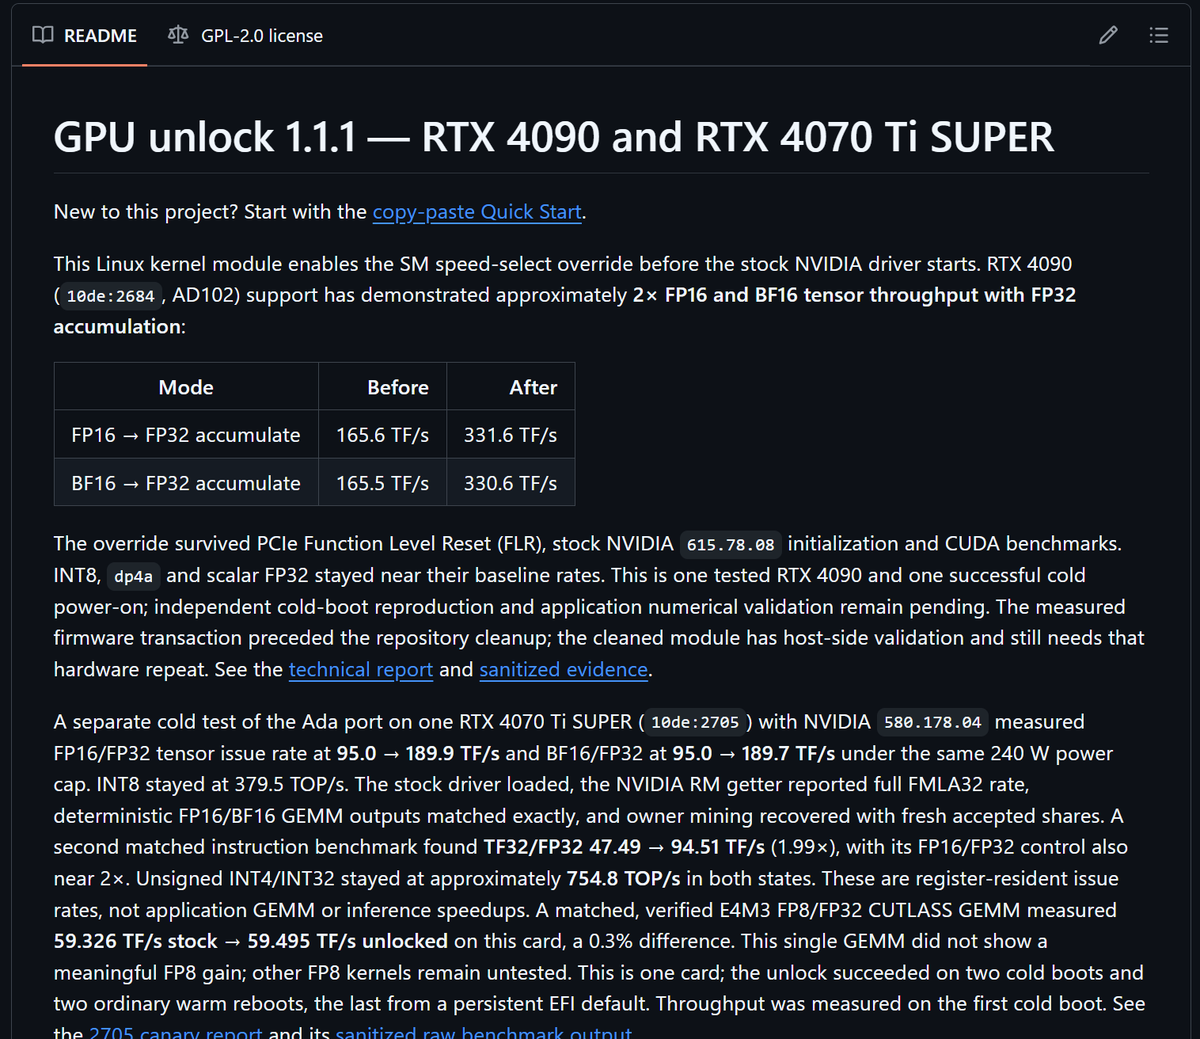
    Nvidia RTX 20, 30, and 40-series GPUs hacked to remove a half-speed AI throttle
    195044040.9K
  5. Ragavan Thurairatnam✓@RagavanThurair
    We made the first AI model you can have a realistic conversation with that was trained entirely on speech! Dessa is a full-duplex speech-to-speech model that you can run on consumer GPUs. This is a GPT3 moment for speech.
    Download
    1K1.2K17.1K4.5M
  6. PyTorch✓@PyTorch
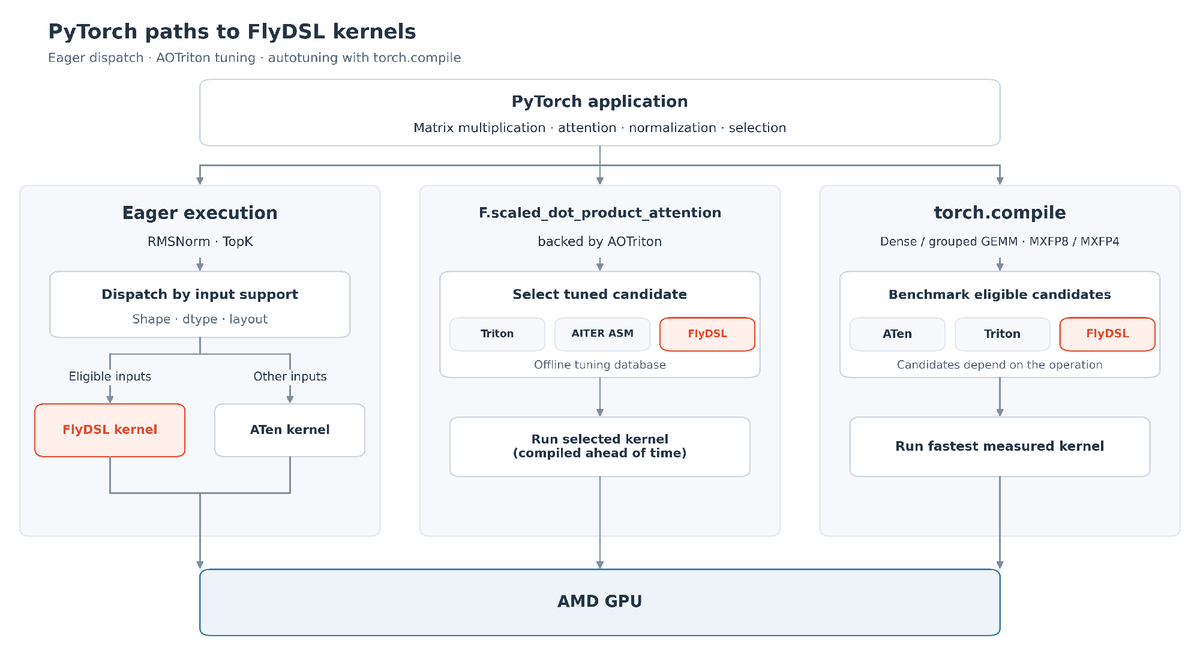
    FlyDSL, an open source Python kernel DSL, now plugs into PyTorch on @AMD MI350-series GPUs via torch.compile and eager mode. Up to 1.68x geomean scaled GEMM kernel speedups and up to 3.01x end-to-end #vLLM serving speedups. Read more:
    Download
    61711215.7K
  7. NVIDIA✓@nvidia
    We introduced the GPU to the world #OnThisDay in 1999! Watch how our GPUs have progressed. What was your first NVIDIA #GPU?
    Download
    1667141.9K
  8. Tom's Hardware@tomshardware
    Leaked video exposes how industrial-scale Chinese factories are dismantling RTX 5090s by the thousands to fuel AI servers
    162317610.1K
  9. Liquid AI✓@liquidai
    Introducing 𝙻𝙵𝙼𝟹: our new generation of Liquid Foundation Models. With a new tri-hybrid architecture and new multimodal encoders, the LFM3 family is the ideal model suite for specialized intelligence. > 6 model instances, across text, audio, vision, and omni modalities, generative and decision models. > 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱: text, 256k context window. > 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱: vision-language model with video-input support for spatial understanding > 𝙻𝙵𝙼𝟹-𝙰𝚞𝚍𝚒𝚘-𝟸𝙱: tool calls, voice chat, reasoning in 18 languages. > 𝙻𝙵𝙼𝟹-𝙾𝚖𝚗𝚒-𝟸𝙱: an omni model combines vision, audio, and language. > 𝚍𝟷-𝟸𝙱 and 𝚍𝟷-𝙾𝚖𝚗𝚒-𝟸𝙱: decision models with typed outputs and calibrated probabilities in a single pass. Omni adds audio input. > fine-tune on 1 GPU. > a new tri-hybrid architecture > architecture optimized for 14 processor classes across GPUs, CPUs, and NPUs. > 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱 is a beast. It performs competitively with Gemma 4 12B (6x larger), and Gemini 3.5 Flash Lite, and GPT-5.6 Luna, with 1.9B parameters. > 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱 is #1 on the Pareto frontier of device intelligence 𝚙𝚒𝚙𝚎𝚝𝚝𝚎.𝚕𝚒𝚚𝚞𝚒𝚍.𝚊𝚒 Every modality for specialized intelligence. Pick the one that fits your use case, customize it, and run it on-device. 1/ 🧵
    Download
    3931.2K6.8K1.3M
  10. a16z@a16z
    GPUs are aging like fine wine, with rental rates up across the board since January 1st Approximate change YTD: - H200: +160% - B200: +120% - RTX PRO 6000: +65% - H100: +35% Even the 6-year-old A100 rents for more than it did at the start of the year Charts of the Week:
    Download
    1363732.3K949K
  11. Crypto Holding™ 💎✓@Crypto_Holding_
    ⛓️ @AethirCloud - the decentralized #GPU powerhouse reshaping #AI & #gaming! Aethir is building the future of high-performance computing with a global #DePIN network of 400,000+ enterprise-grade GPU containers (including #NVIDIA H100s, H200s & more) spanning 90+ countries. 📍 Two flagship products: • Aethir Earth – Bare-metal GPU cloud delivering raw power for AI training, fine-tuning & inference with zero virtualization overhead. • Aethir Atmosphere – Low-latency cloud gaming rendering that streams high-quality experiences to any device. ☁️ Cloud Hosts monetize idle GPUs and earn $ATH rewards, while customers get scalable, cost-efficient compute (up to 80% cheaper than traditional clouds), ultra-low latency, and 95%+ utilization rates. No massive CapEx, no vendor lock-in – just on-demand access closer to the edge. From AI model training to real-time cloud gaming and beyond, Aethir is democratizing enterprise GPU power and powering the next generation of innovation. 🦾 Axe Compute’s $317M in customer prepayments. That single number reframes how AI data centers get built in 2026 🧵 The decentralized cloud is here. Are you ready? 🌐 #Aethir #DePIN #AI #GPUCloud #Web3
    Download
    16959313231K
  12. lium.io✓@lium_io
    have GPUs? here's what they could be earning on lium: b300 node: $50k/month b200: $35k/month h200: $25k/month h100: $12k/month RTX pro: $9k/month A100: $7k/month 5090: $4k/month 4090: $3k/month 3090: $1200/month and all other nvidia models supported too. start here:
    525250583.5K
  13. Tom's Hardware@tomshardware
    Nvidia discusses $2,000-per-GPU annual fee for software that 'runs agents on AI factories' — details unclear about potential overlaps, firm already charges more than twice that amount for its AI Enterprise software platform
    96436.5K
  14. Tom's Hardware@tomshardware
    GPUs from Nvidia RTX 5090 stolen $470,000 shipment from Brazil airport appear for sale online, identified by serial numbers
    719666.1K
  15. AI Search✓@aisearchio
    This is crazy. AI is now helping unlock more throughput for Nvidia 3XXX and 4XXX GPUs. I haven't tested these, so try at your own discretion.
    Download
    58721.4K86.7K
  16. TechPowerUp✓@TechPowerUp
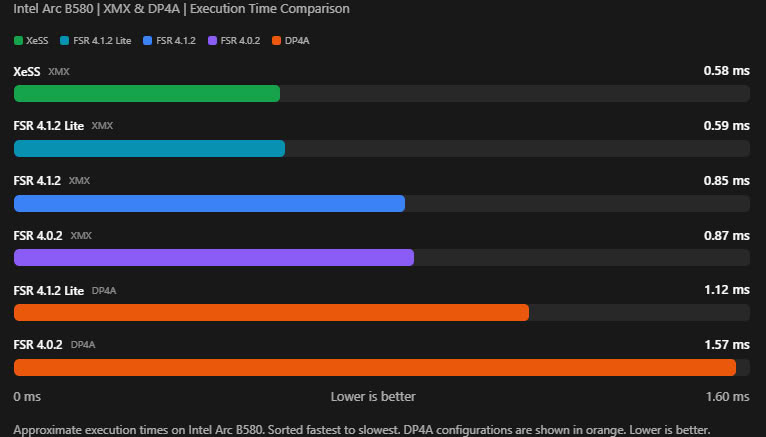
    AMD FSR 4.1.2 Modded to Run on Intel Arc GPUs Leveraging XMX Cores
    Download
    481849.3K
  17. 0xSero✓@0xSero
    Those of you with random laptops, old GPUs, old macs, etc.. you can now run a model that is able to automate your life, fast. This puts tool-calling and coherence on ipads, iphones, watches, maybe your refrigerator Freedom for all
    Liquid AI @liquidai
    Introducing 𝙻𝙵𝙼𝟹: our new generation of Liquid Foundation Models. With a new tri-hybrid architecture and new multimodal encoders, the LFM3 family is the ideal model suite for specialized intelligence. > 6 model instances, across text, audio, vision, and omni modalities, generative and decision models. > 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱: text, 256k context window. > 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱: vision-language model with video-input support for spatial understanding > 𝙻𝙵𝙼𝟹-𝙰𝚞𝚍𝚒𝚘-𝟸𝙱: tool calls, voice chat, reasoning in 18 languages. > 𝙻𝙵𝙼𝟹-𝙾𝚖𝚗𝚒-𝟸𝙱: an omni model combines vision, audio, and language. > 𝚍𝟷-𝟸𝙱 and 𝚍𝟷-𝙾𝚖𝚗𝚒-𝟸𝙱: decision models with typed outputs and calibrated probabilities in a single pass. Omni adds audio input. > fine-tune on 1 GPU. > a new tri-hybrid architecture > architecture optimized for 14 processor classes across GPUs, CPUs, and NPUs. > 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱 is a beast. It performs competitively with Gemma 4 12B (6x larger), and Gemini 3.5 Flash Lite, and GPT-5.6 Luna, with 1.9B parameters. > 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱 is #1 on the Pareto frontier of device intelligence 𝚙𝚒𝚙𝚎𝚝𝚝𝚎.𝚕𝚒𝚚𝚞𝚒𝚍.𝚊𝚒 Every modality for specialized intelligence. Pick the one that fits your use case, customize it, and run it on-device. 1/ 🧵
    25621.4K54.6K
  18. XOTIC PC✓@XoticPC
    Building an AI workstation can be quite the undertaking, many people ask if more than one GPU is necessary. In our assessment, one juiced up flagship card is the way to go. 🤖🖥️🤔#nvidia #gpu #aiworkstation
    Download
    001622
  19. Show more posts