Posts with #Jan

#Jan

Public posts on X that use #Jan.

Related hashtags

  1. Jangada Mines Plc✓@jangadamines
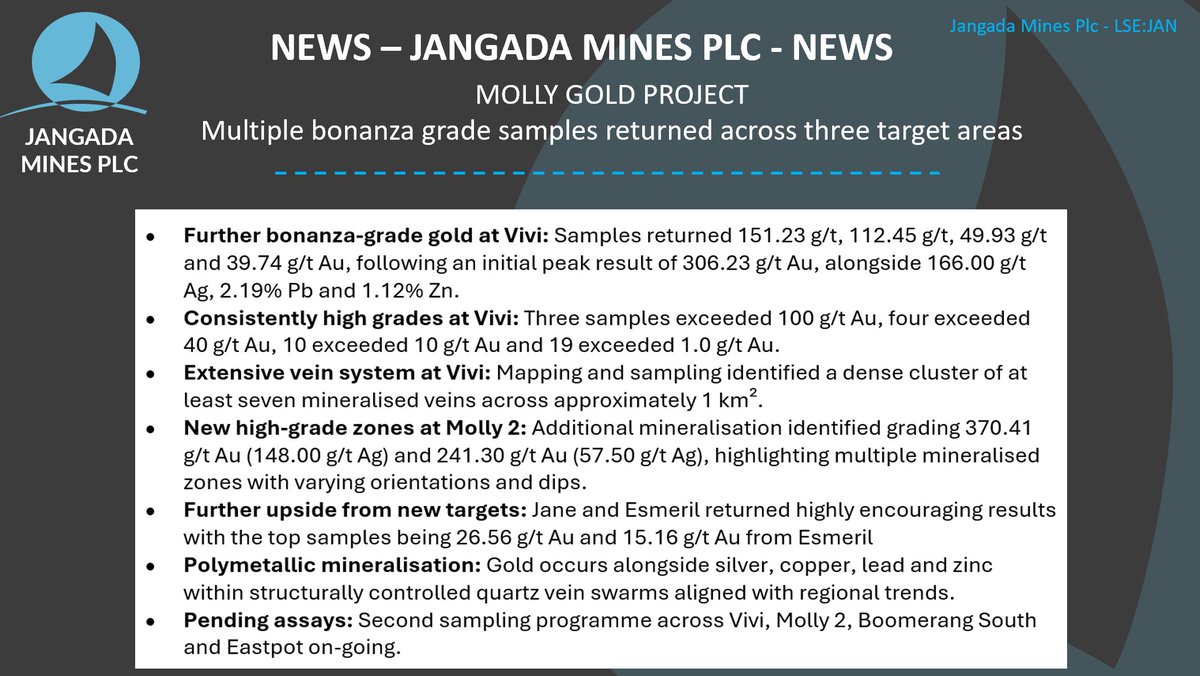
    #JAN Molly Gold Project results have "exceeded our expectations". Bonanza grade from three targets. Up to 370.41 g/t Au at Molly 2 and 151.23 g/t Au at Vivi 7 prospective targets identified across Project Geophysics interpretation nearing completion; fully funded Phase 2 drilling nearly complete Consistently high grades, alongside associated silver, copper, lead and zinc mineralisation, highlight the potential for an extensive, structurally controlled mineralised system #mining #gold #goldequities
    Download
    2514848
  2. Boots✓@JaronEnnis
    Miles in the bag ✅🏃🏾‍♂️💨 #Easy 🤑 #Jan👑 it’s go time 😈 on #Showtime📺⭐️💫 30-0 coming soon🐺⚰️🙏🏾❗️
    2022286
  3. 願望是當李始娟的領帶🦌@barista_somnia
    ฉันตื่นเต้นมากจนมือสั่นไม่หยุดเลยค่ะ พอได้เห็นคุณใกล้ๆ แบบนี้... คุณสวยจริงๆ เลยนะ! 💕 ไว้เจอกันที่คอนเสิร์ตในไทยนะคะ! ระหว่างนี้ ดูแลตัวเองดีๆ ด้วยนะ 🥹🤙🏻 #jan #jingjingyu #janjingiing #BBFanFest2026inKaohsiung
    Download
    00026
  4. Gabriele Berton✓@gabriberton
    Ok my turn to be brave for the good of the community Not sure who needs to hear it, but usually models with JEPA in their title are bad. Like LeJepa is much worse than DINO in practice Pretty papers, fancy math, bad results V-JEPA 2.1 is probably the only exception [1/2]
    Gabriele Berton @gabriberton
    Can we please have more posts like this one? Too many people are afraid to openly criticize posts and papers, and that really hurts the community and lets bad ideas spread fast Thank you @giffmana for saving me (and thousands other people) an hour of my time
    261842150.6K
  5. Gabriele Berton✓@gabriberton
    Can we please have more posts like this one? Too many people are afraid to openly criticize posts and papers, and that really hurts the community and lets bad ideas spread fast Thank you @giffmana for saving me (and thousands other people) an hour of my time
    5526448.7K
  6. TimDarcet@TimDarcet
    @ylecun
    @ylecun @gabriberton Honest question, since when do you consider JEAs to be JEPAs? As far as I can remember you started talking about JEPAs rather in opposition to JEAs, not as a term that encompasses both. If we include JEAs in JEPAs, then JEPA becomes a bit of a vague term just meaning "latent SSL"
    20171.8K
  7. Yann LeCun✓@ylecun
    @TimDarcet
    The P in JEPA stands for predictive. The main distinction is not between JEA and JEPA, but between Joint Embedding (predictive or not) and generative architectures. Whether a predictor is necessary depends on the task. Given observations x and y (y being available only during training), a generative architectures predicts y from x. The loss is the divergence between y and its prediction: L = divergence(y, pred(enc(x)) ) A JEA encodes y as well and minimizes the divergence between the representations of x and y, while preventing collapse: L = divergence( enc(y), enc(x) ) + R( enc(y), enc(x) ) Where R is the anti-collapse regularizer, which may be computed over a batch of samples. JEA are used when the prediction has no particular direction, i.e. when x and y are different views of the same scene. The idea for JEA is very old. Becker and Hinton proposed a simple model in 1989 where the anticollapse was based on information maximization. Schmidhuber had a version in 1992 based on redundancy minimization. At NIPS 1993, I proposed Siamese nets, which was a contrastive method to train JEA. Such contrastive methods gained popu.arity after Google's SimCLR paper in 2020. In 2021, Stéphane Deny in my group proposed the Barlow Twins redundancy reduction regularizer, which seemed to work at scale. This was shortly followed by VICReg by Adrien Bardes, Jean Ponce, and me, and last year by SIGReg by Randall Balestriero and me. DINO is a JEA method that comes from a long string of papers from Piotr Bojanowski's group at FAIR-Paris, starting with Noise as Targets (2017), Deep Clustering (2018-2020), and DINO v1-v3 which are contrastive between clusters, not samples. JEPA adds a predictor, which is useful when the prediction is non-symetric. For example, when x is a degraded/corrupted version of y, or when x is a present observation and y a future observation (temporal prediction). The loss is: L = divergence( enc(y), pred(enc(x)) ) + R( enc(y), enc(x) ) All of these models can be augmented by an action variable a, fed to the predictor, encoding an action, intervention, or transformation to produce y from x. This turns the system into a "world model". In a JEPA, the loss becomes L = divergence( enc(y), pred(enc(x), a) ) + R( enc(y), enc(x) )
    285844136K
  8. Boots✓@JaronEnnis
    Heavy miles in the bag ✅ 🏃🏾‍♂️💨 #Easy🤑 #Jan🌟 30-0 28KOs coming soon 🐺⚰️ 🙏🏾❗️ 👑
    1314226
  9. Boots✓@JaronEnnis
    Couldn’t go back to sleep so I banged my miles out a lil early 😈🔒Nice lil 8 miles in the bag ✅🏃🏾‍♂️💨 #Easy 🤑 #Jan👑 it’s go time on #Showtime📺🌟💫 30-0 28KOs coming soon 🐺⚰️🙏🏾❗️ 🏆
    1918363
  10. Show more posts