Open Closed AI@OpenClosedIO
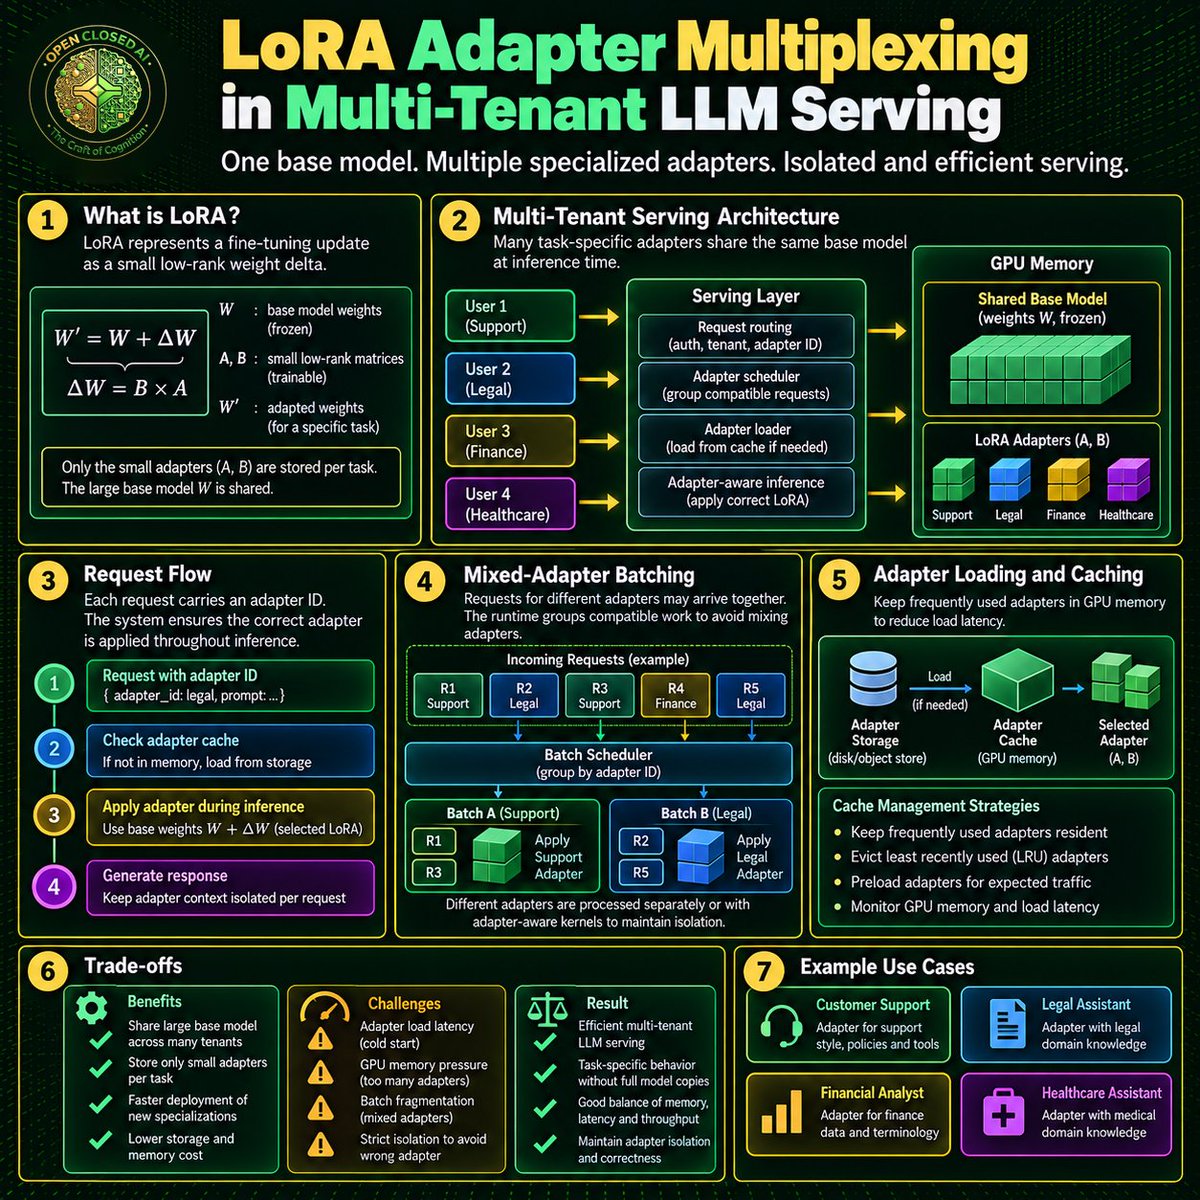
LoRA serving shares base-model weights, but each request must use the right adapter. Mixed-adapter batches need careful scheduling; cold loads cost latency, residency costs GPU memory. #LLMServing #LoRA

0004
Posts with #LLMServing
Public posts on X that use #LLMServing.