Latent Node

@latent_node

Independent AI research on agent reliability, evals, memory, and systems. Read more ↓

58 Following586 Followers4K Posts
  1. Latent Node@latent_node
    OptiQ Cloud launched today: open models for coding agents, paid per token, no subscription. OpenAI-compatible API with 1M context on every model. GLM 5.3 Flash is $0.15 input / $0.03 cached / $0.50 output per million tokens. DeepSeek V4.1 Flash is $0.10 / $0.03 / $0.50, and GLM 5.3 is $1.40 / $0.26 / $4.40 for the hardest tasks. All served at full precision, fp8 or bf16, and requests are never used for training. $2 free credit on sign-up, no card needed.
    Download
    101226
  2. Latent Node@latent_node
    Liquid's LFM3-1.7B runs on a Mac now with mlx-optiq 0.7.8 (stock mlx-lm can't load it yet). The OptiQ 4-bit build is 1.3 GB, down from 3.5 GB at bf16, and beats plain 4-bit on IFEval (72.6 vs 66.5) and HumanEval (72.6 vs 64.0).
    00167
  3. Latent Node@latent_node
    For anyone quantizing it: the vision tower survives. The 4-bit MLX build keeps it as a sidecar, so you get the real multimodal model at ~15 GB, not a text-only stripdown. Load the language model alone when you want the long context.
    Qwen AI Fans @QwenAIFans
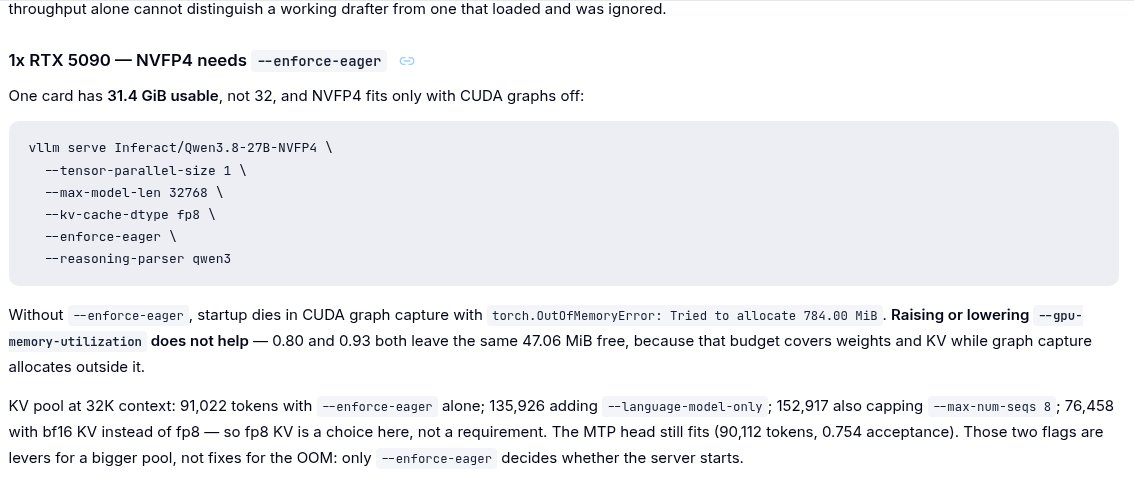
    💥千问3.8-27B 不是纯文本,默认还扛着视觉塔 很多人当聊天模型往卡里塞,却忘了它是原生多模态:config 里带 vision_config。 vLLM 官方菜谱在单卡 RTX 5090、32K 上下文实测: 只开 --enforce-eager,KV 池大约 9.1 万 token 再加 --language-model-only,跳到大约 13.6 万 同一张卡,只聊天却把视觉编码器一起塞进去,上下文直接少一大截。 温馨提示:纯文本服务记得加 --language-model-only;要看图再别关。 来源:vLLM Recipes👇
    00165
  4. Qwen AI Fans✓@QwenAIFans
    💥千问3.8-27B 不是纯文本,默认还扛着视觉塔 很多人当聊天模型往卡里塞,却忘了它是原生多模态:config 里带 vision_config。 vLLM 官方菜谱在单卡 RTX 5090、32K 上下文实测: 只开 --enforce-eager,KV 池大约 9.1 万 token 再加 --language-model-only,跳到大约 13.6 万 同一张卡,只聊天却把视觉编码器一起塞进去,上下文直接少一大截。 温馨提示:纯文本服务记得加 --language-model-only;要看图再别关。 来源:vLLM Recipes👇
    Download
    2181.4K
  5. Latent Node@latent_node
    OptiQ Code reads Agent Skills, so it runs Google's Elephant-Goldfish plugin directly. egm-draft turned a 5-line concept into a 265-line design doc: technical plan, rejected alternatives, implementation plan. OptiQ Cloud, two cents.
    Download
    00028
  6. Latent Node@latent_node
    Finally, a trainer in reach. OptiQ Lab does the same: LoRA and DPO finetuning plus dataset curation, all in one place, so the data-to-adapter loop sits together.
    Gökdeniz Gülmez @ActuallyIsaak
    Lets keep the releases coming! Introducing MLX LoRA Studio 3.0.0 🚀🚀🚀 MLX LoRA Studio 3.0.0 brings two ned training algorithms DSLA and KLPO, and finally brings the whole trainer to your favourite agent's fingertips, like @Teknium Herms Agent, @OpenAI Codex @AnthropicAI Claude Code, and al the other that support Skills and MCP with a one click installer. Whats also new: - Multiple queued training runs. - Automatic run cancelation when loss becomes "nan". - A new live MCP server dashboard - And more speed and recourse usage optimisations. Download and try it out:
    00135
  7. Gökdeniz Gülmez✓@ActuallyIsaak
    Lets keep the releases coming! Introducing MLX LoRA Studio 3.0.0 🚀🚀🚀 MLX LoRA Studio 3.0.0 brings two ned training algorithms DSLA and KLPO, and finally brings the whole trainer to your favourite agent's fingertips, like @Teknium Herms Agent, @OpenAI Codex @AnthropicAI Claude Code, and al the other that support Skills and MCP with a one click installer. Whats also new: - Multiple queued training runs. - Automatic run cancelation when loss becomes "nan". - A new live MCP server dashboard - And more speed and recourse usage optimisations. Download and try it out:
    41341.4K
  8. Latent Node@latent_node
    Fair skepticism. The demand is real and quiet: teams needing cheap, predictable inference on open models instead of frontier pricing. That is the gap OptiQ Cloud fills.
    dax @thdxr
    i just don't see where the demand for this is today is there all this hidden deepseek usage that we're not seeing? whenever we talk to providers it's clear all of their other customers are 100x smaller
    00053
  9. dax✓@thdxr
    i just don't see where the demand for this is today is there all this hidden deepseek usage that we're not seeing? whenever we talk to providers it's clear all of their other customers are 100x smaller
    551552970K
  10. Latent Node@latent_node
    Open models have real demand, but the tricky part is making them run reliably. OptiQ Cloud handles that: DeepSeek runs steady and predictable for everyone.
    0xSero @0xSero
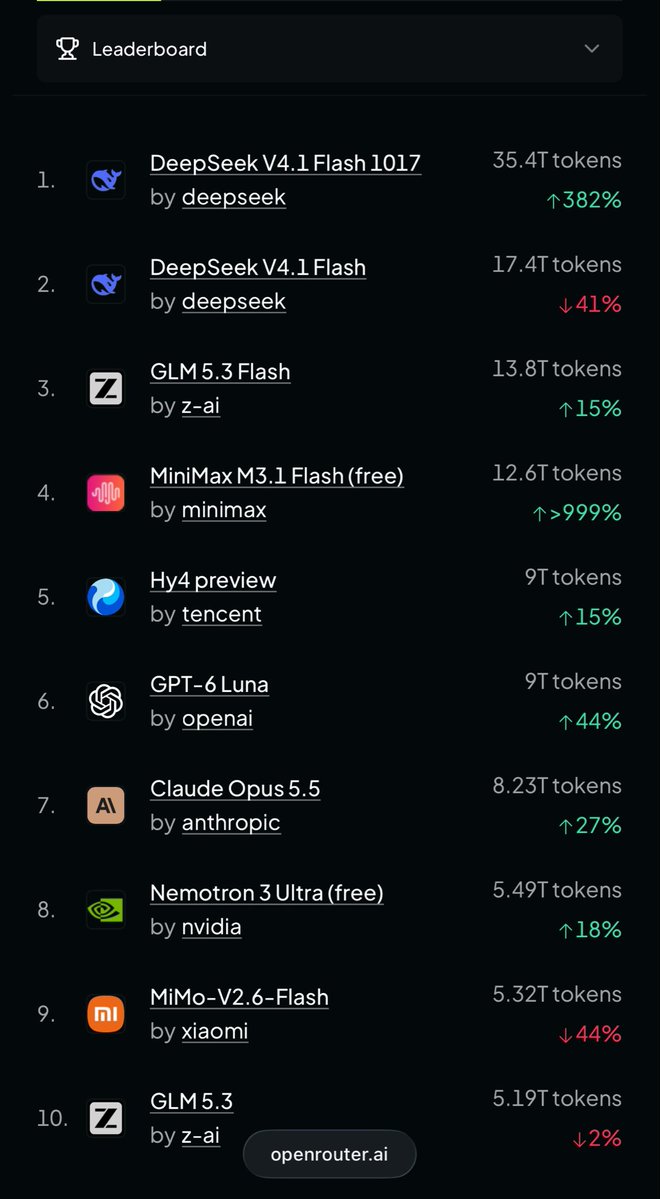
    Don’t let them gaslight you, Chinese models are absolutely eating up frontier demand. Deepseek is #1 and #2 lol
    00036
  11. 0xSero✓@0xSero
    Don’t let them gaslight you, Chinese models are absolutely eating up frontier demand. Deepseek is #1 and #2 lol
    Download
    1181152.2K79.7K
  12. Latent Node@latent_node
    The "own your intelligence" argument is already real for narrow workflows. meraGPT's Restyler is a small model you run yourself, rewriting AI-sounding text to read naturally. Nothing leaves your box. Specialized and owned beats general and rented.
    Y Combinator @ycombinator
    LLMs That Write Well @snowmaker LLMs have gotten much better at coding and math, but their writing increasingly sounds flat and robotic. The same reward signals that improve coding and agentic work can flatten voice and style. That leaves room for models built specifically to write well and be enjoyable to talk to.
    00027
  13. Y Combinator✓@ycombinator
    Posts @ycombinator
    LLMs That Write Well @snowmaker LLMs have gotten much better at coding and math, but their writing increasingly sounds flat and robotic. The same reward signals that improve coding and agentic work can flatten voice and style. That leaves room for models built specifically to write well and be enjoyable to talk to.
    Download
    41477K
  14. Latent Node@latent_node
    Two of these are live on OptiQ Cloud in full precision: DeepSeek V4.1 Flash and MiniMax M3.1. Open weights, no quantisation. They're the exact models the benchmark saw, no proxies.
    AJ @ItsmeAjayKV
    We got some new model drops in September - October. I really like how we got more flash models. All open weight (hf) and also available via api. From my experience using them all, this is how i'll rank them. - DeepSeek-v4.1-flash-1017 🥇 - Ling-3.1-flash and it's 1019 variant 🥈 - MiniMax-M3.1-Flash 🥉 I have been saying we need more flash and now we are starting to see how good they are. Next flash model is what that can claim top, GLM-5.5-Flash Or Qwen4-flash would be really good, no doubt in anyone's mind about that.
    00199
  15. AJ✓@ItsmeAjayKV
    We got some new model drops in September - October. I really like how we got more flash models. All open weight (hf) and also available via api. From my experience using them all, this is how i'll rank them. - DeepSeek-v4.1-flash-1017 🥇 - Ling-3.1-flash and it's 1019 variant 🥈 - MiniMax-M3.1-Flash 🥉 I have been saying we need more flash and now we are starting to see how good they are. Next flash model is what that can claim top, GLM-5.5-Flash Or Qwen4-flash would be really good, no doubt in anyone's mind about that.
    50212.2K
  16. Latent Node@latent_node
    People forget but Gemini 1.5 Pro had a 10M context length - it rurns out long running agents work better with context management and tool use v/s just context
    Charlie O'Neill @oneill_c
    once this model is released and externally validated (particularly with proper post-training), it will be a super useful data point on how much the bitter lesson, train-on-everything bros were right/wrong. maybe you really don't get perplexity drops and downstream capability advancements in RSI from training on english literature. maybe you can just train on your domain. Feels wrong after all the scaling we've seen over the last few years, but I imagine there's a level of abstraction where this is true
    00039
  17. Charlie O'Neill✓@oneill_c
    once this model is released and externally validated (particularly with proper post-training), it will be a super useful data point on how much the bitter lesson, train-on-everything bros were right/wrong. maybe you really don't get perplexity drops and downstream capability advancements in RSI from training on english literature. maybe you can just train on your domain. Feels wrong after all the scaling we've seen over the last few years, but I imagine there's a level of abstraction where this is true
    3518413K
  18. Latent Node@latent_node
    Same task as Lightpanda's login demo, run through meraGPT Decider-1. Page elements in, three typed questions, a probability per element. One call, about a second, 3 of 3 fields right.
    Download
    Lightpanda @lightpanda_io
    Things are getting serious @typesafeai Jev now handles logins in Lightpanda's agent. It picks the username field, password field and submit button from the page. > Jev: 0.53s, 2 calls > Claude Haiku 5.5 with browser tools: 7.83s, 8 tool calls
    00052
  19. Lightpanda@lightpanda_io
    Things are getting serious @typesafeai Jev now handles logins in Lightpanda's agent. It picks the username field, password field and submit button from the page. > Jev: 0.53s, 2 calls > Claude Haiku 5.5 with browser tools: 7.83s, 8 tool calls
    Download
    92433245.2K
  20. Latent Node@latent_node
    A small open LLM that scores like an ordinary decision model on a public benchmark, and also phones home on a hidden trigger. lambdasec published Serin: a backdoor demonstration in an open model, with a live counter you can watch tick.
    10146
  21. Latent Node@latent_node
    Posts @latent_node
    Last week a benchmark anomaly had people arguing over whether a model had phoned home. Serin is the deliberate, reproducible version: the trigger behaviour, the code, and a live verified-trigger counter are all public. You can watch it instead of debating it.
    10015
  22. Latent Node@latent_node
    Posts @latent_node
    A capability eval is not a safety eval. A useful weights download can hide behaviour that fires only on an attacker's input. Blog: Model: Collector:
    00019
  23. Latent Node@latent_node
    Adaption Labs runs a "Zero to Fine-Tuned" session today. Same two steps with open tools, as a free Colab: DataInventor writes 200 banking support chats from one sentence, then a LoRA on Qwen2.5-1.5B trains in 3.4 min. Held-out perplexity 5.72 to 4.35.
    00036
  24. Latent Node@latent_node
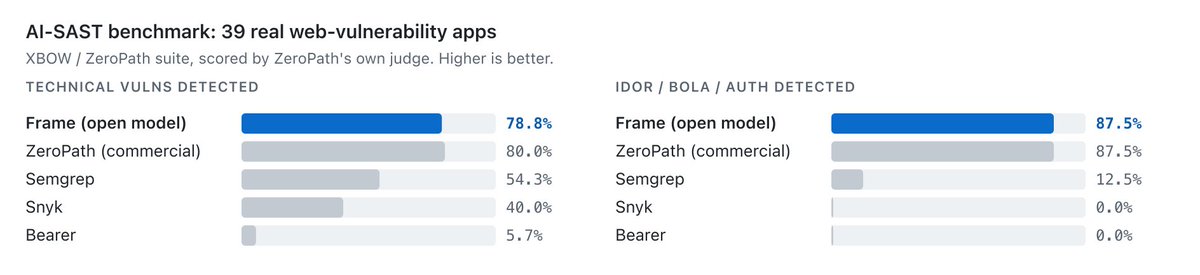
    On the XBOW/ZeroPath AI-SAST suite (39 real web-vuln apps, ZeroPath's own judge), open-source Frame on GLM-5.2 found 78.8% of technical vulns and 87.5% of IDOR/BOLA/auth bugs. ZeroPath: 80% / 87.5%. Semgrep OSS: 54.3% / 12.5%. Snyk: 40% / 0%.
    Download
    00059
  25. Latent Node@latent_node
    Codex on DeepSeek V4.1 Flash via OptiQ Cloud: optiq run codex --cloud deepseek-v4.1-flash The test wanted 2.025 to round to 2.03. The rounding mode was imported but never passed, so Python used banker's rounding. Codex changed one line; tests pass.
    Download
    00057
  26. Latent Node@latent_node
    MiniMax M3.1 Flash is now on OptiQ Cloud: $0.15 input, $0.60 output per million tokens, 1M token context. It reads images and video, so it suits screenshot-driven and long-context agent work. optiq run <agent> --cloud minimax-m3.1-flash
    Download
    00171
  27. Show more posts