Palette is the only enterprise #Kubernetes management platform built for scale in any cloud, bare metal and edge.
Gartner Cool Vendor, CRN Tech Innovator
A few weeks ago, we joined Portworx and IDC to talk about building a resilient retail edge.
If you missed it live, catch Portworx’s recap with clips from all three speakers, from config drift to where to start with AI 👉
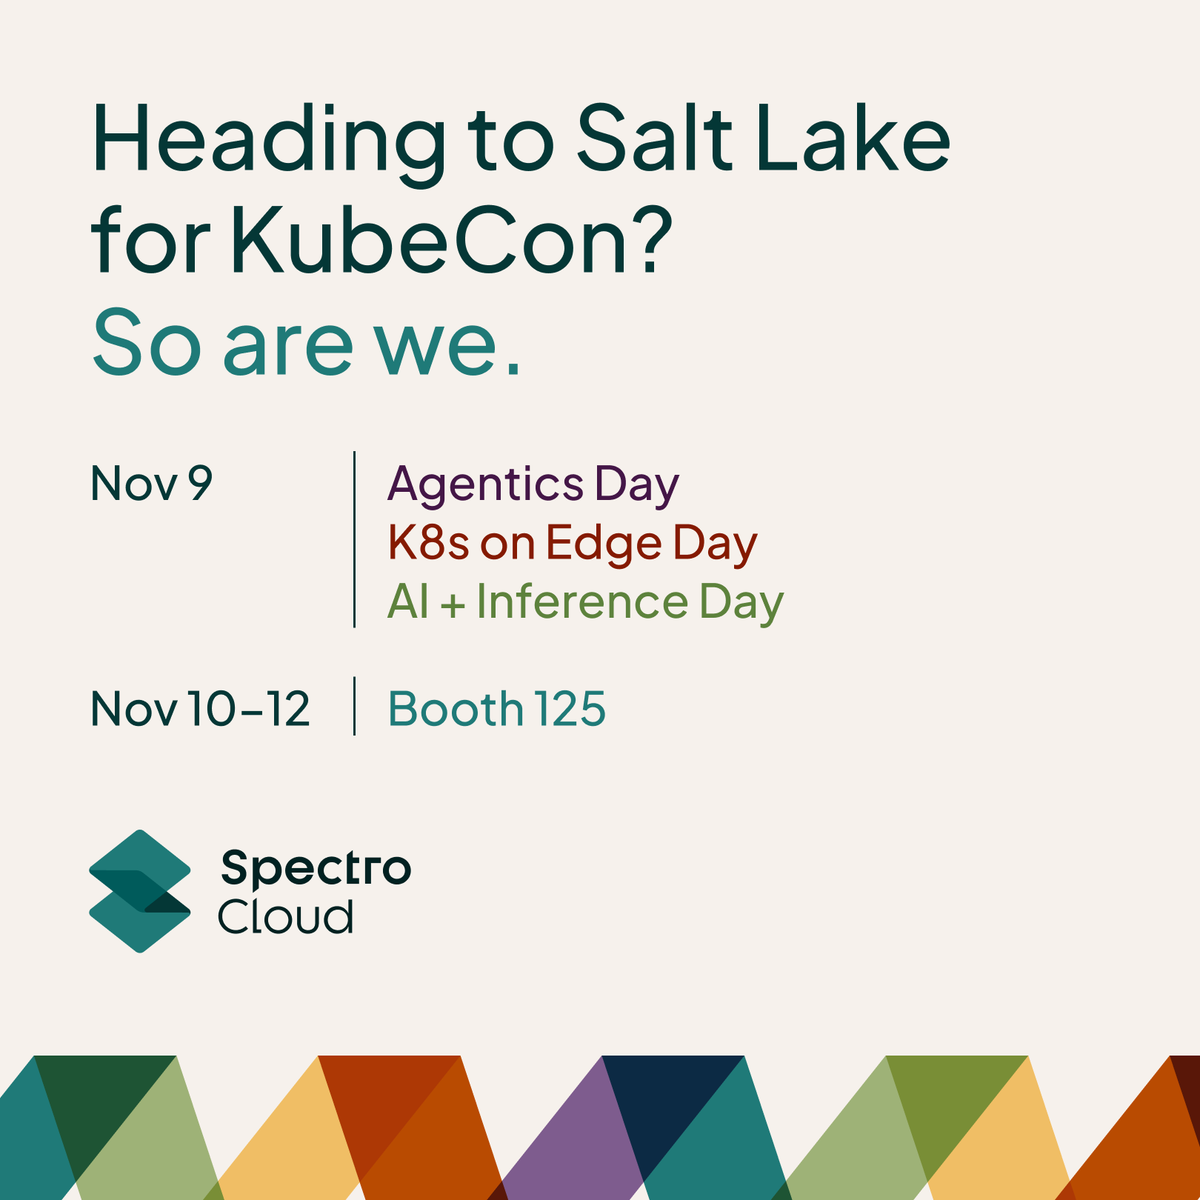
We’re heading back to Salt Lake for KubeCon, and we’re going big! If you’re working on your next infrastructure project, come say hi and see how we can help.
We’ve got a lot going on there, so get all the details, plus how to book a meeting with us 👉
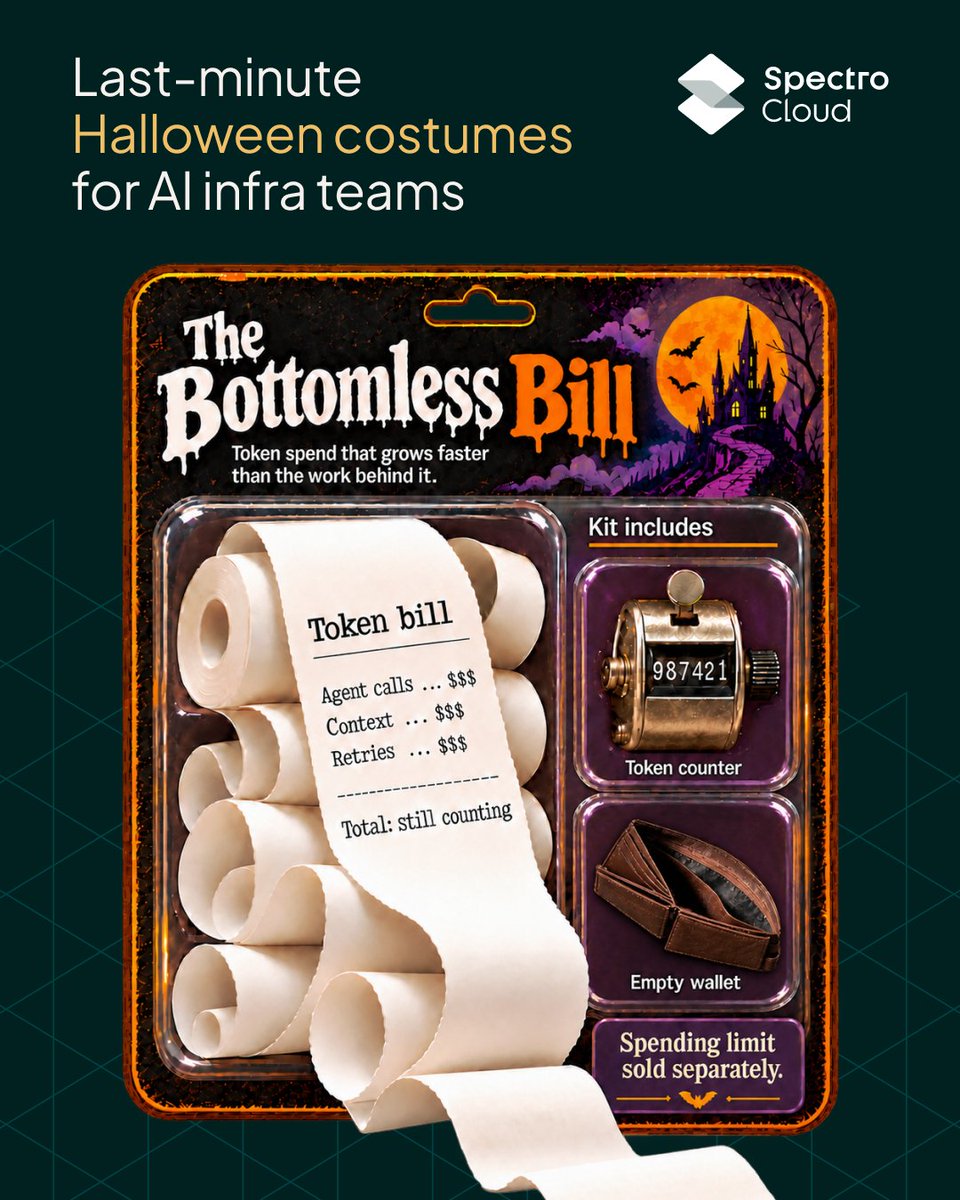
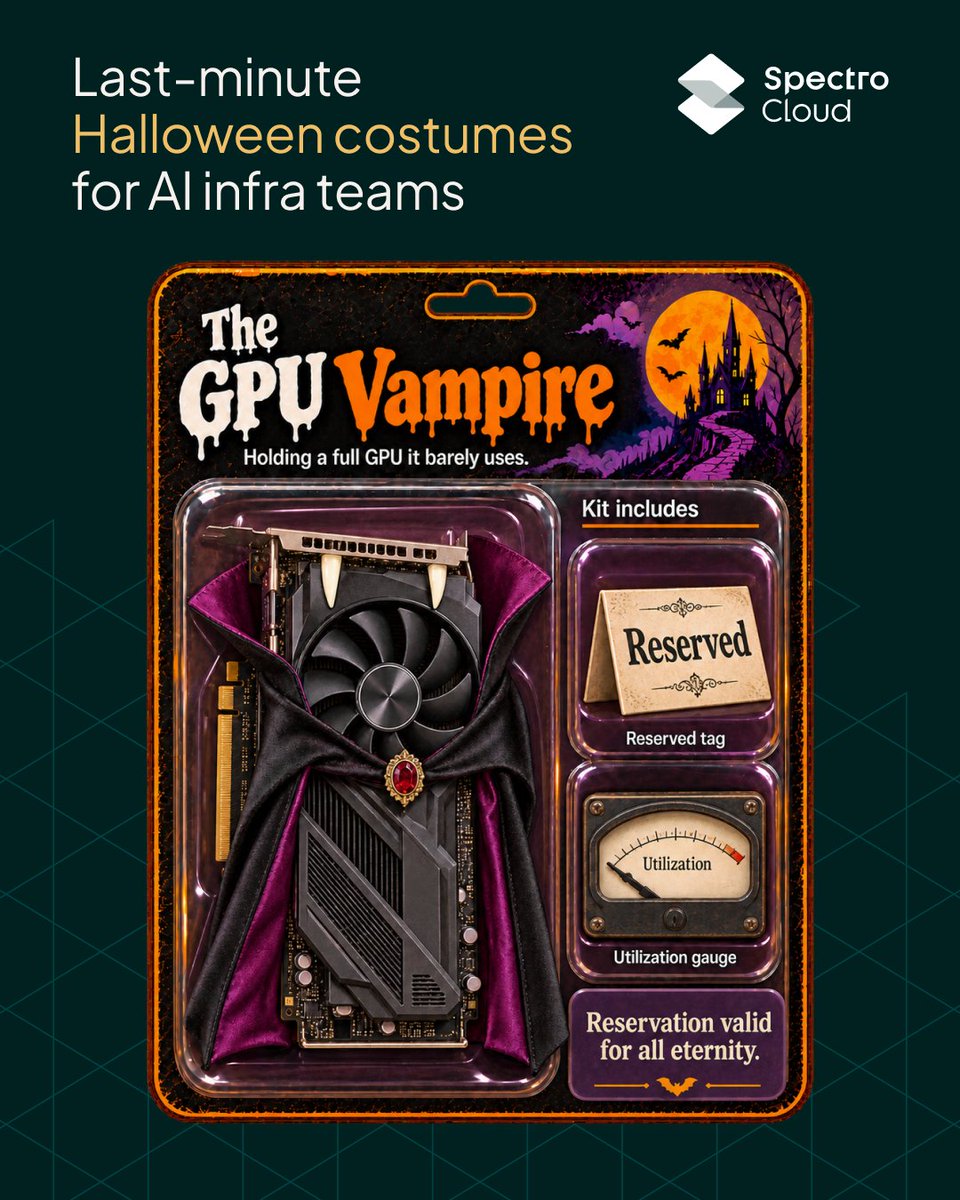
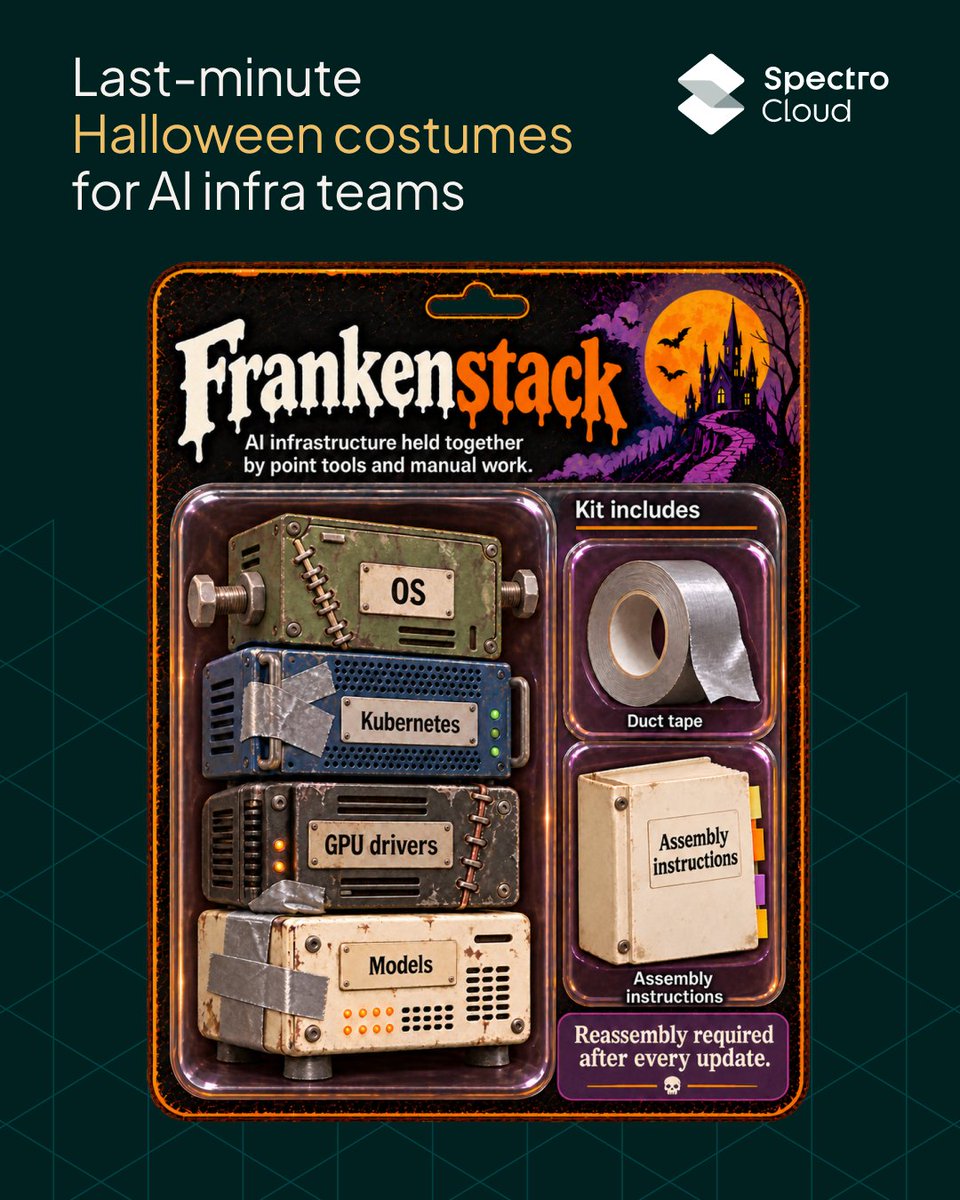
Need some last-minute Halloween inspo? 🎃
We turned your worst AI infrastructure nightmares into costume kits. You’re welcome.
Oh, and viewer discretion is advised. (wait... should we have led with that?)
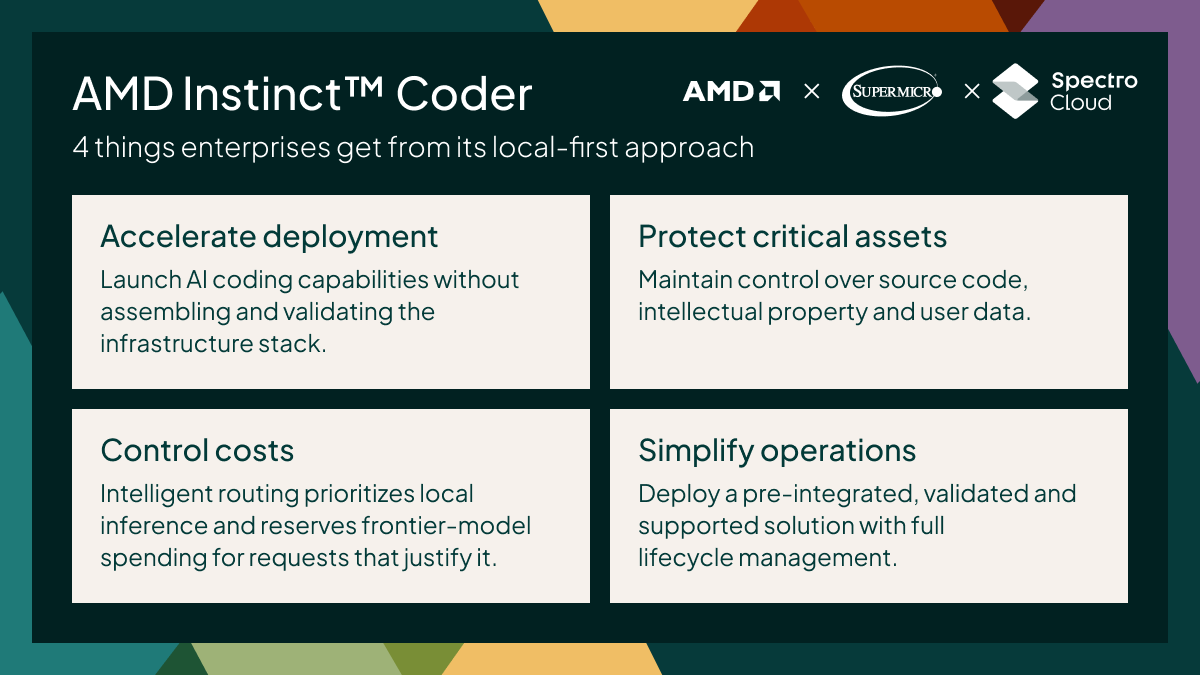
Tuesday, Oct 27, our CTO Saad Malik joins Kumaran Siva and Linda Yang to talk about AMD Instinct™ Coder, our joint turnkey solution that keeps your costs predictable and your source code secure.
Don’t miss it 👉
Share
Copied
Supermicro@Supermicro
Supermicro, @AMD and @spectrocloudinc partnered together to deliver the AMD Instinct™ Coder solution designed to moves suitable inference onto infrastructure the customer controls, while preserving frontier access for the hardest tasks.
Join our webinar and learn how Supermicro AI servers with AMD Instinct™ GPUs, along with Spectro Cloud's PaletteAI Inference Launchpad, deliver a more cost effective, pre-integrated, ready-to-deploy appliance for enterprise agentic coding.
📅Oct 27, 2026
⏰10:00am PT
Save your spot:
We've been saying for a while that local inference can cut your devs' AI coding bill without slowing them down.
This blog brings the receipts, from how we tuned an AMD Instinct Coder box to where it starts costing less than hosted APIs.
Read it here 👉
Quick! Picture physical AI.
*waiting*
If you pictured a shiny humanoid with a face, blame Hollywood.
Meanwhile, plenty of machines that look nothing like us are already on the job.
Read about physical AI already at work & what it takes to make it last 👉
GTC Berlin is a wrap! ⚡
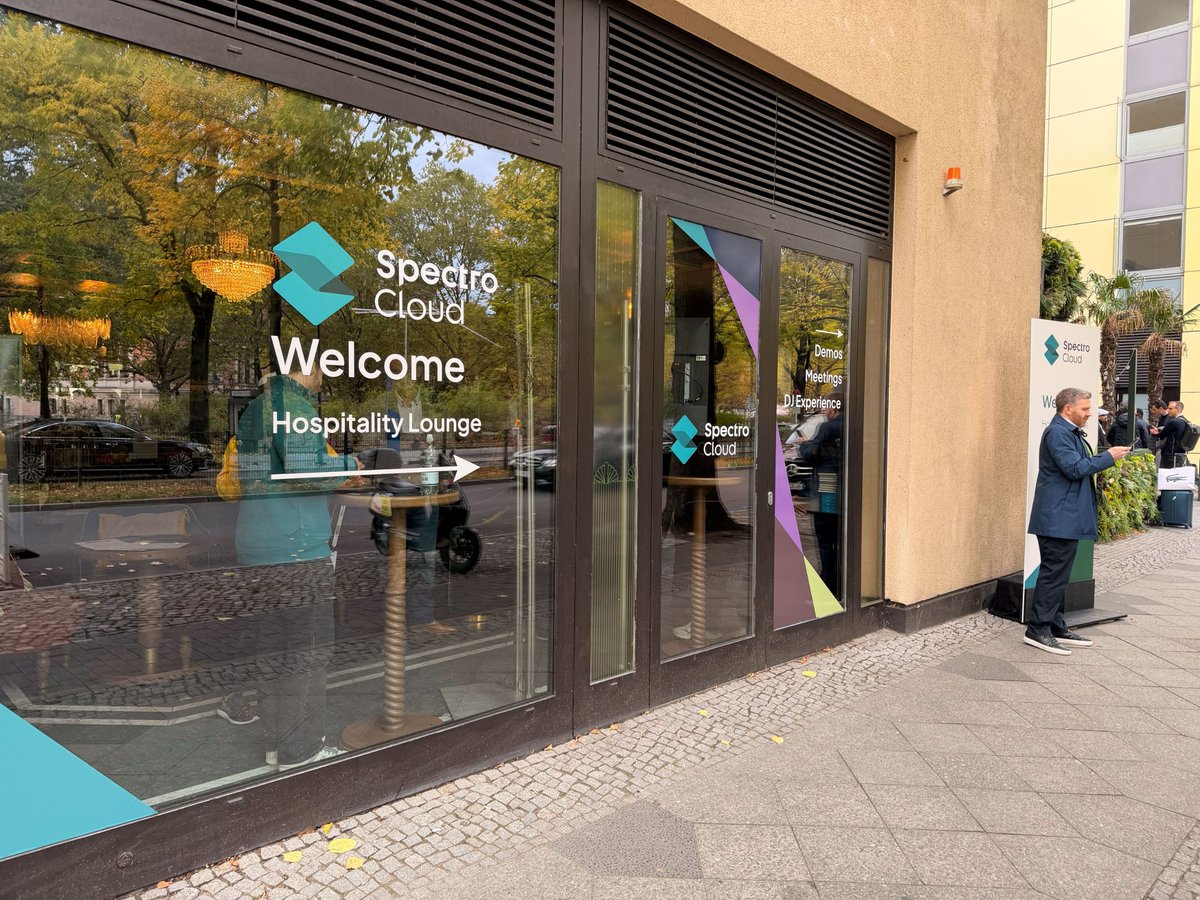
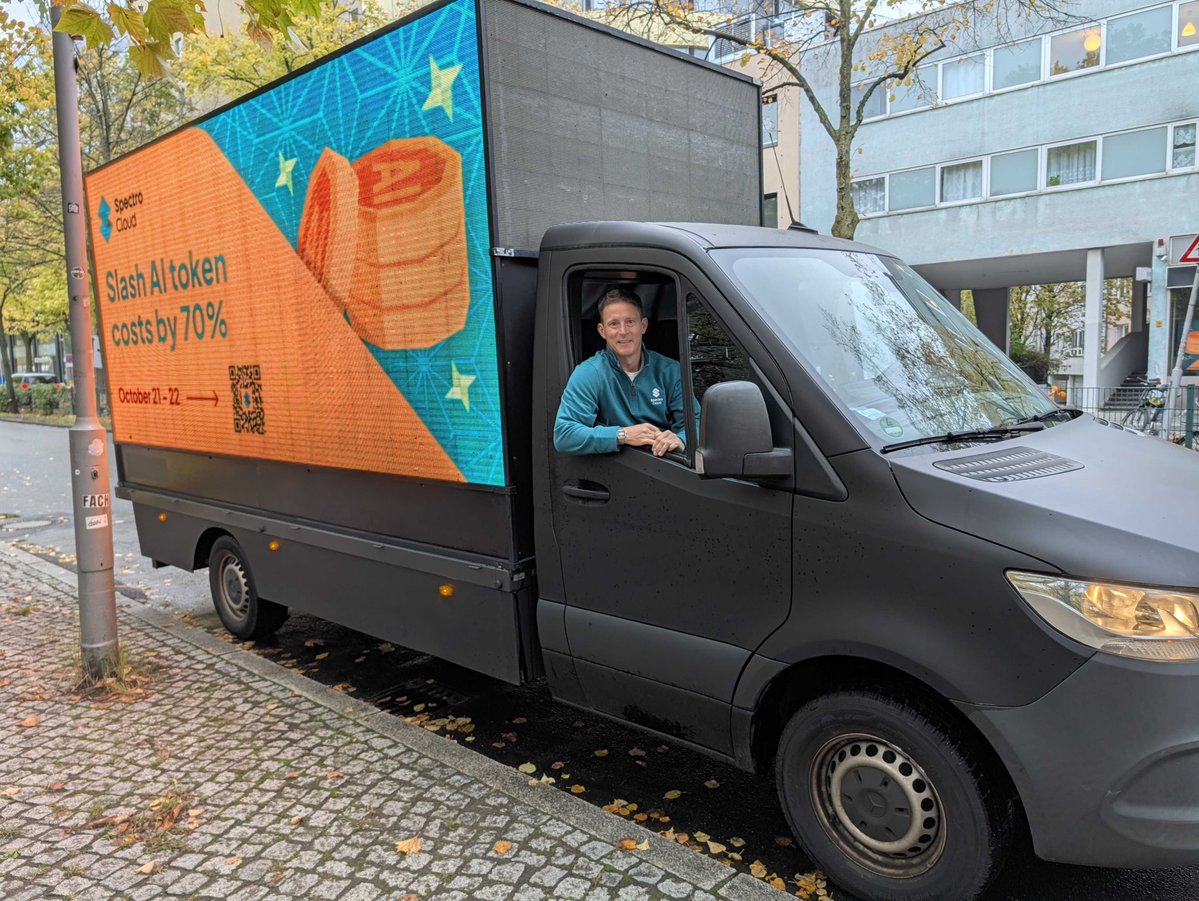
Our team is heading home with a lot of good conversations about AI token spend and local-first inference. Thank you to everyone who spent part of their two days with us at the hospitality suite.
We’re hiring a Senior Software Engineer to own AI inference at scale!
If you enjoy a hard performance problem and have run models in production with engines like vLLM, we’d love to hear from you.
Learn more about the role and apply here 👉
That’s a wrap on day one at GTC Berlin!
Thanks to everyone who came by our hospitality suite to talk token costs and see the demos (and shout-out to our new DJs 🎧).
Now we’re off to the Van Loon with @WEKA, then back at the suite tomorrow from 8am 👉
As an NVIDIA DSX ecosystem partner, we integrated open-source NVIDIA Run:ai into PaletteAI.
Together, we help customers put more of their GPU capacity to work without taking on greater operational complexity.
How it works and how to try it 👉
We’re proud to be an NVIDIA AI Cloud Ready validated partner, and to give neoclouds, sovereign AI clouds, and AI-as-a-service businesses the reliability, consistency, and scale they need to succeed in the long run.
More about the validation 👉
GTC Berlin is right around the corner, and we'll be waiting for you at Gibson Bar!
We’re bringing it all: a smart crew, insightful demos, yummy canapés and a live DJ experience. And on the 21st, you can join us and @WEKA aboard the Van Loon.
Our plans 👉
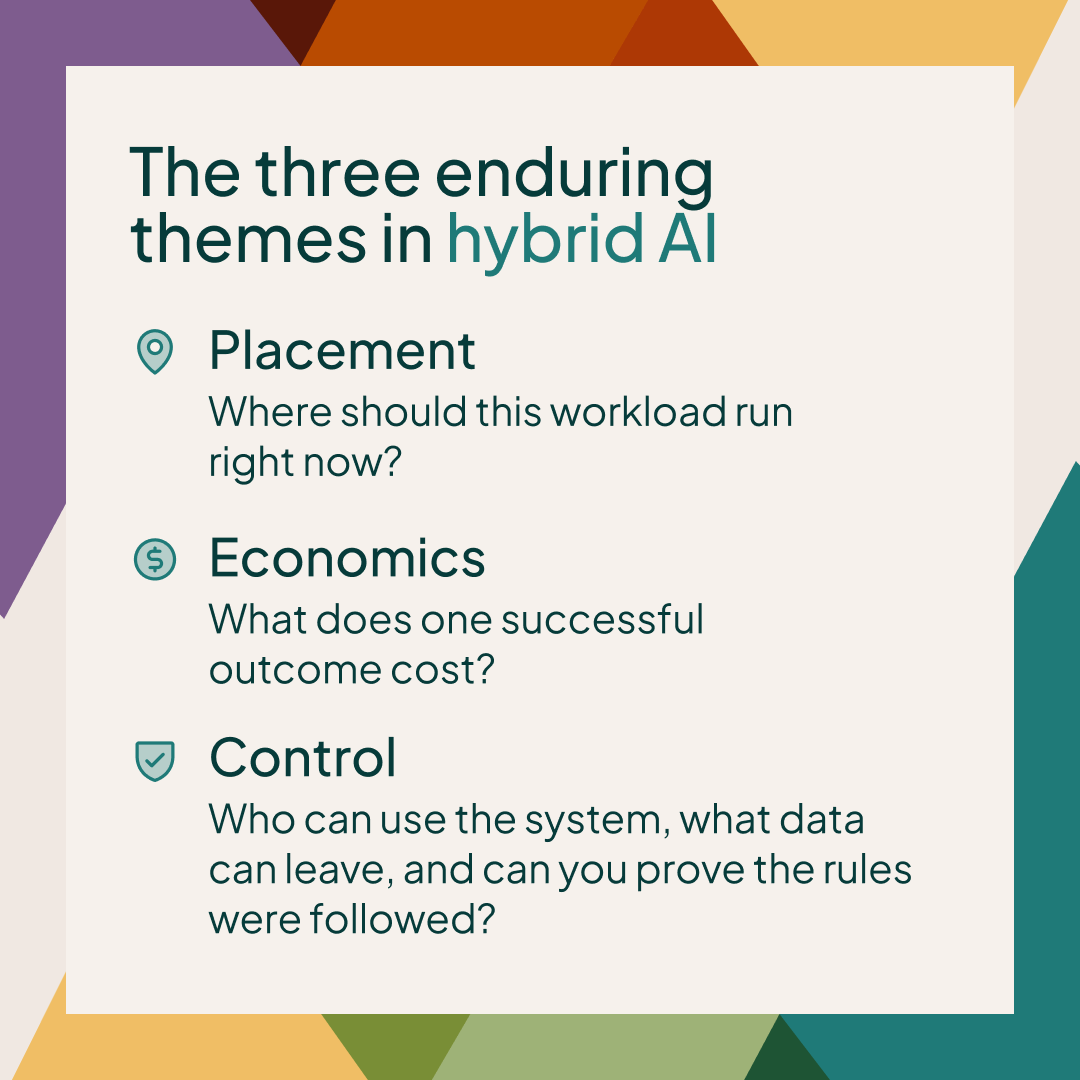
Hybrid AI is going to keep evolving, but three themes will persist: placement, economics and control.
And they can’t be separated. The lowest-cost endpoint is irrelevant if it can’t meet the quality threshold.
Our CEO Tenry Fu goes deeper 👉
Getting AI factories live is only the start. Running them for years takes reliability, consistency, and scale, which is the foundation PaletteAI provides.
We're proud to be an NVIDIA AI Cloud Ready Validated Partner, and we talk more about it here 👉
Together with @EverpureData, we built a two-node + witness setup for edge K8s HA. Two nodes run your containers and VMs, Portworx keeps their data in sync, and a lightweight witness casts the third quorum vote without hosting app data.
More details 👉
Choosing an endpoint is only the starting point. (Pun intended 😉)
A router can pick the endpoint, but someone still has to operate what sits behind it. That’s why you need a control plane for hybrid AI infrastructure.
Our CEO Tenry Fu explains why 👉
Did you know we're an AWS Manufacturing and Industrial Competency Partner? ⚙️
Well, you do now. And that makes five AWS competencies for us, alongside Retail, Consumer Goods, Containers and Government.
See everything we do with AWS 👉
Local inference is taking over Gibson Bar for #NVIDIAGTC Berlin.
If your token bill is getting out of hand, come talk to our team at our hospitality suite, just 4 mins from STATION-Berlin. There'll be live demos and canapés!
See our plans & book a 1:1 👉
We are happy to join @nvidia in today's launch of NVIDIA Run:ai as an open-source platform!
Together, we help customers put more of their GPU capacity to work without taking on greater operational complexity.
How it works and how to try it 👉
When inference runs on your own AMD Instinct GPUs, you can set every request to follow your routing policy, meter every token by team and use case, and use quotas to keep adoption from outrunning your controls.
Learn more about AMD Instinct™ Coder at