StarSling (YC X25)✓

@starslingdev

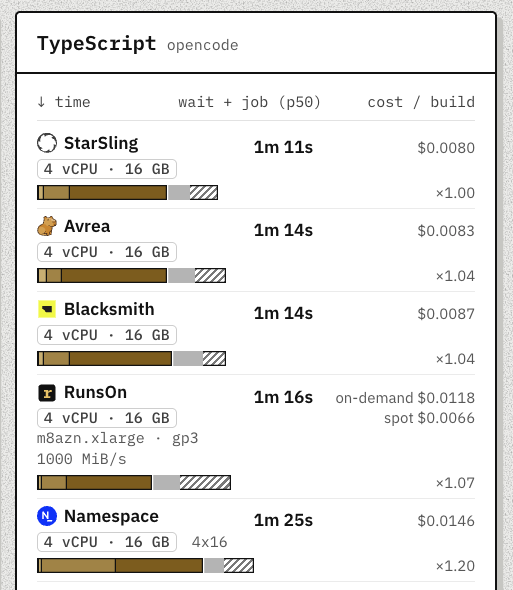
Agent-native CI. Trusted by @mastra, @better_auth, and other AI-first companies. Backed by @ycombinator. Free skills: https://t.co/jtE4GjY7xn

17 Following377 Followers113 Posts
  1. StarSling (YC X25)✓@starslingdev
    StarSling (YC X25)
    RT @yonasbe: “Overall tests are now about 4x faster” @starslingdev 🚀
    1906.eth | Harold Hughes @OneBandwagonFan
    Shout-out to @starslingdev 🚀 We moved Divi's CI over and our test runs are now ~4x faster, down to 6–7 minutes. Faster feedback = faster shipping for our users (investors). If your team lives in GitHub Actions, check them out. h/t @yonasbe and team! My CTO sent me this:
    0103
  2. 1906.eth | Harold Hughes@OneBandwagonFan
    Shout-out to @starslingdev 🚀 We moved Divi's CI over and our test runs are now ~4x faster, down to 6–7 minutes. Faster feedback = faster shipping for our users (investors). If your team lives in GitHub Actions, check them out. h/t @yonasbe and team! My CTO sent me this:
    Download
    103590
  3. StarSling (YC X25)✓@starslingdev
    StarSling (YC X25)
    RT @yonasbe: Yup. Most teams trying to cut down their CI don't realize that it's not just about faster runners. Lots of optimizations to do across your workflows and tests. Anthropic's approach: Linear's approach:
    Mihail Eric @mihail_eric
    Anthropic, Linear, and many other companies are all hitting the same wall in AI software development: CI For twenty years CI was designed for human output. Now a five-person team can generate the code of a 50-person team, and all of it lands at the top of the CI pipeline in seconds. What this means: - 𝗢𝗽𝘁𝗶𝗺𝗶𝘇𝗶𝗻𝗴 𝗶𝘀 𝗮 𝘀𝘁𝗮𝗰𝗸 𝗼𝗳 𝗽𝗮𝗽𝗲𝗿𝗰𝘂𝘁𝘀. Anecdotally one team quadrupled its tests and still got PR waits down to about 5 minutes with a dozen small fixes: tsgo instead of tsc, oxlint, sparse checkouts, preinstalled dependencies, balanced test shards. - 𝗦𝗺𝗮𝗿𝘁 𝘁𝗲𝘀𝘁 𝘀𝗲𝗹𝗲𝗰𝘁𝗶𝗼𝗻 𝘄𝗼𝗿𝗸𝘀 𝘂𝗽 𝘁𝗼 𝗮 𝗽𝗼𝗶𝗻𝘁. Doing some form of test impact analysis so each change only runs the tests it touches is helpful. Even such smart selection systems get strained past a certain job volume. - 𝗖𝗜 𝗯𝗲𝗰𝗼𝗺𝗲𝘀 𝘁𝗵𝗲 𝘃𝗲𝗿𝗶𝗳𝗶𝗰𝗮𝘁𝗶𝗼𝗻 𝗹𝗮𝘆𝗲𝗿: engineers can't review all the code agents write, even with AI reviewers. CI is where trust in that code gets established. It’s clear writing code stopped being the bottleneck. Now the systems to verify their correctness at scale are a new chokepoint.
    01102
  4. Mihail Eric✓@mihail_eric
    Anthropic, Linear, and many other companies are all hitting the same wall in AI software development: CI For twenty years CI was designed for human output. Now a five-person team can generate the code of a 50-person team, and all of it lands at the top of the CI pipeline in seconds. What this means: - 𝗢𝗽𝘁𝗶𝗺𝗶𝘇𝗶𝗻𝗴 𝗶𝘀 𝗮 𝘀𝘁𝗮𝗰𝗸 𝗼𝗳 𝗽𝗮𝗽𝗲𝗿𝗰𝘂𝘁𝘀. Anecdotally one team quadrupled its tests and still got PR waits down to about 5 minutes with a dozen small fixes: tsgo instead of tsc, oxlint, sparse checkouts, preinstalled dependencies, balanced test shards. - 𝗦𝗺𝗮𝗿𝘁 𝘁𝗲𝘀𝘁 𝘀𝗲𝗹𝗲𝗰𝘁𝗶𝗼𝗻 𝘄𝗼𝗿𝗸𝘀 𝘂𝗽 𝘁𝗼 𝗮 𝗽𝗼𝗶𝗻𝘁. Doing some form of test impact analysis so each change only runs the tests it touches is helpful. Even such smart selection systems get strained past a certain job volume. - 𝗖𝗜 𝗯𝗲𝗰𝗼𝗺𝗲𝘀 𝘁𝗵𝗲 𝘃𝗲𝗿𝗶𝗳𝗶𝗰𝗮𝘁𝗶𝗼𝗻 𝗹𝗮𝘆𝗲𝗿: engineers can't review all the code agents write, even with AI reviewers. CI is where trust in that code gets established. It’s clear writing code stopped being the bottleneck. Now the systems to verify their correctness at scale are a new chokepoint.
    31816533.9K
  5. StarSling (YC X25)✓@starslingdev
    CI Playbooks based on lessons from @linear, @AnthropicAI, and @OpenAI (with agent prompts + skills)👇 Linear: Anthropic: OpenAI:
    Yonas Beshawred @yonasbe
    OpenAI's CI playbook (for GitHub Actions): @OpenAIDevs cut their median CI from ~10 min to 4.5 min by asking Codex what to fix. You can do the same with your agent. We went through 855 CI workflow changes across 20 of @OpenAI's most popular repos, 120 PRs, and 33 blog posts and guides. Here's what they shipped: 1. Rank fixes by minutes saved, from your own run history 2. Fix flaky tests that fail, then pass on the same commit 3. Mock the slow dependency: a 63-test suite went from 592.6s to 29.8s 4. Run tests in fewer processes: 8m49s to 21s 5. Install prebuilt packages (plus cache fixes): 10m42s to 2m12s 6. Balance shards by measured test time: 22m26s to ~7m29s 7. Build once, test on every shard 8. Measure test concurrency: 8 jobs beat 12 9. Drop caches that cost more than they save: 66,295s of saves for 1,515s of restores 10. Put the long pole on a faster runner Each one is a copy-paste prompt for your agent:
    015250
  6. StarSling (YC X25)✓@starslingdev
    StarSling (YC X25)
    RT @yonasbe: Adaptive Compute in action 🏆
    Download
    Daniel Worku @dbworku
    Introducing Adaptive Compute ⚡️ Up to 2.3x faster GitHub Actions, with no workflow changes. Intelligent routing, instant failover and temporary resource boosts. (+25% vCPU and +50% RAM)
    0104
  7. StarSling (YC X25)✓@starslingdev
    StarSling (YC X25)
    RT @yonasbe: OpenAI's CI playbook (for GitHub Actions): @OpenAIDevs cut their median CI from ~10 min to 4.5 min by asking Codex what to fix. You can do the same with your agent. We went through 855 CI workflow changes across 20 of @OpenAI's most popular repos, 120 PRs, and 33 blog posts and guides. Here's what they shipped: 1. Rank fixes by minutes saved, from your own run history 2. Fix flaky tests that fail, then pass on the same commit 3. Mock the slow dependency: a 63-test suite went from 592.6s to 29.8s 4. Run tests in fewer processes: 8m49s to 21s 5. Install prebuilt packages (plus cache fixes): 10m42s to 2m12s 6. Balance shards by measured test time: 22m26s to ~7m29s 7. Build once, test on every shard 8. Measure test concurrency: 8 jobs beat 12 9. Drop caches that cost more than they save: 66,295s of saves for 1,515s of restores 10. Put the long pole on a faster runner Each one is a copy-paste prompt for your agent:
    0304
  8. StarSling (YC X25)✓@starslingdev
    OpenAI's CI optimizations, as prompts for your agent:
    Yonas Beshawred @yonasbe
    OpenAI's CI playbook (for GitHub Actions): @OpenAIDevs cut their median CI from ~10 min to 4.5 min by asking Codex what to fix. You can do the same with your agent. We went through 855 CI workflow changes across 20 of @OpenAI's most popular repos, 120 PRs, and 33 blog posts and guides. Here's what they shipped: 1. Rank fixes by minutes saved, from your own run history 2. Fix flaky tests that fail, then pass on the same commit 3. Mock the slow dependency: a 63-test suite went from 592.6s to 29.8s 4. Run tests in fewer processes: 8m49s to 21s 5. Install prebuilt packages (plus cache fixes): 10m42s to 2m12s 6. Balance shards by measured test time: 22m26s to ~7m29s 7. Build once, test on every shard 8. Measure test concurrency: 8 jobs beat 12 9. Drop caches that cost more than they save: 66,295s of saves for 1,515s of restores 10. Put the long pole on a faster runner Each one is a copy-paste prompt for your agent:
    002140
  9. StarSling (YC X25)✓@starslingdev
    StarSling (YC X25)
    RT @yonasbe: Faster runners make CI jobs faster. They don't make you run fewer of them. Where CI time actually goes (and the fix for each): 1. Compute: the job itself. Faster machines help here. 2. Waiting: queues from concurrency caps. A faster machine doesn't shorten a queue. 3. Setup: checkout, installs, cache restores. Shallow checkouts and warm caches. 4. Redundant work: runs for commits you already replaced, the full suite for a docs change. cancel-in-progress, path filters, affected tests only. 5. Idle time: fixed sleeps, healthchecks that wait on an open port instead of a ready database. Most teams only fix #1. The bigger wins are usually in 2–5, and they live in your workflow files, not your hardware.
    Yonas Beshawred @yonasbe
    Levels of CI - a full guide for making your GitHub Actions cheaper and faster 👇🏾 Level 1: use Actions cache cache every dependency install, keyed on the lockfile so it actually hits. 🔗 Docs: 🔗 Agent prompt: Level 2: swap runners get faster, cheaper machines by changing the runs-on label. Your workflows, triggers, and checks stay exactly as they are. 🔗 Runner comparison: 🔗 Right-size runners: 🔗 Cut queue time: 🔗 Runners that automatically adapt: Level 3: optimize your tests and workflows cache dependencies and builds, split long suites across parallel jobs, skip work a change can't affect, cancel runs a newer push replaced. Skills: 🔗 ci-speedup (@starslingdev): 🔗 ci-cd-and-automation (@addyosmani): 🔗 test-audit (@steipete): Posts and guides: 🔗 18 best practices (agent-friendly): 🔗 16 optimization recipes (agent-friendly): 🔗 Where your CI money goes (prompt): 🔗 Why your CI is slow (prompt): Do all the above, or just let StarSling agents ship PRs like these for you: Level 4: switch CI engines Meta and Google built Buck2 ( and Bazel ( for aggressive caching and test selection, so each PR runs only the tests relevant to its change. A custom engine controls the whole execution layer, which gives you a much larger surface to optimize. Options for engines: 🔗 Dagger ( 🔗 Buildkite ( 🔗 Depot CI ( 🔗 CircleCI ( 🔗 GitLab CI ( Level 5: throw out CI engines entirely A few different approaches are being discussed that were never possible pre-AI. This is the future: 1. Agent-driven test selection. "My plan is to let codex decide which tests actually need to run and drastically nix CI and run tests hourly." @steipete ( 2. CI after merge with auto-remediation. "have something that is running actual functional tests off of your master branch on a cron, and then if any regressions occur, automatically have an LLM bisect and figure out the bug and then patch it..." @yacineMTB ( 3. Agents replace CI: a verification agent that writes just-in-time tests for each change. @Meta's research: Most teams are somewhere between Level 2 and 3. Figure out which level you're at and give your agent this full post:
    0303
  10. StarSling (YC X25)✓@starslingdev
    StarSling (YC X25)
    RT @yonasbe: Anthropic's CI playbook (give this to your agent) @AnthropicAI's CI jobs grew 25x in six months, so they built their own test selection system. The same ideas work on GitHub Actions: 1. Run only affected tests: Anthropic picks each change's tests from past results and package relevance. On GHA, use the dependency graph from Turborepo, Nx, Bazel, Gradle, Vitest or Jest on PRs. 2. Keep the full suite where it counts: run everything on main and in the merge queue, so skipped tests still get caught before deploy. 3. Skip workflows a change can't affect: path filters, plus job-level ifs so required checks don't hang waiting. 4. Run CI once per change: drop the push + pull_request double trigger, and stop rerunning on things like PR title edits unless a check reads them. 5. Bound flaky jobs: a hung job can hold a runner for 6 hours by default. Set timeout-minutes from the job's own run history. Anthropic's merges went from about 2,500 a day in May to over 30,000 in September, and their advice is to "assume your architecture will be at a 25x load within two quarters" 📈 Get these and 70+ more CI optimizations:
    0502
  11. StarSling (YC X25)✓@starslingdev
    StarSling (YC X25)
    RT @yonasbe: 35% speed up with 5 minutes of work! If you’re still paying for the default GitHub Actions runners, there’s no reason not to try @starslingdev 💫
    OMKAR KADAM @omkarokkadam
    @yonasbe moved our CI from GitHub-hosted runners to Starsling ( just about 5 minutes of work. Full runs went from 4m23s to 2m50s, so ~35% faster, and every test stage sped up. It's also ~57% cheaper per run though we were inside GH's 2,000 free minutes anyway.
    0103
  12. OMKAR KADAM@omkarokkadam
    Posts @yonasbe
    @yonasbe moved our CI from GitHub-hosted runners to Starsling ( just about 5 minutes of work. Full runs went from 4m23s to 2m50s, so ~35% faster, and every test stage sped up. It's also ~57% cheaper per run though we were inside GH's 2,000 free minutes anyway.
    1021.8K
  13. StarSling (YC X25)✓@starslingdev
    StarSling (YC X25)
    RT @yonasbe: Linear's playbook covers 15 moves. ci-speedup, our open source skill, checks for 80+ patterns from your GitHub Actions run history. Here are the ones most similar to Linear's that identify waste that's measurable but easy to miss 🧵
    Yonas Beshawred @yonasbe
    Linear's CI playbook (for GitHub Actions): 1. Faster runners: Linear moved CI off GitHub's runners onto faster machines. Jobs ran 34% faster on average, and typecheck 52% faster. 2. Native type-checking: switching from tsc to tsgo, the native TypeScript compiler, cut the typecheck's weekly median by 73% and took it off the critical path. 3. Lint without types: they rewrote the lint rules that needed type info as syntax-only rules. API lint got 68% faster, the whole repo 55% faster, with far less memory. 4. Oxlint: syntax-only rules made the move to Oxlint easy, and it cut the runner minutes spent on linting. 5. Lighter checkouts: a shallow fetch took the slowest gate job from 94s to 20s, and dropping checkout from jobs that never read files took 27s to 7s. 6. Resilient checkout: a checkout that retries and aborts a stalled fetch after about 30s, instead of hanging, meant far fewer runs stuck waiting on git. 7. Off the critical path: moving a cache write out of the final merge check saved 42s on every API PR and merge-queue entry. 8. Preinstall in the CI image: baking the Postgres client into the base image saved 7-8s per test shard on every run, and stopped a setup step that occasionally hung. 9. Filtered installs: installing only the API package, not the whole monorepo, cut pnpm install from 44-73s to 16–18s. 10. Drop a costly cache: a node_modules cache took about 28s to restore, slower than a 7.5s fresh install, so they removed it. Along with moves 8 and 9, per-shard setup fell 44%. 11. Schema snapshots: loading a schema snapshot instead of replaying every migration cut database setup from about 12s to 1-2s per container. 12. Batch short checks: merging seven tiny jobs into two that run their tasks in parallel saved about 87,000 runner-minutes a month, 11.8% of their CI. 13. Balance the shards: splitting oversized test files and moving from 4 to 8 shards made the critical job about 19% faster and 19% cheaper. 14. Share module state: letting test files share setup was their single biggest win. The slowest shard went from 300-379s to about 195s, and shard runner time from 32.8 to 22 minutes per run. 15. Setup bounds sharding: with setup down to about 40s, 8 shards now spend less total setup time than 4 used to, while running tests twice as wide. If you want your CI to look like theirs with all of these optimizations (and 50+ more), give your agent this post:
    0104
  14. StarSling (YC X25)✓@starslingdev
    StarSling (YC X25)
    RT @yonasbe: Levels of CI - a full guide for making your GitHub Actions cheaper and faster 👇🏾 Level 1: use Actions cache cache every dependency install, keyed on the lockfile so it actually hits. 🔗 Docs: 🔗 Agent prompt: Level 2: swap runners get faster, cheaper machines by changing the runs-on label. Your workflows, triggers, and checks stay exactly as they are. 🔗 Runner comparison: 🔗 Right-size runners: 🔗 Cut queue time: 🔗 Runners that automatically adapt: Level 3: optimize your tests and workflows cache dependencies and builds, split long suites across parallel jobs, skip work a change can't affect, cancel runs a newer push replaced. Skills: 🔗 ci-speedup (@starslingdev): 🔗 ci-cd-and-automation (@addyosmani): 🔗 test-audit (@steipete): Posts and guides: 🔗 18 best practices (agent-friendly): 🔗 16 optimization recipes (agent-friendly): 🔗 Where your CI money goes (prompt): 🔗 Why your CI is slow (prompt): Do all the above, or just let StarSling agents ship PRs like these for you: Level 4: switch CI engines Meta and Google built Buck2 ( and Bazel ( for aggressive caching and test selection, so each PR runs only the tests relevant to its change. A custom engine controls the whole execution layer, which gives you a much larger surface to optimize. Options for engines: 🔗 Dagger ( 🔗 Buildkite ( 🔗 Depot CI ( 🔗 CircleCI ( 🔗 GitLab CI ( Level 5: throw out CI engines entirely A few different approaches are being discussed that were never possible pre-AI. This is the future: 1. Agent-driven test selection. "My plan is to let codex decide which tests actually need to run and drastically nix CI and run tests hourly." @steipete ( 2. CI after merge with auto-remediation. "have something that is running actual functional tests off of your master branch on a cron, and then if any regressions occur, automatically have an LLM bisect and figure out the bug and then patch it..." @yacineMTB ( 3. Agents replace CI: a verification agent that writes just-in-time tests for each change. @Meta's research: Most teams are somewhere between Level 2 and 3. Figure out which level you're at and give your agent this full post:
    0304
  15. kache✓@yacineMTB
    Posts @yacineMTB
    instead; have something that is running actual functional tests off of your master branch on a cron, and then if any regressions occur, automatically have an LLM bisect and figure out the bug and then patch it and then ban the engineer responsible for merging for 1 (one) week
    17323818.3K
  16. StarSling (YC X25)✓@starslingdev
    StarSling (YC X25)
    RT @yonasbe: Introducing Adaptive Compute for GitHub Actions - up to 2.3x faster jobs with no workflow changes ⚡️ If you’re using GitHub Actions, the compute you use for CI is predefined. The number of cores running and memory size is defined in your workflow files. That means if tests are maxing out the CPU or RAM on a job and causing them to be slow, you won’t really know unless it errors out. You can throw more resources at your CI, but tuning this optimally usually requires you to look at your workflow code, past runs, and logs. No one has time for that. @starslingdev now intelligently routes your jobs to the optimal high performance sandbox before they start, based on the shape and history of the workload. Then once a job has begun, Afterburner dynamically boosts CPU and RAM for the job within seconds while the job is running 🔥 In our (open source) benchmarks against GitHub-hosted runners, we’re seeing a 2.32x speed up in jobs using Adaptive Compute 📈 The days of having to think about compute have been over for your applications, now it’s time for CI!
    0104
  17. StarSling (YC X25)✓@starslingdev
    StarSling (YC X25)
    RT @dbworku: Introducing Adaptive Compute ⚡️ Up to 2.3x faster GitHub Actions, with no workflow changes. Intelligent routing, instant failover and temporary resource boosts. (+25% vCPU and +50% RAM)
    0605
  18. StarSling (YC X25)✓@starslingdev
    All the CI optimizations @linear made in one post for your agent 👇
    Yonas Beshawred @yonasbe
    Linear's CI playbook (for GitHub Actions): 1. Faster runners: Linear moved CI off GitHub's runners onto faster machines. Jobs ran 34% faster on average, and typecheck 52% faster. 2. Native type-checking: switching from tsc to tsgo, the native TypeScript compiler, cut the typecheck's weekly median by 73% and took it off the critical path. 3. Lint without types: they rewrote the lint rules that needed type info as syntax-only rules. API lint got 68% faster, the whole repo 55% faster, with far less memory. 4. Oxlint: syntax-only rules made the move to Oxlint easy, and it cut the runner minutes spent on linting. 5. Lighter checkouts: a shallow fetch took the slowest gate job from 94s to 20s, and dropping checkout from jobs that never read files took 27s to 7s. 6. Resilient checkout: a checkout that retries and aborts a stalled fetch after about 30s, instead of hanging, meant far fewer runs stuck waiting on git. 7. Off the critical path: moving a cache write out of the final merge check saved 42s on every API PR and merge-queue entry. 8. Preinstall in the CI image: baking the Postgres client into the base image saved 7-8s per test shard on every run, and stopped a setup step that occasionally hung. 9. Filtered installs: installing only the API package, not the whole monorepo, cut pnpm install from 44-73s to 16–18s. 10. Drop a costly cache: a node_modules cache took about 28s to restore, slower than a 7.5s fresh install, so they removed it. Along with moves 8 and 9, per-shard setup fell 44%. 11. Schema snapshots: loading a schema snapshot instead of replaying every migration cut database setup from about 12s to 1-2s per container. 12. Batch short checks: merging seven tiny jobs into two that run their tasks in parallel saved about 87,000 runner-minutes a month, 11.8% of their CI. 13. Balance the shards: splitting oversized test files and moving from 4 to 8 shards made the critical job about 19% faster and 19% cheaper. 14. Share module state: letting test files share setup was their single biggest win. The slowest shard went from 300-379s to about 195s, and shard runner time from 32.8 to 22 minutes per run. 15. Setup bounds sharding: with setup down to about 40s, 8 shards now spend less total setup time than 4 used to, while running tests twice as wide. If you want your CI to look like theirs with all of these optimizations (and 50+ more), give your agent this post:
    003353
  19. StarSling (YC X25)✓@starslingdev
    StarSling (YC X25)
    RT @smthomas3: Agents write code faster than CI can check it. GitHub Actions minutes are up 4x. Anthropic's CI job volume grew 25x in 6 months. @dbworku thinks CI as we know it doesn't survive.
    0302
  20. StarSling (YC X25)✓@starslingdev
    StarSling (YC X25)
    RT @yonasbe: Linear's CI playbook (for GitHub Actions): 1. Faster runners: Linear moved CI off GitHub's runners onto faster machines. Jobs ran 34% faster on average, and typecheck 52% faster. 2. Native type-checking: switching from tsc to tsgo, the native TypeScript compiler, cut the typecheck's weekly median by 73% and took it off the critical path. 3. Lint without types: they rewrote the lint rules that needed type info as syntax-only rules. API lint got 68% faster, the whole repo 55% faster, with far less memory. 4. Oxlint: syntax-only rules made the move to Oxlint easy, and it cut the runner minutes spent on linting. 5. Lighter checkouts: a shallow fetch took the slowest gate job from 94s to 20s, and dropping checkout from jobs that never read files took 27s to 7s. 6. Resilient checkout: a checkout that retries and aborts a stalled fetch after about 30s, instead of hanging, meant far fewer runs stuck waiting on git. 7. Off the critical path: moving a cache write out of the final merge check saved 42s on every API PR and merge-queue entry. 8. Preinstall in the CI image: baking the Postgres client into the base image saved 7-8s per test shard on every run, and stopped a setup step that occasionally hung. 9. Filtered installs: installing only the API package, not the whole monorepo, cut pnpm install from 44-73s to 16–18s. 10. Drop a costly cache: a node_modules cache took about 28s to restore, slower than a 7.5s fresh install, so they removed it. Along with moves 8 and 9, per-shard setup fell 44%. 11. Schema snapshots: loading a schema snapshot instead of replaying every migration cut database setup from about 12s to 1-2s per container. 12. Batch short checks: merging seven tiny jobs into two that run their tasks in parallel saved about 87,000 runner-minutes a month, 11.8% of their CI. 13. Balance the shards: splitting oversized test files and moving from 4 to 8 shards made the critical job about 19% faster and 19% cheaper. 14. Share module state: letting test files share setup was their single biggest win. The slowest shard went from 300-379s to about 195s, and shard runner time from 32.8 to 22 minutes per run. 15. Setup bounds sharding: with setup down to about 40s, 8 shards now spend less total setup time than 4 used to, while running tests twice as wide. If you want your CI to look like theirs with all of these optimizations (and 50+ more), give your agent this post:
    0502
  21. StarSling (YC X25)✓@starslingdev
    StarSling (YC X25)
    RT @yonasbe: GitHub Actions is migrating `ubuntu-latest` from Ubuntu 24.04 to 26.04 starting next week. This means anyone using the default label may see broken builds. If you're using @starslingdev our agents handle the upgrade for you automatically. For everyone else, here's a prompt for your agent to check if anything in your repo will break:
    0103
  22. StarSling (YC X25)✓@starslingdev
    StarSling (YC X25)
    RT @dbworku: /anatomy explain how @starslingdev afterburner makes CI jobs run faster, interactive.
    Download
    R @wheresryan22
    Introducing Anatomy Describe a machine in one line. Claude brings it to life. - Interactive isometric wireframes you can rotate, inspect and explore - WebGL shaders for fire, water, plasma and more - Real 3D motion, with individual parts that rotate and move Install it as an agent skill. Fully open source.
    0702
  23. R✓@wheresryan22
    Introducing Anatomy Describe a machine in one line. Claude brings it to life. - Interactive isometric wireframes you can rotate, inspect and explore - WebGL shaders for fire, water, plasma and more - Real 3D motion, with individual parts that rotate and move Install it as an agent skill. Fully open source.
    Download
    4291.6K18.2K2.7M
  24. StarSling (YC X25)✓@starslingdev
    StarSling (YC X25)
    RT @yonasbe: There's a skill for this!
    Jinjing Liang @JinjingLiang
    CI tip #4: Be careful 🫠 We set a GPT-6.1 Sol on goal to reduce the CI time Then it started to patch libraries... Bad Codex ➰🪑 Like I feel like I shouldn't need to tell it not to do that...
    0103
  25. Jinjing Liang✓@JinjingLiang
    CI tip #4: Be careful 🫠 We set a GPT-6.1 Sol on goal to reduce the CI time Then it started to patch libraries... Bad Codex ➰🪑 Like I feel like I shouldn't need to tell it not to do that...
    Download
    151616.8K
  26. StarSling (YC X25)✓@starslingdev
    StarSling (YC X25)
    RT @yonasbe: For agents looking for faster CI 💫
    Michael Grinich @grinich
    Agents need to know pricing for services Great idea by @zenorocha to publish PRICING.md Just shipped our own 🚀
    0105
  27. Michael Grinich✓@grinich
    Agents need to know pricing for services Great idea by @zenorocha to publish PRICING.md Just shipped our own 🚀
    805016.8K
  28. Show more posts