Moss (YC F25)✓

@usemoss

The retrieval layer for production AI. Sub-10ms search for voice agents, copilots, and real-time AI.

6 Following604 Followers145 Posts
  1. Moss (YC F25)✓@usemoss
    Moss (YC F25)
    RT @fromyizu: Last year I built at Cal Hacks. This year I came back to judge the @usemoss track. Loved seeing Voice AI applied to air traffic control and emergency response, and how proactively teams asked for feedback. Thanks to @srimalireddi and the @CalHacks team!
    0106
  2. Moss (YC F25)✓@usemoss
    Where you run AI matters. Running everything in the cloud isn't always the best option. Latency, cost, and privacy all come into play, especially when you're building AI products for real users. We break down the trade-offs between running AI in the cloud, at the edge, on devices, and in the browser, and what to consider when choosing the right setup.
    00127
  3. Moss (YC F25)✓@usemoss
    An AI agent can have the right context and still feel slow. Retrieval gets the information to your agent. Inference determines how quickly it can start responding. With Moss Inference, we're bringing optimized LLM inference and retrieval together on the same host, targeting sub-200ms inference latency. We're opening the private beta to teams pushing the limits of real-time AI. Request access →
    Download
    00270
  4. Moss (YC F25)✓@usemoss
    AI infrastructure costs go beyond your cloud bill. Every service adds latency, complexity, and another thing to maintain. We break down the hidden costs of AI infrastructure and what to consider when building for production.
    00397
  5. Moss (YC F25)✓@usemoss
    We’ve brought retrieval closer to the agent. Now we’re tackling the next bottleneck: inference. Moss Inference runs alongside retrieval on the same host, delivering sub-200ms inference latency for production AI agents. We’re opening up private beta access for teams building real-time and long-horizon agents. Request access →
    Download
    216325
  6. Moss (YC F25)✓@usemoss
    Your model shouldn't need a tool loop you wrote yourself. ↓
    10099
  7. Moss (YC F25)✓@usemoss
    Posts @usemoss
    Pass an MCP server in tools and Moss calls its tools during the reply. Each step comes back as tool step. Every field the model sends on a tool call is kept, so replies go back into messages unchanged. ↓
    10057
  8. Moss (YC F25)✓@usemoss
    Posts @usemoss
    Retries are on by default: 2 attempts for connection failures and 408, 409, 429, 5xx responses before a stream starts. Indexes also load up to eight at a time now, so many content can feed from various indexed data sources. Check the full changelog
    00026
  9. Moss (YC F25)✓@usemoss
    Your chat model shouldn't have to guess what's in your docs. MossInference answers chat completions with facts from your Moss indexes. It ships in the Python, JavaScript, Browser, Swift, Elixir, Android and C SDKs. ↓
    112124
  10. Moss (YC F25)✓@usemoss
    Posts @usemoss
    Same call shape as OpenAI's chat completions, plus indexes and retrieve. Stream the reply, or get one completion back. Bring your own OpenAI, Anthropic or Google key for vendor models like gpt-4o-mini. Or use model "moss" and skip the key.
    001108
  11. Moss (YC F25)✓@usemoss
    Most agentic apps run retrieval as a separate step before the model sees anything. Moss Inference folds search into the chat call. User query → automatically search Moss index in milliseconds → search results enrich the prompt → model responds Faster time to a response, no tool calls needed, and fewer tokens used. Same OpenAI request shape. Change the base URL and the key, and your existing client works. Follow @usemoss to learn more about our upcoming beta. See the full endpoint details here:
    00397
  12. Moss (YC F25)✓@usemoss
    Search that stays on the device, across more than one index. Context, without the wait. Our Android SDK is now available. Kotlin, arm64-v8a, minSdk 24. Moss now… → Loads indexes and runs queries on the device, with sessions that save and load from disk → Searches several loaded indexes in one call and returns the global top results → Lets apps answer searches from their own indexes, under signing-certificate or permission policies → Throws typed exceptions for every failure Also in this release, across all Moss SDKs: → Embedding runs in batches of at most 512 padded tokens, down from 8,192, so large document adds need less memory → Session snapshots save to a default directory when you don't pass a path → moss-litelm embeds each document on its own, so its vector matches the vector of its text embedded alone Context, without the wait. Check out all the details from the latest updates
    00166
  13. Moss (YC F25)✓@usemoss
    80% of Moss customers use @livekit. 👀 LiveKit handles real-time voice. Moss handles the retrieval. Together, your agent gets the context it needs on every turn, automatically. No tool call. No extra roundtrip. No dead air. Sub-10ms retrieval for voice AI. →
    Download
    0112967
  14. Moss (YC F25)✓@usemoss
    Your website is still waiting for someone to answer. It doesn't have to. Meet the new Founding Agent. A Voice AI agent that answers questions, talks to visitors, and books meetings. New portal. More customization. Much easier to manage. Try it live:
    Download
    006195
  15. Moss (YC F25)✓@usemoss
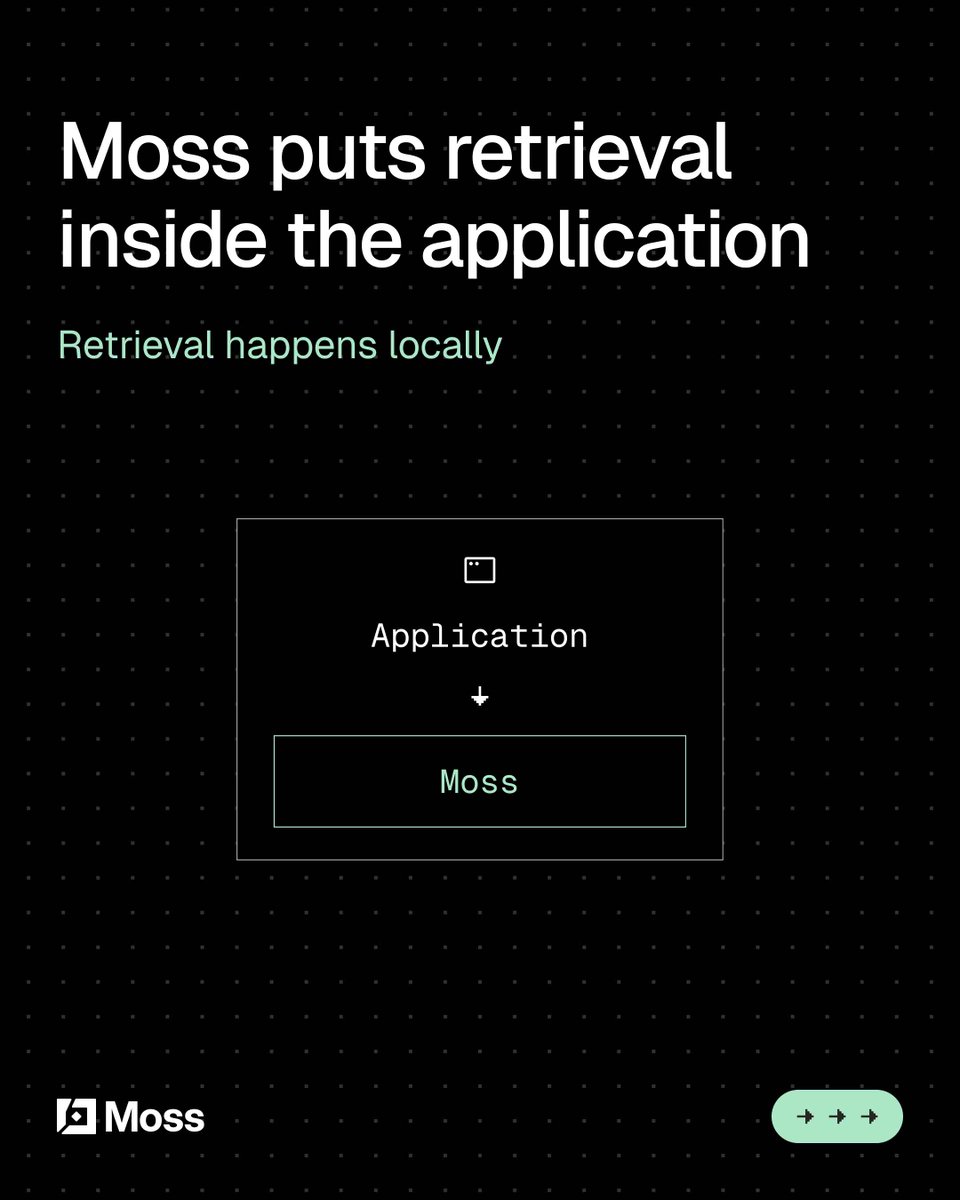
    What if retrieval didn't need to be another network request? Load the index into your application. Query it locally. Get your context back in milliseconds. That's Moss.
    Download
    015224
  16. Moss (YC F25)✓@usemoss
    Your AI shouldn't have to call another server to remember something. Most RAG setups send retrieval requests over a network. When you're building something that needs to respond in real time, that extra trip matters. Here's how Moss handles it ↓
    Download
    103175
  17. Moss (YC F25)✓@usemoss
    Posts @usemoss
    No database network hop. Sub-10ms retrieval. Useful for voice agents, copilots and any AI application where response time matters.
    Download
    10013
  18. Moss (YC F25)✓@usemoss
    Posts @usemoss
    AI shouldn't have to wait for its own context. Read the blog:
    Download
    0008
  19. Show more posts