MLCommons

@MLCommons

Better Artificial Intelligence for Everyone

150 Following3.8K Followers872 Posts
  1. MLCommons@MLCommons
    MLPerf is the performance yardstick in the EU's AI Gigafactories tender, and MLPerf Endpoints v1.0 is open for submissions, with rolling results and mandatory power reporting. Blog: #MLPerf #AIBenchmarks #AI
    Download
    004747
  2. MLCommons@MLCommons
    MLPerf Client is in PCMag, StorageReview, and Wccftech, which used it to measure on-device AI performance on new laptops, including GenAI image generation and agentic workloads. Thanks to the reviewers! Try MLPerf Client:
    002575
  3. MLCommons@MLCommons
    MLCommons
    RT @MLCommons: What is MLPerf Endpoints? It measures the served endpoint the way you actually buy it: model, hardware, serving software, and networking together, under production-like load. Guide: #MLPerf #AIInfrastructure #AIBenchmarks
    020300
  4. MLCommons@MLCommons
    MLCommons has been selected as the Benchmarking Team for the STRIDE Ventures AI Efficiency Challenge. A $3.5 million, two-year award will fund MLPerf Agents: an industry-standard benchmark for the efficiency of complete agentic AI workflows.
    Download
    003198
  5. MLCommons@MLCommons
    Our mission, updated: standardize AI measurement and enable informed decisions. Read the letter from President Peter Mattson:
    Download
    000130
  6. MLCommons@MLCommons
    A vendor's AI benchmark caught 82% of bugs. A rival re-ran the same test: 45%. An independent lab built its own: 63%. Same products. Only the grading changed. New from MLCommons: Assessing & Managing AI Risk for Business and Commercial Deployments.
    Download
    000127
  7. MLCommons@MLCommons
    A chatbot's data protection risks are, for the most part, limited to the individual user. For an agent, the scope is vast. MLCommons releases the Agent Privacy Risk Taxonomy v0.1 - five risk areas specific to agents. Read more: #AIPrivacy #AgenticAI
    Download
    000160
  8. MLCommons@MLCommons
    MLPerf Training introduces DLRMv4: HSTU sequence modeling + Yambda-5B (4.79B real interactions) + a 560 GB embedding footprint. Production-scale recommenders, now benchmarked. Full breakdown from the AMD, Meta, NVIDIA, and ByteDance task force: More:
    Download
    012315
  9. MLCommons@MLCommons
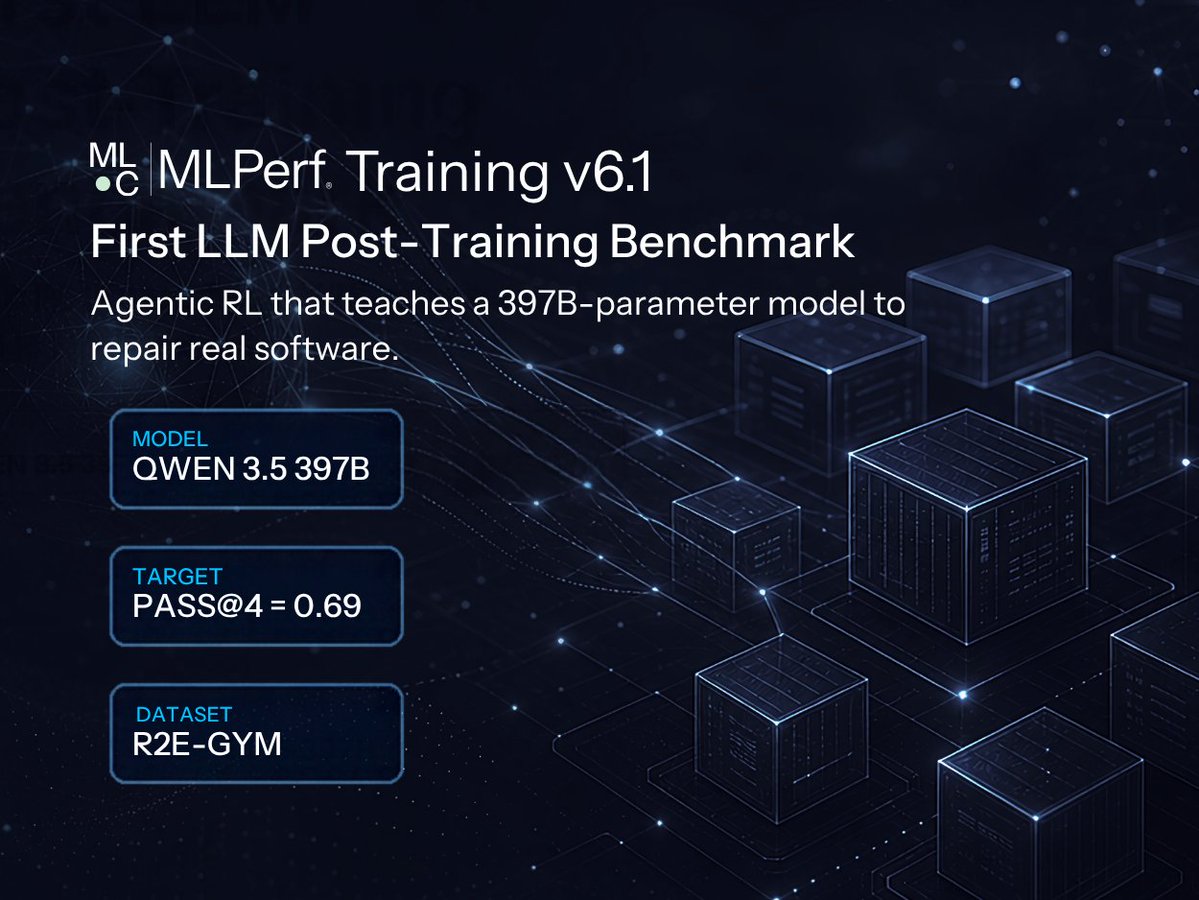
    MLPerf Training v6.1 adds the suite's first LLM post-training benchmark: agentic RL that teaches a 397B-parameter open-weight model to repair real software, scored on pass@4 quality - not just throughput. Details from the task force:
    Download
    128642
  10. MLCommons@MLCommons
    MLCommons joins the EU-funded AIRIS consortium to benchmark next-generation biomedical AI. We're building an evaluation framework to measure mechanism-informed generative AI across accuracy, robustness, fairness, interpretability, and usability. More:
    Download
    011188
  11. MLCommons@MLCommons
    MLPerf Inference v6.1 WG chairs Miro Hodak and Frank Han walk through the record round, new silicon (AMD MI350P, Intel Arc Pro B70, NVIDIA Vera Rubin), the first cross-vendor heterogeneous submission, and what it signals for inference engineering.
    Download
    101357
  12. MLCommons@MLCommons
    🧵 1/ @MLPerf Inference v6.1 is here. Record participation, new benchmarks, and substantial performance gains. 30 organizations submitted — the most ever. Details:
    Download
    136896
  13. MLCommons@MLCommons
    Posts @MLCommons
    7/ 50%+ used our new API-centric harness — the LoadGen++ foundation for MLPerf Endpoints. The transition is happening.
    00154
  14. MLCommons@MLCommons
    AI Infra 2026: MLPerf Inference v6.1 - Technical deep dive. David Kanter, Miro Hodak (AMD), and Frank Han (Dell) on serving scenarios, reasoning workloads, edge measurements, and what's driving the biggest gains this round. Plus: a preview of MLPerf Endpoints. #AIInfraSummit
    Download
    011213
  15. Show more posts