Max For AI✓

@MaxForAI

Head of hype @lobehub Prev @listenhub @Sapient_Int 没啥好看的,也就发点AI相关的内容🫡 同名小红书4万粉丝,公众号01Founder(长文首发) 观点仅代表个人 更多请访问网站⬇️(欢迎商务、合作

3K Following44.7K Followers13.2K Posts
  1. Max For AI✓@MaxForAI
    个人情况更新: 我没有加入 @AnthropicAI 而是选择加入了 @lobehub 担任MAS&Head of growth 原因是 @arvin17x 他们团队对于Agent的前沿探索打动了我,同时Lobehub也是为数不多我见过有自有Benchmark的应用团队(Eval is everting.) 我看到了下一代Agent的样子,以及更远的未来(持续学习、自进化、以及True Agent)。 既然看到了未来,为什么不加入呢?
    828392613K
  2. Max For AI✓@MaxForAI
    梁文峰那双眼睛到底看到了多远....? 之前泄露的 @deepseek_ai 投资人会议录音里,梁文峰曾表示:“Anthropic现在超过OpenAl,不是长期的,是阶段性的。OpenAI和Google未来大概率会交替上升。” 现在Gemini 4 Carbon重新获得了第一名😧
    Artificial Analysis @ArtificialAnlys
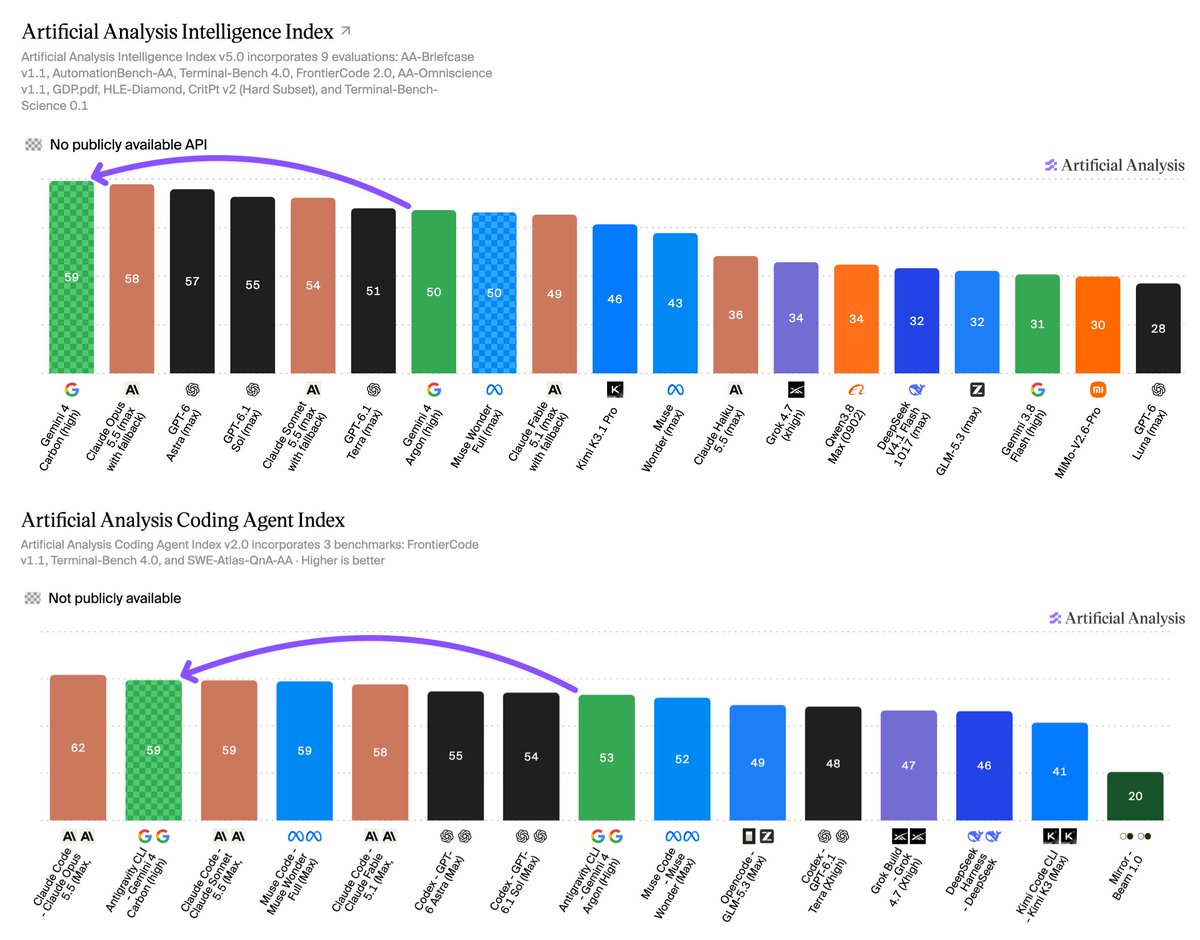
    Google’s Gemini 4 Carbon is the new #1 on the Artificial Analysis Intelligence Index v5, and second only to Claude Opus 5.5 on the Artificial Analysis Coding Agent Index Gemini 4 Carbon scores 59 on Intelligence Index v5, driven by leading performance in complex reasoning, knowledge, and scientific tasks. It also has large gains in coding and knowledge work, particularly when compared to other Gemini models, but it is not leading in all these areas. As with launch of Gemini 4 Argon, Gemini 4 Carbon is being rolled out to selected users and is not yet publicly available. Google is offering a 50% launch discount, with no confirmed end date. All our charts and figures use standard pricing for both Gemini 4 Carbon and Argon. Key results for Gemini 4 Carbon with high reasoning: ➤ Gemini 4 Carbon leads the Intelligence Index v5, with the #1 score in 4 of the 9 Index evaluations: HLE-Diamond, Terminal-Bench-Science, AA-Omniscience, AutomationBench-AA. Carbon makes substantial gains elsewhere but is not leading in coding and knowledge work ➤ Behind only Claude Opus 5.5 on coding agents: With Antigravity CLI, Gemini 4 Carbon (high) scores 59 only 3 points behind Claude Code with Claude Opus 5.5 (max, 62) on the Artificial Analysis Coding Agent Index. Carbon ranks second on both Terminal-Bench 4.0 (64%) and FrontierCode v1.1 (51%), behind Claude Opus 5.5 (max) at 56%. Google has historically underperformed in this area and so this improvement stands out ➤ Improved agentic knowledge work, but not yet leading: On AA-Briefcase, Gemini 4 Carbon (high) scores 1609 Elo, a 126-point improvement over Gemini 4 Argon (high, 1483), but still behind models including Grok 4.7 (xhigh, 1638), Muse Wonder (max, 1659) and Kimi K3.1 Pro (1678). The largest gain comes from Presentation, up 293 Elo to 1598, alongside a 120-point improvement in Analytical Quality to 1671 ➤ Lower Cost per Task than Claude Opus 5.5 for comparable overall intelligence: Gemini 4 Carbon costs $7.76 per Intelligence Index task, ~23% less than Claude Opus 5.5 (max, $10.04) but ~1.2x GPT-6 Astra (max, $6.25). It uses 123k output tokens per task, 29% fewer than Claude Opus 5.5 (max, 173k). At the same $4/$20 standard pricing, its Cost per Task is in line with Gemini 4 Argon ($7.68), while scoring 9 points higher on the Intelligence Index ➤ Leading AA-Omniscience v1.1 score, with low hallucination: Gemini 4 Carbon scores 54 on our recently updated AA-Omniscience v1.1, 6 points ahead of Claude Opus 5.5 (max, 48) and 8 points ahead of Gemini 4 Argon (46). Accuracy (% correct) rises 10 points over Argon to 58%, while its hallucination rate rises from 4% to 11%. This is still the second lowest of any model, behind only Argon, compared with 50% for both Claude Opus 5.5 (max) and GPT-6 Astra (max) Key model details: ➤ Context Window: 1M tokens ➤ Multimodality: Text, image, video, and speech input, with text output ➤ Pricing: $4/$20 per 1M input/output tokens, the same as Gemini 4 Argon’s standard pricing, with a 50% discount. Cached input tokens receive a 95% discount ($0.20 per 1M) Congratulations to the @GoogleDeepMind team!
    1046713.6K
  3. Artificial Analysis✓@ArtificialAnlys
    Google’s Gemini 4 Carbon is the new #1 on the Artificial Analysis Intelligence Index v5, and second only to Claude Opus 5.5 on the Artificial Analysis Coding Agent Index Gemini 4 Carbon scores 59 on Intelligence Index v5, driven by leading performance in complex reasoning, knowledge, and scientific tasks. It also has large gains in coding and knowledge work, particularly when compared to other Gemini models, but it is not leading in all these areas. As with launch of Gemini 4 Argon, Gemini 4 Carbon is being rolled out to selected users and is not yet publicly available. Google is offering a 50% launch discount, with no confirmed end date. All our charts and figures use standard pricing for both Gemini 4 Carbon and Argon. Key results for Gemini 4 Carbon with high reasoning: ➤ Gemini 4 Carbon leads the Intelligence Index v5, with the #1 score in 4 of the 9 Index evaluations: HLE-Diamond, Terminal-Bench-Science, AA-Omniscience, AutomationBench-AA. Carbon makes substantial gains elsewhere but is not leading in coding and knowledge work ➤ Behind only Claude Opus 5.5 on coding agents: With Antigravity CLI, Gemini 4 Carbon (high) scores 59 only 3 points behind Claude Code with Claude Opus 5.5 (max, 62) on the Artificial Analysis Coding Agent Index. Carbon ranks second on both Terminal-Bench 4.0 (64%) and FrontierCode v1.1 (51%), behind Claude Opus 5.5 (max) at 56%. Google has historically underperformed in this area and so this improvement stands out ➤ Improved agentic knowledge work, but not yet leading: On AA-Briefcase, Gemini 4 Carbon (high) scores 1609 Elo, a 126-point improvement over Gemini 4 Argon (high, 1483), but still behind models including Grok 4.7 (xhigh, 1638), Muse Wonder (max, 1659) and Kimi K3.1 Pro (1678). The largest gain comes from Presentation, up 293 Elo to 1598, alongside a 120-point improvement in Analytical Quality to 1671 ➤ Lower Cost per Task than Claude Opus 5.5 for comparable overall intelligence: Gemini 4 Carbon costs $7.76 per Intelligence Index task, ~23% less than Claude Opus 5.5 (max, $10.04) but ~1.2x GPT-6 Astra (max, $6.25). It uses 123k output tokens per task, 29% fewer than Claude Opus 5.5 (max, 173k). At the same $4/$20 standard pricing, its Cost per Task is in line with Gemini 4 Argon ($7.68), while scoring 9 points higher on the Intelligence Index ➤ Leading AA-Omniscience v1.1 score, with low hallucination: Gemini 4 Carbon scores 54 on our recently updated AA-Omniscience v1.1, 6 points ahead of Claude Opus 5.5 (max, 48) and 8 points ahead of Gemini 4 Argon (46). Accuracy (% correct) rises 10 points over Argon to 58%, while its hallucination rate rises from 4% to 11%. This is still the second lowest of any model, behind only Argon, compared with 50% for both Claude Opus 5.5 (max) and GPT-6 Astra (max) Key model details: ➤ Context Window: 1M tokens ➤ Multimodality: Text, image, video, and speech input, with text output ➤ Pricing: $4/$20 per 1M input/output tokens, the same as Gemini 4 Argon’s standard pricing, with a 50% discount. Cached input tokens receive a 95% discount ($0.20 per 1M) Congratulations to the @GoogleDeepMind team!
    Download
    1812993.6K237K
  4. Max For AI✓@MaxForAI
    逆天了,美国大豆包居然跑到世界第一了!??? @GoogleDeepMind 刚刚发布了Gemini 4 Carbon,在Artificial Analysis Intelligence Index v5.0上拿到了59分,超过Claude Opus 5.5的58分和GPT-6 Astra的57分。 最离谱的是,距离上一代Gemini 4 Argon发布才过去两周,分数就从50涨到了59。 Google公布的17项评测里,Carbon拿下了15项最高分,尤其是网络安全、长上下文和Agent能力,提升非常明显。 要知道,之前中文互联网一直管Gemini叫「美国大豆包」,因为它经常一本正经地胡说八道,指出错误之后又特别喜欢道歉,情绪价值拉满。 结果现在,美国大豆包突然支棱起来了。 不过目前Carbon还没有向普通用户开放,排行榜第一能不能转化成实际体验,还得等大家真正上手。 只能说,Google这次是真把美国大豆包给练出来了。。 RSI无敌了😭
    Download
    Google DeepMind @GoogleDeepMind
    Gemini 4 Carbon is our next frontier model. It’s state-of-the-art across cybersecurity and long-horizon capabilities.
    60338.1K
  5. Google DeepMind@GoogleDeepMind
    Gemini 4 Carbon is our next frontier model. It’s state-of-the-art across cybersecurity and long-horizon capabilities.
    Download
    4768859.7K687K
  6. Max For AI✓@MaxForAI
    你知道的,我一直是Gemini的粉丝,从2.5 Pro时期就紧紧跟随;Nano Banana是我的主力,3 Pro第一时间跟上,Flash也一直是拥趸。 重建期熬完了,天赋兑现了,速度、推理、多模态全在线——现在到了Gemini 4复兴的时候,comeon! 至于GPT和Claude,我祝他们好运。
    Download
    81485.3K
  7. Max For AI✓@MaxForAI
    哦草,会发光的MacBook回来了!!?
    John Ternus @johnternus
    3073.8K
  8. Max For AI✓@MaxForAI
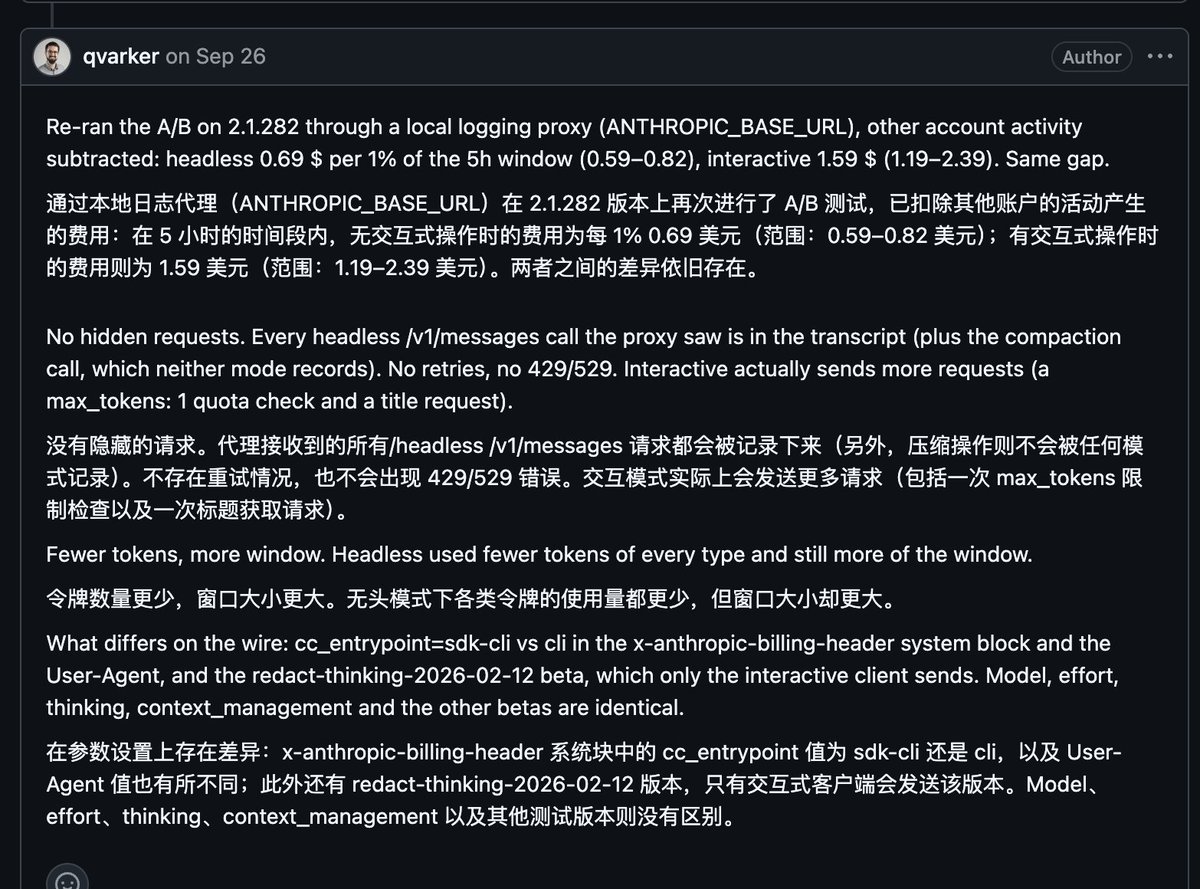
    尼玛,Anthropic又被扒出来搞小动作,偷偷提高了SDK的额度消耗!!! Claude Code被发现了一个有点离谱的问题:同样的模型、同样的任务、消耗几乎相同的 Token,5 小时额度的扣减居然能差一倍以上。 有开发者在 @AnthropicAI 的GitHub上提交了一个Issue #97074,并且做了多组对照实验。 其中一组测试使用Claude Opus 5.5,让模型读取相同的 10 个文件,完成相同的任务。 TUI的Claude Code:142 万折算 Token,消耗 5% 额度。 无头模式的claude -p:132 万折算 Token,消耗 8% 额度。 自定义入口名称的claude -p:143 万折算 Token,只消耗 4% 额度。 也就是说,默认的SDK入口消耗额度的速度,大约是自定义入口的 2.2 倍。 而解决办法,居然只是修改一个环境变量就行了.... 在环境变量里的CLAUDE_CODE_ENTRYPOINT这个地方,你可以给自己的工具设置一个自定义入口名称,例如 my-tool。 然后模型和实际执行的任务没有变化,但订阅额度的消耗明显下降。 更有意思的是,10 月 17 日还有另一位开发者进行了独立测试,发现Agent SDK的sdk-ts和sdk-cli入口,相比VS Code扩展使用的 claude-vscode,消耗 5 小时额度的速度接近 3 倍。 这意味着,差异很可能与Anthropic如何识别、分类不同客户端有关。 目前Anthropic的官方文档只说明,Claude Agent SDK和 claude -p会消耗订阅额度,并没有明确解释不同入口是否存在不同的计量权重。 这件事对大量使用Claude Code自动化、Agent SDK和第三方编程工具的人影响尤其明显。 因为开发者可能一直以为自己遇到的是额度不够用,实际上,不同调用入口可能直接影响同一份订阅额度能够完成多少工作。 目前这个Issue仍然处于Open状态。 究竟是配额统计的Bug,还是Anthropic有意设置了不同的计量策略,仍然没有得到官方回应。 如果这是一项有意设计的策略,我觉得 Anthropic 至少应该把规则公开。 毕竟大家付的是同一份订阅费,连额度怎么扣都搞不清楚,确实有点奇怪。 原 Issue:
    Download
    22109115.4K
  9. Max For AI✓@MaxForAI
    颠覆级别的创新👏
    Radium Wang @iamRadiumWang
    我他妈又弄一个新活,你的哈苏现在可以使用 GPT 了,控制对焦,快门,甚至唠闲嗑都可以我真的笑晕了。 多亏了@openai,@fedesarquis 这是你要的哈苏接入 GPT 吗哈哈哈哈哈哈哈哈哈哈哈哈 将会开源到我的 git 中
    0093.2K
  10. Radium Wang@iamRadiumWang
    我他妈又弄一个新活,你的哈苏现在可以使用 GPT 了,控制对焦,快门,甚至唠闲嗑都可以我真的笑晕了。 多亏了@openai,@fedesarquis 这是你要的哈苏接入 GPT 吗哈哈哈哈哈哈哈哈哈哈哈哈 将会开源到我的 git 中
    Download
    122431121.7K
  11. Max For AI✓@MaxForAI
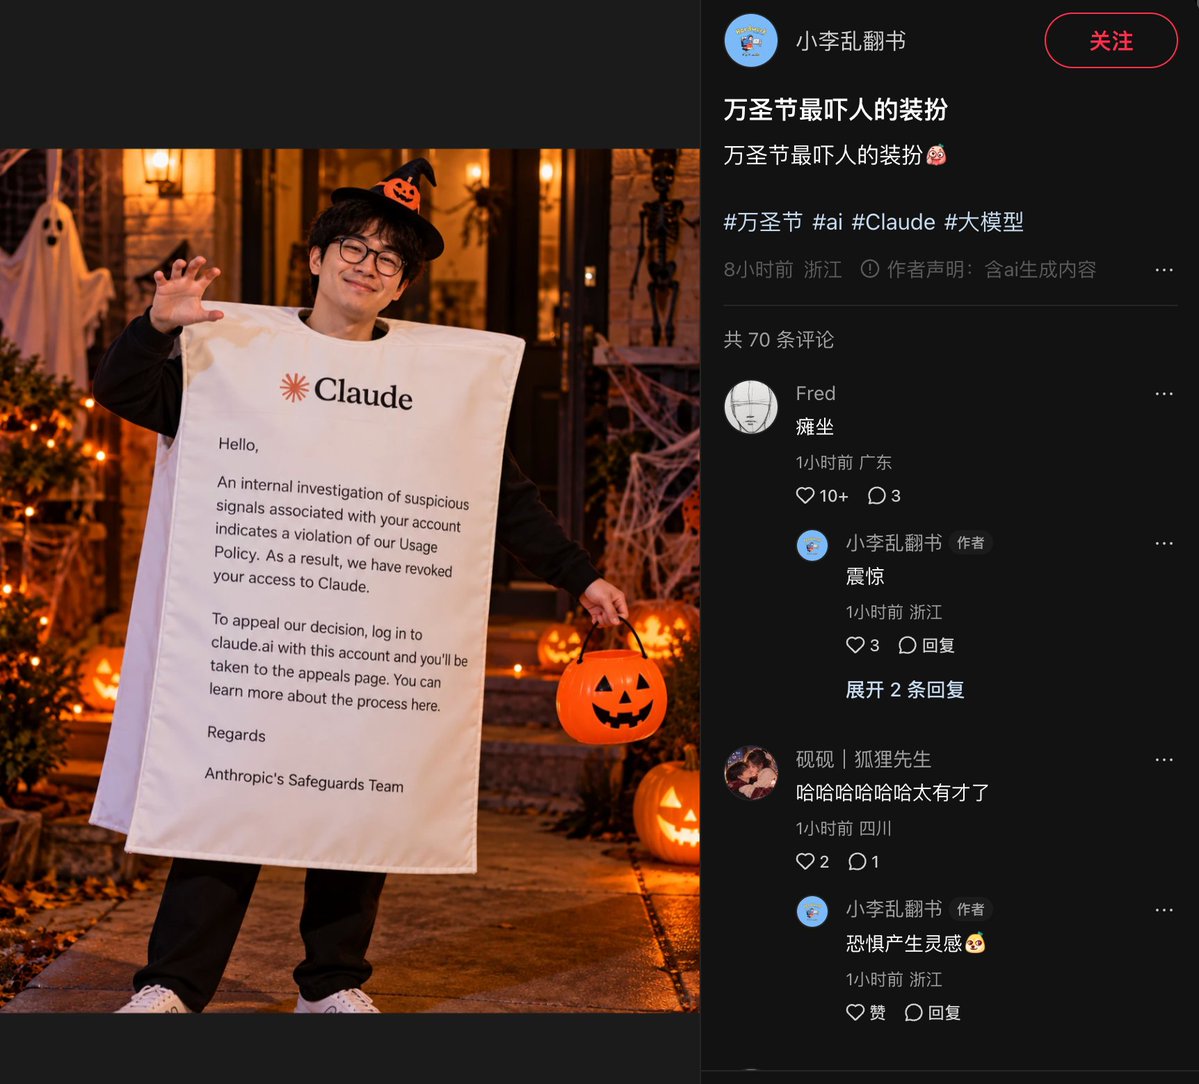
    啊哈哈哈哈哈我不行了,万圣节最吓人的装扮🤣
    Download
    43686.4K
  12. Max For AI✓@MaxForAI
    Posts @MaxForAI
    中国地区限定哦~
    000770
  13. Max For AI✓@MaxForAI
    今天群里都在发这个🤔
    真白大小姐 @Mashiro_0619
    Claude风控天机泄露😱 1. Claude 的风控是积分制:注册时会先给账号打分,之后根据行为加分或减分,低于一定分值就会直接封号(很少加分)。 2. 注册:邮箱和 IP 的权重最高。IP 不一定要家宽,但一定要干净,例如自建 IP。Gmail 已经不是最优选,他们现在使用的是一些其他高权重邮箱。注册时直接弹 KYC 的账号可以直接放弃。注册环节很重要,否则后续稍有高危行为就可能直接封号。使用手机 App 注册会加分。 3. 支付:刚注册就订阅会减分,直接订阅 Max 会大幅减分,最好间隔一两天再订阅 Pro。订阅时弹出 KYC 意味着账号处于考察期,但不一定会封;简而言之,A 社想先看 KYC 结果再决定。KYC 使用中国护照没有问题,最大的问题是不能一人多扫;闲鱼上很多账号都属于这种情况,要小心。 4. 注册后的 IP:最重要的是稳定,千万不要随便切换,尽可能一直使用同一个 IP;同样要求干净即可,不要求一定家宽,最好与注册 IP 一致。代理一定要开启全局模式并启用 TUN,这是重点。 5. 老号:老号权重非常高,也就是积分很多,容错率更高。账号积分会随着账号寿命增加,不过 2023 年的老号才是显著更高。 6. 使用:不要一上来就把周限额用完,尽量控制并平均使用;用量大的宁可开两个号轮换使用,也不要一次性用完。使用 CLI 和 Desktop 都可以,Desktop 似乎会少量加分。尽量少用网页端,最好只保留手机端和 Desktop 登录。 7. 时区和语言基本不减分,或仅极少量减分,没必要特意调整。 8. 高并发、反复提问同一个问题、频繁登录、频繁切换 IP 都会大幅减分。 9. 手机端使用会少量加分。开启记忆功能会加分,甚至可能记忆文件越多分数越高。 10. 支付方式为国外实体正规银行信用卡会加分,其次是 Google Play。Apple Pay 不了解;官方礼品卡不减分,但要注意来源是否为黑卡;虚拟卡直接绑定会减分。 11. 到达斩杀线后可能进入观察期。例如及格线是 60 分,账号 55 分就进入观察;如果继续扣分直接掉到 40 分,就会直接封号。观察期的典型特征是掉登录。有的高权重号可能经历两三个观察期才被封。 12. 多设备登录会大幅扣分,最好只在一台电脑上使用一个客户端。 13. Windows 和 macOS 没什么区别,Linux 使用会减分。 14. 跟 Claude 说自己是中国人也没事,不会因为记忆文件就封号。 15. 充值 Credits 会加分,不过成本太高,尚未进行大量实验。 16. 大量使用 Fable 会减分。 17. 升级 Max 大概率会直接进入观察期,除非是积分特别多的高权重号。观察期内有减分行为,大概率会封号。 18. 在工作时间使用不会扣分,不会出现因为使用北京时间就封号的情况。
    112926.3K
  14. 真白大小姐✓@Mashiro_0619
    Claude风控天机泄露😱 1. Claude 的风控是积分制:注册时会先给账号打分,之后根据行为加分或减分,低于一定分值就会直接封号(很少加分)。 2. 注册:邮箱和 IP 的权重最高。IP 不一定要家宽,但一定要干净,例如自建 IP。Gmail 已经不是最优选,他们现在使用的是一些其他高权重邮箱。注册时直接弹 KYC 的账号可以直接放弃。注册环节很重要,否则后续稍有高危行为就可能直接封号。使用手机 App 注册会加分。 3. 支付:刚注册就订阅会减分,直接订阅 Max 会大幅减分,最好间隔一两天再订阅 Pro。订阅时弹出 KYC 意味着账号处于考察期,但不一定会封;简而言之,A 社想先看 KYC 结果再决定。KYC 使用中国护照没有问题,最大的问题是不能一人多扫;闲鱼上很多账号都属于这种情况,要小心。 4. 注册后的 IP:最重要的是稳定,千万不要随便切换,尽可能一直使用同一个 IP;同样要求干净即可,不要求一定家宽,最好与注册 IP 一致。代理一定要开启全局模式并启用 TUN,这是重点。 5. 老号:老号权重非常高,也就是积分很多,容错率更高。账号积分会随着账号寿命增加,不过 2023 年的老号才是显著更高。 6. 使用:不要一上来就把周限额用完,尽量控制并平均使用;用量大的宁可开两个号轮换使用,也不要一次性用完。使用 CLI 和 Desktop 都可以,Desktop 似乎会少量加分。尽量少用网页端,最好只保留手机端和 Desktop 登录。 7. 时区和语言基本不减分,或仅极少量减分,没必要特意调整。 8. 高并发、反复提问同一个问题、频繁登录、频繁切换 IP 都会大幅减分。 9. 手机端使用会少量加分。开启记忆功能会加分,甚至可能记忆文件越多分数越高。 10. 支付方式为国外实体正规银行信用卡会加分,其次是 Google Play。Apple Pay 不了解;官方礼品卡不减分,但要注意来源是否为黑卡;虚拟卡直接绑定会减分。 11. 到达斩杀线后可能进入观察期。例如及格线是 60 分,账号 55 分就进入观察;如果继续扣分直接掉到 40 分,就会直接封号。观察期的典型特征是掉登录。有的高权重号可能经历两三个观察期才被封。 12. 多设备登录会大幅扣分,最好只在一台电脑上使用一个客户端。 13. Windows 和 macOS 没什么区别,Linux 使用会减分。 14. 跟 Claude 说自己是中国人也没事,不会因为记忆文件就封号。 15. 充值 Credits 会加分,不过成本太高,尚未进行大量实验。 16. 大量使用 Fable 会减分。 17. 升级 Max 大概率会直接进入观察期,除非是积分特别多的高权重号。观察期内有减分行为,大概率会封号。 18. 在工作时间使用不会扣分,不会出现因为使用北京时间就封号的情况。
    1931601.9K334K
  15. Max For AI✓@MaxForAI
    国内的OPC已经惨到这样了么???
    Download
    62256.7K
  16. Max For AI✓@MaxForAI
    嘿!我找到了 @thsottiaux 和 @poteto 的秘密约会视频🔥 原来tibo的28天计划只是为了获得poteto的注意,他能重置别人的额度,但是重置不了他对poteto的💔.....
    Download
    lauren @poteto
    @thsottiaux 💀💀💀 i cant afford
    1457713.6K
  17. lauren✓@poteto
    Posts @thsottiaux
    @thsottiaux 💀💀💀 i cant afford
    274374.2K628K
  18. Max For AI✓@MaxForAI
    我讨厌在社交媒体上公开秀恩爱的😡
    Download
    Tibo @thsottiaux
    has landed
    6211426.8K
  19. Tibo✓@thsottiaux
    has landed
    1.8K36411.7K3.5M
  20. Max For AI✓@MaxForAI
    人形机器人已经能打拳、跳舞、后空翻了,但传奇程序员 John Carmack 今天提出了一个非常有意思的问题: 全世界可能还没有一台通用机器人,能独立给南瓜灯换电池。 听起来很荒谬,毕竟这对于一个几岁的小孩来说,都算不上什么困难的任务。 但仔细想想,你需要让机器人自己去拿南瓜灯,找到放电池的抽屉,拆开 AA 电池的包装,从工具盒里取出精密螺丝刀,按住并旋开四颗小螺丝,再把旧电池弹出来。 每一步都涉及不同的物体、接触方式、力度控制和操作技巧。 更麻烦的是,现实世界里的电池盒、螺丝、包装和工具可能长得完全不同,机器人必须在陌生环境里连续完成这些操作。 当然,今天完全可以训练一个专门的机器人完成换电池任务。 但如果换一个南瓜灯,换一种电池盒,或者把工具放到另一个抽屉里,它还能不能完成? 这才是问题所在。 其实 Carmack 之前还提出过一个类似的测试:让那些会跳舞的机器人拿起游戏手柄,学习一款从未见过的电子游戏。 我觉得他的思路很有价值。 现在我们看到的很多人形机器人演示,已经具备相当惊人的运动能力。 但距离真正可靠的通用操作,仍然有很长的路要走。 机器人可以完成一个极其复杂的预设动作,却可能在一件极其简单的陌生任务面前束手无策。 马斯克 @elonmusk 都在评论区回复了一句: 「这些才是真正的 Benchmark。」 确实,未来衡量具身智能的进步,或许应该多看看它们能不能独立处理那些生活中琐碎、陌生、没有提前排练过的任务。 毕竟,人类的日常生活里,到处都是这样的长尾问题。
    John Carmack @ID_AA_Carmack
    I see how some people can watch flashy robot demos on the timeline and think with a shiver that the robot apocalypse is around the corner, but reality check: There is no robot in the world that can change the batteries in a jack-o-lantern. If you have a robot friendly door handle it might be able to walk outside, pick it up, and carry it back inside. The robot could open the drawer with your batteries in it, but then things get tough. Opening the package of AA batteries? Extracting a precision screwdriver from its case? Unscrewing four tiny screws that require a hard press and twist? Popping batteries out of the case? Yes, you could build and train a specialist robot to do that today, but there is a very long way to go to replace the full range of human capabilities. Near term doomer scenarios should stop at “secretly controlling humanity” instead of “wiping humanity out” 😀
    180235.1K
  21. John Carmack✓@ID_AA_Carmack
    I see how some people can watch flashy robot demos on the timeline and think with a shiver that the robot apocalypse is around the corner, but reality check: There is no robot in the world that can change the batteries in a jack-o-lantern. If you have a robot friendly door handle it might be able to walk outside, pick it up, and carry it back inside. The robot could open the drawer with your batteries in it, but then things get tough. Opening the package of AA batteries? Extracting a precision screwdriver from its case? Unscrewing four tiny screws that require a hard press and twist? Popping batteries out of the case? Yes, you could build and train a specialist robot to do that today, but there is a very long way to go to replace the full range of human capabilities. Near term doomer scenarios should stop at “secretly controlling humanity” instead of “wiping humanity out” 😀
    7294237.7K1.3M
  22. Max For AI✓@MaxForAI
    救命,为什么老外也知道了。。🤣 中国第一部全流程 AI 制作的院线长片票房扑街,居然被 @Polymarket 发到了 X 上,开始接受全球网友围观了。 这部电影叫《三星堆:未来往事》,10 月 23 日正式上映,制作团队近百人,花了两年时间,制作成本超过 1000 万元。 结果上映四天,累计票房只有约 123 万元,上座率一度跌到 0.2%,平均一场电影只有 0.3 个观众。 不过,我觉得这事其实挺值得思考的。 这几年 AI 视频生成的能力确实进步得非常快,制作一部动画电影的技术门槛正在不断下降。 但问题是,观众为什么要为一部电影买单? AI 能把制作成本降低十倍、一百倍,却没办法自动让一个无聊的故事变得有趣。 过去电影制作昂贵,技术、资金和发行渠道本身就是门槛。 未来当制作成本越来越低,真正稀缺的东西可能会重新回到创作者身上:审美、表达、叙事能力,以及对人类情感的理解。 我依然非常看好 AI 影视的发展,但这次票房至少说明了一件事: 观众不会因为一部电影是 AI 做的,就愿意花钱走进电影院。 电影好看才是硬道理。
    Polymarket @Polymarket
    JUST IN: China's first fully AI-generated movie suffers a disastrous box office debut, grossing just $181,000 against a reported $1.5 million production budget.
    2087821.9K
  23. Polymarket✓@Polymarket
    JUST IN: China's first fully AI-generated movie suffers a disastrous box office debut, grossing just $181,000 against a reported $1.5 million production budget.
    1761552.7K167K
  24. Max For AI✓@MaxForAI
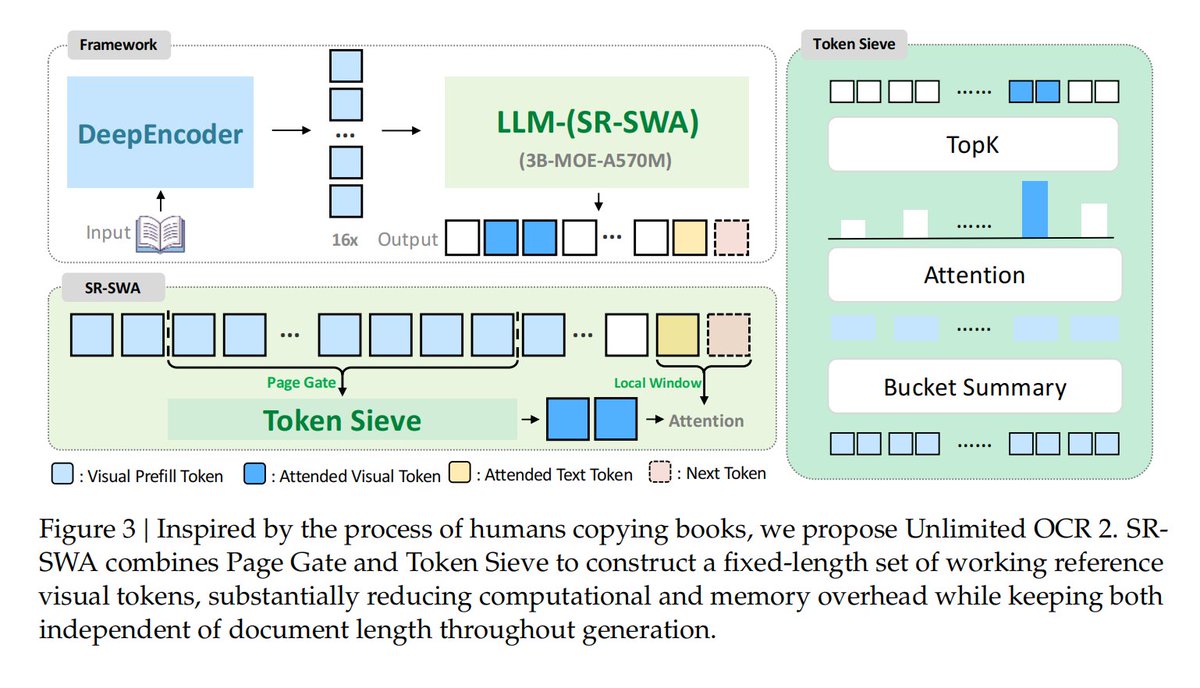
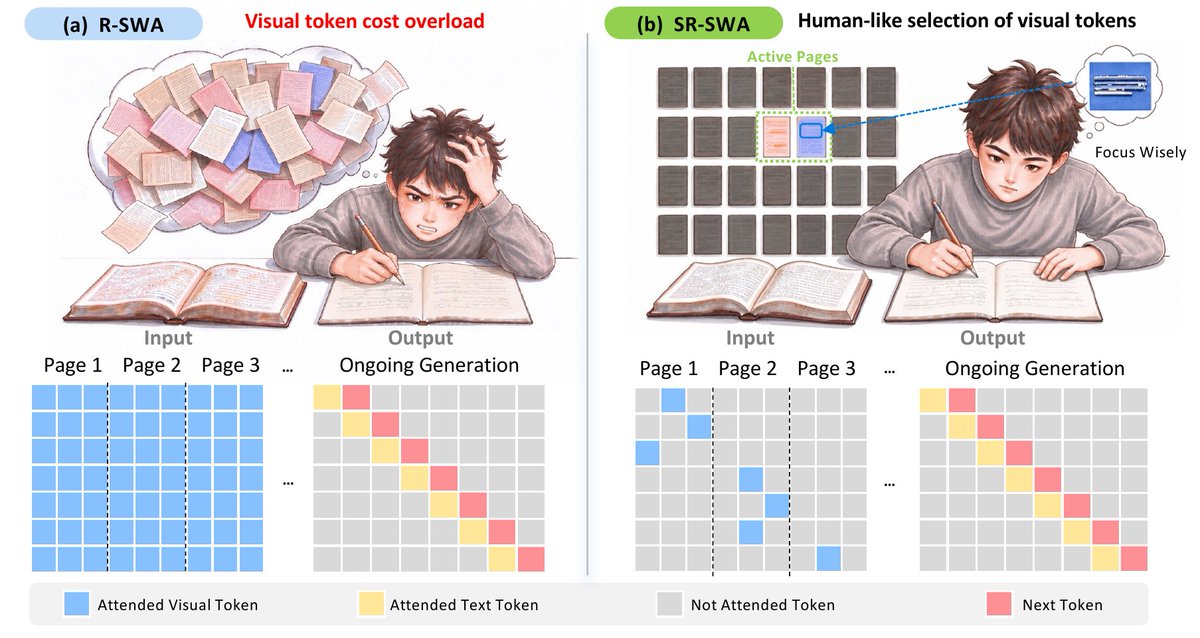
    👀OCR最严厉的父亲,百度文心又发新模型了。 今天,百度开源了文心Unlimited OCR2,直接拿3600多页的《哈利·波特》七部全集做OCR测试,甚至还顺手把1200多页的《三体》全集也给解析了一遍。 我看了一下技术报告,这次还挺有意思的。 对比百度之前的一代Unlimited OCR,当时就靠着可以一次性解析几十页文档的能力,在HuggingFace上拿到了超过1000万次下载,GitHub也积累了将近3万Stars。 但上一代其实还留下了一个很麻烦的问题。 虽然它通过滑动窗口机制,解决了长文档解析过程中部分KV Cache不断膨胀的问题,但每次生成新的Token,模型仍然需要关注前面所有页面的视觉信息。 这就导致一个很尴尬的情况:文档越长,每一步计算就越慢。 到了几百页的时候,光是反复处理那些已经看过的视觉Token,就会产生巨大的计算开销。 所以百度这次干脆换了一个思路。 他们发现,人类在抄一本几千页的书时,其实根本不会每抄一页,就重新把前面几千页全部看一遍。 正常人只会专注于当前页面,偶尔回头参考一下需要的信息。 于是,他们借鉴这个习惯,搞出了一套新的稀疏参考滑动窗口注意力机制(SR-SWA)。 简单来说,就是Page Gate负责确定当前应该关注哪些页面,Token Sieve再从里面挑出最有价值的视觉信息块。 同时,他们还加入了新的无限解码机制,把整本书分成连续的几个部分来处理,复用相邻部分的KVCache,处理完的部分就释放掉。 这样模型就可以一直往后读,而不需要把整本书的视觉缓存都塞进显存里。 效果还挺夸张的。 在他们新提出的百页级文档解析基准MarathonDoc Bench上,Unlimited OCR-2拿到了77.06分,第二名Kimi K3只有33.74分。 处理百页级文档时,单步解码速度相比Full Attention提升了7倍。 另一组测试中,KVCache峰值显存占用从47GB直接降到了1.77GB。 而且这个模型的总参数量只有3B,每个Token实际激活大约5亿参数。 现在回头看,从上一代的几十页,到这一代展示的几千页,百度算是沿着这条技术路线一直往前推。 这次尤其有意思的地方在于,他们通过新的注意力机制和分块解码,让模型能够持续处理长度几乎不受限制的文档,同时将单步解码的计算开销和显存占用控制在相对固定的水平。 论文目前在最高 300 页的文档上进行了系统性的精度评测,同时展示了连续解析 1200 多页《三体》和 3600 多页《哈利·波特》的案例。 我觉得这件事放到 Agent 时代会越来越有价值。 未来 Agent 要接管的真实工作,可能就是从几百页的财报里提取数据,从几千页的合同附件里核对条款,或者把一整套技术文档整理成可以直接使用的信息。 如果连这些基础资料都无法稳定、低成本地解析,后面再强的推理和执行能力也很难充分发挥出来。 现在中国的开源生态已经开始形成这样的技术接力:一个团队的研究成果,成为另一个团队继续创新的基础,新的模型又被开源出来,供更多开发者使用。 我觉得这也是开源最有价值的地方。 大家可以站在彼此的肩膀上,把原本昂贵、复杂的技术,一点点变成所有人都能用上的基础能力。 GitHub:
    Download
    Baidu Inc. @Baidu_Inc
    Unlimited OCR 2 is here, and it's open source. 📖 ✨ Longer documents can mean a lot more attention computation. Our new SR-SWA mechanism keeps that in check by condensing text-visual attention interactions into a fixed-size set of working references. Here's what it delivers: - Document parsing at virtually any length, within a finite context window - Nearly constant per-step decoding latency and memory footprint as documents grow longer - State-of-the-art performance on MPDocBench and MarathonDocBench, covering documents from dozens to hundreds of pages Check out the model here ↓
    1499613.6K
  25. Baidu Inc.@Baidu_Inc
    Unlimited OCR 2 is here, and it's open source. 📖 ✨ Longer documents can mean a lot more attention computation. Our new SR-SWA mechanism keeps that in check by condensing text-visual attention interactions into a fixed-size set of working references. Here's what it delivers: - Document parsing at virtually any length, within a finite context window - Nearly constant per-step decoding latency and memory footprint as documents grow longer - State-of-the-art performance on MPDocBench and MarathonDocBench, covering documents from dozens to hundreds of pages Check out the model here ↓
    Download
    641161.1K161K
  26. Max For AI✓@MaxForAI
    我已经到下一个阶段了:AI比我强,怎么还没有AGI给我取代了🫲😭🫱
    Download
    140313.8K
  27. Max For AI✓@MaxForAI
    🇨🇳中国大陆版本✅
    Download
    ses @sesanaallen
    Now kiss
    121938.9K
  28. ses✓@sesanaallen
    Now kiss
    Download
    3514K62.5K1.5M
  29. Show more posts