Tim Rocktäschel✓

@_rockt

Co-Founder and Chief Scientist of @Recursive_SI, Professor of AI @AI_UCL, PI @BOLD_Lab_AI, Fellow @ELLISforEurope. Ex @GoogleDeepMind @AIatMeta @CompSciOxford

1.9K Following50.2K Followers6.1K Posts
  1. Tim Rocktäschel✓@_rockt
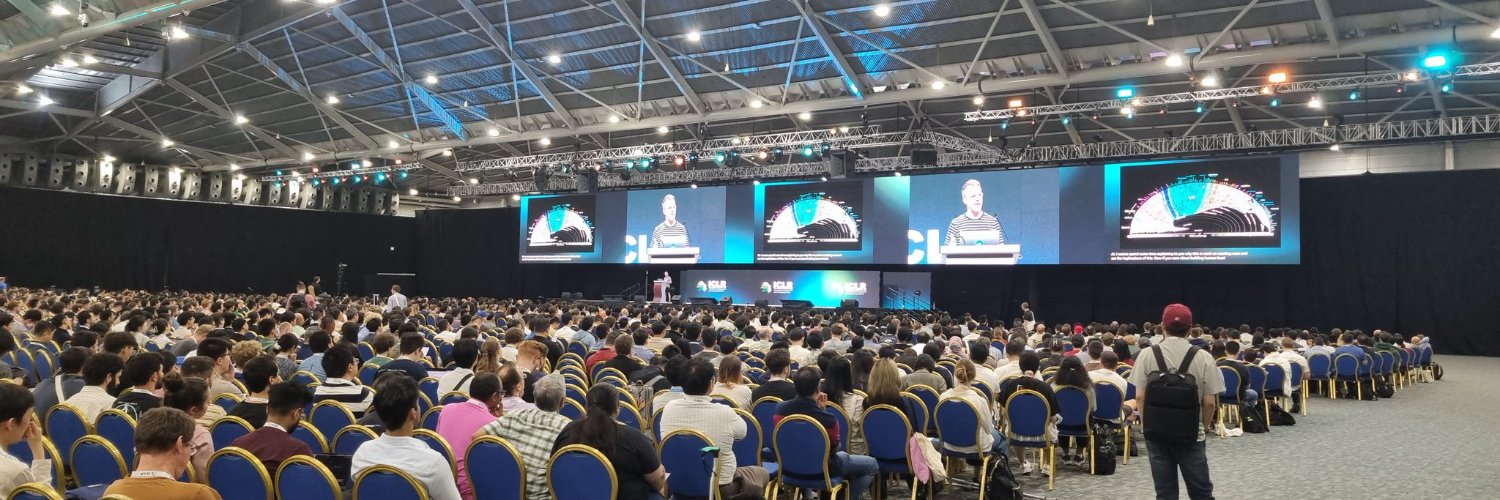
    My @iclr_conf 2025 Keynote on "Open-Endedness, World Models, and the Automation of Innovation" is now publicly available:
    134339769.2K
  2. Tim Rocktäschel✓@_rockt
    Congrats, really impressive scene capture capabilities!
    SpAItial AI @SpAItial_AI
    Introducing Echo-3. A state-of-the-art world model. Echo-3 turns phone captures into photorealistic, metric-scale 3D worlds. From a single room to multi-floor buildings, outdoor and public spaces. Available today.
    21182.3K
  3. SpAItial AI✓@SpAItial_AI
    Introducing Echo-3. A state-of-the-art world model. Echo-3 turns phone captures into photorealistic, metric-scale 3D worlds. From a single room to multi-floor buildings, outdoor and public spaces. Available today.
    Download
    932351.9K289K
  4. Tim Rocktäschel✓@_rockt
    Congrats to my former @GoogleDeepMind colleagues on Genie 4!
    Google DeepMind @GoogleDeepMind
    This is Genie 4, our most realistic and interactive world model yet. 🌐 Explore dynamic environments in real time to see how the scene responds, sounds, and how the people in it move, react, and speak.
    10312.4K
  5. Google DeepMind@GoogleDeepMind
    This is Genie 4, our most realistic and interactive world model yet. 🌐 Explore dynamic environments in real time to see how the scene responds, sounds, and how the people in it move, react, and speak.
    Download
    9262.5K23K3.2M
  6. Tim Rocktäschel✓@_rockt
    Great news for doing science on autoresearch swarms at home.
    Cong Lu @cong_ml
    1/ You can now run a research swarm entirely on your Mac, model included. Eight agents share one local 40B Flint model on a 48 GB M4 Pro: writing code, testing ideas and building on whatever works. Give them a problem and a score to beat. Here's how 🧵
    110887.2K
  7. Cong Lu✓@cong_ml
    1/ You can now run a research swarm entirely on your Mac, model included. Eight agents share one local 40B Flint model on a 48 GB M4 Pro: writing code, testing ideas and building on whatever works. Give them a problem and a score to beat. Here's how 🧵
    Download
    277064561.9K
  8. Tim Rocktäschel✓@_rockt
    Tim Rocktäschel
    RT @atomic_chat_hq: Run Flint locally on 24GB Mac 💻 We released our quant ladder for @Recursive_SI's new 40B coding model on Hugging Face from 42.9GB down to 13.3GB We recommend the 13.3GB AD-IQ2_XXS for 24 GB hardware with room for about 95K tokens of context GGUFs 👇
    Richard Socher @RichardSocher
    Introducing Flint, @Recursive_SI’s first model: a fast local coding model built with our automated research system, the Eureka Machine. • Best-in-class fast local coding • Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark • Built from scratch in under 4 months Private, unmetered intelligence on your own machine. Open weights available now on @huggingface, run it locally on your favorite framework or try it for free on @opencode or @pidotdev.
    0100130
  9. Richard Socher✓@RichardSocher
    Introducing Flint, @Recursive_SI’s first model: a fast local coding model built with our automated research system, the Eureka Machine. • Best-in-class fast local coding • Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark • Built from scratch in under 4 months Private, unmetered intelligence on your own machine. Open weights available now on @huggingface, run it locally on your favorite framework or try it for free on @opencode or @pidotdev.
    Download
    6388948.4K3.4M
  10. Tim Rocktäschel✓@_rockt
    Tim Rocktäschel
    RT @nimorotem: I've been a heavy Qwen user. Now 100% on @Recursive_SI 's Flint. I built this side by side test, running both models at 8bit on the same hardware (RTX A6000 48Gb) try it: (This is running locally on two identical cards) BTW 4 bit is even faster.
    John T Davies 🇪🇺 @jtdavies
    OK, I've had a little play with this 40B MoE Flint model, here are my findings. It's a good model but at 40B it needs to be compared to models a similar size and the Qwen3.6-35B MoE and Qwen3.8-27B are both smaller so make ideal candidates. See thread below...
    050133
  11. John T Davies 🇪🇺✓@jtdavies
    OK, I've had a little play with this 40B MoE Flint model, here are my findings. It's a good model but at 40B it needs to be compared to models a similar size and the Qwen3.6-35B MoE and Qwen3.8-27B are both smaller so make ideal candidates. See thread below...
    Richard Socher @RichardSocher
    Introducing Flint, @Recursive_SI’s first model: a fast local coding model built with our automated research system, the Eureka Machine. • Best-in-class fast local coding • Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark • Built from scratch in under 4 months Private, unmetered intelligence on your own machine. Open weights available now on @huggingface, run it locally on your favorite framework or try it for free on @opencode or @pidotdev.
    11143189K
  12. Tim Rocktäschel✓@_rockt
    Tim Rocktäschel
    RT @atomicagent_io: Recursive Flint 4.7x faster than Nemotron 3.5 🎃 We gave Flint, Ornith and Nemotron the same prompt in Atomic Local AI Agent’s orchestration mode, where Opus plans and the local models get the task done Try Atomic Fusion ->
    Richard Socher @RichardSocher
    Introducing Flint, @Recursive_SI’s first model: a fast local coding model built with our automated research system, the Eureka Machine. • Best-in-class fast local coding • Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark • Built from scratch in under 4 months Private, unmetered intelligence on your own machine. Open weights available now on @huggingface, run it locally on your favorite framework or try it for free on @opencode or @pidotdev.
    0120129
  13. Tim Rocktäschel✓@_rockt
    Tim Rocktäschel
    RT @rapidmlx: Sneak peek: Flint from @Recursive_SI now runs in Rapid-MLX. 🔥 Measured on a 36 GB M5 Max with 4-bit weights, greedy, 256 output tokens: ⚡ ~1K context: 131 tok/s decode, 0.35 s TTFT 📄 ~8K context: 118 tok/s decode, 2.2 s TTFT 👥 4 concurrent requests: 193 tok/s aggregate ♻️ Prefix cache: repeat-prompt TTFT 0.46 s → 0.15 s 💾 Peak memory: ~24 GB Tool calls, streaming and 8K+ context all work out of the box with an OpenAI-compatible API. Ships in the next release. Can't wait? Build from main: git clone && cd Rapid-MLX pip install . rapid-mlx serve flint-40b-a2.5b-4bit
    Richard Socher @RichardSocher
    Introducing Flint, @Recursive_SI’s first model: a fast local coding model built with our automated research system, the Eureka Machine. • Best-in-class fast local coding • Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark • Built from scratch in under 4 months Private, unmetered intelligence on your own machine. Open weights available now on @huggingface, run it locally on your favorite framework or try it for free on @opencode or @pidotdev.
    050122
  14. Tim Rocktäschel✓@_rockt
    Tim Rocktäschel
    RT @josh_tobin_: I was kind of shocked that autoresearch works as well as this with a tiny model like Flint
    Cong Lu @cong_ml
    1/ From OpenAI's Navier–Stokes work to AlphaEvolve's faster algorithms, AI research is getting very real. Now, with Recursive Flint, we can experience that magic locally on our own laptops 💻 The whole research loop runs locally with a selection of tasks! Code + demos 🧵
    070103
  15. Cong Lu✓@cong_ml
    1/ From OpenAI's Navier–Stokes work to AlphaEvolve's faster algorithms, AI research is getting very real. Now, with Recursive Flint, we can experience that magic locally on our own laptops 💻 The whole research loop runs locally with a selection of tasks! Code + demos 🧵
    Download
    173933246.5K
  16. Tim Rocktäschel✓@_rockt
    Tim Rocktäschel
    RT @cong_ml: 1/ Can a model that runs on a laptop also drive GPU training research? Recursive Flint, our new 40B open model, improved NanoChat across 700+ experiments—finishing close to our historical Claude Haiku 4.5 results. We were pleasantly surprised. Here's what it tried 🧵
    050137
  17. Tim Rocktäschel✓@_rockt
    Tim Rocktäschel
    RT @spolen23: Had my agent race Flint against Qwen3.8 27B on my Mac Studio with a couple real coding tasks. Flint did 110 tok/s vs 28 and nailed every one. Qwen thought for 7 minutes on one and never answered. And Recursive's fast kernels don't even support my M4 Max yet. New local default.
    Richard Socher @RichardSocher
    Introducing Flint, @Recursive_SI’s first model: a fast local coding model built with our automated research system, the Eureka Machine. • Best-in-class fast local coding • Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark • Built from scratch in under 4 months Private, unmetered intelligence on your own machine. Open weights available now on @huggingface, run it locally on your favorite framework or try it for free on @opencode or @pidotdev.
    010135
  18. Tim Rocktäschel✓@_rockt
    Tim Rocktäschel
    RT @ka1n0s: darkmux supports Flint and rec. This table compares Flint on the Macbook Pro 128 GB M5 Max, with qwen 3.6 35B-A3B turboquant served by LM Studio. The eval in this case is my very own pepper-grinder fixture. congrats to the @Recursive_SI on a successful launch.
    010120
  19. Tim Rocktäschel✓@_rockt
    Tim Rocktäschel
    RT @UnslothAI: Run Flint locally on 24GB RAM via Unsloth Dynamic GGUFs! Flint is the strongest MoE model under 50B parameters. Recursive’s Apache-2.0 model has 39.8B parameters (2.5B active). Run at 125 t/s on Mac, 150 on RTX Spark GGUF: Guide:
    Richard Socher @RichardSocher
    Introducing Flint, @Recursive_SI’s first model: a fast local coding model built with our automated research system, the Eureka Machine. • Best-in-class fast local coding • Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark • Built from scratch in under 4 months Private, unmetered intelligence on your own machine. Open weights available now on @huggingface, run it locally on your favorite framework or try it for free on @opencode or @pidotdev.
    0930108
  20. Tim Rocktäschel✓@_rockt
    Tim Rocktäschel
    RT @tydsh: Today, we release our first model, Flint-40B-A2B, a fast local coding model built with our automated research system. 1. Strong performance. 54.9% on Terminal-Bench 2.1, 89.7% on SWE-bench Pro v2, and 74.2% on SWE-bench Verified. 2. It is trained from scratch (tokenizer->Pretrain->Midtrain->SFT->RL). 3. Fast in your local laptop. Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark. 4. We build the complete model training pipeline in 4 month!
    Richard Socher @RichardSocher
    Introducing Flint, @Recursive_SI’s first model: a fast local coding model built with our automated research system, the Eureka Machine. • Best-in-class fast local coding • Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark • Built from scratch in under 4 months Private, unmetered intelligence on your own machine. Open weights available now on @huggingface, run it locally on your favorite framework or try it for free on @opencode or @pidotdev.
    090098
  21. Tim Rocktäschel✓@_rockt
    Tim Rocktäschel
    RT @anh_ng8: Incredibly fun journey building the RSI loop(s) that led to a best-in-class local coding LLM. A few simple coding examples Flint could do in < 10 mins. 0 endpoint. 0$. Full CoTs. Stay tuned for more! ps: Fable made this video from the artifacts alone. No editing.
    Richard Socher @RichardSocher
    Introducing Flint, @Recursive_SI’s first model: a fast local coding model built with our automated research system, the Eureka Machine. • Best-in-class fast local coding • Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark • Built from scratch in under 4 months Private, unmetered intelligence on your own machine. Open weights available now on @huggingface, run it locally on your favorite framework or try it for free on @opencode or @pidotdev.
    090131
  22. Tim Rocktäschel✓@_rockt
    Tim Rocktäschel
    RT @_victorvel: 88.8 tok/s on an M5 Pro over an 11.9k-token generation, via LM Studio, fully offline. And the quality is really good, better than I expected from a model this fast. Congrats to the @Recursive_SI team!
    Tim Shi @timshi_ai
    Flint is our first model built with the Eureka Machine, our automated research system, from scratch in 4 months. We are betting that labs that automate AI research will outrun the labs that just hire more researchers. Check it out today for fast, local and unmetered intelligence.
    010126
  23. Tim Shi✓@timshi_ai
    Flint is our first model built with the Eureka Machine, our automated research system, from scratch in 4 months. We are betting that labs that automate AI research will outrun the labs that just hire more researchers. Check it out today for fast, local and unmetered intelligence.
    Richard Socher @RichardSocher
    Introducing Flint, @Recursive_SI’s first model: a fast local coding model built with our automated research system, the Eureka Machine. • Best-in-class fast local coding • Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark • Built from scratch in under 4 months Private, unmetered intelligence on your own machine. Open weights available now on @huggingface, run it locally on your favorite framework or try it for free on @opencode or @pidotdev.
    30141186.8K
  24. Tim Rocktäschel✓@_rockt
    Tim Rocktäschel
    RT @thulme: Evolution created the 20W human brain through open-ended search, pushing compute to the edge so latency wouldn't let entropy win. @Recursive_SI is running accelerated evolution. Instead of hiring more researchers, their Eureka Machine built Flint in under 4 months.
    030111
  25. Tim Rocktäschel✓@_rockt
    Tim Rocktäschel
    RT @WangCankun: Tested on MacBook Pro M5 MAX 64GB - Model: Recursive Flint (40B MoE, 2.5B active), int4 MLX via rec, in pi - TPS: 114–132 output tok/s
    Richard Socher @RichardSocher
    Introducing Flint, @Recursive_SI’s first model: a fast local coding model built with our automated research system, the Eureka Machine. • Best-in-class fast local coding • Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark • Built from scratch in under 4 months Private, unmetered intelligence on your own machine. Open weights available now on @huggingface, run it locally on your favorite framework or try it for free on @opencode or @pidotdev.
    030114
  26. Tim Rocktäschel✓@_rockt
    Tim Rocktäschel
    RT @OpenHandsDev: Excited to support for @Recursive_SI Flint 🚀 40B parameters, just 2.5B active per token, built for fast local coding inference. We’ve tested it with OpenHands. Now developers have another open model for real engineering workflows.
    030100
  27. Tim Rocktäschel✓@_rockt
    Tim Rocktäschel
    RT @OpenRouter: Flint from @Recursive_SI is now on OpenRouter! Recursive's first model: an open-weight 40B MoE (~2.5B active) built for coding agents by their autoresearch system, the Eureka Machine. 262K context, reasoning and tool calling. Recursive reports 54.9% on Terminal-Bench 2.1, 89.7% on SWE-bench Pro v2 and 74.2% on SWE-bench Verified. Free to use at launch. Try it now:
    Richard Socher @RichardSocher
    Introducing Flint, @Recursive_SI’s first model: a fast local coding model built with our automated research system, the Eureka Machine. • Best-in-class fast local coding • Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark • Built from scratch in under 4 months Private, unmetered intelligence on your own machine. Open weights available now on @huggingface, run it locally on your favorite framework or try it for free on @opencode or @pidotdev.
    0200102