Posts with #AudioAI

#AudioAI

Public posts on X that use #AudioAI.

Related hashtags

  1. Eliya Nachmani@NachmaniEliya
    🎧 A new type of audio tokens ✨ GS-Codec, accepted to NeurIPS! Instead of representing audio with discrete codebook tokens, GS-Codec represents audio using parameterized 1D Gaussian primitives. 📄 Paper w/ Ron Aluf and Alon Canfi #NeurIPS #AudioAI #ML
    Download
    103228
  2. Mirco Ravanelli@mirco_ravanelli
    Great work by Jihoon Jeong! Can multi-task self-supervised learning improve audio language models' reasoning? In our latest work, we show promising results in this direction! #AudioAI #MachineLearning
    Jihoon Jeong @jhjeong98
    Audio-R1 🎧 SSL is still in the game. Now with RL rewards. We turn self-supervised audio tasks into verifiable rewards for RL, improving audio-language models on downstream tasks beyond those used in training. 🌐
    00171.1K
  3. Jihoon Jeong@jhjeong98
    Audio-R1 🎧 SSL is still in the game. Now with RL rewards. We turn self-supervised audio tasks into verifiable rewards for RL, improving audio-language models on downstream tasks beyond those used in training. 🌐
    Download
    1111045K
  4. aynursusuz@aigirl244096
    Built an Audio Quality Assessment Space on @huggingface 🎧 It gives a quick technical overview of audio through loudness, noise, dynamic range, clipping, silence, waveform, and spectrogram analysis. Which metric should I add? #AudioAI #TTS #HuggingFace
    Download
    219523
  5. Orchestral Pit@OrchestralPit
    Hidden neurons in audio classifiers map to human-understandable symbolic concepts. Move beyond input attribution to interpret what models learn internally. #AudioAI #Explainability #MIR
    0005
  6. Haolin He@HarlandZZC
    We found LALMs can answer ~50% of questions with SILENT input on the major benchmark. We present AudioMCQ: largest LALMs post-training dataset (571k samples) & Audio-Contribution-Aware SFT-RL post-training paradigm, achieving new SOTA Paper: #AudioAI
    Download
    337309
  7. Slator✓@slatornews
    Why focus and domain expertise matter in #AI with AudioStack’s Peadar Coyle 🎙 Catch up on 📺 Or head over to Apple Podcasts 👉 and Spotify 👉 #VoiceAI #AudioAI @Springcoil
    Download
    004190
  8. enochagram@Enochagram01
    19 yr Solo developer Day 4: Session Page Ready 📂 Also built the Session Page, where users can see their uploaded documents neatly organized. From here, they’ll soon be able to start audio conversations with AI directly from any file. #AudioAI #Productivity #buildinpublic
    Download
    10349
  9. S3dat✓@s3datlab
    Hume introduced an API on November 2 for questions about speech and sound. Access is through a waitlist. Follow @s3datlab for daily AI analysis. #HumeAI #AudioAI
    Download
    0002
  10. Max✓@MH2025_Official
    Not every premium domain gets built overnight. Some become strategic assets first. 👂 Available for acquisition. #AI #VoiceAI #AudioAI #Headphones #Domains #DomainForSale
    Download
    Mike Domainer @MikeDomainer
    Youcoin .com seems not responsive at all. These thousands of dollars sales makes you thinking.
    229519
  11. Shiek Javeed@shaikjaved100
    🎧 SAM Audio brings Segment Anything to sound. Isolate voices, instruments, or noise from complex mixes using text, clicks, or time ranges. One model instead of many tools. Open source and available now. Audio editing just got easier. @Meta #AInews #AudioAI #MetaAI #OpenSource
    Download
    04495
  12. 2DAI: Creative Gen AI Community✓@2DAICommunity
    🌊🐧 Be prepared for an unforgettable experience as we showcase our new technical demo of our #2DAI Motion AI v2 (#AIVideo engine), combined with our new cutting-edge #AudioAI engine! Witness a captivating penguin swimming in the ocean against a breathtaking mountain backdrop. This is just a glimpse into the future of #AI-powered video content. Stay tuned for the upcoming updates and get ready to dive in! 🤯
    Download
    616439.9K
  13. AITopTools✓@aitoptools
    Just listed: Coolo AI — a browser-based audio tool that separates songs into vocals, drums, bass, and more, and cleans audio by reducing noise and reverb. Perfect for creators, DJs, music teachers, and karaoke fans. Try it now: #audioAI
    312158
  14. Milvus✓@milvusio
    1/ 🎧 Dive into the world of Audio Embedding Models! 🔊These AI tools transform raw sound into powerful numerical vectors. Let's explore the TOP 10 models. 🧵 #AudioAI #MachineLearning #EmbeddingModels
    112154
  15. Milvus✓@milvusio
    @milvusio
    12/ Pro Tip: These models are most powerful when combined with vector databases like #Milvus! 💡 They enable: • Efficient Similarity Searches • Large-Scale Audio Processing • Real-Time Retrieval The future of audio AI is here! 🚀 Popular AI Models:
    112126
  16. AIverse Daily@AIverseDaily
    ElevenLabs: Voice Magic for Creators! 🎙️ ElevenLabs is your secret weapon—generate hyper-realistic voices from text in 29+ languages. Perfect for podcasts, videos, or audiobooks without a mic! Free tier: 10k chars/month. Beginner bonus: Clone your voice in minutes.
    Download
    1114K
  17. AIverse Daily@AIverseDaily
    @AIverseDaily
    Quick start guide: 1. Free sign-up at 2. Paste text or upload audio 3. Pick voice/style (friendly, epic...) 4. Generate & download MP3/WAV 5. Export to your editor—done! Regen for variations. Magic! #AITutorial #PodcastTips
    10133
  18. AIverse Daily@AIverseDaily
    @AIverseDaily
    For creators: Pairs with Canva for quick vids or Descript for edits. 2025 update: AI noise removal + sound effects gen (rain, footsteps). Free limits? Upgrade from $5/mo for unlimited. Scale your indie stories effortlessly. #AICreators #AudioAI
    10228
  19. Mike Domainer@MikeDomainer
    Youcoin .com seems not responsive at all. These thousands of dollars sales makes you thinking.
    Download
    63883.7K
  20. Samuel Zeng✓@SamuelZengML
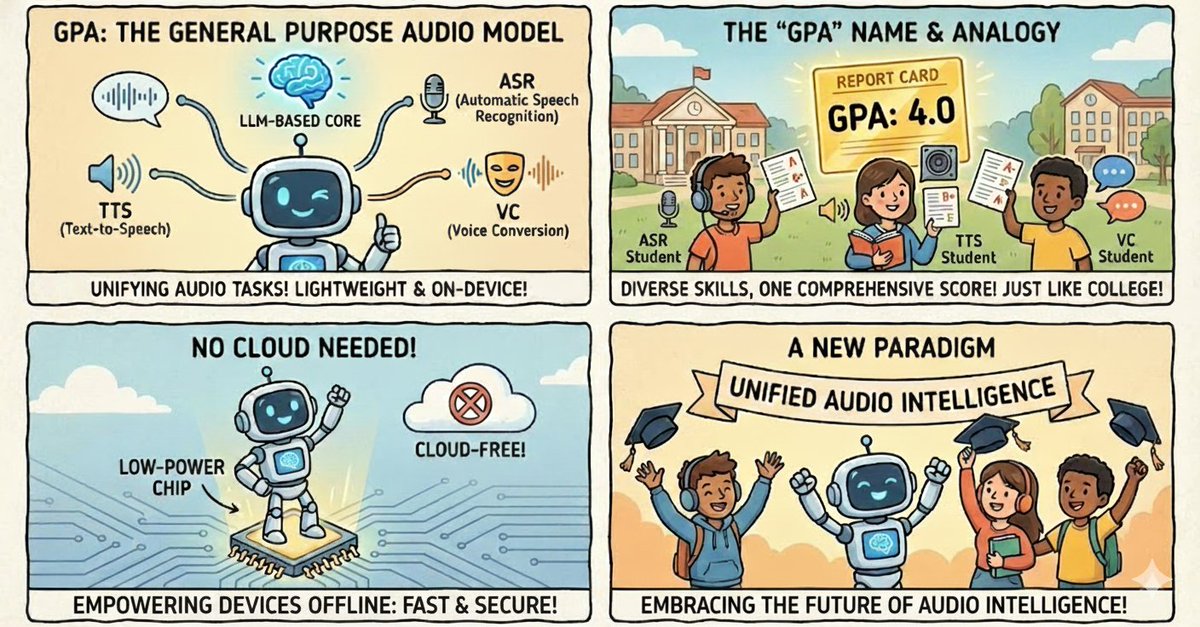
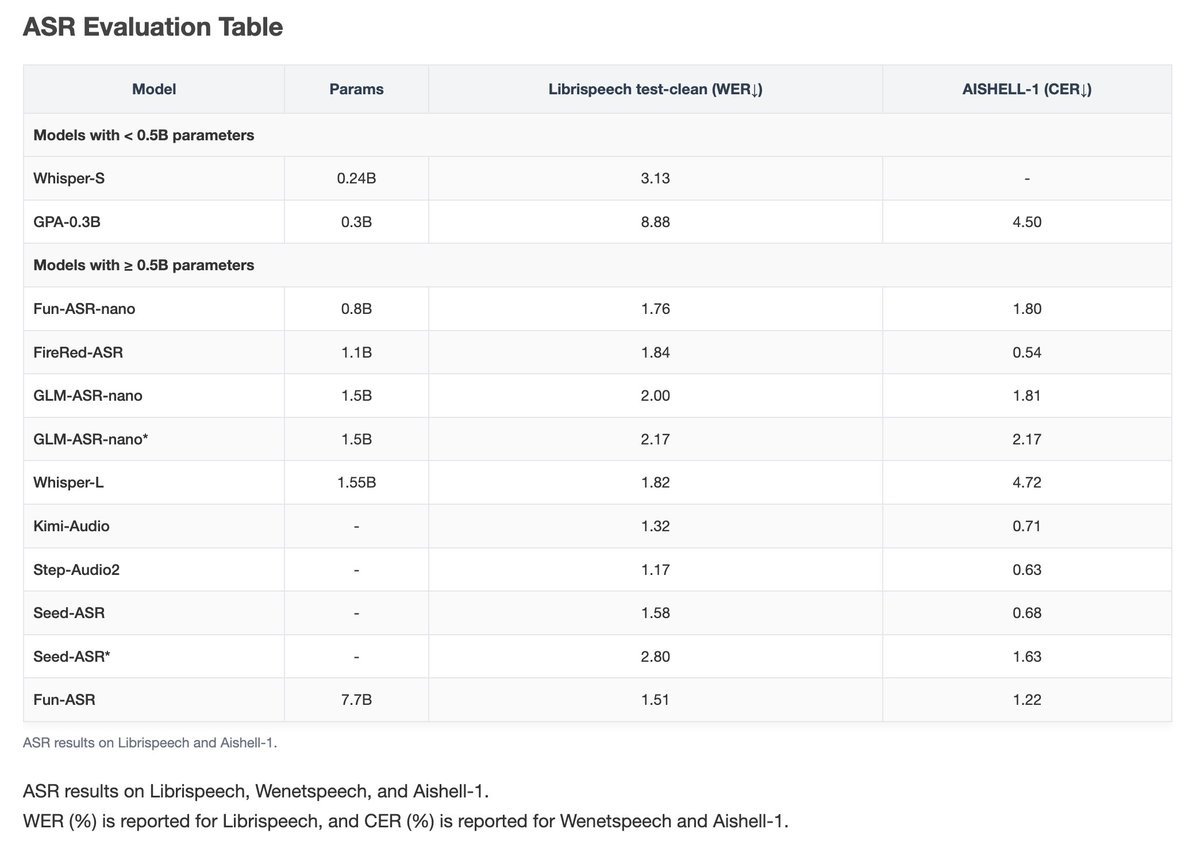
    We are excited to release GPA (General Purpose Audio), a unified model designed to streamline speech processing. Unlike traditional pipelines that chain multiple models, GPA handles TTS, ASR, and VC within a single, cohesive architecture. #AI #SpeechAI #OpenSource
    Download
    349418
  21. Samuel Zeng✓@SamuelZengML
    @SamuelZengML
    On-device AI often struggles with memory bottlenecks. GPA solves this by allowing a single model to handle both input (ASR) and output (TTS). This significantly reduces peak memory usage and computational overhead, making it ideal for mobile and IoT integration. 📱🔋
    Download
    10293
  22. Samuel Zeng✓@SamuelZengML
    @SamuelZengML
    Get Started! Whether you are building high-scale voice agents or lightweight on-device assistants, GPA provides the foundational audio intelligence you need. Check out the documentation and star us on GitHub to follow the development: #AudioAI #OpenSource
    01495
  23. Show more posts