Posts with #Dataselection

#Dataselection

Public posts on X that use #Dataselection.

Related hashtags

  1. Bryan Kian Hsiang Low✓@bryanklow
    Check out our @icmlconf #ICML2026 spotlight! No more cherry-picking of experiments and datasets for #DataSelection problems! Latest Results ⚽️⚽️⚽️ #DataShapley 0-1 Random NASH 5-4 Random (going into penalty shootout)
    Xiao Tian @snoidetx
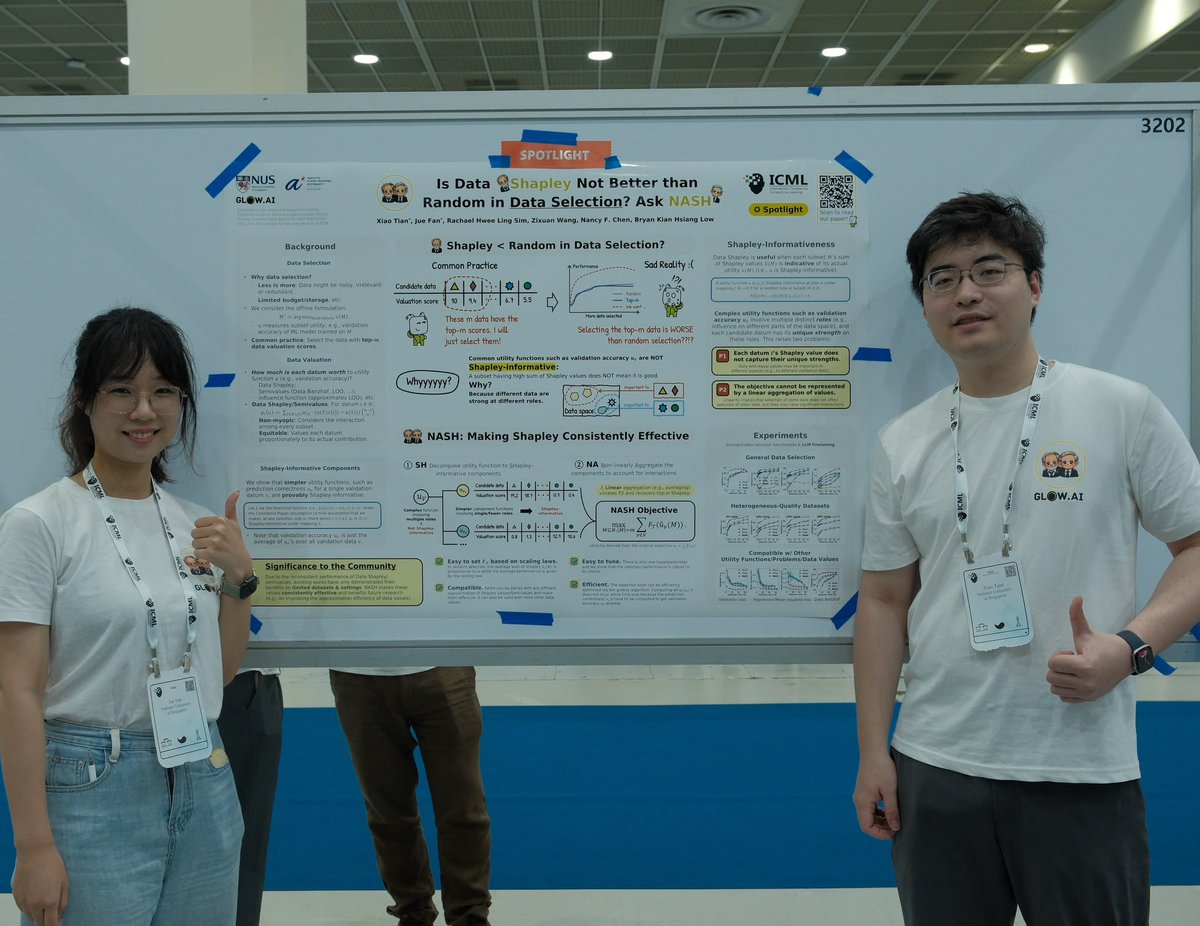
    ✨ 𝐈𝐂𝐌𝐋 2026 𝐒𝐩𝐨𝐭𝐥𝐢𝐠𝐡𝐭✨ In #DataSelection, a common practice is to use #DataValuation methods (e.g., #DataShapley, #Semivalues) to compute the worth of each data point, and select the top-m data points. But more than often, the selection is not even better than random. #DataValuation researchers can only demonstrate on limited datasets and settings. Is #DataShapley really not better than random in data selection? Our #ICML2026 Spotlight paper, NASH, answers NO 🙅‍♀️. What’s the problem? Imagine a company hiring from applicants who each receive an overall score. If the company simply hires the highest-scoring candidates, it may end up with a team full of excellent coders, but no product managers, salespeople, or designers. Top-m applicants ≠ complete team 🙅‍♂️, which needs to fulfil a variety of roles. NASH addresses this by (1) breaking down the complex objective function to multiple simpler components (≈ roles) so that the data values on these components accurately reflect each data point’s unique strengths and weaknesses 📊; (2) forming a new objective which non-linearly aggregates these components so that a data point is preferred when its strengths complement the other selected data points 🧑‍🧑‍🧒‍🧒. NASH consistently and substantially boosts the performance of Data Shapley with minimal additional runtime cost. Future research on #DataShapley would not need to limit their datasets and settings any more 😁. Drop by our poster to say hi or discuss more 🤝! 📍 Poster: #3202 | Hall A 🕔 Time: 8 July 2026 (Wed), 5:00 - 6:45 pm 📖 OpenReview: 📝 Authors: @snoidetx @YvonneFan12 @RachaelSim2 Zixuan Wang, Nancy F. Chen, @bryanklow #DataSelection #DataValuation #MachineLearning #LLM
    008523
  2. Xiao Tian@snoidetx
    ✨ 𝐈𝐂𝐌𝐋 2026 𝐒𝐩𝐨𝐭𝐥𝐢𝐠𝐡𝐭✨ In #DataSelection, a common practice is to use #DataValuation methods (e.g., #DataShapley, #Semivalues) to compute the worth of each data point, and select the top-m data points. But more than often, the selection is not even better than random. #DataValuation researchers can only demonstrate on limited datasets and settings. Is #DataShapley really not better than random in data selection? Our #ICML2026 Spotlight paper, NASH, answers NO 🙅‍♀️. What’s the problem? Imagine a company hiring from applicants who each receive an overall score. If the company simply hires the highest-scoring candidates, it may end up with a team full of excellent coders, but no product managers, salespeople, or designers. Top-m applicants ≠ complete team 🙅‍♂️, which needs to fulfil a variety of roles. NASH addresses this by (1) breaking down the complex objective function to multiple simpler components (≈ roles) so that the data values on these components accurately reflect each data point’s unique strengths and weaknesses 📊; (2) forming a new objective which non-linearly aggregates these components so that a data point is preferred when its strengths complement the other selected data points 🧑‍🧑‍🧒‍🧒. NASH consistently and substantially boosts the performance of Data Shapley with minimal additional runtime cost. Future research on #DataShapley would not need to limit their datasets and settings any more 😁. Drop by our poster to say hi or discuss more 🤝! 📍 Poster: #3202 | Hall A 🕔 Time: 8 July 2026 (Wed), 5:00 - 6:45 pm 📖 OpenReview: 📝 Authors: @snoidetx @YvonneFan12 @RachaelSim2 Zixuan Wang, Nancy F. Chen, @bryanklow #DataSelection #DataValuation #MachineLearning #LLM
    Download
    152010.1K
  3. Xiao Tian@snoidetx
    🫂 Data Shapley x NASH framework 📖 OpenReview: 🍄 Fun fact: In a special case, NASH framework maximizes the Nash welfare. #DataShapley #DataSelection #LLM
    Bryan Kian Hsiang Low @bryanklow
    When will Shapley and Nash ever walk together? Only @icmlconf #ICML2026.
    21111.6K
  4. Bryan Kian Hsiang Low✓@bryanklow
    When will Shapley and Nash ever walk together? Only @icmlconf #ICML2026.
    Download
    Xiao Tian @snoidetx
    ✨ 𝐈𝐂𝐌𝐋 2026 𝐒𝐩𝐨𝐭𝐥𝐢𝐠𝐡𝐭✨ In #DataSelection, a common practice is to use #DataValuation methods (e.g., #DataShapley, #Semivalues) to compute the worth of each data point, and select the top-m data points. But more than often, the selection is not even better than random. #DataValuation researchers can only demonstrate on limited datasets and settings. Is #DataShapley really not better than random in data selection? Our #ICML2026 Spotlight paper, NASH, answers NO 🙅‍♀️. What’s the problem? Imagine a company hiring from applicants who each receive an overall score. If the company simply hires the highest-scoring candidates, it may end up with a team full of excellent coders, but no product managers, salespeople, or designers. Top-m applicants ≠ complete team 🙅‍♂️, which needs to fulfil a variety of roles. NASH addresses this by (1) breaking down the complex objective function to multiple simpler components (≈ roles) so that the data values on these components accurately reflect each data point’s unique strengths and weaknesses 📊; (2) forming a new objective which non-linearly aggregates these components so that a data point is preferred when its strengths complement the other selected data points 🧑‍🧑‍🧒‍🧒. NASH consistently and substantially boosts the performance of Data Shapley with minimal additional runtime cost. Future research on #DataShapley would not need to limit their datasets and settings any more 😁. Drop by our poster to say hi or discuss more 🤝! 📍 Poster: #3202 | Hall A 🕔 Time: 8 July 2026 (Wed), 5:00 - 6:45 pm 📖 OpenReview: 📝 Authors: @snoidetx @YvonneFan12 @RachaelSim2 Zixuan Wang, Nancy F. Chen, @bryanklow #DataSelection #DataValuation #MachineLearning #LLM
    01309.9K
  5. Shaobo Wang✓@ShaoboWang6
    With compute scaling, is data selection now a bigger focus in pretraining/fine-tuning?😇 Or is the community more focused on data composition (e.g., balancing sources), synthetic/distilled data, or curation techniques?🧐 🧠📊 #LLM #DataSelection #AI #GPT #DeepSeek
    005322
  6. Akridata Inc.@akridata
    Data selection involves exploring the entire dataset, identifying key features, and minimizing biases. Learn how to choose wisely, train smartly, and continuously monitor your models to achieve production-grade results. #dataselection
    02260
  7. Vasudev Bailey, PhD@vasudevbailey
    During WWII, the Navy wanted to armor aircrafts. Analysis of where planes were shot came up w/: wingtips, central body, elevators Real soln: nose area, engines, & mid-body. They weren’t looking at the whole sample set, only the survivors. #dataselection Courtesy: Nick Nunno
    Download
    012
  8. Show more posts