Sometimes the best GPU optimization is literally adding useless data🤯
I took a naive CUDA matrix multiplication from 943.10 µs down to 650.24 µs (31.1% faster) just by adding padding to the end of every row.
Wrote a summary :
#CUDA#GPUComputing#AI
CUDA.jl 6.4 is here 🚀
🟢 Improved NVIDIA Jetson support
🟢 Compiled GPU code caching for faster TTFX
🟢 CUDA 13.4 support
🟢 LLVM 23 upgrade
See what's new →
#JuliaLang#CUDA#GPUComputing
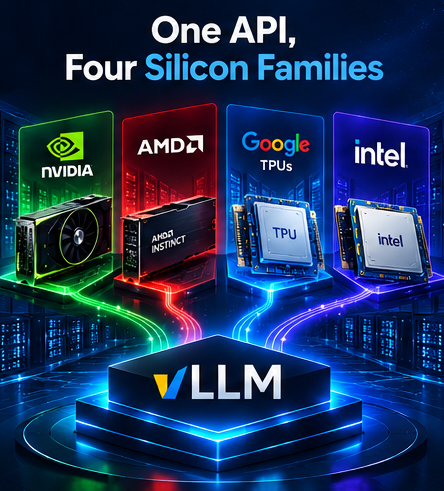
One API. Four silicon ecosystems. ⚡
vLLM can run across NVIDIA, AMD, Google TPU & Intel—but compatibility ≠ equal performance.
The real decision: performance, latency, scale, portability & cost.
📖 Full analysis:
#vLLM#LLMInference#GPUComputing
Made a tunnel running on my raspberry pi,
a workaround to effectively use the gpu, and control it from any device, even mobile
#ai#GPUComputing#SelfHosting
Lambda servers are now available with NVIDIA A40 GPUs. Read our A40 Deep Benchmark blog post to learn how they can accelerate your machine learning workloads.
#deeplearning#machinelearning#gpucomputing
Shark symbolic regression decouples from GPLearn for cleaner extensibility — and with GPU acceleration, it delivers nearly 100x speedup over traditional gplearn. Mining 50 factors from 1.66M rows takes ~9 seconds. #DolphinDB#QuantFinance#GPUComputing
#AI & #GPUComputing are changing how we approach business architecture 💼
Join VP of Research Betsy Burton's webinar TOMORROW at 10 AM PT | 1 PM ET to learn how to strategize for these new models and revamp your architecture plan for 2026
Register now >>
⏰ Starting in 10 Minutes! ⏰
Aragon's VP of Research, Betsy Burton, shares the latest #AI and #GPUComputing insights. Don't miss out on key strategies for the new architecture models of 2026!
Get your free seat now 🙌 :
2/2 We ran an ETL process 20X faster than Apache Spark, that means we're over 95% cheaper! $0.07 running on #T4 GPUs in #GCP vs. $1.39 running on 4 node 8 vCPU cluster. Wait for scale up. And that's the key point, with #GPUComputing the cost savings increase at scale.