Posts with #embedding

#embedding

Public posts on X that use #embedding.

Related hashtags

  1. Google Gemma✓@googlegemma
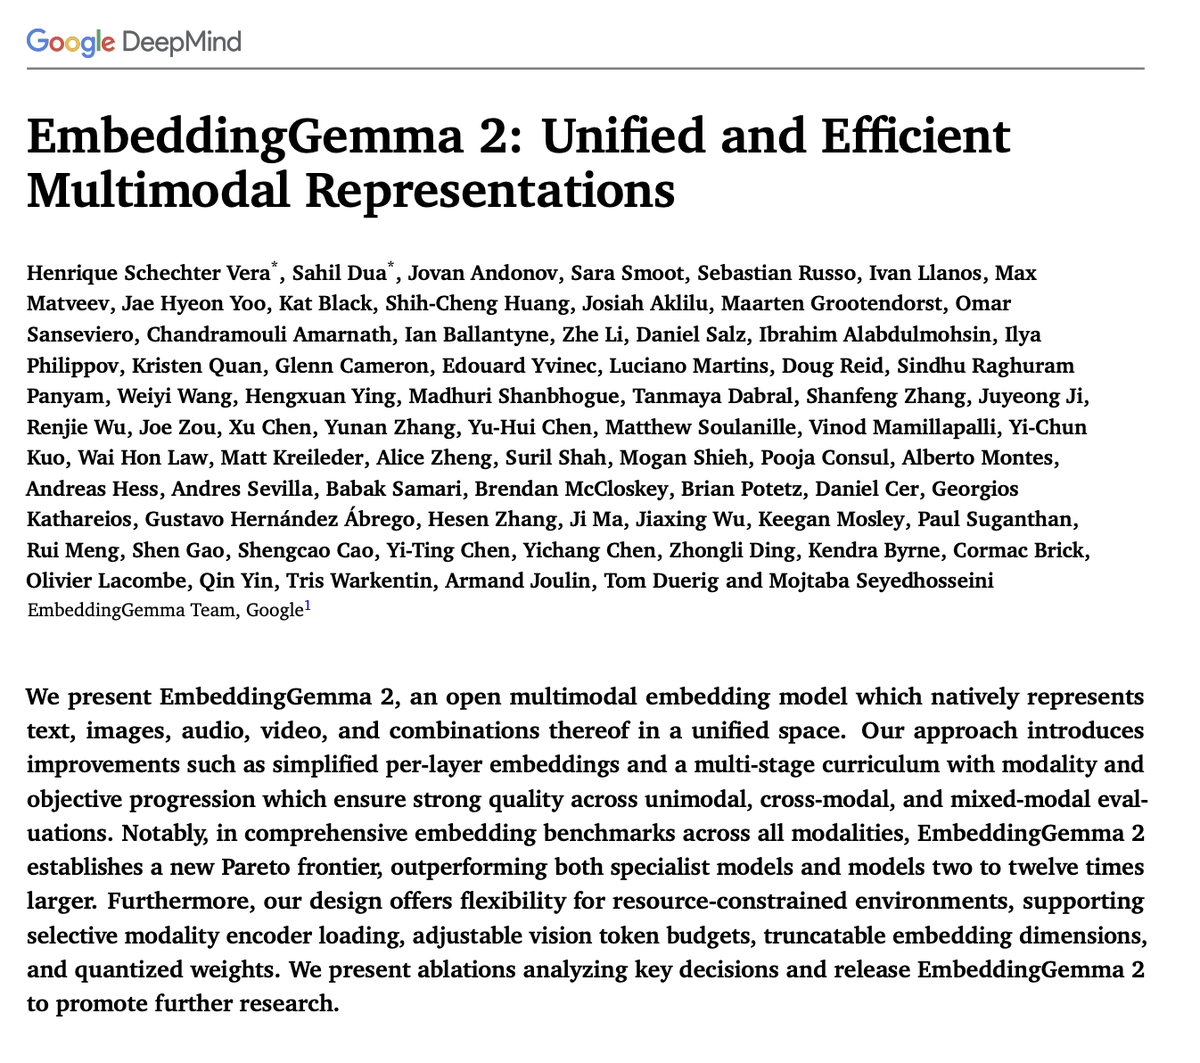
    The EmbeddingGemma 2 tech report is officially live! We are sharing the full architecture, training recipe, and ablations behind our 740M open multimodal embedding model. Inside the paper: 🌐 Unified representations for text, code, images, audio, and video 📈 How it outperforms specialist and general models up to 12x larger ⚡ On-device efficiency: modular encoders, Matryoshka dims, and int4 quantization (down to 567MB) Read the full report:
    Download
    341041.1K45K
  2. Kuldeep Singh Sidhu✓@kuldeep_s_s
    One embedding model for text, code, images, video, and audio - in under 750M parameters. ⠀ Google DeepMind's Gemma team just released EmbeddingGemma 2, an open multimodal embedding model that maps every modality (and interleaved combinations of them) into a single unified vector space. The interesting part is how it's built. ⠀ Under the hood: ⠀ The architecture is modular: a 271M-parameter bidirectional transformer backbone, a 167M vision encoder (a ViT with patch size 16), and a 305M audio encoder based on the Universal Speech Model's conformer design. Because the modality encoders independently convert media into soft tokens before entering the shared backbone, you can load only what you need - 271M for text-only, 439M for vision-language, 577M for audio-language. ⠀ Text is tokenized normally; images are compressed to a configurable budget of 70 to 1120 vision tokens; audio is processed in 40ms chunks yielding 25 soft tokens per second; video is sampled at 1 fps with frames optionally interleaved with audio segments and timestamps. Everything flows through the same bidirectional transformer, gets mean-pooled, projected, and normalized into a 768-dimensional embedding - truncatable to 512, 256, or 128 dims via Matryoshka Representation Learning. ⠀ Training is a three-stage curriculum (~2.9T tokens total): text-only pre-finetuning driven almost entirely by distillation from the much larger Gemini Embedding 2, then multimodal pre-finetuning with pure distillation, then a finetuning stage that drops distillation entirely in favor of contrastive learning plus a spread-out regularizer - letting the model escape its teacher's embedding geometry and learn a space tailored to its own size. The final model merges checkpoints from different points along the same finetuning run. ⠀ Clever simplification: instead of Gemma's dedicated per-layer embedding lookup table, they derive per-layer inputs directly from the shared input embeddings. Fewer parameters, and the ablations show it actually improves quality across modalities. ⠀ Why it matters: it sets a new Pareto frontier across text, code, image, video, document, and audio benchmarks, often beating models 2 to 12x larger - and landing within 2 points of a 28x larger model on code retrieval. Native audio embedding beats an ASR-then-embed pipeline by a wide margin. With quantization-aware training, the full multimodal model runs in ~567 MB on a phone (191 MB text-only). ⠀ Small, open, and genuinely any-to-any. Worth a read for anyone building retrieval or RAG systems.
    Download
    00074
  3. Beautiful Day@abitofsmile
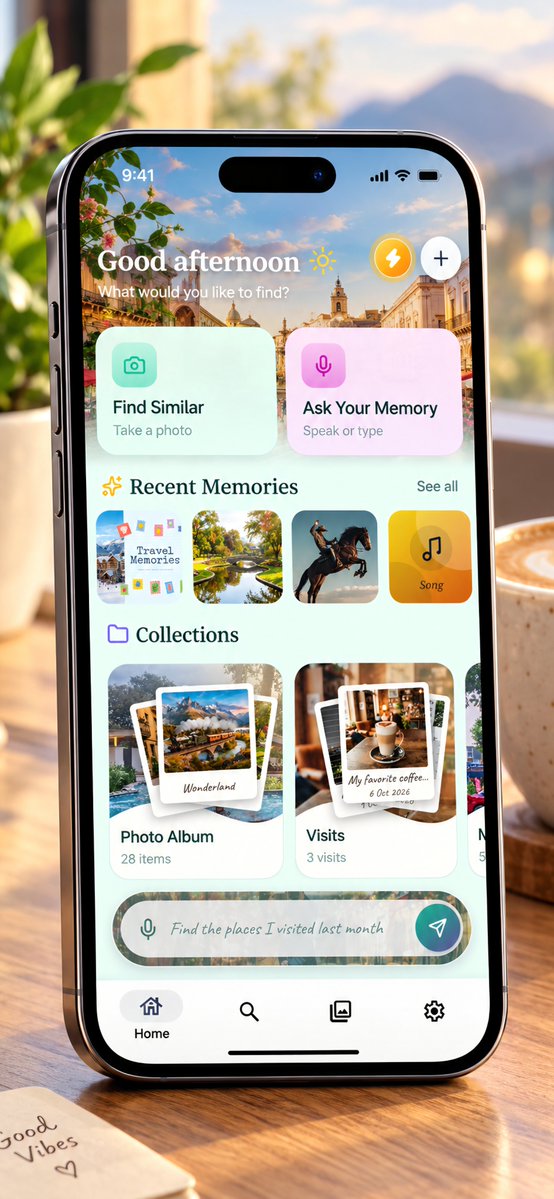
    There are open weights models, perfom amazingly well in specific use case. Magic Memory is such example where we leverage Parakeet for transcription, Paddle for OCR, and Embedding Gemma 2 for blazing fast search Check it out
    Download
    00171
  4. Vivek Galatage✓@vivekgalatage
    Some preliminary experiments with Embedding Gemma 2 on the automotive hardware have been looking quite promising. And with the latest release of the technical report from @GoogleDeepMind, I am excited to read this in detail. Exciting times.
    Download
    03101.2K
  5. TechVerser✓@realfxw
    🚀 突发!Google Gemma 官方正式发布了 EmbeddingGemma 2 技术报告!这绝对是多模态和端侧 AI(On-device AI)领域的一大里程碑式突破!🔥🔥🔥 对于一直在寻找高效、轻量级且全能的嵌入模型(Embedding Model)的开发者来说,这简直是个极具颠覆性的好消息。这次 Google 毫不吝啬地开源分享了他们 740M 多模态嵌入模型的完整架构、训练配方以及消融实验细节。 让我们来看看这篇硬核论文里到底有哪些令人惊叹的亮点: 🌐 真正的多模态统一表示:不再需要为不同类型的数据头疼了!EmbeddingGemma 2 完美支持文本、代码、图像、音频和视频的统一表示。就像评论区开发者说的那样,这意味着你过去 RAG 技术栈里需要同时维护的 5 个不同的嵌入器,现在只需要这 1 个模型就能全部搞定! 📈 越级打怪的强悍性能:虽然它的参数量只有 740M,但它的表现却令人瞠目结舌。官方数据显示,它成功击败了比它大 12 倍的专家模型和通用大模型!真正做到了“小块头有大智慧”。 ⚡ 极致的端侧运行效率(最让人惊艳的一点!):这是整个开发者社区最激动人心的地方!得益于模块化编码器(Modular Encoders)、Matryoshka 维度以及 int4 量化技术,整个模型的体积被惊人地压缩到了仅 567MB!这意味着如此强大的多模态模型完全可以直接部署在你的智能手机或本地 ANE(苹果神经网络引擎)上离线运行。它不仅可以让你根据需要卸载不需要的音频或视频模块,还能最大程度保护用户数据隐私。 无论你是想要优化现有的 RAG 系统,还是希望在移动端构建下一代多模态 AI 应用,EmbeddingGemma 2 都提供了一个几乎完美的开源基座。 如果你也对如何用 567MB 塞下能够处理音视频图文的超强模型感兴趣,强烈建议去阅读完整的技术报告: 大家觉得这个 567MB 的全能模型会如何改变未来的端侧 AI 开发生态?欢迎在评论区分享你的看法!👇 论文地址: #GoogleGemma #AI #多模态 #EmbeddingGemma2 #端侧AI #RAG #机器学习
    43325015.6K
  6. DAIR.AI✓@dair_ai
    82930163K
  7. Pierre Monnin@piermonn
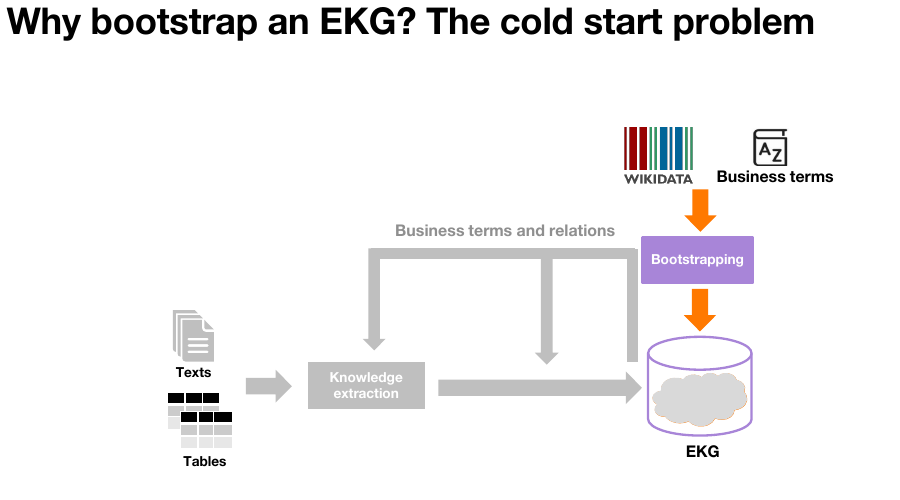
    Great session on @wikidata & #KnowledgeGraphs. Happy to have presented our work with Lucas Jarnac on bootstrapping a KG from Wikidata by selecting subgraphs of interest with node degree and #embedding distance thresholds. #wikiworkshop2023 @wikiworkshop
    Download
    Wiki Workshop 2025 @wikiworkshop
    Time for the third round of parallel sessions at #WikiWorshop2023‼️ Sessions on the @WikiResearch track will focus on: 💫 Governance 💫 Multimedia & images 💫 Readers & Editors 💫 @Wikidata & Knowledge graphs 💫 @Wikipedia within the online ecosystem
    310282.5K
  8. Louis Brulé Naudet@BruleNaudet
    My biggest #release of the year: a series of 7 specialized #embedding models for information retrieval within #tax documents, is now available for #free on @huggingface 🤗 These new models aim to offer an #opensource alternative for in-domain semantic search from large text #corpora and will improve #RAG systems and context addition for large language models. Trained on more than 43 million tax tokens derived from semi-synthetic and raw-synthetic data, enriched by various methods (in particular #MSFT's evol-instruct by @WizardLM_AI), and corrected by humans, this project is the fruit of hundreds of hours of work and is the culmination of a global effort to open up #legal technologies that has only just begun. A big thank you to @microsoftfrance, @OpenAI for giving me access to state-of-the-art models and infrastructure to train these models, and to @julien_c, @ClemDelangue 🤗, @Thom_Wolf and the whole #HF team for the inference endpoint #API and the generous provision of @AIatMeta LLama-3.1-70B. Special thanks also to @tomaarsen for his invaluable advice on training embedding models and Loss functions ❤️ Models are available on my personal HF page as a comment on this post 🎙️ #LLM #AI #GenAI #LegalTech #Legal #NLP #tax
    Download
    4105013K
  9. Accepted papers at TMLR@TmlrPub
    LEA: Learning Latent Embedding Alignment Model for fMRI Decoding and Encoding Xuelin Qian, Yikai Wang, Xinwei Sun, Yanwei Fu, Xiangyang Xue, Jianfeng Feng. Action editor: Bertrand Thirion. #embedding #fmri #generative
    1251.1K
  10. Show more posts