Juan Carlos Niebles

@jcniebles

Multimodal AI, AI Agents, Computer Vision. VP, Research @Samsung @Samsung_RA, Adjunct Professor @Stanford @StanfordSVL.

429 Following5.6K Followers962 Posts
  1. Juan Carlos Niebles@jcniebles
    In case you missed it, here are my slides for my talk today at CONTEXTUS @eccvconf Thanks to the organizer for the invitation and the audience for the engaging questions!
    Download
    Juan Carlos Niebles @jcniebles
    📢I’ll be speaking at the CONTEXTUS workshop @eccvconf 2026 in just a few minutes! 1:20PM 📍Join us at Skybox 504-505 (5th floor, yes) at Malmo Arena. I’ll be taking about our recent work on perception, evidence and efficiency for AI in the physical world. #ECCV2026
    13212.5K
  2. Juan Carlos Niebles@jcniebles
    📢I’ll be speaking at the CONTEXTUS workshop @eccvconf 2026 in just a few minutes! 1:20PM 📍Join us at Skybox 504-505 (5th floor, yes) at Malmo Arena. I’ll be taking about our recent work on perception, evidence and efficiency for AI in the physical world. #ECCV2026
    Download
    14174.1K
  3. Juan Carlos Niebles@jcniebles
    Juan Carlos Niebles
    RT @keshigeyan: Super excited to introduce TRACER! I’ve always been interested in long-form video understanding ( 🙂). At @StanfordSVL, we pushed it to multi-day patient care in the ICU: video + EHR → track activity + behavior → assist clinicians with decision-making. It was great to co-lead this work with @DuranteZane and Dr. Paul Tang!
    Zane Durante @DuranteZane
    1/ Can AI help doctors make more informed decisions based on patient activity and behavior over the course of a hospital stay? Today we introduce TRACER: a training-free multimodal harness that enables LLMs and VLMs to track patient activity using bedside video and health records. Blogpost: Paper:
    04021
  4. Zane Durante✓@DuranteZane
    1/ Can AI help doctors make more informed decisions based on patient activity and behavior over the course of a hospital stay? Today we introduce TRACER: a training-free multimodal harness that enables LLMs and VLMs to track patient activity using bedside video and health records. Blogpost: Paper:
    Download
    103818917.7K
  5. Juan Carlos Niebles@jcniebles
    Juan Carlos Niebles
    RT @keshigeyan: Super excited about this line of work! LILIE is an invertible, lossless image encoder trained with language supervision. Swapping pixel loss for LILIE-space loss improves T2I quality; combining the losses improves it further. GPIC gFD drops by over 13 points 🙂 Great work led by @agarwal_suchir!!
    Suchir Agarwal @agarwal_suchir
    1/8 Introducing LILIE: a Language-Informed and Lossless Image Encoder. We train a language-informed encoder to supervise end-to-end visual generative models. Against a pixel-space JiT model, LILIE improves gFD on GPIC by 14 points (66.84 -> 53.01).
    03019
  6. Juan Carlos Niebles@jcniebles
    Juan Carlos Niebles
    RT @agarwal_suchir: 1/8 Introducing LILIE: a Language-Informed and Lossless Image Encoder. We train a language-informed encoder to supervise end-to-end visual generative models. Against a pixel-space JiT model, LILIE improves gFD on GPIC by 14 points (66.84 -> 53.01).
    027021
  7. Juan Carlos Niebles@jcniebles
    Juan Carlos Niebles
    RT @keshigeyan: Excited to share Halcyon, our latest research on multimodal pretraining! Building strong text-to-image generative models is simpler than we think! Blog: Models: Paper:
    Radical Numerics @RadicalNumerics
    1/8 Does text-to-image generation need language pretraining? Today, we share Halcyon, a family of early-fusion, base models trained from scratch. Halcyon outperforms strong late-fusion baselines with up to 275× less pretraining compute. Models and recipes are open. Halcyon is part of a research program at Radical Numerics on the science of multimodal pretraining and scaling.
    032021
  8. Radical Numerics✓@RadicalNumerics
    1/8 Does text-to-image generation need language pretraining? Today, we share Halcyon, a family of early-fusion, base models trained from scratch. Halcyon outperforms strong late-fusion baselines with up to 275× less pretraining compute. Models and recipes are open. Halcyon is part of a research program at Radical Numerics on the science of multimodal pretraining and scaling.
    Download
    43217976.1K
  9. Juan Carlos Niebles@jcniebles
    Juan Carlos Niebles
    RT @drfeifei: The goal of building any technology, AI included, should be bettering human lives and society.
    Bloomberg TV @BloombergTV
    “Any threat to human society, including existential, is within ourselves,” says World Labs Technologies CEO Fei-Fei Li as she discusses the risks surrounding AI, and the responsibility humans have in shaping how the technology is developed and used. Listen to our full interview here:
    0172010
  10. Bloomberg TV✓@BloombergTV
    “Any threat to human society, including existential, is within ourselves,” says World Labs Technologies CEO Fei-Fei Li as she discusses the risks surrounding AI, and the responsibility humans have in shaping how the technology is developed and used. Listen to our full interview here:
    Download
    841161161K
  11. Juan Carlos Niebles@jcniebles
    Juan Carlos Niebles
    RT @CSProfKGD: I’m speaking next at the #ECCV2026 Workshop on “Universal Representations for Perception, Reasoning, and World Modeling” 🤓
    04021
  12. Juan Carlos Niebles@jcniebles
    I'm hiring! Looking for a Director of Vision Intelligence to join my team at @Samsung_RA 🚀 If you’re passionate about multimodal AI, computer vision, and bringing advanced research directly onto everyday devices, let’s connect! Details & apply:
    04242.3K
  13. Juan Carlos Niebles@jcniebles
    Juan Carlos Niebles
    RT @3scorciav: @CVPR Attendees in Denver 🇺🇸 Do you have a plan for today? Are you onto AI for content creation, GenAI for video & multimedia? @cveu_workshop got you cover while you finish preparing your trip's agenda. June 3 · 8:30 AM – 12:30 PM · Room 501 More =>
    0404.3K
  14. Juan Carlos Niebles@jcniebles
    Processing long videos with VLMs shouldn't scale quadratically. Enter StateKV! 🎬💡 By framing streaming prefill as a fixed-capacity temporal state, we unlock linear-time prefill while keeping full per-frame detail. Paper by @CristbalEyzagu2 and team👇
    Cristóbal Eyzaguirre Ercilla @CristbalEyzagu2
    1/ The biggest problem in video understanding today isn't the models. It's that we can barely run them. Introducing StateKV: an inference-time method that makes pretrained video VLMs scale linearly with video length.🧵 🔗
    05132.8K
  15. Cristóbal Eyzaguirre Ercilla✓@CristbalEyzagu2
    1/ The biggest problem in video understanding today isn't the models. It's that we can barely run them. Introducing StateKV: an inference-time method that makes pretrained video VLMs scale linearly with video length.🧵 🔗
    Download
    4186813.3K
  16. Juan Carlos Niebles@jcniebles
    Juan Carlos Niebles
    RT @zhou_honglu: It's #CVPR week! 🎉 If you're looking to dive deep into the future of intelligent reasoning systems, we've got your 𝗧𝗵𝘂𝗿𝘀𝗱𝗮𝘆 𝗺𝗼𝗿𝗻𝗶𝗻𝗴 plans sorted in #Denver. Join us for the 6th 𝗠𝘂𝗹𝘁𝗶𝗺𝗼𝗱𝗮𝗹 𝗔𝗹𝗴𝗼𝗿𝗶𝘁𝗵𝗺𝗶𝗰 𝗥𝗲𝗮𝘀𝗼𝗻𝗶𝗻𝗴 Workshop! We've put together an incredible lineup of keynotes, talks, and deep-dive discussions exploring the cutting edge of AI reasoning. You won't want to miss this. 📅 When: Thursday, June 4, 2026 | 8:55 AM - 12:30 PM MDT 📍 Where: 𝗥𝗼𝗼𝗺 𝟲𝟬𝟭, Colorado Convention Center, Denver, CO We are incredibly honored to welcome this stellar lineup of keynote speakers: ⏰ 𝟬𝟵:𝟬𝟬 𝗔𝗠 | 🎤 𝗝𝘂𝗮𝗻 𝗖𝗮𝗿𝗹𝗼𝘀 𝗡𝗶𝗲𝗯𝗹𝗲𝘀 @jcniebles 💡 — 𝗦𝗮𝗹𝗲𝘀𝗳𝗼𝗿𝗰𝗲 𝗔𝗜 𝗥𝗲𝘀𝗲𝗮𝗿𝗰𝗵 @SFResearch ⏰ 𝟬𝟵:𝟯𝟬 𝗔𝗠 | 🎤 𝗝𝗶𝗮𝘆𝘂𝗮𝗻 𝗠𝗮𝗼 @maojiayuan 💡 — 𝗨𝗻𝗶𝘃𝗲𝗿𝘀𝗶𝘁𝘆 𝗼𝗳 𝗣𝗲𝗻𝗻𝘀𝘆𝗹𝘃𝗮𝗻𝗶𝗮 @Penn ⏰ 𝟭𝟬:𝟰𝟱 𝗔𝗠 | 🎤 𝗠𝗲𝗹𝗮𝗻𝗶𝗲 𝗠𝗶𝘁𝗰𝗵𝗲𝗹𝗹 @MelMitchell1 💡 — 𝗦𝗮𝗻𝘁𝗮 𝗙𝗲 𝗜𝗻𝘀𝘁𝗶𝘁𝘂𝘁𝗲 @sfiscience ⏰ 𝟭𝟭:𝟭𝟱 𝗔𝗠 | 🎤 𝗝𝗶𝗮𝗹𝗼𝗻𝗴 𝗪𝘂 💡 — 𝗧𝘀𝗶𝗻𝗴𝗵𝘂𝗮 𝗨𝗻𝗶𝘃𝗲𝗿𝘀𝗶𝘁𝘆 @Tsinghua_Uni A huge thank you to our generous sponsors for making this event a reality: 🤝 𝗠𝗶𝘁𝘀𝘂𝗯𝗶𝘀𝗵𝗶 𝗘𝗹𝗲𝗰𝘁𝗿𝗶𝗰 𝗥𝗲𝘀𝗲𝗮𝗿𝗰𝗵 𝗟𝗮𝗯𝗼𝗿𝗮𝘁𝗼𝗿𝗶𝗲𝘀 (𝗠𝗘𝗥𝗟) @merl_news : 🌐 🤝 𝗘𝗹𝗼𝗿𝗶𝗮𝗻 𝗔𝗜 @ElorianAI : 🌐 Massive shoutout to our dedicated organizers: 🔹 𝗔𝗻𝗼𝗼𝗽 𝗖𝗵𝗲𝗿𝗶𝗮𝗻 @anoopcherian — 𝗠𝗘𝗥𝗟 🔹 𝗦𝘂𝗵𝗮𝘀 𝗟𝗼𝗵𝗶𝘁 @Suhas_Lohit — 𝗠𝗘𝗥𝗟 🔹 𝗞𝘂𝗮𝗻-𝗖𝗵𝘂𝗮𝗻 𝗣𝗲𝗻𝗴 @KuanChuanPeng — 𝗠𝗘𝗥𝗟 🔹 𝗛𝗼𝗻𝗴𝗹𝘂 𝗭𝗵𝗼𝘂 @zhou_honglu — 𝗦𝗮𝗹𝗲𝘀𝗳𝗼𝗿𝗰𝗲 𝗔𝗜 𝗥𝗲𝘀𝗲𝗮𝗿𝗰𝗵 🔹 𝗞𝗲𝘃𝗶𝗻 𝗦𝗺𝗶𝘁𝗵 @realkevinsmith — 𝗠𝗜𝗧 @MIT 🔹 𝗝𝗼𝘀𝗵𝘂𝗮 𝗕. 𝗧𝗲𝗻𝗲𝗻𝗯𝗮𝘂𝗺 — 𝗠𝗜𝗧 As AI systems become increasingly capable across vision, language, action, and interaction, reasoning remains one of the field's most exciting open challenges. This workshop brings together researchers and practitioners across academia and industry to discuss the latest advances in multimodal reasoning, foundation models, physical & agentic reasoning, and human–AI comparisons. 👉 𝗚𝗲𝘁 𝘁𝗵𝗲 𝗳𝘂𝗹𝗹 𝘀𝗰𝗵𝗲𝗱𝘂𝗹𝗲 𝗮𝗻𝗱 𝘄𝗼𝗿𝗸𝘀𝗵𝗼𝗽 𝗱𝗲𝘁𝗮𝗶𝗹𝘀 𝗵𝗲𝗿𝗲: 🌐 Will you be joining us on Thursday? Drop a comment or tag a colleague you're attending with! 👇 #CVPR2026 #CVPRWorkshop #AI #MultimodalAI #Reasoning #FoundationModels #MachineLearning #MultimodalReasoning #IntelligentSystems
    0601.4K
  17. Juan Carlos Niebles@jcniebles
    Massive drop for the AI community! 🚀 28 trillion pixels, 100M+ images, and entirely permissively licensed for commercial and research use. A major step forward for open, stable, and scalable generative modeling. Congrats @keshigeyan and team on the launch! 👇
    Keshigeyan Chandrasegaran @keshigeyan
    1/ Introducing GPIC: a Giant Permissive Image Corpus and benchmark for visual generation! 🚀100M VLM-captioned image-text pairs for training 📊1M image-text pairs for benchmarking 🖼️~28 trillion pixels 🤗Centrally Hosted ✅Fully permissive for research + commercial use Dataset, benchmark and models🧵👇 Co-led with @KyleSargentAI
    135965
  18. Keshigeyan Chandrasegaran✓@keshigeyan
    1/ Introducing GPIC: a Giant Permissive Image Corpus and benchmark for visual generation! 🚀100M VLM-captioned image-text pairs for training 📊1M image-text pairs for benchmarking 🖼️~28 trillion pixels 🤗Centrally Hosted ✅Fully permissive for research + commercial use Dataset, benchmark and models🧵👇 Co-led with @KyleSargentAI
    Download
    1684376159K
  19. Juan Carlos Niebles@jcniebles
    Juan Carlos Niebles
    RT @CSProfKGD: #KostasThoughts: While consensus among reviewers is appreciated, it is not strictly necessary. As an Area Chair, what matters most is understanding each reviewer’s reasoning and decision-making process. That is why it is imperative that reviewers provide a clear final summary explaining why they recommend accepting or rejecting the paper, which concerns were addressed through the rebuttal and discussion, and which concerns, if any, remain unresolved. Simply putting “my concerns were not resolved” is not being a responsible reviewer. If you initially misunderstood parts of the paper or made an error in your assessment, that’s okay we all make mistakes. Please put personal ego aside and focus on making the correct decision based on the technical merits of the paper, the rebuttal, and the discussion.
    European Conference on Computer Vision #ECCV2026 @eccvconf
    The #ECCV2026 reviewer discussion period has started! Reviewers should carefully read the authors’ rebuttal, consider the other reviews, and actively participate in the discussion BEFORE finalizing their reviews.
    0403.7K
  20. Juan Carlos Niebles@jcniebles
    For those who couldn't make the talk, I’ve just posted a summary and slides on my blog. 🦾 Check it out here: Work at @SFResearch by @zhou_honglu, @artemispng, @ZiyangW00, Kanchana Ranasinghe and others. #ICLR2026
    Juan Carlos Niebles @jcniebles
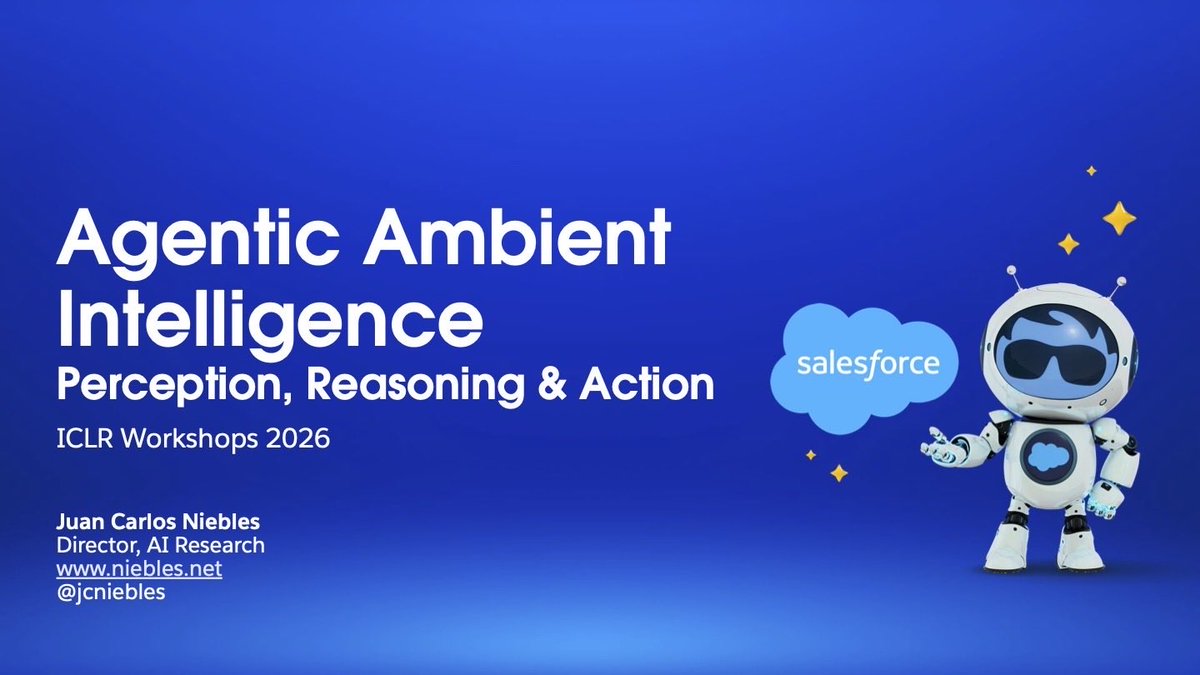
    Heading to the DATA-FM workshop at #ICLR2026? 🦾 Catch my invited talk at 1:30 PM today in Room 203A+B: "Agentic Ambient Intelligence: Perception, Reasoning & Action." I’ll be diving into 4 new research pillars for moving AI into the physical world. Come say hi! 📍
    04111.8K
  21. Juan Carlos Niebles@jcniebles
    Heading to the DATA-FM workshop at #ICLR2026? 🦾 Catch my invited talk at 1:30 PM today in Room 203A+B: "Agentic Ambient Intelligence: Perception, Reasoning & Action." I’ll be diving into 4 new research pillars for moving AI into the physical world. Come say hi! 📍
    Download
    0263K
  22. Juan Carlos Niebles@jcniebles
    Thank you @dimadamen for coming and for the shout out!
    Dima Damen @dimadamen
    Workshops are always more interesting than the main conference! ⁦@iclr_conf⁩ workshop on what’s next in next token predication w talk from ⁦@jcniebles⁩
    004390
  23. Juan Carlos Niebles@jcniebles
    Juan Carlos Niebles
    RT @dimadamen: Workshops are always more interesting than the main conference! ⁦@iclr_conf⁩ workshop on what’s next in next token predication w talk from ⁦@jcniebles⁩
    0302.6K
  24. Juan Carlos Niebles@jcniebles
    Juan Carlos Niebles
    RT @zhou_honglu: Predicting future optical flow turns out to be surprisingly powerful; it boosts both robot control 🤖 and video generation 🎥. 🚀 New Research Alert! 📰 Paper: I'm thrilled to share the release of 𝗙𝗼𝗙𝗣𝗿𝗲𝗱 (paper/code/checkpoint/interactive demo) - our model forecasts optical flow conditioned on language instructions. 👉 𝗧𝗿𝘆 𝗶𝘁 𝘆𝗼𝘂𝗿𝘀𝗲𝗹𝗳 𝘃𝗶𝗮 𝘁𝗵𝗲 𝗱𝗲𝗺𝗼 link on our project website! • Website: • HuggingFace checkpoint: • Demo: • GitHub: In this work, we argue that what has to be provided to the models for many (robot) control and (video) generation tasks is how things should move in the future. This inherently is a challenging task, as it requires: 1⃣ - a clear formulation of what type of ‘future motion’ we will be computing 2⃣ - curating large enough training data with strong supervisory signals 3⃣ - an elegant model capable of fully digesting such (potentially cross-domain) training data while generalizing across domains. We focus on 𝗙𝘂𝘁𝘂𝗿𝗲 𝗢𝗽𝘁𝗶𝗰𝗮𝗹 𝗙𝗹𝗼𝘄 𝗣𝗿𝗲𝗱𝗶𝗰𝘁𝗶𝗼𝗻 - a language-conditioned, spatially dense motion prediction task. We discuss a 𝘀𝘂𝗶𝘁𝗮𝗯𝗹𝗲 𝗺𝗼𝗱𝗲𝗹 𝗮𝗿𝗰𝗵𝗶𝘁𝗲𝗰𝘁𝘂𝗿𝗲 (a unified VLM-diffusion model) and show 𝗵𝗼𝘄 𝘄𝗲 𝗰𝗮𝗻 𝗵𝗶𝗴𝗵𝗹𝘆-𝘀𝗰𝗮𝗹𝗮𝗯𝗹𝗲 𝘁𝗿𝗮𝗶𝗻 our model with videos from various sources (web-scale human activity videos with noisy camera motion + robot action videos in controlled environments). FoFPred adapts to both 𝗹𝗮𝗻𝗴𝘂𝗮𝗴𝗲-𝗱𝗿𝗶𝘃𝗲𝗻 𝗿𝗼𝗯𝗼𝘁𝗶𝗰 𝗺𝗮𝗻𝗶𝗽𝘂𝗹𝗮𝘁𝗶𝗼𝗻 and 𝗹𝗮𝗻𝗴𝘂𝗮𝗴𝗲-𝗴𝘂𝗶𝗱𝗲𝗱 𝗺𝗼𝘁𝗶𝗼𝗻 𝘃𝗶𝗱𝗲𝗼 𝗴𝗲𝗻𝗲𝗿𝗮𝘁𝗶𝗼𝗻 - to the best of our knowledge, the first to support such cross-domain versatility. We hope this work paves the way toward generalizable, 𝗺𝗼𝘁𝗶𝗼𝗻-𝗮𝘄𝗮𝗿𝗲 𝘄𝗼𝗿𝗹𝗱 𝗺𝗼𝗱𝗲𝗹𝘀 that understand and act through dynamic visual grounding. Be sure to check out the project website and read our paper, which covers lots of useful information, including qualitative results, ablations (on human web videos, architecture choices, camera motion separation / motion target disentanglement), and our insights on open challenges and future directions. 👏 Huge shoutout to Kanchana Ranasinghe @kahnchana, our intern at Salesforce AI Research @SFResearch, for the outstanding work on this project and for making an excellent open source! 🫶👍😁 #WorldModels #DiffusionModels #VideoGeneration #Robotics #EmbodiedAI #GenerativeAI
    Salesforce AI Research @SFResearch
    Introducing FOFPred — a language-driven future optical flow prediction framework that enables improved robot control and video generation. Instead of reacting to motion, FOFPred predicts how motion will evolve — conditioned on natural language. 🌐 Project: 📄 Paper: 💻 Code: 🤗 Model: 🕹️ Demo: 🧵[1/3]
    030838
  25. Salesforce AI Research✓@SFResearch
    Introducing FOFPred — a language-driven future optical flow prediction framework that enables improved robot control and video generation. Instead of reacting to motion, FOFPred predicts how motion will evolve — conditioned on natural language. 🌐 Project: 📄 Paper: 💻 Code: 🤗 Model: 🕹️ Demo: 🧵[1/3]
    Download
    14133.1K
  26. Show more posts