
When your team built a community powered GPU network 2.5 years ago before they banned all the GPUs and now they can't control you.
@Sogni_Protocol
21255.5K

@krunkosaurus
Decentralized AI, Local AI, co-founder @Sogni_protocol
Aesther @AestherMLQwen 3.8 27B is actually the most brilliant retarded model that I have ever used. 😅 It spends about 2/4 of its reasoning trace coming up with the most retarded ideas known to man, and then an additional 1/4 convincing itself that its ideas are completely retarded. It then manages, from the ashes of retardation, to arise towards the cleanest, most efficient, and bug-free implementation of any open-weight model of this size. It kinda works like American politics, in a way?!

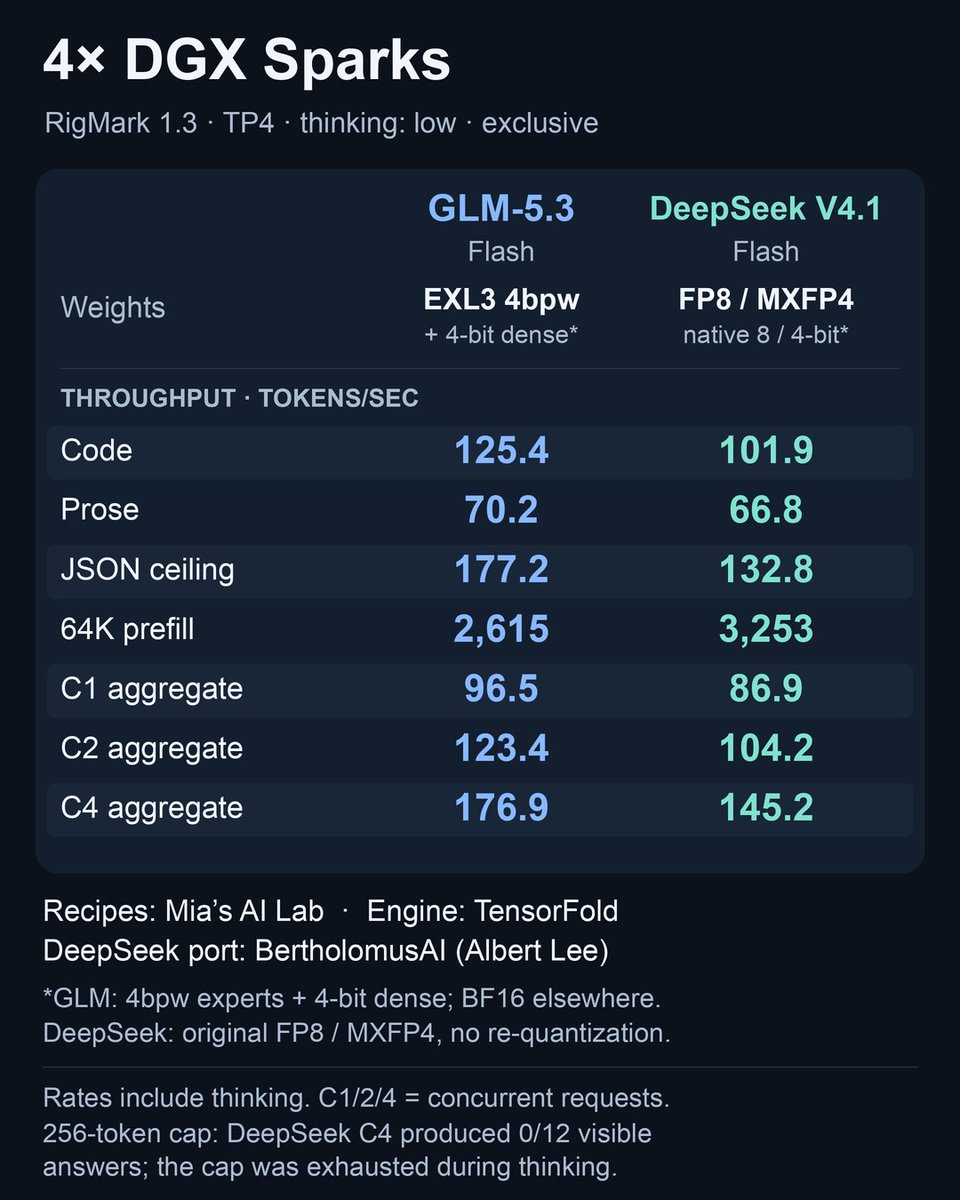
Mia @MiaAI_labI'd take 4x DGX Sparks over M5U 512 GB any day! The system is so mature right now, and works so well, it will take YEARS for the Mac to get this good, if ever. You can't get with one Mac the versatility you have with 4 Sparks. You just can't. I can decide to run 2 models per 2 Sparks, or 1 model on all 4 Sparks, or 1 model on one Spark and another model on 3 Sparks. What about diffusion models? Image and video generation. How will that work if you run image gen on your Mac but also want to use an LLM? The versatility of the DGX Sparks is insane! Also, CUDA.

Codie Sanchez @Codie_SanchezAll employees come in 5 levels, choose wisely: Level 1 - tells you there's a problem Level 2 - tells you there's a problem and what caused it Level 3 - tells you there's a problem, what caused it, and options to fix it Level 4 - tells you there's a problem, what caused it, options to fix it, and which one they'd pick Level 5 - tells you there was a problem, what caused it, how they fixed it, and future proof’d it

Mia @MiaAI_labImportant updates and fixes have been pushed to DeepSeek V4.1 Flash for 4x DGX Sparks ⚡️ This update includes 7 community PRs! Performance - Chats with images: resending a 35-image chat dropped from 20 s to 1 s (20x faster) - No more waiting: a short question asked during a long 51k-token prompt now answers in 0.3 s instead of ~13 s - CPU use per machine dropped from ~310% to ~0.2% (about 12 CPU cores freed) when on idle More reliable - Long prompts no longer time out clients (a keep-alive signal every 15 s) - Safer start/stop scripts - The test tools can’t report a false “pass” anymore Also, /metrics now shows how many prompt tokens came from the cache (prompt_tokens_cached_total), so dashboards can tell cache hits from real prefill work Thanks to @easthambuilds, @krunkosaurus, @uchkw, Manuel (manuel1618), and SvangenStudios, plus upstream TensorFold work by @jayleaton, @ashxhart and @BobClawblaw 🙏 Get it here:


Alex Cheema @alexocheemaThe memory unit economics of Apple Silicon are insane. When you realise LLM inference is massively memory-bound (even at high concurrency!), you find that $ per memory bandwidth ($/GB/s) is the most important metric for inference. M5 Ultra: $5499, 96GB @ 1.2TB/s, $4.5/GB/s DGX Spark: $6950, 128GB @ 273GB/s, $25.5/GB/s DGX Station: ~$150K, 252GB @ 7.1TB/s (HBM3e), $21.1/GB/s M5 Ultra has 5.6x better $/GB/s than DGX Spark and 4.7x better $/GB/s than DGX Station. I am surprised Apple didn't increase their prices more (maybe they will so might be a good time to buy...) I expect 512GB M5 Ultra Mac Studio to start at $15899 (following the usual +$25/GB incremental memory price). That's a crazy good price for that much high speed memory. With RDMA over Thunderbolt 5 you get single digit microsecond latency and you can connect up to 5 Thunderbolt 5 cables between Macs for 400Gb/s network bandwidth (same as ConnectX-7). Thunderbolt 5 cables are ~$25 each. The main problem is the software on Apple Silicon is not great. There are about 30 competing inference engines, each supporting a small set of models, and quite unstable. The ecosystem around MLX is immature and limited (e.g. no Dynamo, LMCache, llm-d, ...). In our experience, more serious customers like Governments and Enterprises are put off by that and want something stable with an ecosystem of tools and software to run inference in production.

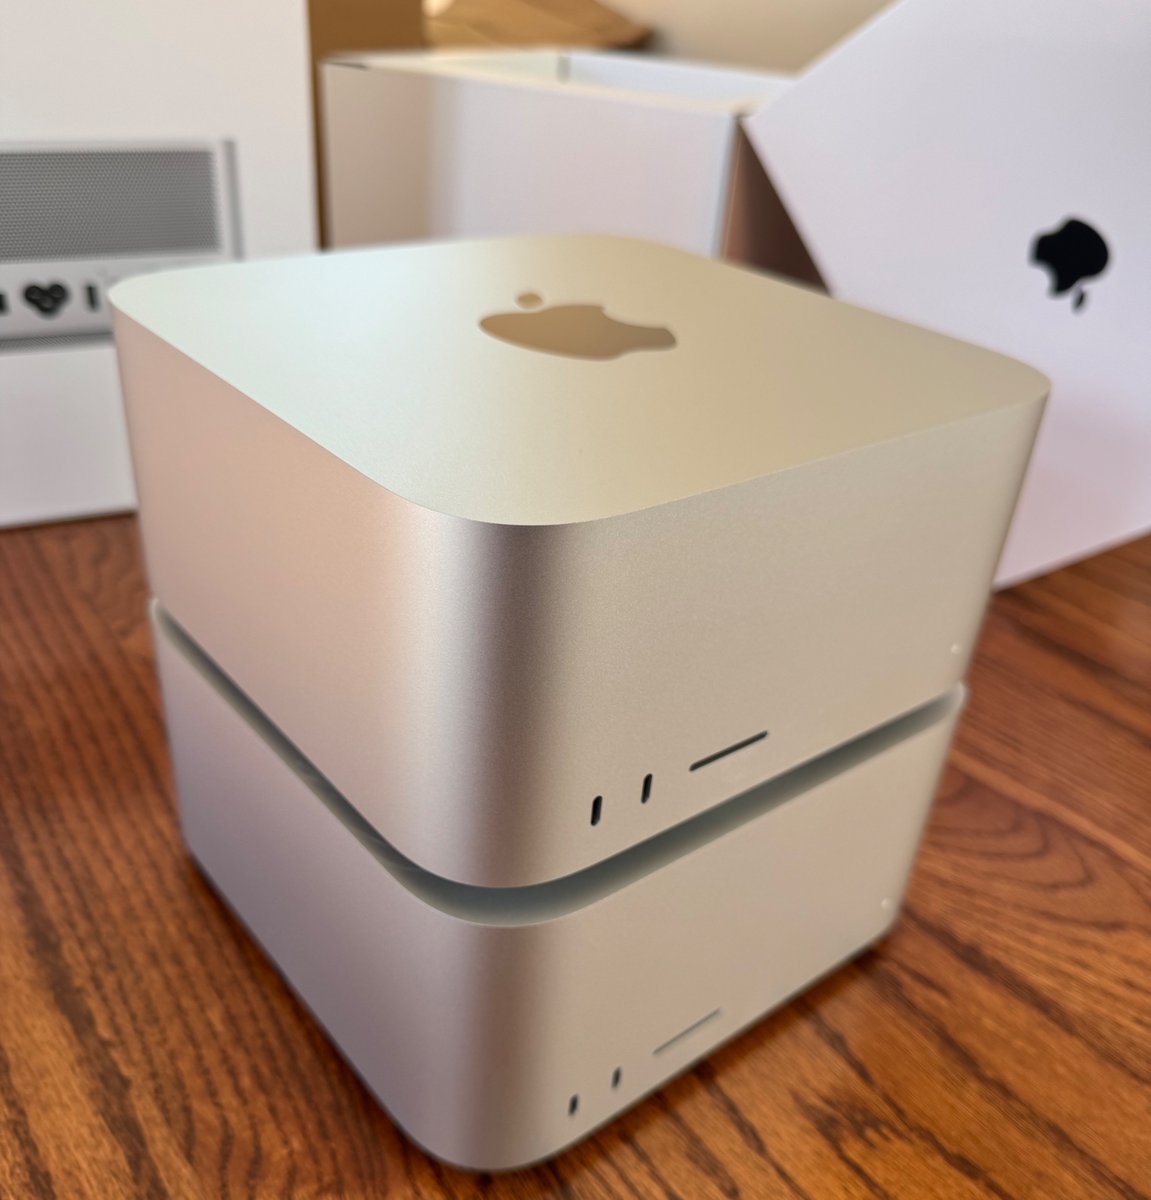
TechMD @TechMDAIIt’s crazy I’m using my 4 DGX sparks more than my 2 RTX pro 6000 currently. What world are we living in.

Mia @MiaAI_labRun DeepSeek V4.1 Flash 1017 with the full official weights on your 4x DGX Sparks, using TensorFold, Abliterated! 🔥 - Full support for switchless TP4 - 1M context, 16M total KV cache - 16 concurrent sessions with 1M each - 15 GB of free mem per Spark after load - OFFICIAL weights, no further quantization! - Needle passed at 100% depth - ABLIT is off by default. Gated. Performance tested on a switchless TP4. It should be faster with a switch. Decode speeds, non-greedy, thinking on: - 66 tok/s on prose, single stream - 96 tok/s on prose, 2 concurrent streams - 173 tok/s on prose, 16 concurrent streams Decode speeds, greedy, thinking off: - 85 tok/s on prose, single stream - 113 tok/s on prose, 2 concurrent streams - 210 tok/s on prose, 16 concurrent streams Decode speeds per stream in deep context (128k), non-greedy, thinking on: - 58.6 tok/s on prose, single stream - 83 tok/s on prose, 2 concurrent streams - 132 tok/s on prose, 8 concurrent streams Prefill: 4000+ tok/s up to 256k. This is the best model to run if you have 4x DGX Sparks, bar none! It works so well on the Sparks that it's unbelievable. Get it here:

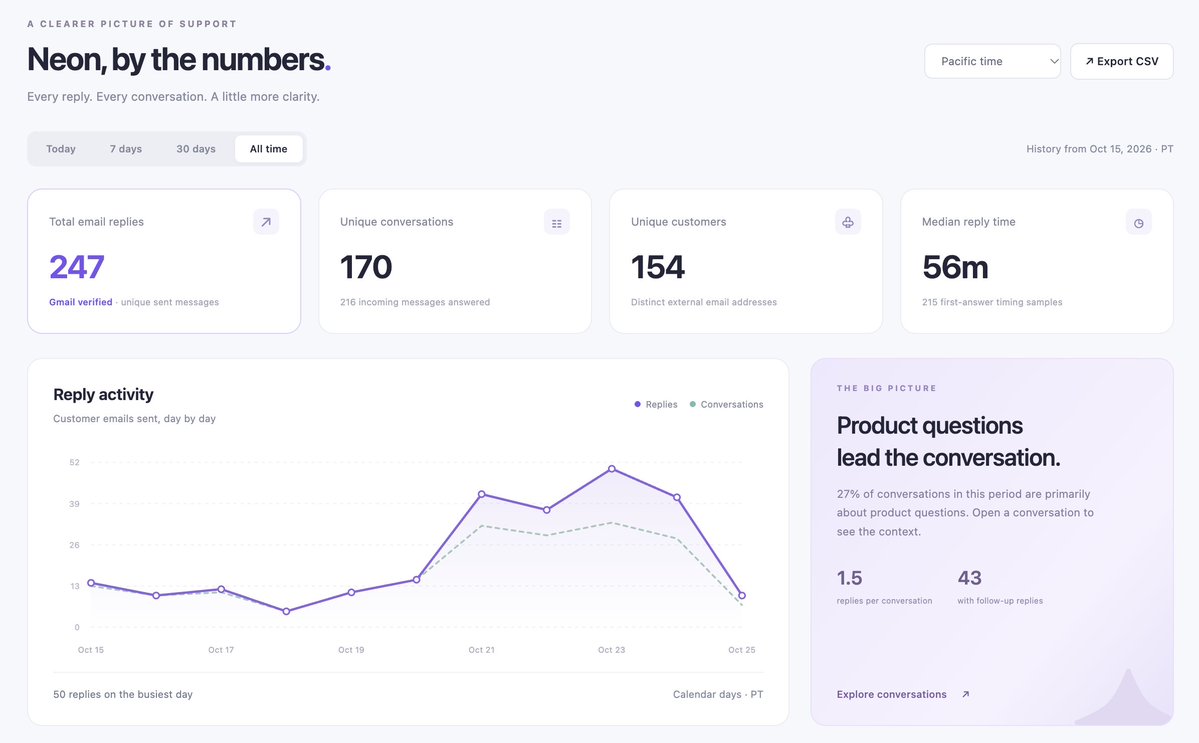
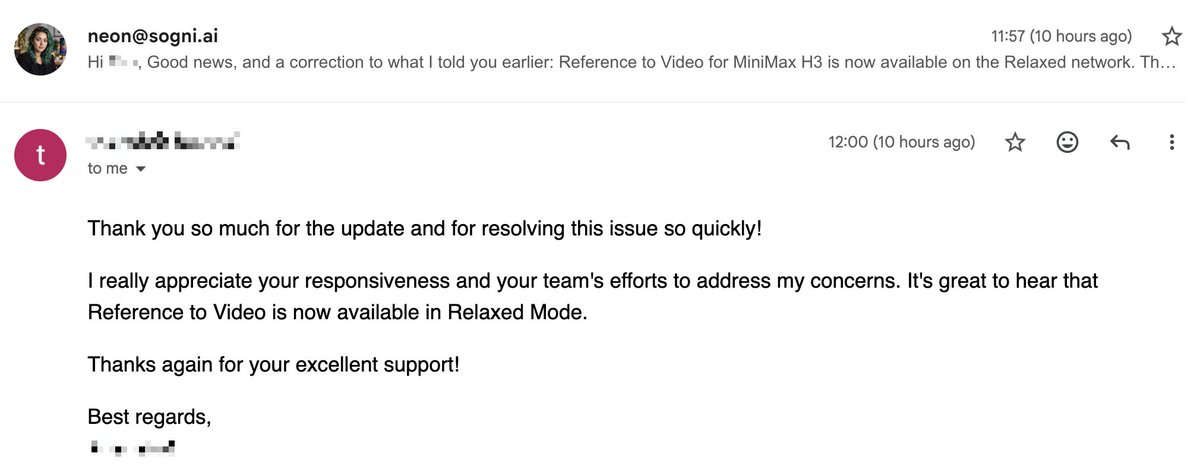
Mau “Rules without Rulers” Ledford @krunkosaurusWhat would you automate first with your own local agents?


