Sujee Maniyam✓

@sujee_dev

Building and explaining AI with open models, coding agents & visual demos. Open source builder. AI Developer Advocate @NebiusAI

587 Following316 Followers337 Posts
  1. Sujee Maniyam✓@sujee_dev
    Thanks for the shoutout @ChrisPirillo 😊
    Chris Pirillo @ChrisPirillo
    Vibe Coding & AI News to Use: October 27, 2026… A visual explainer traces an LLM API request to the GPU and back. @sujee_dev Better Backlog filters GitHub issues with decision models. @AnthropicAI shares early progress on drug development with Claude. OpenAI's Codex CLI reaches rust-v0.165.0. Gemini CLI v0.67.0-preview.0 rolls out a new preview build. @googleaidevs @hexanalytics raises $100M. CleanCode puts Claude Code and Codex on one shared canvas. Agent Skills collects 51 SKILL.md workflows for coding agents. OpenBot 0.52.1 refreshes a desktop workspace for persistent AI teammates. @discord will soon surface public server messages through Google. Wenlan is an LLM wiki that flags what it can't back up. Ghostty 1.4 is out. Genie 4 opens a new generation of DeepMind world simulation. OpenHands 1.34.0 updates the open-source coding agent. @jetbrains ThinkRail ships a new v0.3.0 nightly of its vibe-coding IDE. Wikipedia's cleanup project tackles AI-generated writing. @ieeespectrum Cindy v0.1.118-beta iterates on an out-of-the-box open-source agent. PulseDev: click a UI bug on localhost and your agent fixes it. Revix AI reviews code against your repo's own rules. @userevix Try this image style: Take the attached photo and redraw it as Needle-felted wool diorama: eyes two round buttons of dense black wool framed by stitched ring rims, nose a softly pinched wool wedge, mouth one strand of roving couched in a closed gentle smile, hair a close cap of felted charcoal fibres with a soft halo of loose fleece, and hands and body shaped from firmly needled oat-coloured wool that keeps its visible felting-needle pockmarks. Palette: oat fleece, madder red, slate blue, charcoal wool. Waist-up three-quarter view of Chris at a wide shared table, needle-felting the last seam of a small madder-red helper robot while its slate-blue felt mate reaches across a single stretched canvas lying flat between them, loose wisps of raw fleece and a barbed needle resting at the table edge, warm side light raking the fuzzy wool halo. Keep the person recognizable. Square, no text. Meet Seattle-area builders at Builder Day and Builder Night. See the calendar for upcoming events.
    002159
  2. Chris Pirillo✓@ChrisPirillo
    Vibe Coding & AI News to Use: October 27, 2026… A visual explainer traces an LLM API request to the GPU and back. @sujee_dev Better Backlog filters GitHub issues with decision models. @AnthropicAI shares early progress on drug development with Claude. OpenAI's Codex CLI reaches rust-v0.165.0. Gemini CLI v0.67.0-preview.0 rolls out a new preview build. @googleaidevs @hexanalytics raises $100M. CleanCode puts Claude Code and Codex on one shared canvas. Agent Skills collects 51 SKILL.md workflows for coding agents. OpenBot 0.52.1 refreshes a desktop workspace for persistent AI teammates. @discord will soon surface public server messages through Google. Wenlan is an LLM wiki that flags what it can't back up. Ghostty 1.4 is out. Genie 4 opens a new generation of DeepMind world simulation. OpenHands 1.34.0 updates the open-source coding agent. @jetbrains ThinkRail ships a new v0.3.0 nightly of its vibe-coding IDE. Wikipedia's cleanup project tackles AI-generated writing. @ieeespectrum Cindy v0.1.118-beta iterates on an out-of-the-box open-source agent. PulseDev: click a UI bug on localhost and your agent fixes it. Revix AI reviews code against your repo's own rules. @userevix Try this image style: Take the attached photo and redraw it as Needle-felted wool diorama: eyes two round buttons of dense black wool framed by stitched ring rims, nose a softly pinched wool wedge, mouth one strand of roving couched in a closed gentle smile, hair a close cap of felted charcoal fibres with a soft halo of loose fleece, and hands and body shaped from firmly needled oat-coloured wool that keeps its visible felting-needle pockmarks. Palette: oat fleece, madder red, slate blue, charcoal wool. Waist-up three-quarter view of Chris at a wide shared table, needle-felting the last seam of a small madder-red helper robot while its slate-blue felt mate reaches across a single stretched canvas lying flat between them, loose wisps of raw fleece and a barbed needle resting at the table edge, warm side light raking the fuzzy wool halo. Keep the person recognizable. Square, no text. Meet Seattle-area builders at Builder Day and Builder Night. See the calendar for upcoming events.
    Download
    707845
  3. Sujee Maniyam✓@sujee_dev
    Want to try @Kimi_Moonshot K3.1 Pro? Here are a few ways to access it: 1 - OpenCode Go Starts at $10/month. An affordable way to get started. 2- Kimi CLI + Kimi API $2/M input tokens, $10/M output, $0.20/M cached input 3 - OpenRouter Same API pricing. 4 - Find other providers Compare options on I've tried both Kimi CLI + Kimi API and OpenCode + OpenCode Go. My experience so far: - Kimi CLI has been the most reliable for me. - OpenCode Go is a budget-friendly way to get started, but it's been a little laggy, and you could hit usage limits during intensive coding tasks. How are you using K3.1 Pro? What's your experience been like? (Note: K3.1 Pro weights aren't public yet. @Kimi_Moonshot says they'll be released by Nov 4, 2026.)
    002148
  4. Sujee Maniyam✓@sujee_dev
    What actually happens when you call an LLM API? 🤔 I've been working on this visual explainer for a while, and I'm excited to finally share it! 🎬 Follow a single request from client → gateway → tokenizer → router → queue → GPU (prefill + decode) → streamed response. Along the way, explore optimizations like: KV caching / Prompt caching Cache-aware routing Continuous batching Disaggregated prefill/decode Speculative decoding I recently gave a talk on this at Hacktoberfest 2026, but here's the entire journey in just 5 minutes! Watch it and let me know what you think! 👇 Full talk and repo in the reply.
    Download
    2371.3K
  5. Sujee Maniyam✓@sujee_dev
    Posts @sujee_dev
    🛠️ Behind the scenes: This video is part of my Visual Stories series, where I use AI-assisted animation and storytelling to make complex technical concepts easier to understand. The project lives on GitHub, along with the source code and production details. Check it out & remix & share:
    10052
  6. Sujee Maniyam✓@sujee_dev
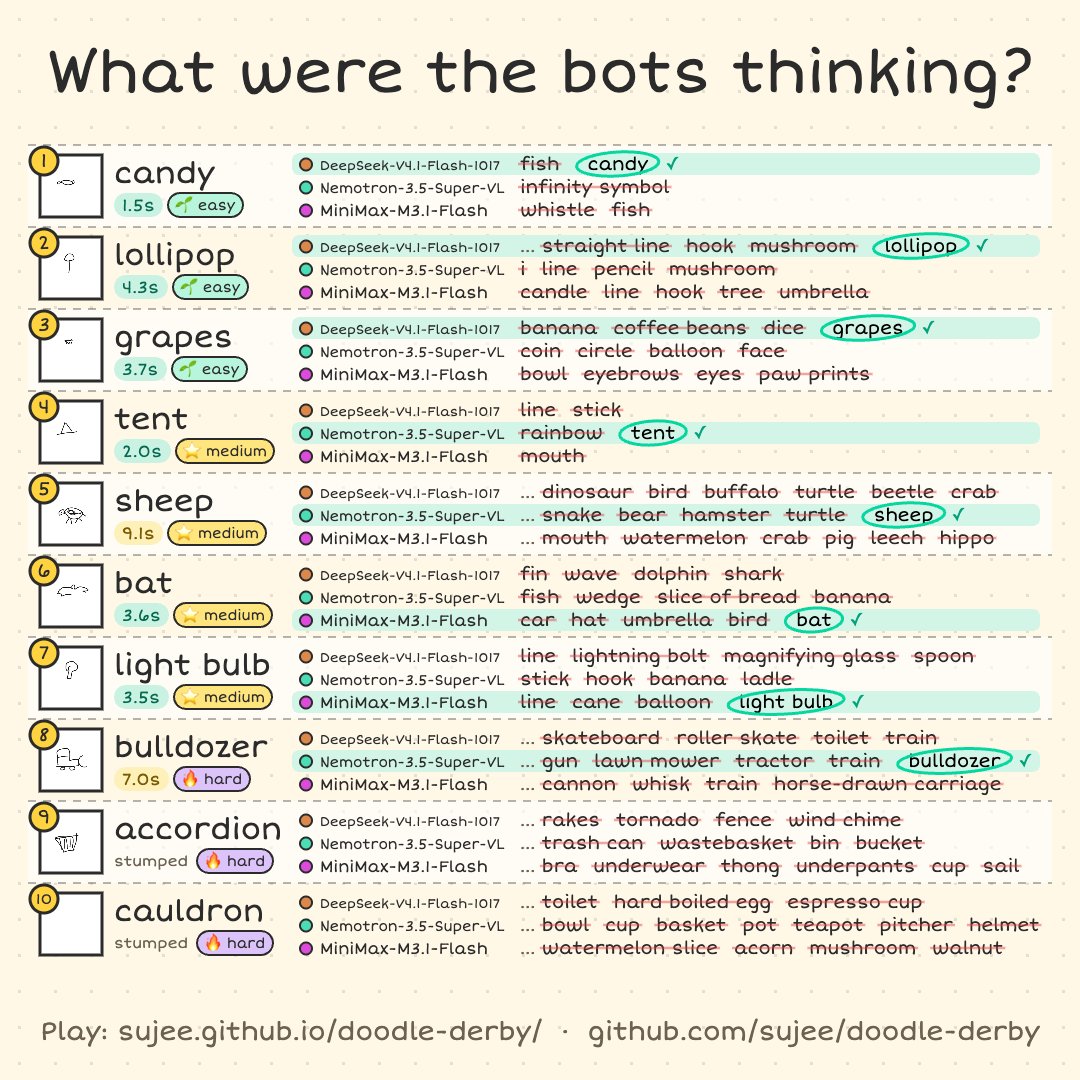
    Friday fun! 🎨🤖 I built Doodle Derby - where 3 vision models compete to recognize doodles as they're being drawn in real time! @MiniMax_AI M3.1-Flash @deepseek_ai V4.1-Flash-1017 @NVIDIAAI Nemotron-3.5-Super-VL All running on @nebiustf 🚀 Who won? And what were the models thinking? 👀 Watch 👇 (Inspired by Google's Quick, Draw!)
    Download
    205335
  7. Sujee Maniyam✓@sujee_dev
    Posts @sujee_dev
    @MiniMax_AI @deepseek_ai @NVIDIAAI @nebiustf 🎨 Your turn! BYOK (Bring Your Own Key) and play Doodle Derby: 🔑 Keyless version coming soon! 💻 Source: Give it a try! Feedback and suggestions welcome! 🙌
    00030
  8. Sujee Maniyam✓@sujee_dev
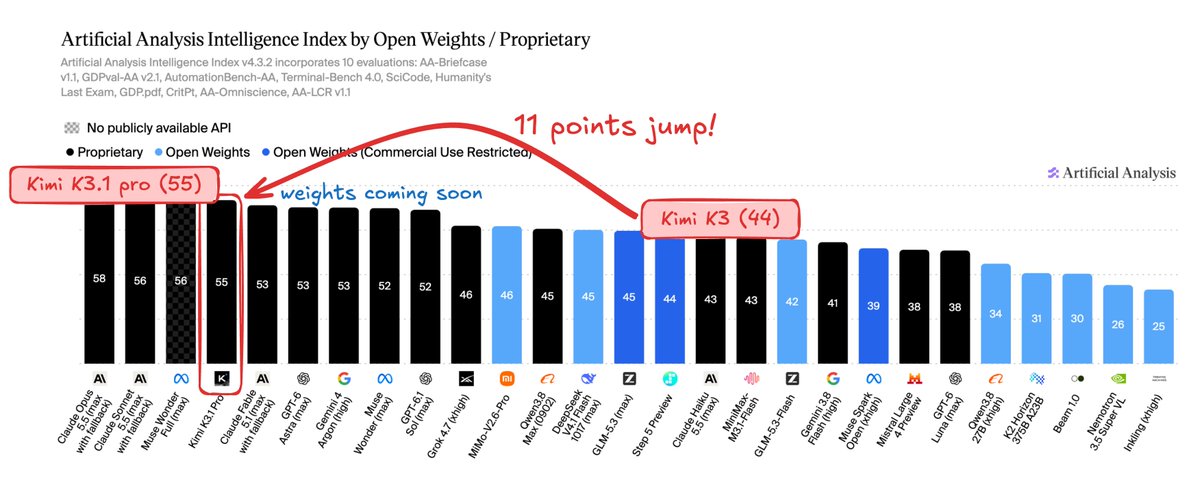
    🚀 @Kimi_Moonshot 's progress in just 3 months is impressive! Kimi K3 (July): AA Intelligence Index 44 Kimi K3.1 Pro (Oct): AA Intelligence Index 55 That's an 11-point jump! 📈 Even more interesting: both have the same 2.8T total / 104B active parameters. More intelligence, without a bigger model 👏
    Download
    Kimi.ai @Kimi_Moonshot
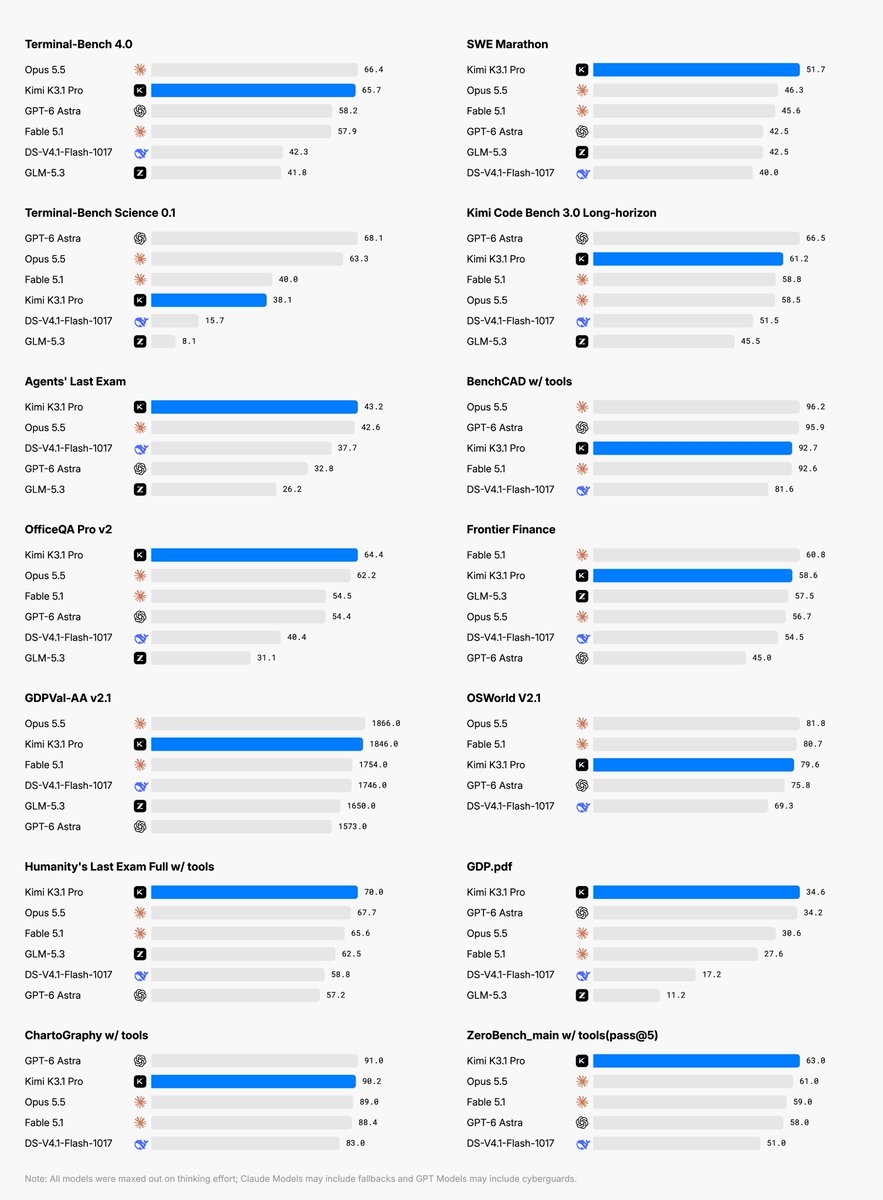
    Introducing Kimi K3.1 Pro: our most capable 3T-class open-weight model. 🔹 1M-token context, 2.8T total / 104B active params (MoE), Multimodal. 🔹 Full-project coding: games in Unreal, Unity & Godot. 🔹 Excels at parametric 3D modeling in Blender & CAD. 🔹 More reliable at finance work: Accurate modeling with hallucination down by 65%. 🔹 Matching the strongest proprietary models across coding, agentic and knowledge benchmarks. Kimi K3.1 Pro and K3.1 Pro Highspeed (2–3× faster) are now live on Kimi Work, Kimi Code, and the Kimi API. Open weights by Nov 4, 2026. 🔗 API: 🔗 Tech blog:
    001101
  9. Kimi.ai@Kimi_Moonshot
    Introducing Kimi K3.1 Pro: our most capable 3T-class open-weight model. 🔹 1M-token context, 2.8T total / 104B active params (MoE), Multimodal. 🔹 Full-project coding: games in Unreal, Unity & Godot. 🔹 Excels at parametric 3D modeling in Blender & CAD. 🔹 More reliable at finance work: Accurate modeling with hallucination down by 65%. 🔹 Matching the strongest proprietary models across coding, agentic and knowledge benchmarks. Kimi K3.1 Pro and K3.1 Pro Highspeed (2–3× faster) are now live on Kimi Work, Kimi Code, and the Kimi API. Open weights by Nov 4, 2026. 🔗 API: 🔗 Tech blog:
    Download
    1.3K3.2K30.2K4.1M
  10. Sujee Maniyam✓@sujee_dev
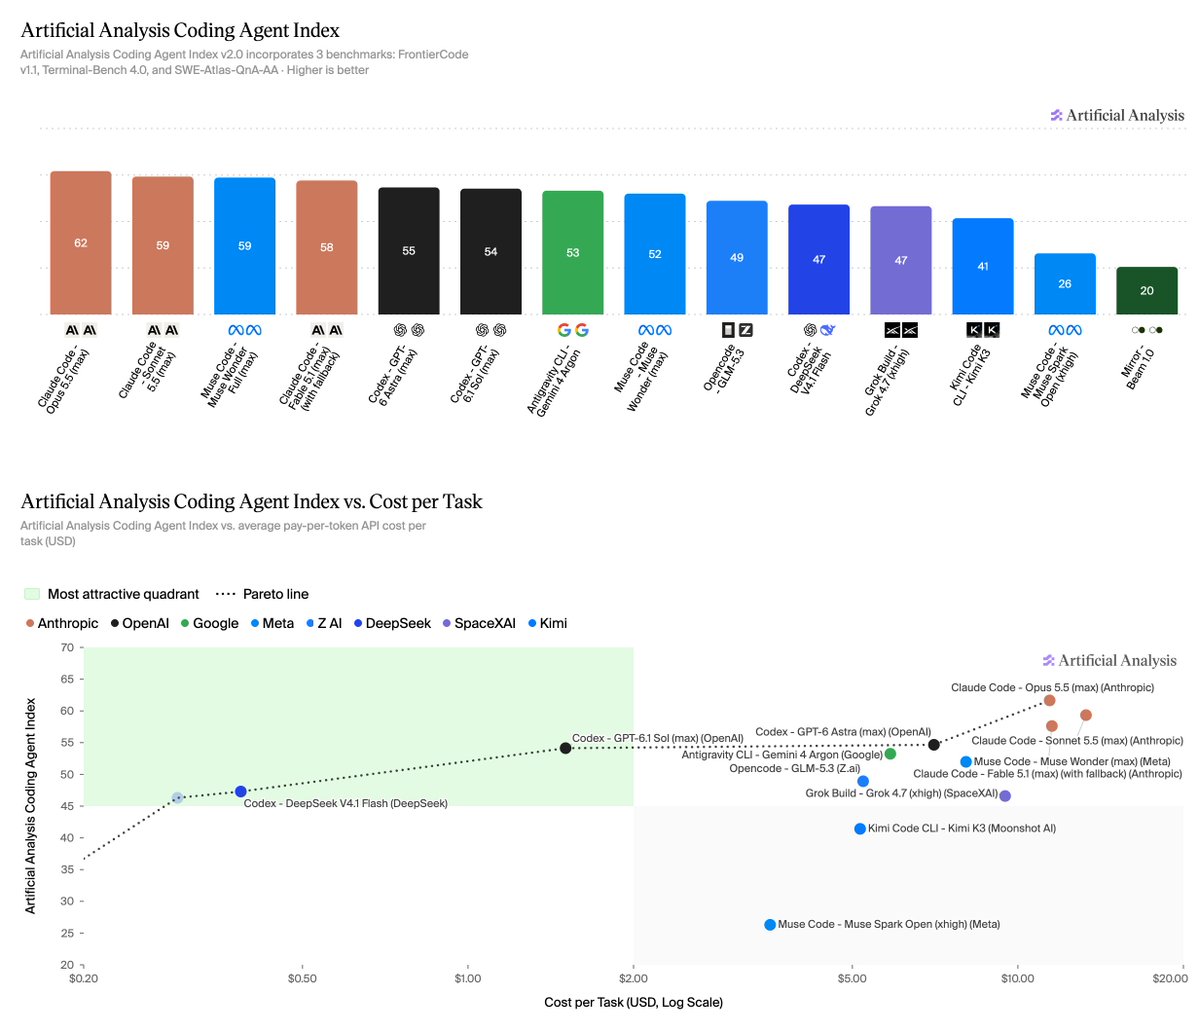
    A few interesting takeaways from this @ArtificialAnlys coding benchmark 👇 1 - Coding performance isn't just about the model. The coding harness matters too. That's why comparing harness + model combinations makes sense. 2 - Impressive to see Muse Code + Muse Wonder climb the rankings so quickly! 3 - My current open-model coding workhorse: @opencode paired with GLM 5.3 or DeepSeek 4.1 Flash. I explored this in my talk, "Coding with Open Models":
    Artificial Analysis @ArtificialAnlys
    Announcing Artificial Analysis Coding Agent Index v2.0: FrontierCode v1.1 from Cognition replaces DeepSWE, SWE-Atlas-QnA grading is revised, and Claude Opus 5.5 in Claude Code leads at 61.7 Today we are launching v2.0 of the Coding Agent Index. The Index evaluates models together with their agent harnesses, now across 290 tasks covering software engineering, terminal use, and repository Q&A, with the three benchmarks weighted equally. Changelog (Index v1.5 → Index v2.0): → FrontierCode v1.1 replaces DeepSWE v1.1. FrontierCode is a benchmark from @cognition with a private test set: 100 software engineering tasks on real open-source repositories, graded on whether a maintainer would merge the change. An attempt that fails a blocking check scores zero, and one that passes them all scores between 70% and 100% depending on the non-blocking checks it meets. We also scan each trajectory with a modified version of Cognition's rule-based scanner, and any attempt flagged for accessing solution material scores zero. → Revised SWE-Atlas-QnA grading, now SWE-Atlas-QnA-AA. Scale AI's 124 repository Q&A tasks are unchanged. We reworded 127 of the 1,306 rubric criteria for more consistent verdicts and moved to GPT-6 Luna (xhigh) as the judge, with five votes per criterion. The dataset and judge configuration are published on Hugging Face. Key results: ➤ Claude Opus 5.5 leads the Index: Claude Code with Claude Opus 5.5 (max) scores 61.7, followed by Claude Code with Claude Sonnet 5.5 (max) at 59.3, Muse Code with Muse Wonder Full (max) at 58.9 and Claude Code with Claude Fable 5.1 (max with fallback) at 57.6. ➤ FrontierCode v1.1 is where Opus 5.5 pulls ahead: Opus 5.5 scores 56.0% on FrontierCode, ahead of Codex with DeepSeek V4.1 Flash (max) at 52.6%, Codex with GPT-6.1 Sol (max) at 49.4% and Codex with GPT-6 Astra (max) at 49.3%. Below the top, FrontierCode scores are tightly packed: 15 of the 24 configurations on the Index score between 43% and 49%. ➤ SWE-Atlas-QnA-AA grading is stricter and more consistent: across the 21 configurations evaluated on both Index versions, the mean score falls 1.7 points, from 58.8% to 57.1%, with 14 of 21 moving down. Individual configurations move by up to 7 points: Muse Code with Muse Spark Open (xhigh) falls 7.0, Kimi K3 in Kimi Code CLI and Codex with GPT-6 Luna (max) 6.2, and Muse Code with Muse Wonder (max) 5.6, while Codex with GPT-6.1 Sol (max) gains 2.1. ➤ Four configurations sit on the cost frontier: Codex with DeepSeek V4.1 Flash (max) scores 47.3 at $0.39 per task, Codex with GPT-6.1 Sol (max) 54.1 at $1.50, Codex with GPT-6 Astra (max) 54.7 at $7.04 and Claude Code with Claude Opus 5.5 (max) 61.7 at $11.42. Costs are pay-per-token API costs, not subscription prices. We will keep updating the Coding Agent Index incrementally, with more evaluations and agents to come.
    005230
  11. Artificial Analysis✓@ArtificialAnlys
    Announcing Artificial Analysis Coding Agent Index v2.0: FrontierCode v1.1 from Cognition replaces DeepSWE, SWE-Atlas-QnA grading is revised, and Claude Opus 5.5 in Claude Code leads at 61.7 Today we are launching v2.0 of the Coding Agent Index. The Index evaluates models together with their agent harnesses, now across 290 tasks covering software engineering, terminal use, and repository Q&A, with the three benchmarks weighted equally. Changelog (Index v1.5 → Index v2.0): → FrontierCode v1.1 replaces DeepSWE v1.1. FrontierCode is a benchmark from @cognition with a private test set: 100 software engineering tasks on real open-source repositories, graded on whether a maintainer would merge the change. An attempt that fails a blocking check scores zero, and one that passes them all scores between 70% and 100% depending on the non-blocking checks it meets. We also scan each trajectory with a modified version of Cognition's rule-based scanner, and any attempt flagged for accessing solution material scores zero. → Revised SWE-Atlas-QnA grading, now SWE-Atlas-QnA-AA. Scale AI's 124 repository Q&A tasks are unchanged. We reworded 127 of the 1,306 rubric criteria for more consistent verdicts and moved to GPT-6 Luna (xhigh) as the judge, with five votes per criterion. The dataset and judge configuration are published on Hugging Face. Key results: ➤ Claude Opus 5.5 leads the Index: Claude Code with Claude Opus 5.5 (max) scores 61.7, followed by Claude Code with Claude Sonnet 5.5 (max) at 59.3, Muse Code with Muse Wonder Full (max) at 58.9 and Claude Code with Claude Fable 5.1 (max with fallback) at 57.6. ➤ FrontierCode v1.1 is where Opus 5.5 pulls ahead: Opus 5.5 scores 56.0% on FrontierCode, ahead of Codex with DeepSeek V4.1 Flash (max) at 52.6%, Codex with GPT-6.1 Sol (max) at 49.4% and Codex with GPT-6 Astra (max) at 49.3%. Below the top, FrontierCode scores are tightly packed: 15 of the 24 configurations on the Index score between 43% and 49%. ➤ SWE-Atlas-QnA-AA grading is stricter and more consistent: across the 21 configurations evaluated on both Index versions, the mean score falls 1.7 points, from 58.8% to 57.1%, with 14 of 21 moving down. Individual configurations move by up to 7 points: Muse Code with Muse Spark Open (xhigh) falls 7.0, Kimi K3 in Kimi Code CLI and Codex with GPT-6 Luna (max) 6.2, and Muse Code with Muse Wonder (max) 5.6, while Codex with GPT-6.1 Sol (max) gains 2.1. ➤ Four configurations sit on the cost frontier: Codex with DeepSeek V4.1 Flash (max) scores 47.3 at $0.39 per task, Codex with GPT-6.1 Sol (max) 54.1 at $1.50, Codex with GPT-6 Astra (max) 54.7 at $7.04 and Claude Code with Claude Opus 5.5 (max) 61.7 at $11.42. Costs are pay-per-token API costs, not subscription prices. We will keep updating the Coding Agent Index incrementally, with more evaluations and agents to come.
    Download
    21357882177K
  12. Sujee Maniyam✓@sujee_dev
    going live in 90 mins (10 am PT / 1pm ET / 7pm CET) and See you there!
    Sujee Maniyam @sujee_dev
    What actually happens when you send a request to an LLM? Gateway → tokenizer → router → queue → prefill → decode → streamed back to you, one token at a time. I'm tracing the whole trip tomorrow at Hacktoberfest 2026. ⚡ Thu, Oct 22 online @ 10am PT / 1pm ET link below 👇
    314195
  13. Sujee Maniyam✓@sujee_dev
    What actually happens when you send a request to an LLM? Gateway → tokenizer → router → queue → prefill → decode → streamed back to you, one token at a time. I'm tracing the whole trip tomorrow at Hacktoberfest 2026. ⚡ Thu, Oct 22 online @ 10am PT / 1pm ET link below 👇
    Download
    31124.1K
  14. Sujee Maniyam✓@sujee_dev
    Posts @sujee_dev
    What Happens When You Call a Model API" 👉 More Hacktoberfest talks:
    00081
  15. Sujee Maniyam✓@sujee_dev
    Friday fun 🎉 The Nemotron family (Super, Lightning, Ultra) went to the carnival… and raced horses 🎪🏇 One of them is a total sprinter. Guess who? 👀 Link below 👇
    Download
    519184
  16. Sujee Maniyam✓@sujee_dev
    Posts @sujee_dev
    Race your own models 👉
    00140
  17. Sujee Maniyam✓@sujee_dev
    taking muse-wonder, gpt-astra and claude-opus for a (horse) ride :-) it was a close race - latency was a big decider see below 👇 (just a fun test, not a benchmark)
    Download
    102129
  18. Sujee Maniyam✓@sujee_dev
    Posts @sujee_dev
    play
    00152
  19. Show more posts