Doubleword

@Doubleword_

Let there be tokens. Open-weight inference for token-hungry workloads: long-running agents, evals and batch at a fraction of the cost. https://t.co/XNFOeea250

32 Following961 Followers167 Posts
  1. Doubleword@Doubleword_
    Your token bill is too high. Models are getting better, agents are getting more ambitious, but the bill keeps getting worse. We don't think developers should have to ration intelligence. One customer cut their bill 4x on the same model and workload. Let there be tokens.
    14582.3M
  2. Doubleword@Doubleword_
    Doubleword
    RT @MeryemArik9: We onboarded a new customer yesterday, they’re in the defensive cyber space, overnight they found 5X more vulnerabilities than they normally do in a typical day. This was because with their other inference provider 50% of their runs were failing because of rate limits - now none of them do. Let there be tokens 🕊️🎲
    0102
  3. Doubleword@Doubleword_
    🎙️ Where will the next wave of value creation in AI inference come from? @MeryemArik9 recently joined @mikebutcher at @WorldSummitAI to discuss how the focus is shifting from simply accessing the most capable models to running them efficiently, reliably and at scale. 🎥 Watch the full discussion here:
    013443
  4. Doubleword@Doubleword_
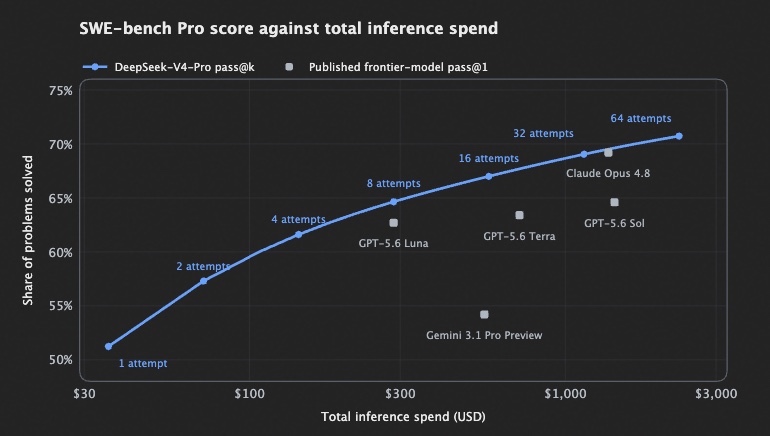
    🚀 Another day, another model on Doubleword. @deepseek_ai's V4.1 Flash 1017 is now available, built for coding, complex reasoning and long-running agentic workflows. ⚡ Model highlights: - 1M+ token context window - Multimodal support for text and image inputs - Optimised for coding, reasoning and long-context analysis Available via our Anthropic & OpenAI-compatible API across Realtime, Async and Batch inference. Start building →
    Download
    0212719
  5. Doubleword@Doubleword_
    🚀 Meta’s Muse Spark Open is now available on Doubleword. Meta's latest 816B parameter open-weight model built for coding, complex reasoning and long-running agentic workflows. ⚡ Model highlights: 816B total / 42B active parameters 1M+ token context window Optimised for coding, reasoning and tool use Available via our OpenAI-compatible API Available across Realtime, Async and Batch inference. Running Muse Spark Open at scale? We also offer dedicated deployments with guaranteed capacity, optimised latency and throughput, and pricing tailored to your workload. Start building →
    Download
    024164
  6. Doubleword@Doubleword_
    SecretSauce Labs runs sentiment and intent analysis for just 3 cents per 100 sessions with Doubleword. What started as a prototype that was too expensive to run in production now analyses user conversations at scale, helping the team understand what users want from its AI content platform. They’ve also increased analysis frequency from once a week to every 3–6 hours and added a second workload curating useful lessons from PR conversations into agent memory. Thanks to @cocolitron and the @trysecretsauce team for sharing how they’re building with Doubleword. Read the full case study 📷
    10197
  7. Doubleword@Doubleword_
    Doubleword
    RT @BrettHarrison: The Liquid Inference router network is growing quickly. We now have 28 verified companies serving >1000 models, offering capacity dynamically and updating quotes in real-time. Average time for providers to onboard and integrate models is 3 hours, full verification within a day.
    02901
  8. Doubleword@Doubleword_
    Doubleword
    RT @jaedmunt: Run open models with @FactoryAI's Droid harness and tackle your most ambitious work reliably and for less, with models like Kimi K3, GLM-5.3, and DeepSeek V4.1 Flash served on @Doubleword_ . Add us as a provider in the settings once, and the models will appear in your model picker. From there, delegate entire software builds to a 'droid army' of agents who autonomously search repositories, edit files, and run tests end-to-end. Full setup guide 👉
    0101
  9. Doubleword@Doubleword_
    On Friday, @MeryemArik9 will join the Agent Engineering HQ conference in London to share insights into inference engineering for long-running agents. 👉 Tickets are still available.
    Agent Engineering HQ @AgentEngHQ
    📣 Speaker Announcement 07: Agent Engineering 🇬🇧 London! 🎙️ We're excited to announce Meryem Arik, @MeryemArik9 Co-founder & CEO of @Doubleword_ as a speaker at Agent Engineering London 👉 Meet Meryem and follow the speaker lineup:
    000158
  10. Doubleword@Doubleword_
    Next week, @MeryemArik9 will join the @AgentEngHQ conference in London to share insights into inference engineering for long-running agents. 📍Everyman, Canary Wharf, London 🗓️ Friday 16 October. 👉 Tickets are still available at:
    Download
    0001.1K
  11. Doubleword@Doubleword_
    Doubleword is now a built-in provider in @OpenMed_AI Agent 0.5.0. OpenMed is an open-source medical AI agent with a 93-tool clinical workflow, PHI gates, and a full audit trail. With one Doubleword API key, users can now run real-time, async, and batch inference directly from the CLI. Users can choose from 11 open models on Doubleword, including DeepSeek V4.1 Flash, GLM 5.3, Kimi K3, and Nemotron 3 Ultra. Check out the docs in the comments:
    Download
    1392.4K
  12. Doubleword@Doubleword_
    Over 2T tokens in September & not slowing down... 🚀
    Meryem Arik @MeryemArik9
    Doubleword processed 2T tokens *just* on long horizon coding agents in September 🤓 We built Doubleword to achieve the highest efficiency inference. That means we want to produce the most number of tokens possible per GPU second. There are no better use cases for this kind of inference than long horizon coding agents. These are one of the most token intensive use cases currently possible, with some of our clients running agents over 12+ hours with hundreds of tool calls along the way. Vroooooom - October is already tracking to be huge for this workload
    0131.5K
  13. Meryem Arik✓@MeryemArik9
    Doubleword processed 2T tokens *just* on long horizon coding agents in September 🤓 We built Doubleword to achieve the highest efficiency inference. That means we want to produce the most number of tokens possible per GPU second. There are no better use cases for this kind of inference than long horizon coding agents. These are one of the most token intensive use cases currently possible, with some of our clients running agents over 12+ hours with hundreds of tool calls along the way. Vroooooom - October is already tracking to be huge for this workload
    Download
    20232.9K
  14. Doubleword@Doubleword_
    Next week @MeryemArik9 is speaking at @WorldSummitAI on what it takes to build reliable AI systems beyond the model itself. Inference, orchestration, evals, observability, failure modes + more. 📅 7 Oct, 11:30
    Download
    128908
  15. Doubleword@Doubleword_
    More efficient inference does not just lower cost, it can improve outcomes too. On SWE-bench Pro, a single DeepSeek-V4-Pro agent scored 51.2%. Running 64 independent attempts on Doubleword raised that to 70.7%. Because each completed attempt cost just $0.049 of node time, all 64 attempts per problem came to $3.13 overall, roughly the spend of a single attempt on the SGLang baseline. That is what cheaper inference makes possible: more agent loops, increased accuracy and better results. Read more:
    Download
    21141.4K
  16. Doubleword@Doubleword_
    Doubleword
    RT @finn_fergus: Was great to collaborate with @sh_reya and @charles_irl and the rest of the team on this awesome project. I think there are still lots of great opportunities out there for 'pushing down' workloads into the inference stack!
    Shreya Shankar @sh_reya
    Excited to share Quail, our new open source AI-SQL engine (a collab with Modal)! By planning queries and LLM inference together, it reaches 1B+ input tokens/min on one H100 for one query 😱🚀 AI-powered data operators create a new, interesting inference workload👇
    0401
  17. Shreya Shankar✓@sh_reya
    Excited to share Quail, our new open source AI-SQL engine (a collab with Modal)! By planning queries and LLM inference together, it reaches 1B+ input tokens/min on one H100 for one query 😱🚀 AI-powered data operators create a new, interesting inference workload👇
    Download
    841631.6K380K
  18. Doubleword@Doubleword_
    Doubleword
    RT @konarkmodi: Just another day leveraging @Doubleword_’s extremely robust inference platform. We just processed 32.6 MILLION tokens in 10m 57s. Total cost: $0.58 or $18/Billion tokens. 30,000 classifications.
80 possible categories. 
Peak throughput: 128.7k tokens/sec. The model wasn’t the interesting part. The interesting part was how much throughput we could extract simply by running the workload in parallel.
    0201
  19. Doubleword@Doubleword_
    Doubleword
    RT @rushilbhat: Came away from this amazed at how much latent ability models possess. DeepSeek-V4-Pro solves 51% of SWE-bench Pro with one attempt and 71% with 64 attempts. Efficient inference turns parallel sampling into a lever worth pulling, especially on tasks you can verify.
    Meryem Arik @MeryemArik9
    1/ We think parallel test-time scaling is one of the most underexplored ways to improve model quality We spend a lot of time on efficiency for long-horizon agentic inference We showed that a swarm of DeepSeek-V4-Pro agents lifts the SWE-Bench-Pro score by ~20 points, beating the cost-performance trade-off of the leading frontier models🧵
    0203
  20. Doubleword@Doubleword_
    Doubleword
    RT @MeryemArik9: 1/ We think parallel test-time scaling is one of the most underexplored ways to improve model quality We spend a lot of time on efficiency for long-horizon agentic inference We showed that a swarm of DeepSeek-V4-Pro agents lifts the SWE-Bench-Pro score by ~20 points, beating the cost-performance trade-off of the leading frontier models🧵
    01004.9K
  21. Doubleword@Doubleword_
    A week after release, DeepSeek V4.1 Flash is already one of the most popular models on Doubleword, and the latest cost per task figures from Artificial Analysis help explain why... Try it here 👉
    Download
    01162.1K
  22. Doubleword@Doubleword_
    Doubleword
    RT @Shashikant86: 🎙️ Speaker Announcement 07: Agent Engineering 🇬🇧 London! 🙌 Excited to announce Meryem Arik Co-founder & CEO of @Doubleword_ , as a speaker at Agent Engineering London Founders Edition 2026. She joins us on the Inference ⚡ Engineering track. I can't think better company than Doubleword to fill the Inference Engineering space innovating from UK 🇬🇧 🙏 Delighted to welcome her to the stage at Everyman Canary Wharf on 16 October 2026. 👉 Meet Meryem and follow the speaker lineup: More speaker announcements coming soon. Stay tuned! #AgentEngineering #InferenceEngineering #Doubleword #LLMInference #AIEngineering #AIAgents #London
    0103
  23. Doubleword@Doubleword_
    Doubleword
    RT @AgentEngHQ: 📣 Speaker Announcement 07: Agent Engineering 🇬🇧 London! 🎙️ We're excited to announce Meryem Arik, @MeryemArik9 Co-founder & CEO of @Doubleword_ as a speaker at Agent Engineering London 👉 Meet Meryem and follow the speaker lineup:
    0102
  24. Show more posts