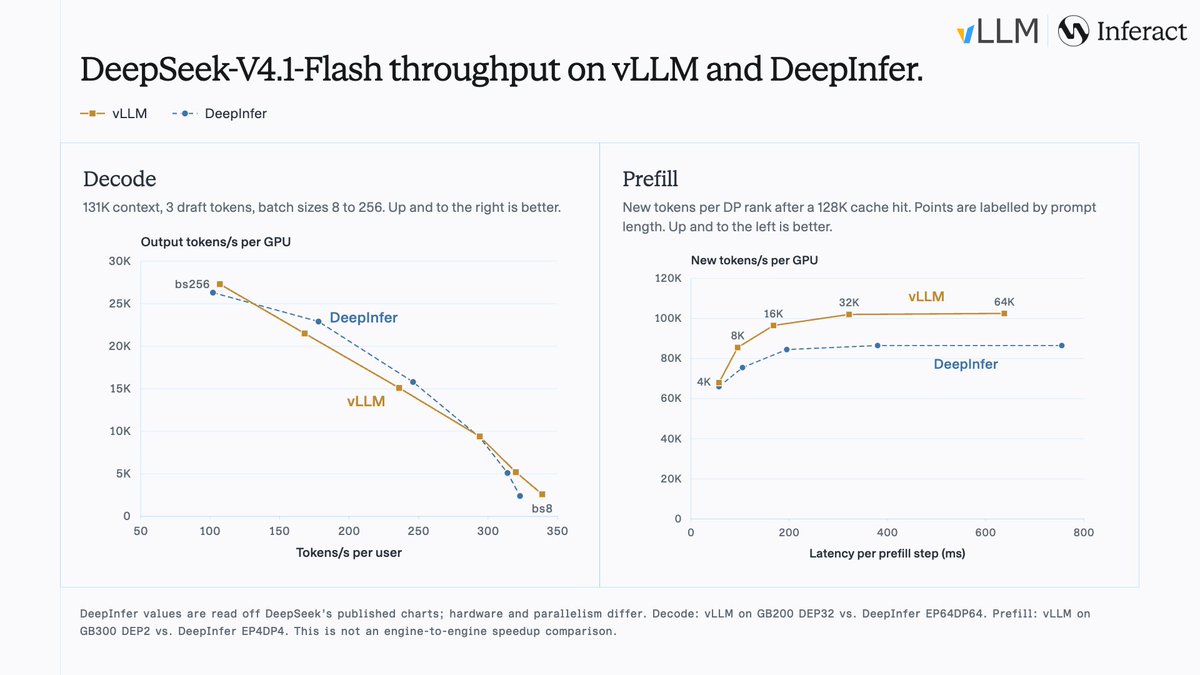
DeepSeek open-sourced DeepInfer this week, the engine behind its own DeepSeek-V4.1-Flash serving. We think it is the most useful kind of release: a purpose-built engine, originally built on @vllm_project, that shows what one model can do on one piece of hardware.
Our team got vLLM to match it on DeepSeek's own decode configuration, using half the GPUs, and then kept going to where an offline reference engine does not reach: online serving across a full GB300 NVL72 rack, at 954K tokens/s per GPU on SemiAnalysis AgentX and $38.96 of token value per GPU-hour.
Our view is that the gap between a lab’s reference engine and the engine you run in production should be close to zero, and that closing it is mostly careful systems work rather than new algorithms.
vLLM @vllm_projectvLLM matches DeepInfer, DeepSeek's own engine for DeepSeek-V4.1-Flash, on DeepSeek's decode configuration across batch sizes 8 to 256, and does it at DEP32 against DeepInfer’s EP64DP64. DeepInfer was originally built on vLLM. By integrating DeepSeek's open-source kernels and extensively optimizing prefill and decode, vLLM now matches DeepInfer's performance curves.
22161528.1K