- Defensive work shouldn’t mean sending sensitive data somewhere you don’t control. You can run open models locally with Ollama, or on Ollama’s cloud with zero data retention.Michael @mchiang0610More security teams are coming to @ollama to run open models for defensive work. Defending a system means understanding how attackers get in, which means using models that will help with things like exploit analysis and red teaming. Most closed model providers only allow that through special access programs. Open models can be used by any team, on their own machines or on servers they control. Open models can be misused and teams should run them with care. But attackers already have them, so defenders should too.341321814.8K
 More security teams are coming to @ollama to run open models for defensive work. Defending a system means understanding how attackers get in, which means using models that will help with things like exploit analysis and red teaming. Most closed model providers only allow that through special access programs. Open models can be used by any team, on their own machines or on servers they control. Open models can be misused and teams should run them with care. But attackers already have them, so defenders should too.323014.1K
- ollamaRT @SparkLLM: Spark-X2.6-4B is here! Stronger coding, agents & long-context skills through improved post-training. Thinking: none / low / high. @huggingface @ModelScope2022 @ollama @vllm_project @sgl_project08701.9K
- 1767011.4K
- Meet Flint from @Recursive_SI! A ~40B parameter MoE open model for fast, accurate agentic coding use case made to run on-device. Flint can generate >125 tps on a M4 Pro Macbook Pro and >150 tps on a 64GB NVIDIA RTX Spark on short contexts. Try it on Ollama today: ollama run flint Claude Code: ollama launch claude --model flintRichard Socher @RichardSocherIntroducing Flint, @Recursive_SI’s first model: a fast local coding model built with our automated research system, the Eureka Machine. • Best-in-class fast local coding • Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark • Built from scratch in under 4 months Private, unmetered intelligence on your own machine. Open weights available now on @huggingface, run it locally on your favorite framework or try it for free on @opencode or @pidotdev.583651338.7K
 Introducing Flint, @Recursive_SI’s first model: a fast local coding model built with our automated research system, the Eureka Machine. • Best-in-class fast local coding • Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark • Built from scratch in under 4 months Private, unmetered intelligence on your own machine. Open weights available now on @huggingface, run it locally on your favorite framework or try it for free on @opencode or @pidotdev.6368958.4K3.4M
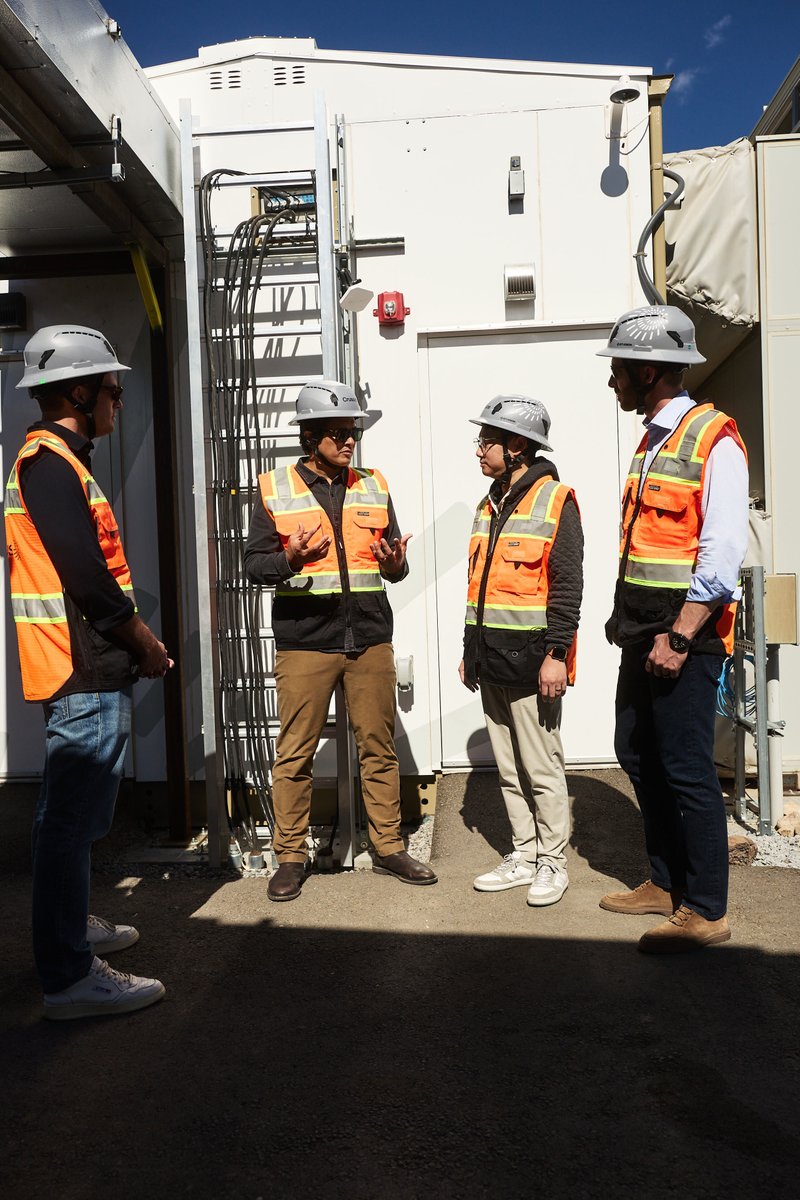
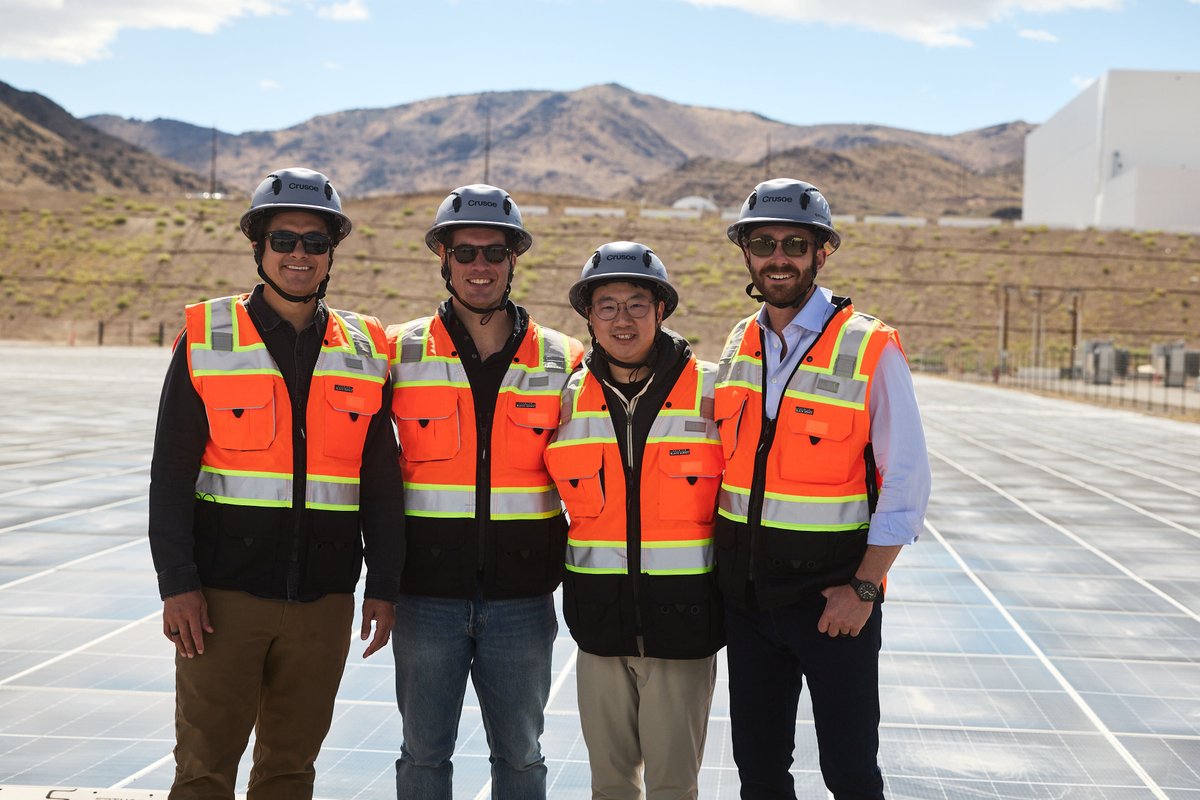
- We've spent the last several months scaling our compute footprint right here in the U.S., and we got to see some of it up close at the @CrusoeAI and Redwood Materials site in Nevada. Thanks @Electron_Cowboy and @ChaseLochmiller for the tour! Excited to keep building with Crusoe to bring our users day-zero models and full ZDR, with top performance. We look forward to sharing more soon 👀

 151312213.8K
- ollamaRT @CrusoeAI: San Francisco showed up! 🌉 @ollama's @jmorgan and @TrajectoryLabs' @MichaelElabd joined Crusoe's Erwan Menard to explore a fundamental choice for AI builders: closed, open, or proprietary models? 📸 Moments from an incredible evening. Stay tuned for our next AI talk.0701.8K
- Clef from @Cloudflare is on Ollama. Run it locally or in the cloud. 27B multimodal decision model, supports text and image input and is compatible with Jev and System One APIs. 🔒Hosted in the US and with zero data retention.222126624.2K
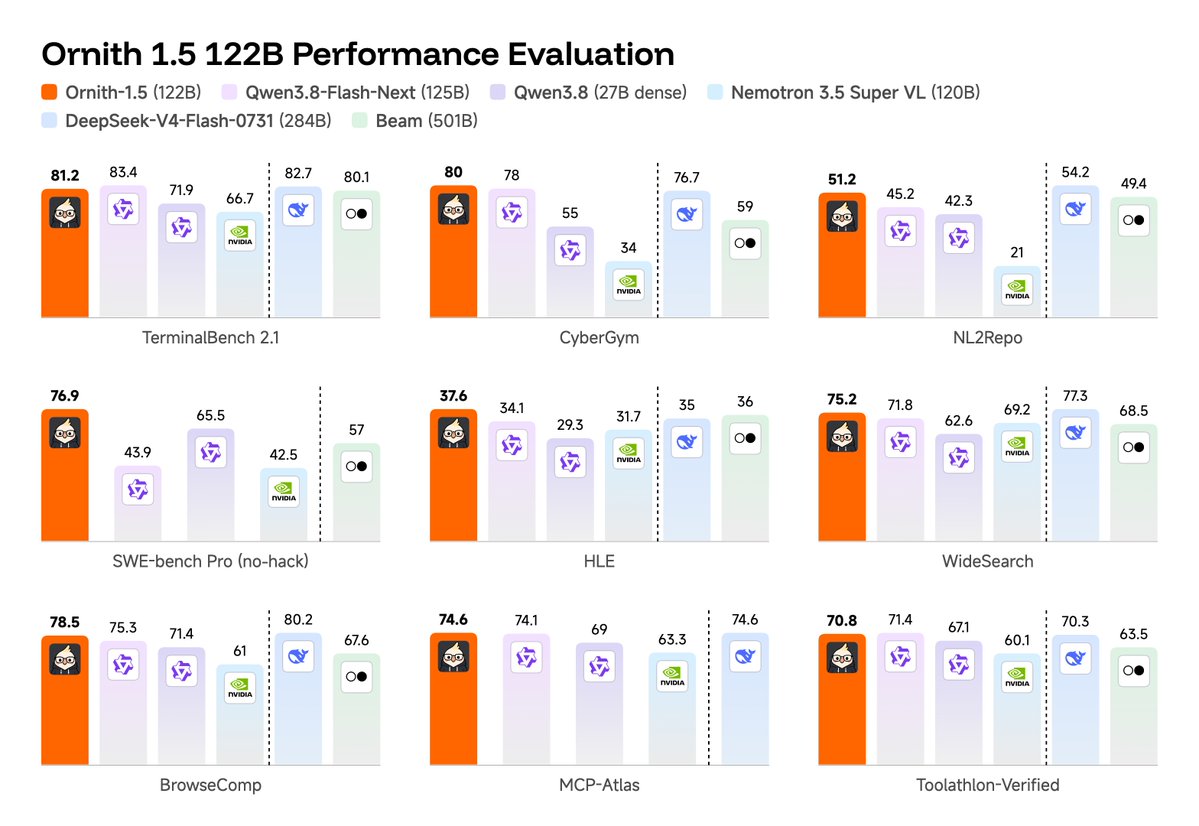
- Ornith 1.5 122B is available on Ollama! Run it all locally on your device. ollama run ornith-1.5:122bOrnith @ornith_Aloha!🌺 Meet Ornith-1.5-122B: No Tradeoff Between Strong and Fast Stronger. Faster. Leaner. Ornith-1.5-122B delivers frontier-level capabilities with exceptional inference efficiency. With superior instruction following, stronger task decomposition, and deeper understanding of real-world workflows, it achieves state-of-the-art performance among open-source models of comparable size, while running on a single NVIDIA DGX card!! Open weights under the MIT license. Coding ✅SWE-bench Verified: 0.845 ✅TB2.1: 0.813 ✅CyberGym: 0.800 ✅NL2Repo: 0.512 Agentic ✅HLE: 0.446 ✅BrowseComp: 0.785 ✅MCP-Atlas: 0.746 ✅Toolathlon: 0.708 🤗Hugging Face: We can’t wait to see what you build with Ornith-1.5-122B.383639530.6K
 Aloha!🌺 Meet Ornith-1.5-122B: No Tradeoff Between Strong and Fast Stronger. Faster. Leaner. Ornith-1.5-122B delivers frontier-level capabilities with exceptional inference efficiency. With superior instruction following, stronger task decomposition, and deeper understanding of real-world workflows, it achieves state-of-the-art performance among open-source models of comparable size, while running on a single NVIDIA DGX card!! Open weights under the MIT license. Coding ✅SWE-bench Verified: 0.845 ✅TB2.1: 0.813 ✅CyberGym: 0.800 ✅NL2Repo: 0.512 Agentic ✅HLE: 0.446 ✅BrowseComp: 0.785 ✅MCP-Atlas: 0.746 ✅Toolathlon: 0.708 🤗Hugging Face: We can’t wait to see what you build with Ornith-1.5-122B.
 2225232.8K1.5M
- For the next 3 days, in collaboration with @MiniMax_AI, MiniMax M3.1 Flash will be free on Ollama's Cloud! Hosted in the US and with zero data retention.ollama @ollamaMiniMax M3.1 Flash is on Ollama! 🔒 Hosted in the US and with zero data retention. Fast coding and agentic workflows, with image understanding and a 1M-token context window. Try it on Ollama Cloud: ollama run minimax-m3.1-flash:cloud Claude Code: ollama launch claude --model minimax-m3.1-flash:cloud Codex: ollama launch codex -–model minimax-m3.1-flash:cloud434076749.1K
- MiniMax M3.1 Flash is on Ollama! 🔒 Hosted in the US and with zero data retention. Fast coding and agentic workflows, with image understanding and a 1M-token context window. Try it on Ollama Cloud: ollama run minimax-m3.1-flash:cloud Claude Code: ollama launch claude --model minimax-m3.1-flash:cloud Codex: ollama launch codex -–model minimax-m3.1-flash:cloudMiniMax (official) @MiniMax_AIMiniMax M3.1 Flash: Space Performance + Bunny Speed 🚀🐰 Yes, Space Bunny - which has topped global leaderboards with 200T+ tokens - was an earlier version of M3.1 Flash. 💰Redefining the performance economics of agentic AI. M3.1 Flash achieves frontier-level intelligence across key tasks such as Cowork (Automation-Bench: 62%; ALE: 30%), Coding (DeepSWE: 74%) and Visual Reasoning (BabyVision: 91%), at 1/3 the cost of M3 and 3x the speed. API pricing (flat rate): $0.15 / $0.60 per 1M input/output tokens, with cache reads at $0.015 / 1M tokens. Model weights will arrive on Oct 23. API: M Plan: MiniMax Code for desktop:483041471.7K
- ollamaRT @MiniMax_AI: Day0 support from @ollama 🦙🤝🐰 M3.1 Flash, US-hosted, zero data retention, ready for your agents. Go build!ollama @ollamaMiniMax M3.1 Flash is on Ollama! 🔒 Hosted in the US and with zero data retention. Fast coding and agentic workflows, with image understanding and a 1M-token context window. Try it on Ollama Cloud: ollama run minimax-m3.1-flash:cloud Claude Code: ollama launch claude --model minimax-m3.1-flash:cloud Codex: ollama launch codex -–model minimax-m3.1-flash:cloud0401.7K
 MiniMax (official)@MiniMax_AIMiniMax M3.1 Flash: Space Performance + Bunny Speed 🚀🐰 Yes, Space Bunny - which has topped global leaderboards with 200T+ tokens - was an earlier version of M3.1 Flash. 💰Redefining the performance economics of agentic AI. M3.1 Flash achieves frontier-level intelligence across key tasks such as Cowork (Automation-Bench: 62%; ALE: 30%), Coding (DeepSWE: 74%) and Visual Reasoning (BabyVision: 91%), at 1/3 the cost of M3 and 3x the speed. API pricing (flat rate): $0.15 / $0.60 per 1M input/output tokens, with cache reads at $0.015 / 1M tokens. Model weights will arrive on Oct 23. API: M Plan: MiniMax Code for desktop:
 4726787.5K1.7M